❌

Vue lecture

Candidate Statement for the 2026 W3C TAG Election

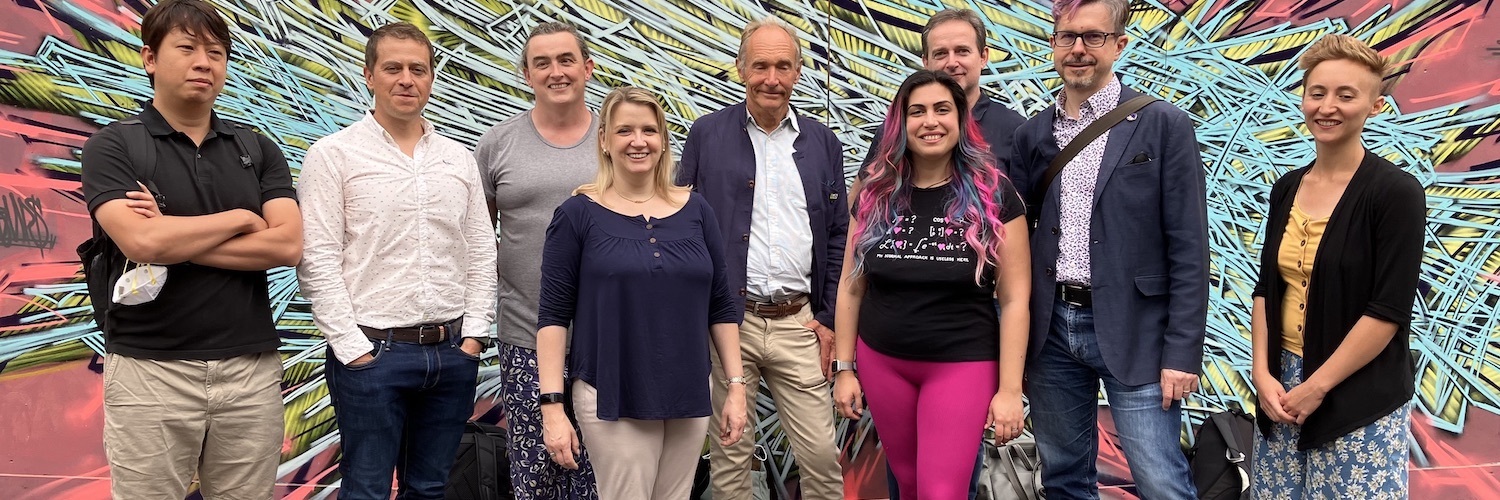
Group photo of the W3C TAG in July 2022 with me to the left of Sir Tim Berners-Lee (inventor of the Web and TAG chair emeritus). Photo credit: Dan Appelquist

I had the great honor of being elected to the TAG by the W3C membership in 2020 and again in 2022, serving two terms from 2021 to 2025. After a two-year break, this year I’m running to return, thanks to Google, Microsoft, and OpenJS Foundation pooling resources to make it possible. 💙

The W3C Technical Architecture Group (TAG) is the Working Group that ensures that Web Platform technologies are usable and follow consistent design principles, whether they are created inside or outside W3C. It advocates for the needs of everyone who uses the Web and everyone who works on the Web.

If you work for a company that is a W3C Member, please consider encouraging your AC rep to vote for me! (Ask me if you don’t know who that is)

My candidate statement follows.

I’m Lea, and I’m running to return to the TAG, where I served two terms from 2021 to 2025. It was some of the most fulfilling work of my career. The only reason I did not run in 2024 is that the job takes hundreds of hours a year, which as an independent I could not sustain pro bono. This year, in recognition of my service, Google, Microsoft, and the OpenJS Foundation have pooled resources to fully fund my participation, so I can finally commit the time the job deserves while remaining independent.

My work spans the entire web platform: 14 years in the CSS Working Group, active participation in TC39 and WHATWG, two decades of building for the web, and open source running on millions of websites. In 2025 the OpenJS Foundation recognized my overall impact on the web platform with its Pathfinder for Standards Award. That breadth is exactly what the TAG requires.

With a PhD in Human-Computer Interaction from MIT and a 20+ year career that includes entrepreneurship and product leadership, I combine academic rigor and big-picture perspective with pragmatism, an eye for hard tradeoffs, and a deep commitment to user needs. And as a bilingual Greek woman, I bring a Mediterranean and European perspective and firsthand appreciation of the Web’s internationalization needs. For more on my background, see my 2020 and 2022 candidate statements.

In my four years on the TAG, I worked to direct the group’s limited time towards maximizing impact: I co-led the Web Platform Design Principles, turning previously implicit design knowledge into published guidance that improves consistency across the platform and helps reviews scale, started the Web Platform Gaps initiative to find what the platform is missing, served as liaison to TC39 to keep JavaScript and Web APIs consistent, and participated in hundreds of design reviews, becoming the TAG’s go-to reviewer for API design.

But I believe the TAG can, and should, do more.

The Web is changing rapidly, and reactive review is no longer enough. The TAG is uniquely positioned to see the platform as a whole, yet it mostly encounters features after their architecture has taken shape, sometimes even after they ship. By then, consequential decisions are difficult to change. Who identifies gaps that span multiple working groups? Who sketches the big cross-cutting solutions, or decides which layer a problem belongs in when that is non-obvious? Individual groups see their own slice, and the sum of several low-level views is not the big picture. The result is architectural debt.

I want the TAG to help shape the architecture of the Web, not just review it. To proactively identify gaps, sketch coherent, composable solutions, and then bring the relevant working groups into the conversation to develop and standardize the pieces within their scope. Not to take over their work, but to provide the cross-cutting architectural perspective that no individual group is positioned to offer.

Expanding the gap analysis work I began last term is the first step, and my work since then has given me a much richer evidence base to draw from. I am one of the people leading Modern Web Guidance, a multi-vendor project teaching AI coding agents to use the modern web platform effectively and follow best practices. This work involves reviewing implementation instructions for a broad range of use cases, ensuring they reflect the best the modern Web has to offer. This makes the many ways the web platform still falls short incredibly salient, revealing systemic gaps that are easy to miss when looking at web features in isolation.

The biggest change since my last term is that a growing share of the code targeting the web platform is written by AI agents, and a growing share of the Web is consumed by them. The TAG should treat this as an architecture question and answer it with principles and evidence, not enthusiasm or alarm. Many of the principles that make APIs robust and usable for humans also benefit agents, but the differences expose new tradeoffs that deserve careful architectural attention. And none of this changes what the Web is for: user agency, privacy, accessibility, and interoperability apply no matter who, or what, writes the code, and defending them is the TAG’s job.

I am not employed by a browser vendor or a big tech company, and my funders do not direct, approve, or veto my positions. I remain free to disagree with any of them, in public, on any proposal. My only agenda is a web platform that lives up to its potential and remains owned by no one. I’ve spent four years helping the TAG improve the Web. I want to help it shape the Web’s future, and for the first time, I have the resources to see it through.

I would like to thank the OpenJS Foundation, Google, and Microsoft for fully funding my TAG participation in the event that I am elected, and OpenJS Foundation and Bocoup for partly funding it during my previous terms.

  •  

The best way to use icons in Web UIs

TL;DR? Jump to demo

I’ve always had a soft spot for icons1. Not only do they add polish to a UI, they can also tangibly improve usability. Familiar icons help users find what they need quickly, since we recognize pictures much faster than we read words.

And as a web architect at heart, the current dominant ways we have to include icons on the Web make me sad. While there are many, many different ways to include icons in a Web UI, each with different performance characteristics, by far the most common ones involve adding inline SVG to the HTML. For example, a trash icon might be included like this:

<button>
<svg xmlns="http://www.w3.org/2000/svg" width="24" height="24" viewBox="0 0 24 24" fill="none" stroke="currentColor" stroke-width="2" stroke-linecap="round" stroke-linejoin="round" class="lucide lucide-trash preview-icon"><path d="M10 11v6"/><path d="M14 11v6"/><path d="M19 6v14a2 2 0 0 1-2 2H7a2 2 0 0 1-2-2V6"/><path d="M3 6h18"/><path d="M8 6V4a2 2 0 0 1 2-2h4a2 2 0 0 1 2 2v2"/></svg>
Delete
</button>

Some people use a separate SVG file for sanity and include icons via <use>, but the markup is still fairly clunky (not to mention slow, sans bundlers). All this clunkiness forces people to resort to hiding the icon under layers of abstraction, such as dedicated custom elements like <x-icon name="trash"></x-icon> or React components like <TrashIcon />, but the ugliness still ships under all these layers, and the browser still has to deal with it.

Icon fonts did put icons in CSS (::before { content: "\f1f8" } is still how Font Awesome’s pseudo-element mode works), and a lot of their appeal was exactly that. But they came with a long list of issues: large downloads (even with subsetting), fallback glyphs when the font fails to load, screen readers announcing private-use codepoints, user font overrides (e.g. for dyslexia) wiping them out, and text hinting that was never designed for pictures. We threw out the baby with the bathwater: the problem was the font, not the CSS.

Many of the attempts to move this to CSS still involve markup. The mask trick that most of them rely on is not new either: Chen Hui Jing covered it in 2021, and Iconify generates mask-based CSS for its entire catalog. But in all of these, which icon to use (and whether to use one at all) is still decided in the markup, via one class per icon; CSS only handles color. The closest I’ve seen is David Bushell’s 2024 post on including icons purely via CSS via generated content + masks, where the icon is picked in CSS, but every selector that wants to support icons needs its own chunk of CSS, and there is no way to override the icon on a case by case basis. I still think it’s superior to inline SVG in HTML, and it baffles me why it isn’t more popular.

A user-centered icon system

Per the principles outlined in my user effort article, a good icon system should:

  1. keep syntax close to the minimum necessary to declare intent, and
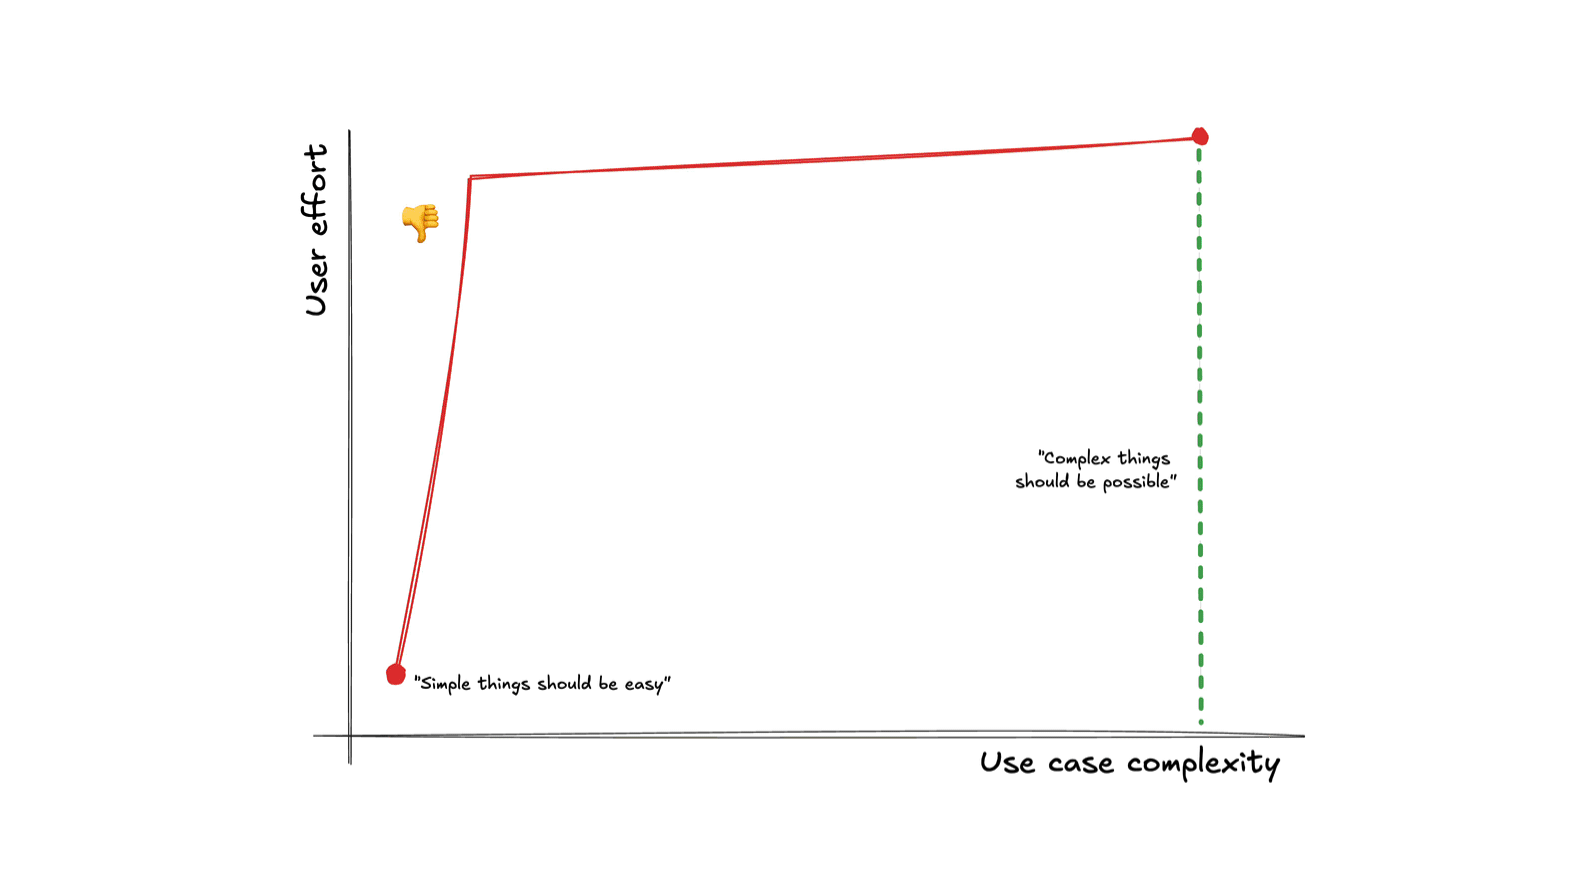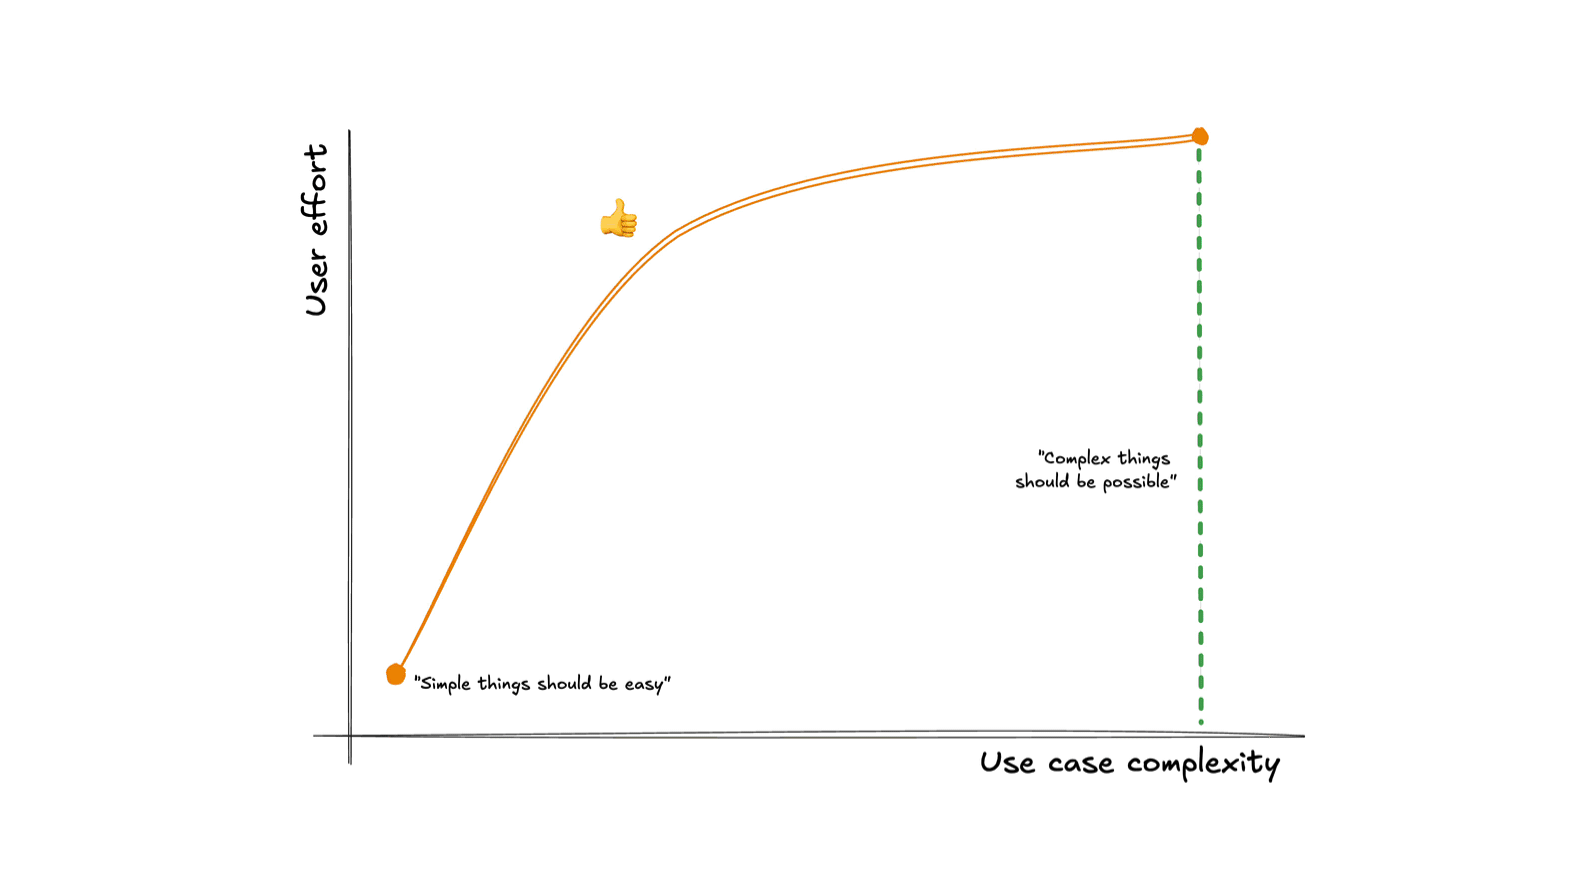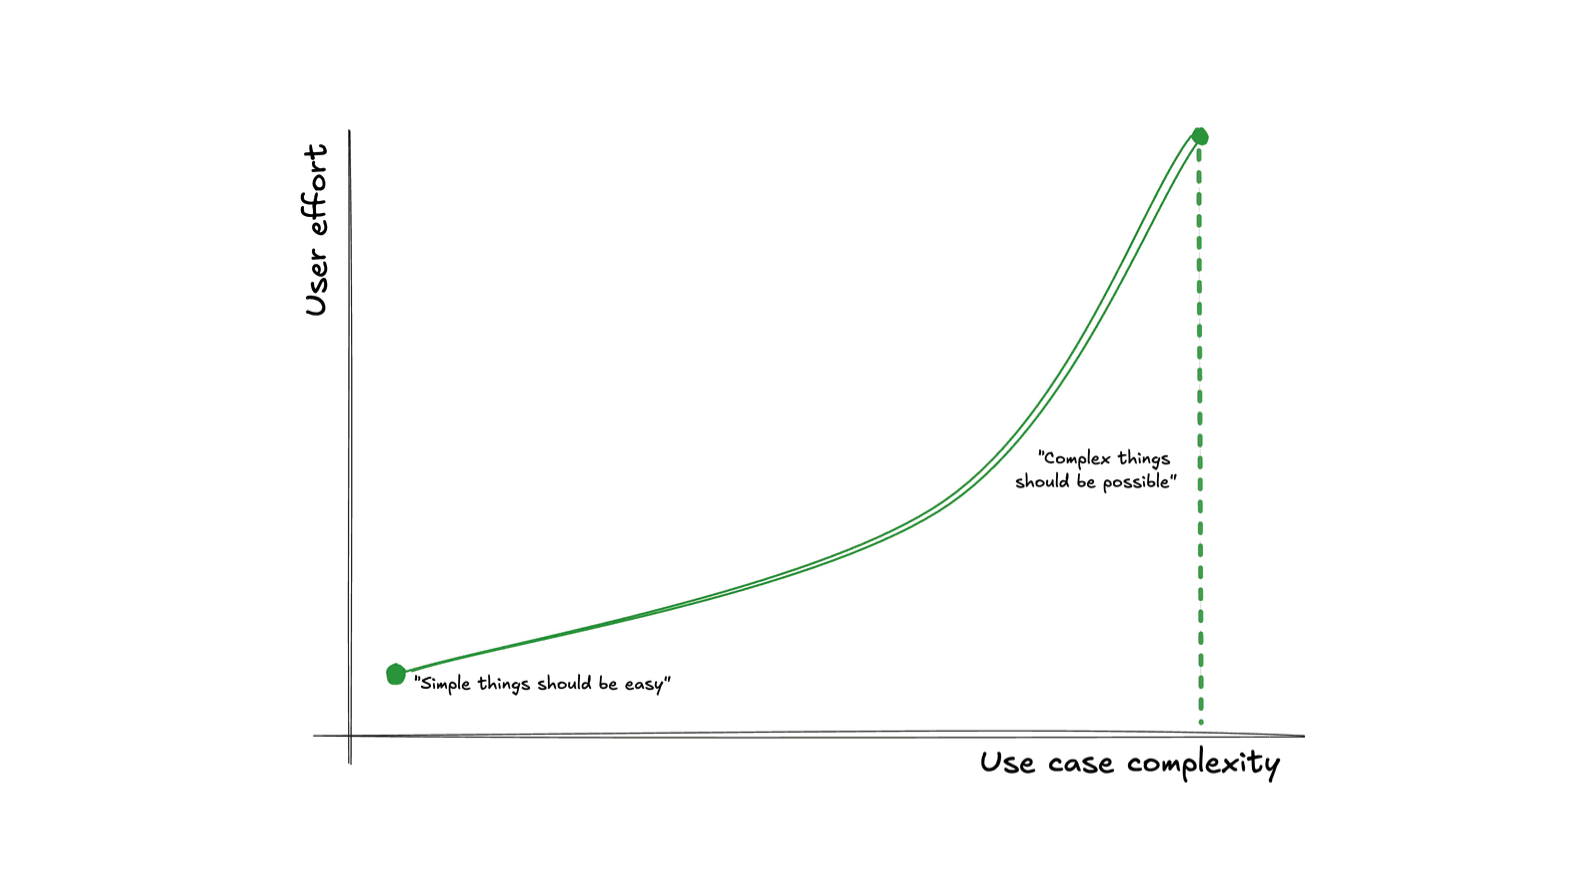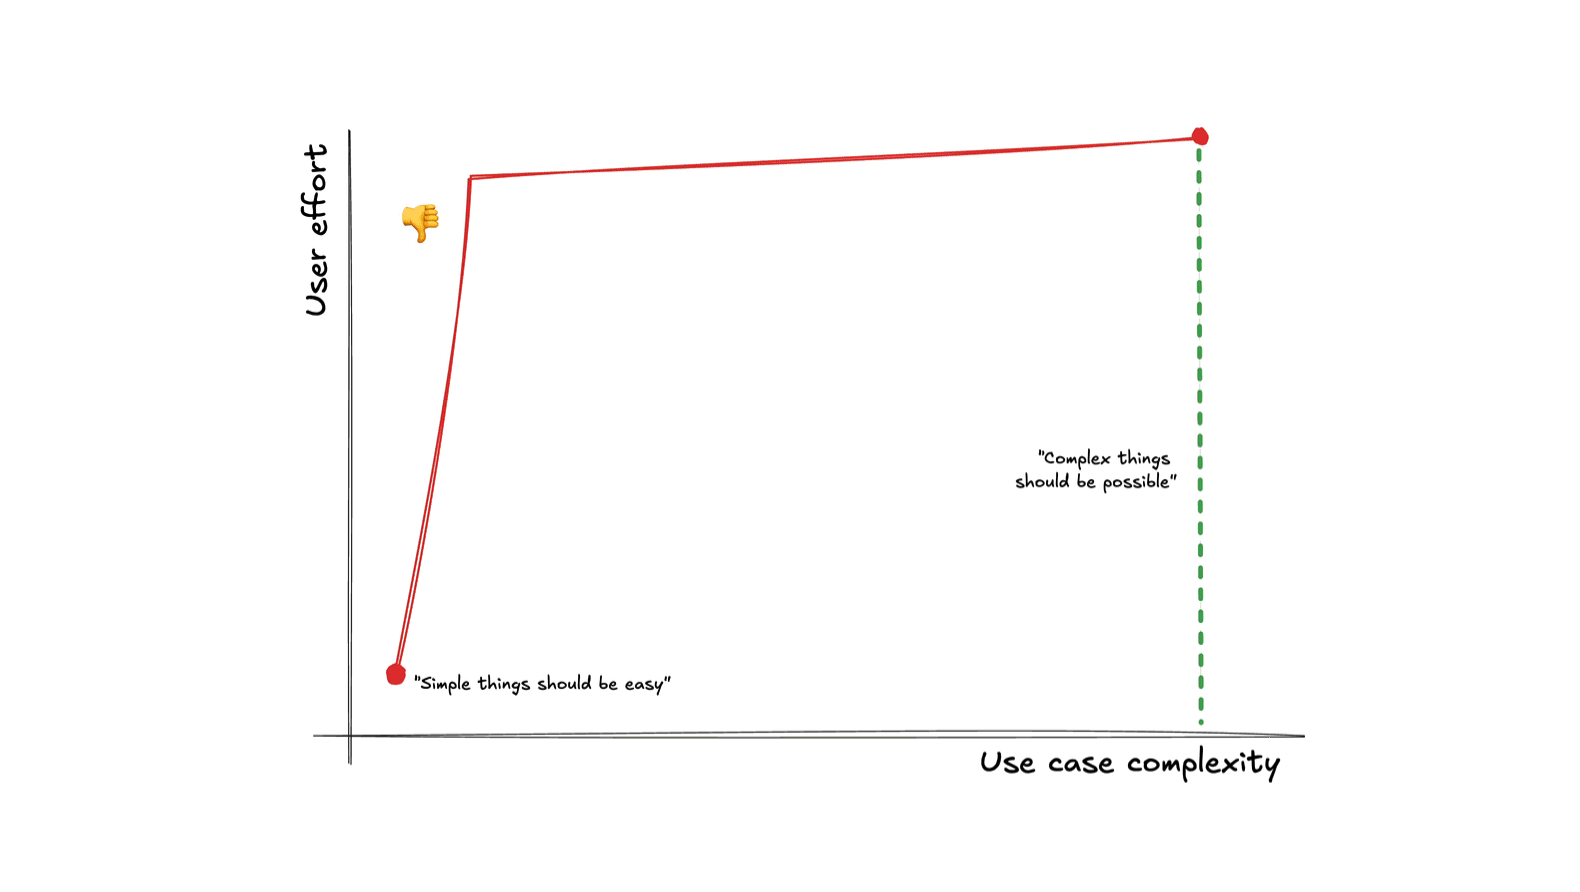
  2. make simple things easy, complex things possible, and the transition from one to the other smooth (no usability cliffs)

How does that translate to an icon system?

  • High signal-to-noise ratio: The intent to add or override an icon is basically “icon” plus the icon name, and possibly its location (start, end, marker, etc). Anything beyond that is boilerplate. Some boilerplate is unavoidable, but most <svg>-based solutions involve unacceptable amounts of boilerplate (which is why we end up abstracting that away).
  • Simple things should be easy:
    • We should be able to define default icons for certain cases without having to explicitly include them at every callsite. E.g. a <button class="delete"> should automatically get a trash icon, without needing to declare it in the markup in any way, shape, or form, unless we want to override it.
    • The default icon color should follow the local text color (or designated icon color, if different) without any additional song and dance.
  • Complex things should be possible:
    • We should be able to easily override the default icon for a component, either permanently or as a result of various conditions (state changes, user interaction, etc.).
    • Styling the icon should be as easy as applying a CSS property. The minimum is color, but the more extensive styling is possible, the better.
  • No usability cliffs: Overridding an icon, temporarily or permanently, should still not require much more than the bits of information necessary to declare intent.

Per consumers > producers, making icon usage ergonomic is more important than making icon definition ergonomic, but ideally adding a new icon to the icon system should not require much more than:

  • declaring the name of the icon, and
  • providing the SVG path data or a URL to an SVG file

And of course, it still needs to be reasonably performant — the existing success criteria don’t disappear!

The dominant ways to include icons today fail to meet at least one of these criteria. Can we do better?

Why CSS?

CSS is the only web platform language that facilitates reactive aggregation: you declare what applies to what conditions (type of element, interaction state, media query, etc.) and the browser automatically applies the right styles when those conditions are met and cleanly removes them when they are no longer met, without affecting any other conditions that simultaneously apply to the element, and without forcing developers to manage any of these side effects manually.

I personally think we are underutilizing this wonderful language by artificially restricting it to styling, but that’s a topic for another article.

If we can nail icons via CSS, this gives us tremendous expressive power, with practically no loss of flexibility.

Imagine being able to tweak icons based on…

  • Any selector, including interaction pseudo-classes (:hover, :focus, etc.), e.g. to communicate additional information about the action or adapt to a different background color
  • Media queries (print, dark mode, high contrast, etc), e.g. use different icons in dark mode, add or remove them in print, etc.
  • Container queries
  • Writing mode, e.g. to use a different icon for RTL text

Additionally, if icons can be injected or tweaked via CSS, this means we can specify them on pseudo-elements, such as details::marker, select::picker-icon, or option::checkmark, something no markup solution accommodates.

Or even, imagine applying entirely different icon sets to the entire page (or a portion) without having to touch any markup! E.g. a section with a hand-drawn aesthetic could get a hand-drawn icon set, without affecting the rest of the UI.

The possibilities are endless. Once you allow yourself to consider that this is possible, you will start seeing use cases everywhere.

Icons should be design tokens

Including icons as direct <svg>s (especially with no wrapping abstraction to manage a shared registry) means there is no way to enforce consistency — anything goes. One page might use a Font Awesome trash icon, another might use a Lucide trash icon.

I think the icons themselves should be a type of design token, managed by the design system, that UI components simply use, just like colors and gradients.

Managing icons via CSS also allows us to define them alongside other design tokens (e.g. as CSS variables on :root), rather than in a separate place.

What does it look like?

Suppose icons were CSS variables, and we could add an icon to an element simply by setting an --icon custom property, e.g. by doing something like

<button style="--icon: var(--icon-trash)">Delete</button>

This means we could also make simple things easy via:

button.delete {
  --icon: var(--icon-trash);
}

while maintaining the ability to override the icon on a case by case basis by simply overridding the --icon property.

We can even adapt to state reactively:

button.delete {
	--icon: var(--icon-trash-outlined);

	@media (prefers-color-scheme: dark) {
		--icon: var(--icon-trash-filled);
	}

	&:hover {
		background: var(--color-danger);
		/* See https://lea.verou.me/blog/2024/contrast-color/
			for making it adapt automatically */
		color: var(--color-danger-text);
	}
}

a[href^="https://"] {
	@media print {
		--icon-end: var(--icon-link-external);
	}
}

or user interaction, e.g. to communicate both where a link goes (GitHub) and what it is (an external link):

a.github {
	--icon: var(--icon-github);

	&:hover {
		--icon: var(--icon-link-external);
	}
}

And for completely ad hoc standalone icons where adding CSS would be more work than doing it inline in HTML, we can have an .icon class:

<i class="icon" style="--icon: var(--icon-trash)"></i>

This makes it strictly more powerful than the markup approaches, with the only exception being that completely inline SVG allows potentially changing the SVG itself in arbitrary ways (e.g. morphing it into another icon or changing it dynamically as the result of user input). For those cases, we’d still need inline SVGs. But how many of your icons fall in that category?

How it works

The core idea can be summarized as:

  • Icons are first-class design tokens stored in --icon-[name] properties that hold <image> values (embedded or remote)
  • Icons are inserted via pseudo-elements.
  • The icon is applied as a mask to a square with background equal to the icon color.
  • The system uses general CSS custom properties like --icon, --icon-start, and --icon-end for flexibility and reusability.
  • Style queries + @property for conditional icon insertion based on these custom properties.

Rendering and referencing icons

Icons are inserted via pseudo-elements, which use the icon to mask a square with background equal to the icon color.

The referencing syntax I’ve settled on is:

  • Low-level --icon-[location] properties:
    • --icon-start to prepend an icon to element contents (via ::before)
    • --icon-end to append an icon to element contents (via ::after)
    • Optionally, additional properties can redirect to other pseudo-elements, e.g. --icon-marker for ::marker
  • --icon higher level abstraction that just means “add an icon to this component”: components2 can redirect it to any of the lower-level --icon-[location] properties on the element itself or a descendant depending on what makes sense for that component. E.g. --icon may set --icon-start on a <button> but --icon-marker on <summary>

You could be more elaborate and also define --icon-[state] properties like --icon-hover, --icon-focus etc, if you deem them useful! The beauty of this approach is its immense flexibility.

Available icons are defined on :root as CSS variables, e.g.:

:root {
	/* Embedded, for performance */
	--icon-trash: url("data:image/svg+xml,<svg viewBox='0 0 448 512' xmlns='http://www.w3.org/2000/svg'><path d="…"></svg>");

	/* Remote SVGs work fine too! */
	--icon-link-external: url("icons/link-external.svg");

	/* more icons here */
}

One-off icons can still be used by setting e.g. --icon: url(…) instead of --icon: var(--icon-foo), but if most UI references registered icons, they will stand out like a sore thumb and will be easy to spot in a review.

Then, to display these as icons, the crux is:

  • An empty pseudo-element e.g. ::before or ::after is used to display the icon
  • The pseudo-element is painted as a 1em square with background: currentColor
  • A CSS mask masks the square in the shape of the icon (But, but, but …browser support?!? Fear not! Masks are actually Baseline Widely Available nowadays)
  • A CSS property (--icon-start or --icon-end) is used to specify the icon to display, instead of an ad hoc one like --arrow. This means we can set any element’s icon from any place that accepts declaration, including via inline styles

For simplicity, I will only discuss --icon-start/::before in the rest of this section, but everything applies identically to --icon-end/::after and any additional ones.

::before {
	content: "";
	display: inline-block;
	width: 1em;
	height: 1em;
	background-color: currentColor;
	mask: var(--icon-start) no-repeat center / contain;
}

Why not use aspect-ratio?

You may be wondering why I’m specifying the size twice instead of width: 1em; aspect-ratio: 1. Flex items stretch by default, and a stretched size is definite, so aspect-ratio is ignored. Since icons so often live in buttons, and buttons are so often display: flex, an explicit height is far more robust. Grid happens to be fine (align-self: normal behaves as start for items with an aspect ratio), but flex has no such exception.

Unfortunately, you need to repeat the pseudo-element contents for every type of pseudo-element you want to be able to support icons on. Mixins will eventually fix that.

Restricting it to only elements that actually have an icon

As described above, this would apply to all elements, which is far from ideal!

We can use a style query (finally Baseline! 🎉) to restrict this to only elements with the --icon-start property set:

@container style(--icon-start) {
	::before {
		/* same as above * /
	}
}

We would also need to register --icon-start as non-inheriting via @property, otherwise any container with an icon would sprout an icon for every single descendant (including inline formatting like <strong>, <em> etc!), which we definitely don’t want.

@property --icon-start {
	syntax: '*';
	inherits: false;
}

And then just explicitly inherit them in the pseudo-element:

@container style(--icon-start) {
	::before {
		--icon-start: inherit;
		/* same as above * /
	}
}

But can I really depend on style queries?

Style queries are Baseline 2026, which sounds quite cutting edge. However, if you look at market share, it is supported in ~93% of users’ browsers worldwide per Can I Use data. While this data under-represents old Chrome Android (it lumps all Chrome Android under its latest version), Chrome shipped style queries in 2023 (in version 111) and Chrome Mobile users do seem to upgrade pretty quickly, so the real number won’t be meaningfully lower.

How is this possible? If you sort by date, you will see that all major browsers except Firefox had shipped style queries by 2024. Firefox was the last one to ship them, in May 2026.
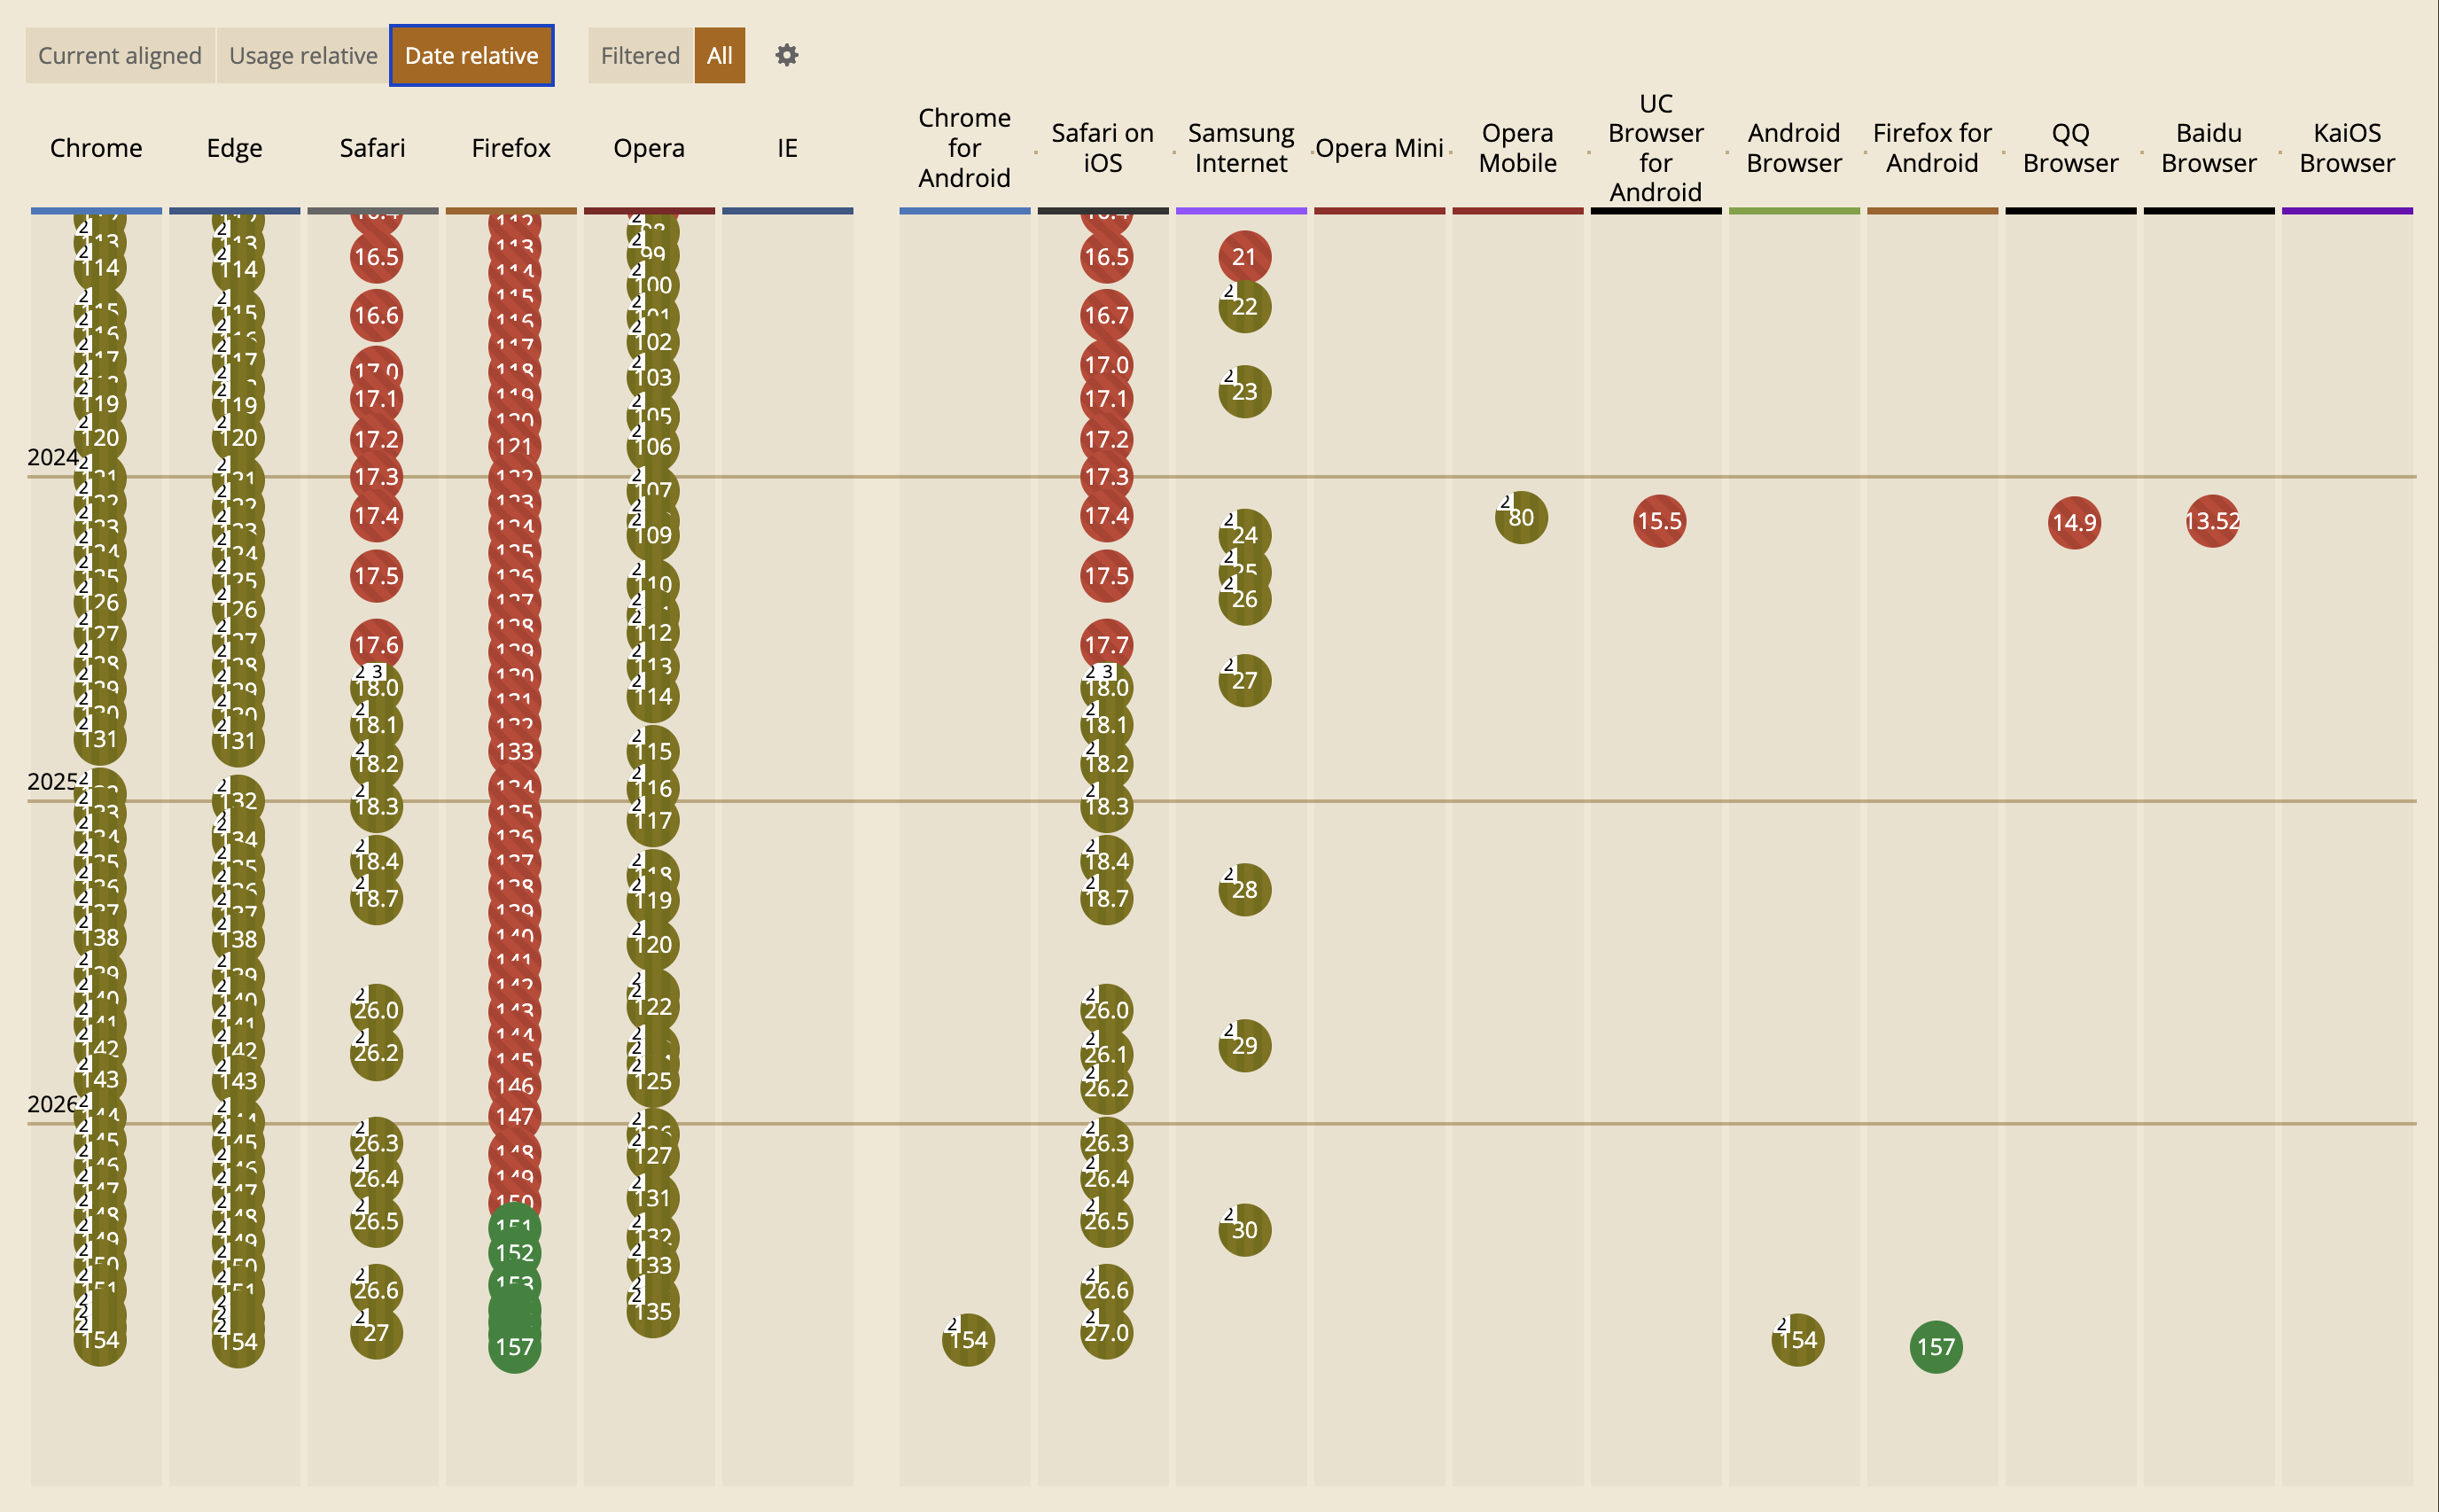
Sorting style queries by date on CanIUse

Now, let’s see the Usage relative chart:
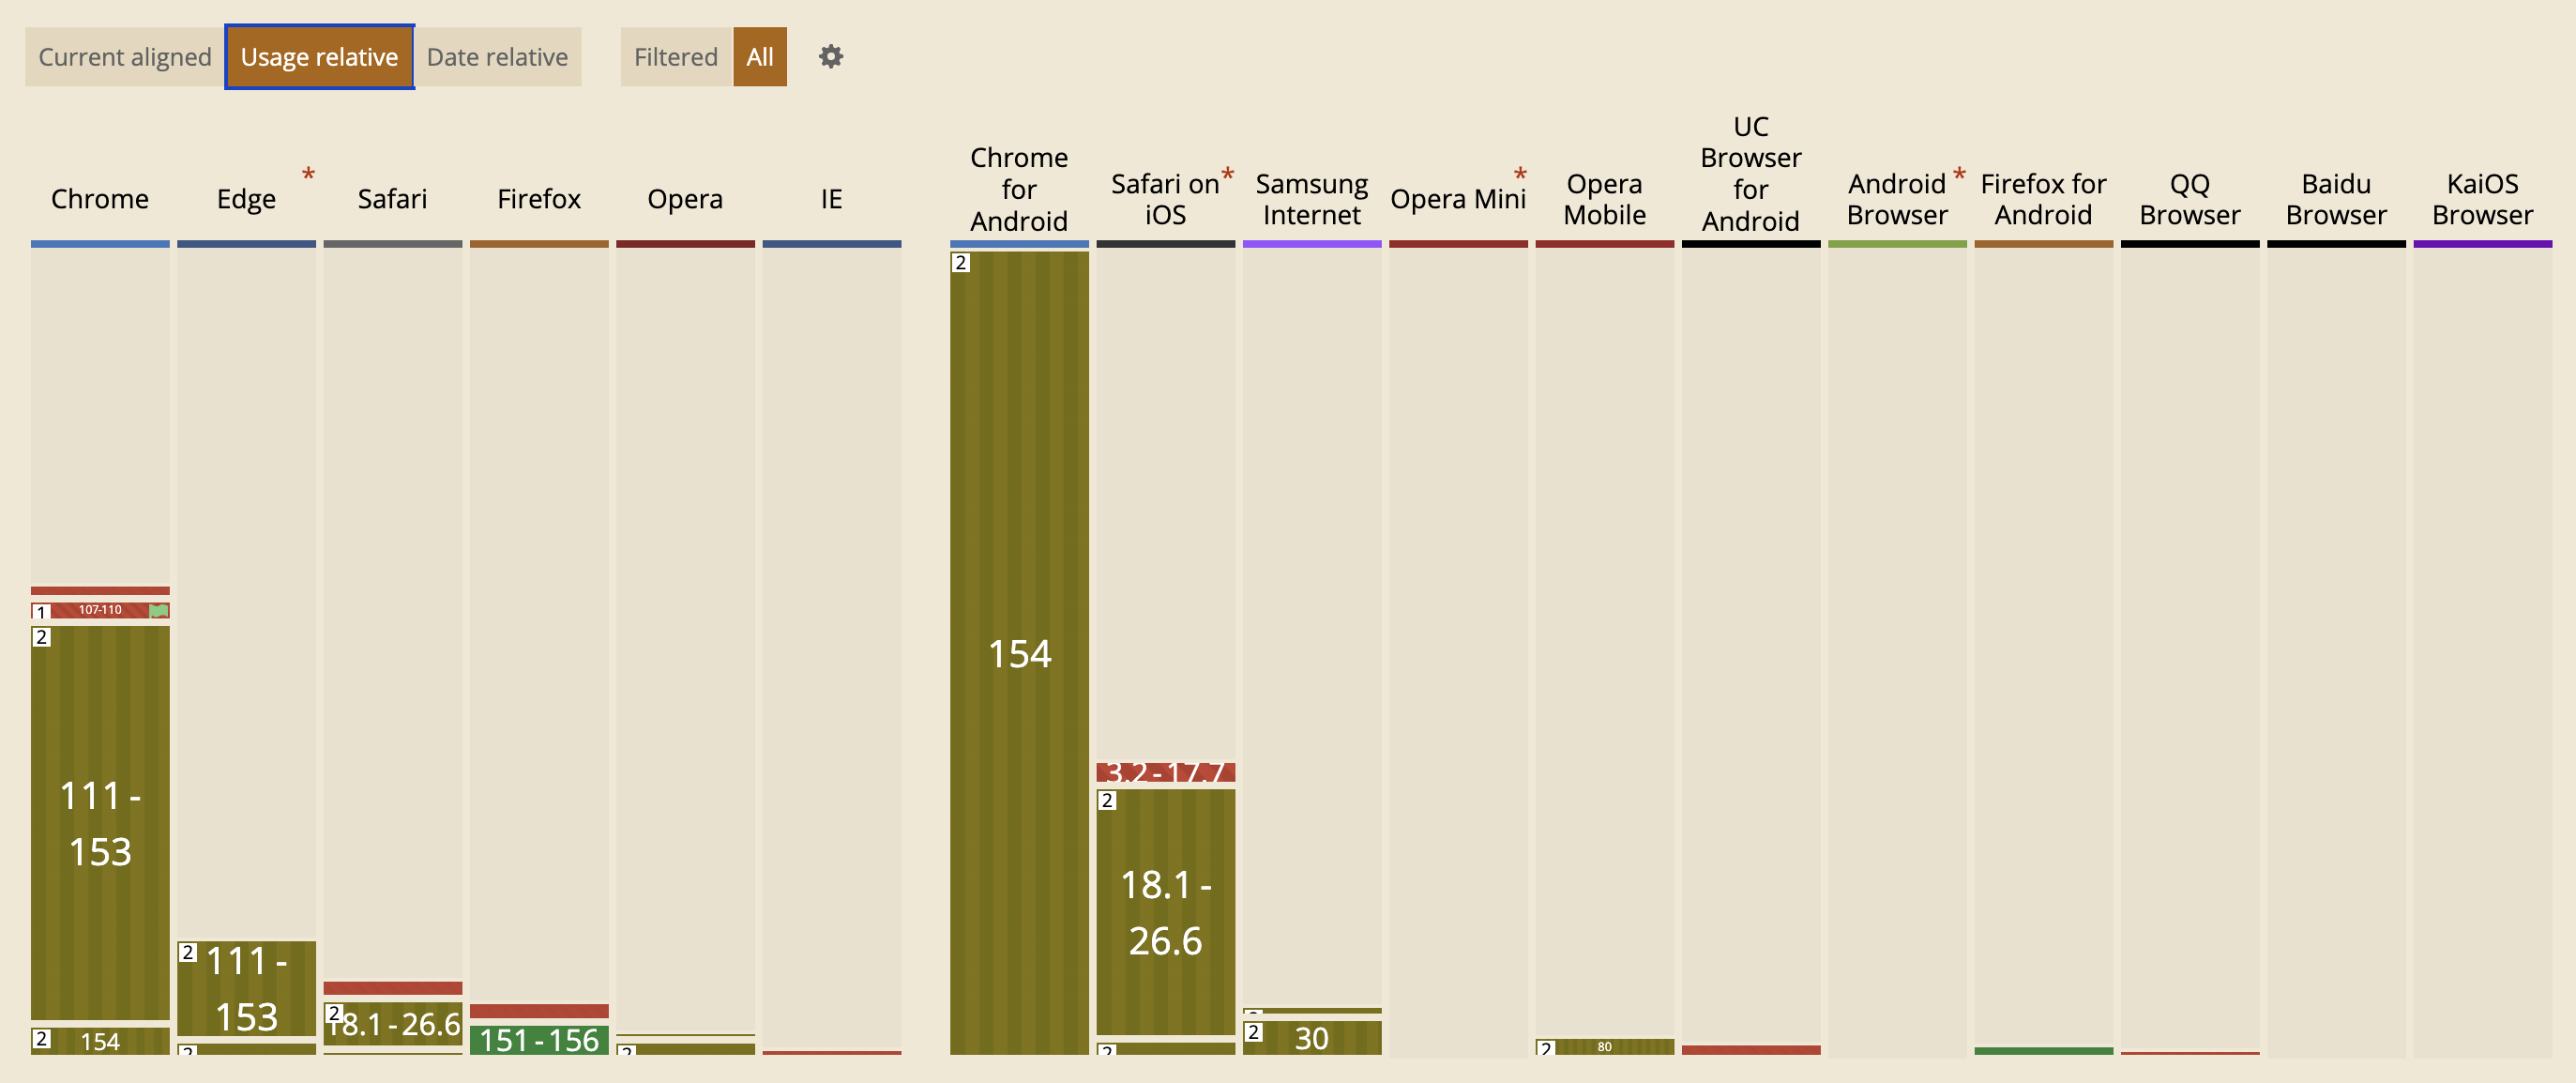
Sorting style queries by market share on CanIUse

Firefox as a whole accounts for 2.28% of worldwide market share.

Now, I’m not saying ignore Firefox because of its low market share! That would be a d*ck move, comparable to making UIs inaccessible because screen reader users are a minority. Some things matter more than their raw numbers might indicate, and not excluding Firefox is essential for the Web to remain open, interoperable, and not controlled solely by large companies.

That said, for features that have shipped in every major browser, I think it’s defensible to take market share into account. Baseline tiers are a great …baseline, but no compact metric could possibly convey this kind of granularity.

Especially for something like this, where things generally still work fine without icons, it’s a plausible strategy to treat icons as a progressive enhancement and just accept not having them in the 7% of browsers that don’t support them.

For the cases where icons are crucial, (e.g. icon-only controls) we can use a class (e.g. .icon, .icon-start, .icon-end, etc), so that older browsers with no style query support still get them.

Then, how much you want to lean in to progressive enhancement depends on how widely you rely on the class vs the style query.

You could even add other known selectors to it e.g. inline styles or known selectors with icons:

.icon-start,
[style*="--icon-start:"],
button.delete {
	&::before {
		/* ... */
	}
}

Do note that unrestricted attribute selectors like that can be slow, so use them judiciously.

One issue with the class approach is that it hardcodes icon presence, even if you can still tweak the icon itself via CSS custom properties.

One way to deal with this is to specify a content value that becomes IACVT if the custom property has no value, which would make the entire pseudo-element disappear:

.icon-start::before {
	content: image-set(
		linear-gradient(transparent 0 100%),
		var(--icon-start)
	);
	/* ... */
}

This will resolve content to a transparent image if --icon-start is defined, and to unset → none if it is not, which will effectively remove the pseudo-element. And yes, image-set() is Baseline Widely Available. It doesn’t remove any of the other properties, so it still cannot compose with other ::before styles, so don’t apply it so broadly it can clash with other elements that may have ::before styles.

Adding polish

The styles above are a start, but we can do better:

  • Customizable color and size: Rather than hardcoding currentColor and 1em, read them from custom properties with those as fallbacks: background-color: var(--icon-style-color, currentColor) and width: var(--icon-style-size, 1em) (same for height). Since they inherit, you can style every icon in a subtree by setting them on an ancestor, without ever touching the pseudo-element. The --icon-style- prefix keeps them from colliding with the icons themselves, which are also --icon-*.
  • Preserve in forced colors mode: forced-color-adjust: none; to keep the mask fill in forced-colors mode. currentColor will still follow the forced text color.
  • Don’t get in the way of pointer interactions: pointer-events: none so that it doesn’t trap clicks it shouldn’t.
  • Don’t shrink in flex containers: flex: none. An empty pseudo-element has a zero minimum size, so in a flex button it is the first thing to shrink when the label is long, and it can shrink all the way to zero. An icon’s size is a design decision, not something layout pressure should negotiate.
  • Vertical centering: I add vertical-align: calc(0.5cap - size / 2 - 0.02em); to center the icons on the cap height and nudge them a tiny bit upwards (our eyes weigh the space above the icon more than the space below it, so if something is perfectly centered mathematically, it will look a bit low). With a customizable size and offset, that becomes calc(0.5cap - var(--icon-style-size, 1em) / 2 + var(--icon-style-voffset, -0.02em)), so that the icon’s center stays put as it grows.
  • Spacing from text: margin-inline-end: var(--icon-style-spacing, .3em); to add a bit of space between the icon and the content (margin-inline-start for ::after). Make sure to remove it for standalone icons.
  • Accessibility: The pseudo-element has no text, so assistive technology ignores it entirely, which is exactly what we want for an icon next to a label. Icon-only controls still need a name, and we can let the icon provide one via alternative text for generated content: content: "" / var(--icon-style-alt, ""), so that <button style="--icon: var(--icon-trash); --icon-style-alt: 'Delete'"> is announced as “Delete”. aria-label on the control itself still works, of course.

Working around Safari bugs

Putting it all together so far, we get something like this

<link rel="stylesheet" href="icon-tokens.css">
<link rel="stylesheet" href="styles.css">
<style>
/* Icon system */
/* Icon defs on :root */
@import url("icon-tokens.css");

@property --icon-start {
	syntax: '*';
	inherits: false;
}

@container style(--icon-start) {
	::before {
		--icon-start: inherit;
		content: "" / var(--icon-style-alt, "");
		display: inline-block;
		overflow: hidden;
		/* Centers the icon on the cap height: https://blog.kizu.dev/cap-height-align/
		   overflow: hidden makes the box's baseline its bottom edge (clip does not). */
		vertical-align: calc(
			0.5cap - var(--icon-style-size, 1em) / 2 + var(--icon-style-voffset, -0.02em)
		);
		width: var(--icon-style-size, 1em);
		height: var(--icon-style-size, 1em);
		margin-inline-end: var(--icon-style-spacing, .3em);
		background-color: var(--icon-style-color, currentColor);
		mask: var(--icon-start) no-repeat center / contain;
		pointer-events: none;
		flex: none;
		forced-color-adjust: none;
	}
}
</style>
<style>
/* Button styles (relevant subset) */
button {
	:where(&) {
		/* Redirect --icon to something more specific */
		--icon-start: var(--icon);
	}

	&:hover {
		--icon-start: var(--icon-hover, var(--icon));
	}

	&.danger {
		--icon: var(--icon-trash-outlined);

		&:hover {
			--icon: var(--icon-trash);
		}
	}
}
</style>

<button>No icon</button>
<button style="--icon: var(--icon-github)">One-off icon</button>
<button class="danger">Default icon</button>
<button class="danger">With <strong>inline <em>style</em></strong></button>
<button style="--icon: var(--icon-github); --icon-hover: var(--icon-link-external);">GitHub to link</button>

If you’re viewing the demo in Chrome or Firefox, it should work as expected. If you’re viewing the demo in Safari, you’ll already know that it’s severely broken.

My research on this resulted in filing not one, but two Safari bug reports. The good news is that all have workarounds. The bad news is that these workarounds force us into suboptimal code, and unless we’re willing to ship a different version to Safari, everyone suffers.

Working around WebKit bugs #301609 and #320220

WebKit bug #301609 was the one that really threw a spanner in the works the most for this technique: The tl;dr is if you use what I wrote above, the icons will not show up in Safari until the user interacts with them in some way (e.g. hover, focus, etc.).

Thankfully, I found a CSS workaround:

/* Workaround for https://bugs.webkit.org/show_bug.cgi?id=301609
   A zero-duration animation on the pseudo-elements forces WebKit
   to re-resolve style, this time against the correct container.
   Must be outside the @container block (which is false on the first pass).
*/
@keyframes webkit-301609 {}

/* List all relevant pseudo-elements here */
::before, ::after {
	animation: webkit-301609 0s;
}

However, since this applies an animation to all ::before and ::after pseudo-elements, ideally we’d want to restrict it a bit, and make it easier to override by wrapping it in a layer.

/* Workaround for https://bugs.webkit.org/show_bug.cgi?id=301609
   A zero-duration animation on the pseudo-elements forces WebKit
   to re-resolve style, this time against the correct container.
   Must be outside the @container block (which is false on the first pass). */
@keyframes webkit-301609 {}

/* Safari 18+. WebKit-only properties ORed for robustness */
@supports ((-webkit-nbsp-mode: normal) or (-webkit-touch-callout: none) or (font: -apple-system-body)) and (content-visibility: auto) {
	@layer webkit-301609-fix {
		::before, ::after {
			animation: webkit-301609 0s;
		}
	}
}

Turns out this seems to magically also fix WebKit bug #320220, which is also relevant here.

At this point our demo works almost perfectly!

<link rel="stylesheet" href="icon-tokens.css">
<link rel="stylesheet" href="styles.css">
<style>
/* Icon system */
/* Icon defs on :root */
@import url("icon-tokens.css");

@property --icon-start {
	syntax: '*';
	inherits: false;
}

@container style(--icon-start) {
	::before {
		--icon-start: inherit;
		content: "" / var(--icon-style-alt, "");
		display: inline-block;
		overflow: hidden;
		/* Centers the icon on the cap height: https://blog.kizu.dev/cap-height-align/
		   overflow: hidden makes the box's baseline its bottom edge (clip does not). */
		vertical-align: calc(
			0.5cap - var(--icon-style-size, 1em) / 2 + var(--icon-style-voffset, -0.02em)
		);
		width: var(--icon-style-size, 1em);
		height: var(--icon-style-size, 1em);
		margin-inline-end: var(--icon-style-spacing, .3em);
		background-color: var(--icon-style-color, currentColor);
		mask: var(--icon-start) no-repeat center / contain;
		pointer-events: none;
		flex: none;
		forced-color-adjust: none;
	}
}

/* Workaround for https://bugs.webkit.org/show_bug.cgi?id=301609
   A zero-duration animation on the pseudo-elements forces WebKit
   to re-resolve style, this time against the correct container.
   Must be outside the @container block (which is false on the first pass). */
@keyframes webkit-301609 {}
/* Safari 18+ only */
@supports ((-webkit-nbsp-mode: normal) or (-webkit-touch-callout: none) or (font: -apple-system-body)) and (content-visibility: auto) {
	@layer webkit-301609-fix {
		::before, ::after {
			animation: webkit-301609 0s;
		}
	}
}
</style>
<style>
/* Button styles (relevant subset) */
button {
	:where(&) {
		/* Redirect --icon to something more specific */
		--icon-start: var(--icon);
	}

	&:hover {
		--icon-start: var(--icon-hover, var(--icon));
	}

	&.danger {
		--icon: var(--icon-trash-outlined);

		&:hover {
			--icon: var(--icon-trash);
		}
	}
}
</style>

<button>No icon</button>
<button style="--icon: var(--icon-github)">One-off icon</button>
<button class="danger">Default icon</button>
<button class="danger">With <strong>inline <em>style</em></strong></button>
<button style="--icon: var(--icon-github); --icon-hover: var(--icon-link-external);">GitHub to link</button>

Can you spot the bug that remains?

Working around WebKit bug #325900

There are two buttons that change their icon on hover: Default icon and Github to link. The former works, the latter doesn’t. WAT?!

So, there is a difference between them: .danger sets --icon on hover, whereas Github to link sets --icon-start directly, via --icon-hover. And --icon-start is registered as non-inheriting, which is quite relevant here.

Turns out that --non-inherited: inherit used to not work at all in Safari until 2023, and there are still some cases where it reproduces today. The investigation resulted in WebKit bug #325900 being filed.

There are a few solutions here of which the only workable one seems to be to register the property as inherited after all, and add a style query that resets it on descendants:

@property --icon-start {
	syntax: '*';
	inherits: true;
}

@container style(--icon-start) {
	* {
		--icon-start: initial;
	}
}
/* ... */

It’s a bit more fragile and likely slower, so ideally we’d only ship it to Safari. @supports can only detect features, not bugs, so once more we have to resort to sniffing WebKit. Conveniently, @property is allowed inside conditional rules, and when a property is registered multiple times, the last registration wins:

@property --icon-start {
	syntax: '*';
	inherits: false;
}

/* Workaround for https://bugs.webkit.org/show_bug.cgi?id=325900
   `inherit` on non-inherited registered properties is unreliable,
   so register them as inherited and reset them on descendants instead. */
@supports ((-webkit-nbsp-mode: normal) or (-webkit-touch-callout: none) or (font: -apple-system-body)) and (content-visibility: auto) {
	@property --icon-start {
		syntax: '*';
		inherits: true;
	}

	@layer webkit-325900-fix {
		@container style(--icon-start) {
			* {
				--icon-start: initial;
			}
		}
	}
}
/* ... */

The layer means any unlayered declaration wins over the reset, even zero-specificity ones like :where(button) { --icon-start: var(--icon) }.

Demo

Putting it all together, here is the final demo, with both workarounds applied:

<link rel="stylesheet" href="icon-tokens.css">
<link rel="stylesheet" href="styles.css">
<style>
/* Icon system */
/* Icon defs on :root */
@import url("icon-tokens.css");

@property --icon-start {
	syntax: '*';
	inherits: false;
}

@container style(--icon-start) {
	::before {
		--icon-start: inherit;
		content: "" / var(--icon-style-alt, "");
		display: inline-block;
		overflow: hidden;
		/* Centers the icon on the cap height: https://blog.kizu.dev/cap-height-align/
		   overflow: hidden makes the box's baseline its bottom edge (clip does not). */
		vertical-align: calc(
			0.5cap - var(--icon-style-size, 1em) / 2 + var(--icon-style-voffset, -0.02em)
		);
		width: var(--icon-style-size, 1em);
		height: var(--icon-style-size, 1em);
		margin-inline-end: var(--icon-style-spacing, .3em);
		background-color: var(--icon-style-color, currentColor);
		mask: var(--icon-start) no-repeat center / contain;
		pointer-events: none;
		flex: none;
		forced-color-adjust: none;
	}
}

/* Workaround for https://bugs.webkit.org/show_bug.cgi?id=301609
   A zero-duration animation on the pseudo-elements forces WebKit
   to re-resolve style, this time against the correct container.
   Must be outside the @container block (which is false on the first pass). */
@keyframes webkit-301609 {}

/* Safari 18+ only */
@supports ((-webkit-nbsp-mode: normal) or (-webkit-touch-callout: none) or (font: -apple-system-body)) and (content-visibility: auto) {
	@layer webkit-301609-fix {
		::before, ::after {
			animation: webkit-301609 0s;
		}
	}

	/* Workaround for https://bugs.webkit.org/show_bug.cgi?id=325900
	   `inherit` on non-inherited registered properties is unreliable,
	   so register them as inherited and reset them on descendants instead. */
	@property --icon-start {
		syntax: '*';
		inherits: true;
	}

	@layer webkit-325900-fix {
		@container style(--icon-start) {
			* {
				--icon-start: initial;
			}
		}
	}
}
</style>
<style>
/* Button styles (relevant subset) */
button {
	:where(&) {
		/* Redirect --icon to something more specific */
		--icon-start: var(--icon);
	}

	&:hover {
		--icon-start: var(--icon-hover, var(--icon));
	}

	&.danger {
		--icon: var(--icon-trash-outlined);

		&:hover {
			--icon: var(--icon-trash);
		}
	}
}
</style>

<button>No icon</button>
<button style="--icon: var(--icon-github)">One-off icon</button>
<button class="danger">Default icon</button>
<button class="danger">With <strong>inline <em>style</em></strong></button>
<button style="--icon: var(--icon-github); --icon-hover: var(--icon-link-external);">GitHub to link</button>

Using remote icons

When using icons from SVG files it’s important to remember that any relative URL will resolve relative to the CSS file that uses the icon, not the one it’s defined in. In practice, this forces you to use root-relative URLs (e.g. url('/assets/icons/trash.svg')), otherwise you’ll have random breakage in any nontrivial project structure.

Registered properties are supposed to fix this: the computed value of a registered <url> or <image> is an absolute URL, resolved against the stylesheet that declared it. So in theory, you could register the icon properties as <image> via @property and specify their values via initial-value:

@property --icon-caret {
	syntax: '<image>';
	inherits: true;
	initial-value: url("icons/caret.svg");
}

This would also be better for other reasons:

  • There won’t be hundreds of --icon-… variables in dev tools for :root
  • You can even override it temporarily with another icon for a specific context, and reset it wherever via --icon-caret: initial;

Unfortunately, in practice this only works in Firefox. I put together a test page that tries four different syntaxes, with the URL either in initial-value or declared on :root, and the results are all over the place:

  • Firefox gets everything right.
  • Safari resolves URLs in initial-value against the document, regardless of syntax. Values declared on :root work with every syntax.
  • Chrome has the same initial-value bug, and additionally, values declared on :root only work when the syntax starts with <url>: <url> and <url> | <image> work, but <image> and <image> | <url> resolve against the document.

So today, the only thing that works everywhere is to register the icon properties with a syntax that starts with <url>, and still declare the actual icons on :root:

@property --icon-caret {
	syntax: "<url> | <image> | none";
	inherits: true;
	initial-value: none;
}

:root {
	--icon-caret: url("icons/caret.svg");
}

This loses most of the benefits above, but it does make relative URLs work. The obvious downside is DX: each icon now needs to be in two places, and there is a lot more boilerplate. The plain :root declarations can be managed by hand, even for many icons. This starts requiring a build step after a dozen or so.

Additionally, registered properties are currently global and don’t work in shadow roots, so that may not fit every use case.

Another option might be to go through all --icon-* properties in :root and register them via JS:

const cs = getComputedStyle(document.documentElement);
const iconTokens = [...cs].filter(p => p.startsWith("--icon-") && !p.startsWith("--icon-style"));
for (let name of iconTokens) {
	CSS.registerProperty({ name, inherits: true, syntax: "<url> | <image> | none", initialValue: "none" });
}

Other caveats

Multi-color icons

Since the icon is a mask, this technique only works for monochrome icons (varied opacity is fine) — but most icons are monochrome these days anyway. If you really need more, Allegro’s engineers stack masks on the element and both its pseudo-elements, which gets you up to three colors from a single element.

But what about full color icons, e.g. emojis? Or textual icons, e.g. …emojis?

In theory, the technique can work fine with them, these are actually easier! For full color icons you just set them as background images, no masking required. And for textual icons, you can just set them directly on the content property.

The only challenge here is branching between these three. But this may be the subject of a future post, as this is already getting quite long.

Icons with backgrounds etc.

Since the entire pseudo-element is masked, you cannot apply a separate background or border to it. For that, you’d need an actual element (e.g. <i class="icon">), and you can apply the borders, backgrounds, etc to that.

What about animation?

Completely arbitrary animation would obviously still require inline <svg> elements.

But what about predefined animations? A checkmark or X being drawn, a hamburger animating to a close button, etc.?

I thought I had figured out a way. And I did get so close! Close enough that the whole saga deserves its own post, so stay tuned 😉

The North Star

The system above gets us pretty good DX (especially without the Safari bugs!), but some things are still not ideal.

First, the masking approach does introduce some limitations it would be nice to be able to get rid of.

Then, signal-to-noise ratio could be even better:

  • What if --icon: trash could work, instead of --icon: var(--icon-trash)?
  • What if <button icon="check"> could work, instead of <button style="--icon: var(--icon-check)">? (ignoring HTML restrictions around attribute names for a bit)

And while consumers > producers, it would be really nice if adding support for new pseudo-element types did not require such a song-and-dance.

A number of upcoming CSS features get us closer to this North Star.

Linked parameters = arbitrary customizations!

If you haven’t heard of the new CSS Linked Parameters spec, it’s the best thing that has happened to CSS icons in a long time.

It allows us to pass arbitrary data to any resource that supports it (and yes, SVG is one of them), which means we can customize icons in ways that were previously impossible, such as changing the stroke width, color, or even entirely arbitrary customizations, since SVG also supports style queries.

And as of a couple weeks ago, it also supports passing color and accent-color without any double opt-in from the icon, which means we can use any existing icon library without it having to be updated to utilize them!

--icon: url("icons/link.svg");
link-parameters: param(color)
	param(--stroke-width, 2px);

There are some limitations still, but it is being actively designed, Firefox has shipped an earlier version of the spec, and is one of the top Interop 2027 proposals, so I’m quite hopeful it can make it much easier to use icons in CSS. Keep a close eye on that one!

Soon we won’t need to use backgrounds

Currently, due to a technicality in how the content property is handled, we have to rely on background images to include icons, because otherwise width and height don’t work. Even Link Parameters by itself won’t change that, it will just allow us to get rid of the masking hack.

Thankfully, we (CSS WG) recently resolved on a change that will fix this! (pending compat analysis)

ident() would let use identifiers instead of CSS variables

ident() is the CSS feature you didn’t know you were desperate for, and deserves an article of its own for its myriad of use cases in design systems. Until I write that, Bramus has a great write-up.

But more relevant to icons, once ident() is widely supported, we can construct variable names dynamically, meaning we can use plain identifiers instead of CSS variables, which will make the syntax even cleaner, meaning we’d be able to translate --icon-start-trash into var(--icon-start-trash) at the cost of a little complexity on the producer side:

--_icon-start: var(ident(--icon- var(--icon-start)));

Yes, it’s ugly, but it’s also an implementation detail that’s not exposed to icon consumers, so I think the tradeoff is worth it.

Combined with expanded attr(), which is getting there with only Safari remaining (Safari TP already supports it), this also unlocks ad hoc icons via a plain attribute:

<i data-icon="trash"></i>

[data-icon] {
	--_icon-start: var(ident(--icon- attr(data-icon)));
}

More ergonomic mass property registration

We recently resolved to support registering multiple properties with the same descriptors at once via @property --prop1, --prop2, --prop3 { … }, this won’t help much here, since we need different initial values.

You could of course register multiple properties with the <image> syntax and then also set their actual icons on :root but now you need to add each icon in two places, so I’d consider it worse than the current expanded @property syntax.

However, another direction we are exploring in the CSS WG is a shorthand form of @property that would allow more compact registration. For the icon above it would look like this:

@property --icon-caret <image> = url("icons/caret.svg");

@mixin will allow us to centralize pseudo-element styles

Currently, we have to repeat a lot of styles between the different pseudo-elements. If we want to also have a fallback class that doesn’t depend on style queries, we need to repeat them four times!

With @mixin we can just do:

@mixin --icon {
	content: "";
	display: inline-block;
	overflow: hidden;
	vertical-align: calc(0.5cap - 0.5em - 0.02em);
	width: 1em;
	height: 1em;
	background-color: currentColor;
	mask: no-repeat center / contain;
	pointer-events: none;
	flex: none;
}

@mixin --icon-start {
	@apply --icon;
	--icon-start: inherit;
	margin-inline-end: .3em;
	mask-image: var(--icon-start);
}

@mixin --icon-end {
	@apply --icon;
	--icon-end: inherit;
	margin-inline-start: .3em;
	mask-image: var(--icon-end);
}

And then we can use them all over the place:

.icon {
	--icon-start: var(--icon);
}

.icon::before,
.icon-start::before {
	@apply --icon-start;
}

.icon-end::after {
	@apply --icon-end;
}

@container style(--icon-start) {
	::before {
		@apply --icon-start;
	}
}

@container style(--icon-end) {
	::after {
		@apply --icon-end;
	}
}

@container style(--icon-marker) {
	::marker {
		@apply --icon-marker;
	}
}

/* and so on… */

Use it today via @nudeui/icons!

I published a package that puts together everything from this post, polish and warts included. It contains no icons, just the icon system. You’d just include it and then you can use --icon-start and --icon-end in your styles. It also includes the .icon, .icon-start, and .icon-end classes. It does not wrap its contents in a layer to give you maximum choice, but I’d recommend importing it in a layer anyway.

@nudeui/icons


  1. There’s a small chance I may have been the first to use a web font for UI icons, in 2010. I even worked as Product Lead at Font Awesome for a bit. ↩︎

  2. I’m using “components” here in the general sense of a reusable UI element, not in the sense of a framework component or a custom element. E.g. a styled <button> or an <article class="callout"> would qualify. ↩︎

  •  

The best dark mode toggle is probably none

About a month ago, I wrote an article recommending that if you are going to have an always visible control for switching between light and dark mode, it should be a two-state toggle that alternates between system and whatever the current opposite of system is, not a tri-state one (system, light, dark). If you are forced to include such a control (say, someone is pointing a gun at you and shouting “code dammit! now!”), I stand by that recommendation: use two states, as described in the article.

But the article explicitly doesn’t answer the question “should you have one at all?”. I was much more neutral on this at the time of writing. I am now firmly in the “no” camp. More on that below.
The two-state toggle design proposed in my article can actually express all three data model states.

What I didn’t mention was that I had been meaning to write this article for years, but had been putting it off. What finally pushed me to write it 1 was that Bramus argued that some Modern Web Guidance I had written on this was incorrect. He assumed it was an oversight, that I simply hadn’t thought of all the implications. On the contrary, my recommendation had been the result of some very careful consideration, combined with my HCI background. Surely, if I explained my reasoning well, he would see it!

I tried to convince him through discussion (in person, as we were both in Berlin at the time) to no avail. My conclusion was that I must be doing a poor job explaining my reasoning, and that a blog post was in order to explain it properly. Surely, after that he would be convinced!

And thus, one of my most successful blog posts was born.

Reactions

This article really made the rounds. It was shared by hundreds of folks, including people I really respect, such as:

and many others. A lot more who hearted it.

Some of the quotes really made me blush ☺️. Here is a small selection:

I wasn't sold on this until I got to the implementation. It's so smart I'm probably gonna spend my day redesigning at least one or two of the theme toggles I've built.

[image or embed]

— Josh Collinsworth (@collinsworth.dev) August 6, 2026 at 4:30 PM

This is one of the best articles I've seen about the difference between letting the underlying settings dictate the structure of your UI, and thinking about what actually makes sense to your users. Really, really insightful, and definitely worth ten minutes of your time.

[image or embed]

— Dylan Beattie (@dylanbeatt.ie) August 6, 2026 at 4:43 PM

Once upon a time web developers regularly wrote blog posts about UX design that were this good. Thank you to @lea.verou.me for keeping the art alive.

[image or embed]

— Sam Littlefair (@littlefair.ca) August 6, 2026 at 6:19 PM

OK, I'm persuaded. For a toggle in the header or footer, a toggle between 'system colour scheme' ↔️ 'the opposite' is better than system ↔️ light ↔️ dark.

Lea is a master of user experience.

[image or embed]

— Josh Tumath (@joshtumath.uk) August 7, 2026 at 2:19 AM

This is a great post to read, lots of useful UX and usability thoughts. I like this approach.

[image or embed]

— Ahmad Shadeed (@ishadeed.com) August 7, 2026 at 11:09 AM

Really, really appreciate the deep thinking about the user's _actual_ needs and intentions, irrespective of conventions and commonalities, in this brilliant piece. 👌

[image or embed]

— sylvia (@svillegas.com) August 12, 2026 at 9:12 PM

Tri-state theme controls always make me think™. Minor friction, but unnecessary. We can do better.

The intent is simple: "flip the theme". The UI only needs two states: light and dark. “Follow system” can stay under the hood.
The algorithm I use in my projects ➡️ https://t.co/8s15vxVFY2

— Alexey Ardov (@ardovalexey) August 4, 2026

This is the missing piece of the puzzle for theming controls in the UI. I’m a little bit jealous I didn’t think of it myself :) https://t.co/HDjvCO1UhN

— zerts (@zertsdev) August 7, 2026

Articles were written, for and against it. This is a small sample (I couldn’t find most of them):

Unfortunately, I failed to convince Bramus, who two weeks later wrote a blog post of his own 😢

Bramus’ objections

Bramus’s central objection to the two-state toggle is this:

Consider this scenario:

  1. The user’s OS is set to auto-switch Light/Dark based on the time of day.
  2. They visit a website during the day, so they see the Light theme.
  3. Using the site’s two-state control, they try out the Dark theme. They decide they don’t like it, so they revert it back to Light.
  4. They visit the site again at night.

Because the two-state toggle maps one of its values back to “System” behind the scenes, the site is now dark, although they explicitly chose light the last time they interacted with the control. You may now expect an incoming bug report for the control not properly working …

His reasoning is that a tri-state control sidesteps this by letting users pin light or dark explicitly at all times, which he also considers clearer overall, since all three options are always visible.

An easily-misread framing: auto-switching by time of day works fine

In both of his posts, Bramus initially frames the disagreement as “this will not work for users that have their system set to automatically switch to dark mode at night”, which is false: it will work just fine. The control covers all three intents with a single click. Not a single click per session — a single click, ever. The variable is around when that click happens. In fact, I dedicated a whole section to this exact scenario in the original article, which he acknowledges but says he’s “not buying it”.

He does later explain what he sees as broken in more detail, but since most people do not read very carefully, there were a couple people who agreed thinking the two-state toggle I was proposing is somehow broken for auto-switching systems.

His poll asks the wrong population the wrong question

Bramus asked developers which control they build, then used the tally as evidence for which control is usable!

Those are different questions. Developer preference is confounded with convention and implementation convenience. If asking developers what they build gave us data on what UI is most usable, we wouldn’t need user testing, ever 😅

We optimize UIs around user goals, not around developer preferences. In fact, more often than not there is a tension between what is easiest to build and what is optimal for usability, because usability is all about abstracting the underlying model (which is closer to the machine), and exposing a model that is closer to how the user thinks.

“Local feedback” doesn’t solve the gulf of evaluation

Responding to the objection that two of the three options produce the same visual result, Bramus writes that

“the selected option does change so there is local visual feedback.”

Sure, the button highlights, and that’s better than if nothing happened at all. But the button is the means, not the end. The user clicked it to change the page, not the button!

When the control changes and the page doesn’t, the user acted and the world didn’t respond — that’s Norman’s gulf of evaluation. Widget feedback with an unchanged outcome is the failure, not a mitigation of it. It’s also why NN/g’s toggle guidelines insist a toggle has an immediate, visible effect.

Implementation simplicity != cognitive load

Bramus says:

“there is nothing complex about a tri-state control” […] it’s “the Dumbest Approach™ one could possibly take.”

Yes, it is — that was exactly my point when I wrote that tri-state toggles are implementation-driven UI. The actual user goal in the moment is not abstract (“system” is a variable, not a value), it is concrete (light or dark). Using a tri-state control involves a mental translation from the three states to the actual user goal. It’s of course very short, almost imperceptible to users — but avoiding this type of unnecessary mental processing was exactly the point of Don’t Make Me Think — which ironically Bramus cites to support his argument.

“Clarity over brevity” is one of these platitudes that everyone agrees with 2, but people use it to support even entirely contradictory positions. Whenever I see one of these, my tendency is to prod deeper; clarity about what? Clarity about the implementation’s state machine is not clarity about outcome. The tri-state is optimized for people who already hold the system model — which is, again, developers.

The failure scenario is rare, and recovery is cheap

Bramus’ central objection is that with a two-state control, forcing a mode “shouldn’t be dependent on the time of the day.” The scenario he gives requires OS auto-switching, plus toggling and reverting within a session, plus revisiting after the switch, plus remembering the earlier interaction.

Usability problems are prioritized by frequency × impact × persistence, and this scenario scores low on all three. The tri-state, by contrast, taxes every interaction with a state most users never need. Optimizing the common path over a rare, cheaply recoverable edge case is not an antipattern, it’s precisely how usability engineering is supposed to work!

“Once a user has interacted with a control, they have mentally set it to the specific state”

People don’t remember settings on sites they rarely visit. For them, a site that tracks the OS matches expectations; a stale override fighting the OS is the actual surprise (“why is this site light at night?”). And in practice no user devotes nearly as many cycles contemplating why the theme of a website they visited to accomplish a task matches or doesn’t match their OS, at most they just toggle and move on. It’s not even System 2 thinking. If there is a recurring problem, sure, they may think about it more consciously, a few may even report a bug. But something that’s fixed with a single click, in a very obvious way? It might not even surface to the conscious mind.

Bramus himself admits that his scenario is purely theoretical; he has never experienced it himself nor seen anyone else experience it.

Once you’ve spent a lot of time and effort on something, you overestimate how much it matters to everyone else. This is true not just in UI design, but in all aspects of life, from any areas you’re an expert in to even your kids 4. Developers have spent days on this control, users will spend half a second at most. It’s the IKEA effect meeting the false-consensus effect: you overvalue what you built, then assume users do too.

Alternative designs

My favorite part of the debate was that it spawned a number of alternative designs.

Some people were divided. They agreed with the reasoning, but still thought a tri-state toggle added clarity. So naturally, they did what UI designers do best: they designed, and the results are quite clever.

Others took a different, hilarious tack on the problem, and attempted to imagine the worst possible dark mode toggles.

Lawful Good 😇

Vale’s 3-in-2 toggle

The alternative that made the rounds most is Vale’s innovative design:

System Light Dark

The core premise is quite clever: Three states with the real estate of two icons (33% saving over the typical tri-state control — though still double that of a two-state control), and clarity about whether you’re selecting system or pinning a mode that happens to coincide with your current system setting.

However:

  • As Vale themselves admit, some users did not realize they could revert the option they had selected, simply because that’s not a common interaction pattern. Vale does say this was a minority of users, and that it was “immediately understood by the great majority of people [they] tested it with”, however I have doubts on whether this would hold true in the wild, when you haven’t already primed users to pay extra attention to the dark mode toggle.
  • Vale claims that “It only takes up the space of a two-state toggle”, but that’s not true. A two-state dark mode toggle only needs the real estate of one icon, not two. It’s possible to implement one that shows both icons simultaneously, but that’s rare.
  • In its default state, nothing communicates “system”. It is two icons with no indication of which is currently active. We understand that it’s a dark mode toggle, because it’s presented in isolation, in the context of an article about dark mode toggles. But used on an actual website, I wouldn’t be surprised if users had no idea how to use it and only figured it out by trial and error. Subtly highlighting what System currently resolves to could help here, but then we’re back distinguishing whether “light” means “System (light)” or “Light, always”.

But most importantly, this is adding significant implementation and UI complexity for something that the vast majority of users don’t devote nearly as much thought to as we think they do. In my opinion, this is admirable effort that is ultimately solving a non-problem.

Toni’s undoable two-state toggle

This is also quite interesting:

i feel this is a good trade off if you want to give users the most control, even though i see your point that this is possibly too niche of an edge case to justify.

did i do the UX version of premature optimization, or does this just suck too?

[image or embed]

— toni / link (@sarcevic.dev) August 9, 2026 at 2:49 AM

It’s a two-state toggle that pins light/dark when interacted with, but provides a clear button. This is similar to Bramus’ idea but with more polish.

As I said on bsky, I don’t think this particular design works because:

  • Spacing makes it look like these are separate controls, not one clearing the other’s selection
  • The clear button has nothing associating it with the color scheme toggle (not proximity, nor its icon).

But none of these are core to the idea, and could be fixed with a little more UI design massaging. If someone really wanted to have three states visible at all times, a reworked version of this would probably be the best way (and can be designed to occupy similar screen real estate as a two-state toggle).

Should anyone spend the time to do this rework? Like I wrote in the previous section, my opinion is that these efforts are pouring a great amount of brilliant creative energy into solving a non-problem, so I would not recommend it.

Chaotic Evil 😈

The Big Dark Mode Toggle Debate™ raged on for weeks, and I think my favorite part of it was the side thread of people taking the piss and coming up with the worst possible dark mode toggle designs imaginable 😅, possibly as a tribute or reprise of The Worst volume control UI.

I reject your two-state toggle and submit my own 4-state toggle. Pray that I do not increase it to 5.

[image or embed]

— Michael Ficarra (@michael.ficarra.me) August 6, 2026 at 5:02 PM


[image or embed]

— Michael Ficarra (@michael.ficarra.me) August 6, 2026 at 5:13 PM


[image or embed]

— Michael Ficarra (@michael.ficarra.me) August 6, 2026 at 5:18 PM

Of course, I had to participate:

Oh but why stop there? 🤣

[image or embed]

— Lea Verou, PhD (@lea.verou.me) August 6, 2026 at 5:25 PM

I actually strive for perfect clarity with my color theme pickers.

codepen.io/editor/chris…

[image or embed]

— Chris Coyier (@chriscoyier.net) August 23, 2026 at 5:51 PM

Did anyone already mention "Dark mode with spotLight"? No!? That's the only valid way.

Demo: codepen.io/t_afif/pen/Y… via @codepen.io

Debating about toggles? Well, I don't understand …

[image or embed]

— CSS by T. Afif (@css-only.dev) August 24, 2026 at 1:36 PM

Anything below 4 is unacceptable. right @svenning.io

[image or embed]

— Andreas Møller (@andreasmoller.dk) August 22, 2026 at 12:05 PM

This may be my favorite:

The current debate between 2 vs 3 state theme switchers is ridiculous. Everyone knows that the right answer is 100

#css #a11y

[image or embed]

— Andreas Møller (@andreasmoller.dk) August 22, 2026 at 11:59 AM

Two-state, tri-state, four-state...why should we concern ourselves with this anyway? I say users should not get this for free at all; therefore, I introduced a new mode in this article called capitalism mode ✅

codepen.io/editor/sunka…

#css

[image or embed]

— Sunkanmi Fafowora (@sunkanmifafowora.bsky.social) August 26, 2026 at 1:33 AM

Could the best dark mode toggle be …none?

However, my biggest insight from all of this is that while I stand by my original recommendation that in most cases, if you are going to have a dark mode toggle that is visible at all times, it should only have two states (system and opposite), I now think that for the vast majority of websites, you should not have such a toggle at all.

Follow system as the default, and if need be have a separate settings panel (even if it’s not actually implemented as a separate page but just an overlay) and put it there. It simply doesn’t warrant permanent screen real estate for the vast majority of users.

The eye-opening moment was when I sent my post to a colleague who is also an HCI PhD, to get their feedback on whether my reasoning was sound, or whether I had any blind spots. For background, this was someone who was much less immersed in the technical weeds of the Web — their work centers more around humans than around deep technical details.

I expected either agreement or constructive criticism, but what I got was much more eye-opening: It turned out that they had no idea what control the article was talking about! Folks, …they had never seen a dark mode toggle!5

And then it dawned on me: all these persistent dark mode toggles I had seen, literally all of them have been on developer-facing sites!

I could not think of a single well-known consumer-facing site with a persistent dark mode toggle. All consumer-facing websites that supported this functionality displayed it in a separate settings panel (which is a different use case). Even those which people spend hours a day using, like Gmail, Facebook, BlueSky, etc. None of them see this as a use case that deserves precious header real estate.

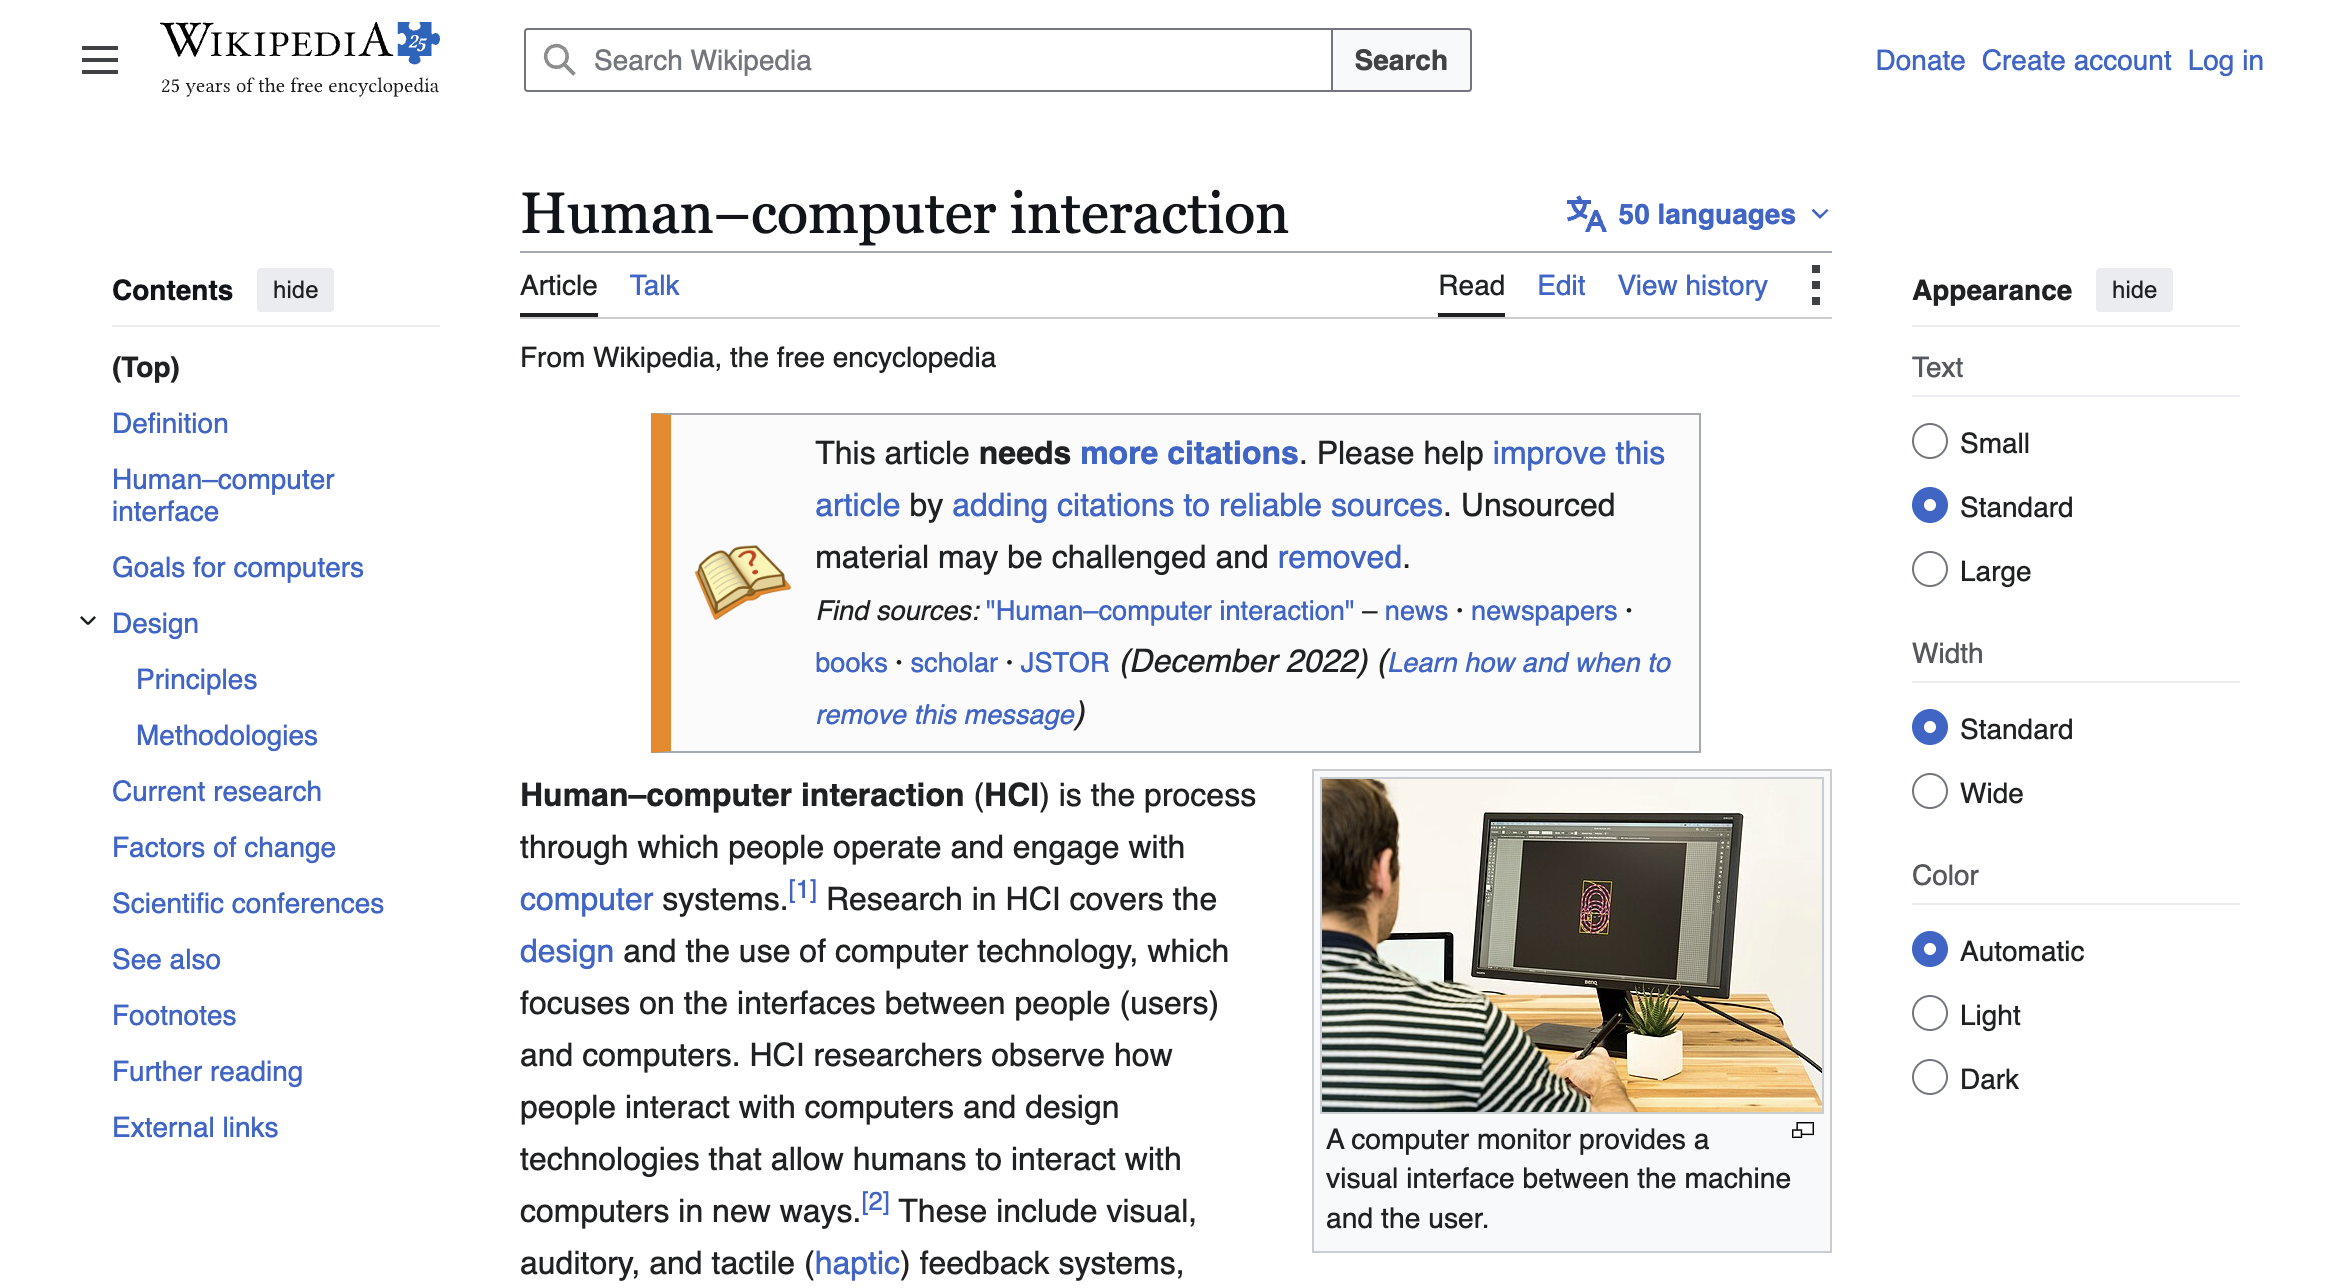
Wikipedia with the settings panel expanded

Wikipedia does show this sidebar by default on large enough viewports, but this is not an exception — just an auto-expanded settings panel.

Now, this alone is not evidence that dark mode toggles are a bad idea. A pattern can be widespread and still suffer from poor usability. And every UX innovation started off not being popular, so the reverse doesn’t hold either: a pattern can be unpopular and still be good. But in this case, I think they’re right. It suddenly all made sense to me: this doesn’t matter nearly as much to the average user as it does to us developers.

To be clear: “always light/dark, even against the OS” is a legitimate intent! But it is also a relatively rare one, and rare intents belong behind progressive disclosure — a settings surface — not in the one control every visitor sees.

In a textbook case of false-consensus bias, we have been so focused on our debugging needs that we convinced ourselves this is top of mind for the average user.

When is a persistent dark mode toggle a good idea?

A corollary from the reasoning above is that a dark mode toggle is a good idea when the website is developer-facing or developer-adjacent (e.g. a site for designers).

Experimental validation

Usability is a property of user outcomes, and no users were observed in any of this. Even my own article was derived from first principles and my experience observing users, but no actual observations of users interacting with dark mode toggles were made.

Per the previous section, I’m not convinced this is a problem worth solving. That said, if we do want to solve it, the best answer is obviously to get data from real user interactions.

However, there is a caveat here: qualitative user testing6 is less useful for infrequent microinteractions like this one.

Think about it: how would you design a meaningful qualitative experiment? At best, each participant would only interact with the toggle once. Most wouldn’t click it at all, unless the experiment was designed to show a website where the OS default theme is awful, which generalizes poorly.

Another easy bias in a controlled experiment is that it’s easy to bias the results by drawing attention to things that users would otherwise pay much less attention to. E.g. Vale wrote that the 3-in-2 switch was “intuitive and immediately understood by the great majority of people [they’ve] tested it with”. I strongly suspect these users were aware that something around dark mode toggles was being tested, and were paying a lot more attention to the control than they organically would.

I think the best way to get data for something like this is to record how users actually interact with the control, at scale, then analyze the data quantitatively. The experiment could involve different toggle designs as separate conditions.

Then, we could look at the data to answer questions like:

  • How frequently do people interact with the control meaningfully (i.e. ending up with a different selection)? (to see if it’s worth permanent screen real estate)
  • On a tri-state control, how frequently do users actually select the option that matches system but isn’t system? (to see if you actually need three states)
  • For mouse users, how much time passes between hovering the control and making a final selection for each condition and how many clicks does it involve? (as a proxy for cognitive load)
  • etc

By select above, I’m not referring to clicking, but the actual, final selection, to avoid noise from people playing with the control just to see what it does.

The big picture: Question the problem first

It is easy to get deep into a rabbit hole of trying our hardest to solve a problem that shouldn’t exist in the first place.

Especially for those of us with an engineering background, problem-solving comes naturally and it’s very hard to resist a challenging problem.

I’ve seen this happen repeatedly in many types of technical debates. It’s very common in standards groups as well: someone proposes a feature and the group starts debating the details before deciding whether the feature should exist at all.

Before any significant problem-solving task, it’s always good practice to step back and ask ourselves “is this a real problem worth solving?”.

You’d be surprised how often the answer is no.


  1. during a CSS WG meeting where I was presenting several topics no less! ↩︎

  2. It’s right up there with “simplicity”. I have seen developers happily shovel complexity downstream to users using “simplicity” as the justification. ↩︎

  3. I’m not talking about you Bob! ↩︎

  4. Most parents hugely overestimate how many people are interested in kidnapping their kids. In reality they struggle to even find someone to look after them for an evening, let alone take them forever 😅 ↩︎

  5. or — perhaps more likely — never paid attention to one ↩︎

  6. The kind where you get a few users and observe them using the UI to accomplish a task — i.e. what most people refer to as just “user testing” ↩︎

  •  

Dark mode toggles: two states are enough

A good two-state toggle can actually express all three data model states.

Until recently, if you looked at most websites with a theme toggle1, you’d find three options: Light, Dark, and System.

Tailwind Red Hat Design System Ant Web Awesome Excalidraw Taiga Astro Hero UI

Examples of tri-state dark mode toggles. In (LTR) reading direction: Tailwind, Red Hat Design System, Ant Design, Web Awesome, Excalidraw, Taiga, Astro, Hero UI.

Thankfully, these days the trend has shifted towards a simpler two-state toggle, but tri-state ones are still incredibly common.

Vitepress Material Spectrum Radix Shadcn

Examples of two-state dark mode toggles. In (LTR) reading direction: Vitepress, Material Design, Adobe Spectrum, Radix, ShadCN.

The rationale sounds plausible: “System” is a different intent than “Light” or “Dark”! One is a policy (whatever my OS says, do that) The other is a value (dark, forever, I don’t care what my OS says.) Surely, users should be able to express that intent!

Except, real users don’t generally seek out dark mode toggles to express intent for things to stay as they are, they seek them out when things need to change.

Think of the user goal when browsing a website (as opposed to a separate Settings page, where three states are fine). E.g. on a documentation site, they may be there to look something up. On a landing page, they may be trying to evaluate whether the product is suitable for their needs.
On a media site, they may be there to read the news.
On a graphics app, they want to draw something.

One thing is for certain: tweaking the theme is not their primary goal 2. To get in the mindset of tweaking the theme, something needs to be off. When things look right, users just move on with their actual goal instead of thinking about the theme.

The tri-state control is solving a largely imaginary user goal that is extremely rare among real users, and does not justify the additional complication and UX friction of a three-state toggle.

Worse, it forces the user to decide between choices that produce no visible difference, breaking the principle of feedback.

Yes, tri-state toggles are common. That doesn’t make them good. This essay explains why, and how to do better.

This article is about how to implement a good dark mode toggle, if you have already decided you need one. It does not prescribe whether one is necessary at all. If you decide to simply default to the system preference and not offer a toggle, I think that is a perfectly valid choice. And yes, I agree that eventually browsers should provide this as part of their chrome, instead of every website having to implement it themselves, but we’re not there yet.

Tri-state toggles are implementation-driven UI

One of the most common UX mistakes is designing UI around the underlying data model instead of user goals. Good interfaces abstract away the underlying model and expose a model that aligns with user goals (unless of course these happen to coincide, which is rare).

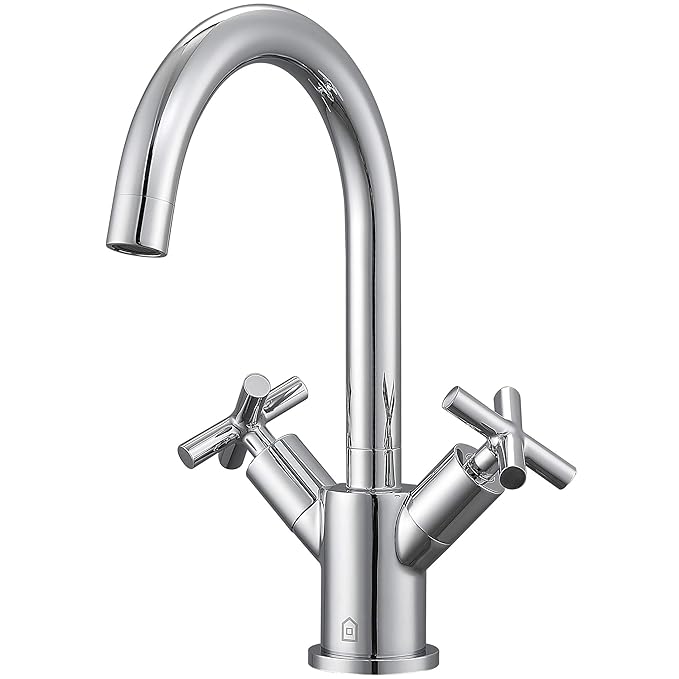
The user goal here is to set a specific flow and temperature. The underlying model works with amounts of hot and cold water. Guess which faucet is easier to use?

This is exactly the case with tri-state dark mode toggles; exposing all three states is data model leaking into the UI.

Yes, there should absolutely be three states in the underlying implementation! But at any given point, one of them is irrelevant to the end-user.

Users cannot meaningfully express intent about problems they don’t currently have.

A dark mode toggle is a temporary comfort adjustment. When it comes to user goals, there are only two real states:

  1. The website looks ok. The user moves on with their actual goal and doesn’t look for the toggle at all.
  2. The website is too bright or too dark to be comfortable. The user wants to fix it.

You’re reading in bed, the page is a flashbang, you hit the toggle. You’re on a laptop outside and the dark theme is unreadable in sunlight, you hit the toggle. It’s situational, it’s immediate, and it’s usually about the environment you’re in rather than a considered long-term stance on color schemes.

A third state assumes a usage scenario where a user visits a website that looks perfectly fine, and still looks for a dark mode toggle to ensure it can continue to look fine in the future. Users do all sorts of weird things, so I won’t assert that this never happens, but it is not a natural user interaction, fueled by a real user goal. Even the strongest proponents of tri-state toggles I have spoken with either admit they have never done this, or bring up some extremely rare, weird one-off edge cases.

But what’s the harm?

One could argue that sure, the third state is not frequently needed, but surely it doesn’t hurt to have it there for the one user that will need it, right?

But a more complex UI has a cost. It increases cognitive load for interacting with the control and forces you towards certain UI design decisions.

A two-state toggle can be very compact: Just a single icon that switches to another when clicked.

Some websites do go that route with a tri-state toggle that cycles through three states. Docusaurus for example:

Docusaurus header

But generally, the ergonomics of that are poorer than for the two state toggle, so it is no surprise it’s rare (Docusaurus was the only example I could find).

Some tri-state controls go for three icons side by side, which triples the screen real estate used.

RetHat Design System Hero UI Excalidraw Tailwind

Red Hat, Hero UI, Excalidraw, and Tailwind display three icons side by side.

Others, in an attempt to balance clarity and real estate, resort to a dropdown:

Ant Web Awesome Taiga Astro

Ant Design, Web Awesome, and Taiga UI go this route. Points for Web Awesome being the only one (!) to actually display what the system default resolves to.

That improves learnability, at the cost of efficiency, as it turns a single click interaction into a two-step process.

The actual perceived friction is actually worse than one extra click. Perceived friction is not a pure function of user actions, but also of the mental effort required to make a decision, and larger UI shifts (e.g. opening a dropdown) are more cognitively expensive than smaller ones (e.g. clicking a toggle) as the user needs to perceive and interpret a larger area.

If not three states, then what?

Guidance towards using tri-state controls is well meaning, but often based on paring good tri-state controls against poor two-state ones. E.g. in this article by Bramus:

Above that many implementations I have seen don’t take the “System” value into account. By omitting this option, the sites will never be able to respond to the system preference again, as they always have an override applied.

Indeed, a bad two state toggle is worse than a tri-state one. It makes the system mode unreachable once tweaked, making the selection irreversible and violating the usability principle of user control and freedom. A good two-state should be able to express all three states.

The idea is that the underlying model is still three states, but only two are shown at any given time:

Option Shown as Stored value
System default Current resolved value (e.g. sun or moon) None
Override Opposite of current resolved value (e.g. moon or sun) light or dark

When you press it for the first time, it toggles to the opposite of what you’re currently seeing, and stores the literal value (light or dark). The next time you press it, it toggles back to the system default, and removes the stored value.

That last bit is the one many two-state toggles get wrong. Storing a value that happens to match the system preference silently converts a temporary adjustment into a permanent pin with no way out.

Another common mistake is being overzealous about removing the stored value when the system preference changes, even if the user has explicitly set an override.

This evaluation must only happen at user interaction.

This is important because many users have their OS set to automatically switch between light and dark mode based on time of day, and removing the stored value proactively would make it impossible for them to actually pin a theme.

If a stored override later happens to coincide with the system preference — because the OS changed, not because the user did anything — you keep it.

This looks like an oversight — they’re the same now, why not tidy up? Because tidying up silently downgrades an explicit choice into a default, based on an event the user didn’t cause and can’t see.

Interactive demonstration

Here’s a concrete scenario that you can navigate interactively (view on separate page):

  1. Your OS is in light mode and the site has stored nothing, so the page follows along. Flip the OS control to run this the other way round.
  2. You toggle. The target is dark, which is not what the OS says, so the site stores an override. The page goes dark.
  3. Your OS switches to dark. The override now matches it but is still kept. Nothing visibly happens, which is correct.
  4. Your OS switches back to light. The page stays dark, because the override is still active.
  5. You toggle. The target is light, which is what the OS says, so the override is removed. The page follows the OS again.
  6. Your turn. Both controls are live and nothing from here on is scripted. Drive them in any order and watch what does — and does not — end up in localStorage.

But what if users get confused?

An argument I heard when discussing this was “but if the user selects light when their OS is light, then the OS switches to dark, won’t they get confused that the website did not preserve their choice?”

People hypothesizing that other people, who are not them, will get “confused” is a bit of a pet peeve of mine in usability discussions, but let’s entertain it for a moment.

Here’s that exact scenario:

  1. Your OS is in light mode and nothing is stored.
  2. You toggle to dark, which is stored as an override.
  3. You toggle again, meaning to pin light. It matches the OS, so the override is removed — you actually got the system default.
  4. Your OS switches to dark and the page follows. Not what you meant!
  5. But the fix is a single click: light no longer matches the OS, so this time it is an override, and thus pinned, so this can only happen at most once.

Remember, this control is entirely tangential to the actual user goal for visiting the website. Even if their intent were to pin light instead of reverting to System (light), this is something they would only notice once these diverge, i.e. the OS switches to dark. At that point, fixing it is a single click away. It’s such an easy fix, that there is no point in dwelling on it further.

It’s not that this never comes up, but making the tradeoff in favor of a tri-state control isn’t justifiable, IMO. A tri-state control introduces permanent UI complexity to prevent a one-time, easily fixable problem.

Additionally, color appearance is not just a pure function of color components, but also affected by surroundings and other factors. Even if a website implements only two modes, light mode may look slightly different in a light OS vs a dark OS, so selecting it as an override makes it an informed decision.

The title and icon could make the state clearer (e.g. the tooltip saying “Switch back to light (system default)” instead of “Switch to light” or the icon having a small screen icon instead of just a sun or moon). But those would need user testing to validate that they are an actual improvement. My concern is that once you distinguish System (light) from light, it (ironically) could become the thing that primes users to seek a third state that they previously had not considered.

Even if there is an ingenious UI that exposes three states at the same time without adding any cognitive load or friction (I have some ideas about what that might look like), I’m unconvinced this is a problem worth solving, and feels a lot like the UX version of premature optimization.

When is a tri-state control appropriate?

Although I spent the whole article arguing against tri-state toggles, there are actually valid use cases for them.

These are the two cases I’m aware of, but feel free to recommend more in the comments!

1. Color scheme setting that lives a separate settings panel

This article is primarily geared towards a permanently visible toggle in the header or footer.

A setting that lives alongside other settings in a settings panel is a fundamentally different usage scenario:

  • The user is already in the mode of making decisions about their future
  • The expectation is not that every setting must produce immediate feedback
  • There is a lot more screen real estate to explain three states.

It is no accident that while 2-state toggles are becoming the norm for persistent controls, tri-state is (rightly) king for settings panels.

Bluesky settings panel

Bluesky’s Appearance settings panel. The tri-state is fine here. Showing the “Dark mode” option below even when it produces no effect, on the other hand…

Google Calendar settings panel

Google Calendar. Love the icons, it would be nice to actually indicate what System currently resolves to.

Twitter/X settings panel

I’m not one to praise post-X Twitter, but having two two-state toggles instead of one tri-state is a very interesting design choice. The UX is not quite there, but if done well, I think it could be the best of both worlds when you have the screen real estate.

2. When color schemes are implemented differently depending on the system setting

This entire essay assumes the common case where a website only has two color schemes: light and dark, and there is no difference between light mode in a dark OS vs light mode in a light OS. Vadim Makeev had an interesting idea: color schemes should take the underlying OS setting into account. Light mode should be less bright in a dark OS and dark mode should be less dark in a light OS, to reduce the contrast between the website and the rest of the system.

I have not seen many UIs doing this, and CSS does not make it easier (light-dark() is very much designed around duality), but if you are actually doing this, you have earned your three states my friend, display them as prominently as you like, none of this applies to you!

Edit: I reached out to Vadim to ask if he had seen any UIs following his guidance. Here’s what he had to say:

Unfortunately, I haven’t seen any websites using this idea. I would say we’re pretty limited with tools currently to do so. The moment we want to override prefer-color-scheme, the whole light-dark() convenience is falling apart.

Yet another problem that CSS functions will solve (nothing preventing us from creating a 2-4 arg version of this).

The general version

The dark mode toggle is a nice case study, but the underlying lesson is bigger:

Users do not seek out solutions to problems they don’t currently have.

The tri-state toggle is the GUI version of low signal-to-noise APIs that ask you to pass dozens of parameters that could have sensible defaults, forcing you to decide on problems you have not encountered and are not relevant.

Do not flood users with options that are irrelevant to their current situation. Options that might become relevant in the future, should be surfaced in that future, not pre-emptively.

Not every state of your state machine warrants visible UI.

Ultimately, everything boils down to the very same principle:
Respect user effort.

Thanks to Chris Lilley and Jake Archibald for reviewing an earlier version of this draft

Addendum: The best dark mode toggle is probably …none

This article generated a lot of discussion on social media, but I have since concluded that actually, the best dark mode toggle is probably …none. Read the followup to see why!


  1. Unless otherwise noted, this refers to a permanently visible toggle in the header or (rarely) footer, not a theme setting in a separate settings panel. ↩︎

  2. This is about users. Yes, the developers of the site may have a goal of testing the theme, but we optimize UIs for being used, not getting debugged. ↩︎

  •  

In defense of polyfills

If you’re a web developer, you may find the title baffling. “Polyfills need defending? Who’s against them?!” you might ask.

Two weeks ago, I’d be in the same boat.

Polyfills and I go way back. I dug up a JSConf EU talk of mine from 2011 on exactly this topic.

YouTube still from that talk
Trying not to think about how young I look here 😅

One of the few opinions I have held strongly over the years is that polyfills are a net positive for the Web, and the good outweighs the rare failure cases where polyfills became too popular, too soon, and restricted the design space for the native API.

As with most things in life, it’s all about the cost-benefit. We don’t stop flying planes because crashes happen. We do a post-mortem and figure out how we can prevent the same accident from happening again. And crucially, the point of a post-mortem is to find the root cause — not to ground the entire fleet.

Don’t get me wrong, concerns about polyfills are well-intentioned. They come from implementors and standards folks who want to preserve the design flexibility to build the best API surface possible — a goal I share deeply. Being both a spec editor and a library author, striking that balance is something I navigate all the time.

Still, I was under the impression that seeing polyfills as a net positive was the consensus view of the web standards community as a whole. That while we may not have consensus on the specific tradeoffs or solutions, we see polyfilling as a good thing and we generally do want web platform features to be polyfillable.

So, you can imagine my surprise when in a recent WHATWG meeting where I presented a proposal for extending mutation observers to observe shadow root attachment, Anne van Kesteren expressed the view that polyfilling is harmful.

Say what now?!

It’s important to note that Anne is not some rando. He is the main active editor of most WHATWG specs (HTML, DOM, Fetch, import maps, etc.), a WebKit engineer at Apple, and has tremendous overall influence on the direction of the Web platform.

I had to find out if Anne’s comment reflected broader committee consensus, so I brought the topic up in the WHATWG Matrix and asked some folks privately.

Thankfully, it became clear that no, Anne’s comment did not reflect broader consensus (😮‍💨), but some of the views expressed about polyfills were more ambivalent than I’d have expected.

As I said, these concerns are well-intentioned — but I believe they are generally misplaced. Most fail to consider the system holistically, and especially the human factors that drive developer behavior.

Let me explain.

It’s not the polyfills

Authors want to use native behavior when it exists, without breakage when it doesn’t. That’s the crux of it. That’s what restricts design flexibility.

Scooby do mask reveal meme with the first panel reading “Polyfills” and the second (revealed) reading “Progressive Enhancement”

Whenever this happens too early, by too many people, you can have a problem. It doesn’t matter whether the code using it is a polyfill, a fallback, “progressive enhancement” or “graceful degradation”.

Fundamentally, every pattern that uses the native feature when it exists and a userland implementation (or even nothing) when it doesn’t risks breakage if the feature changes in a way that is incompatible with that usage.

This includes:

  • Using CSS properties for progressive enhancement, accepting that they won’t work everywhere
  • CSS fallbacks via the cascade or @supports
  • Conditional imports after feature detection
  • Using a modern HTML element, with a script that converts it to (or wraps it with) a web component if not supported
  • Build tools that include fallbacks alongside the native feature
  • JS let foo = nativeThing?.() ?? fallbackThing()
  • etc etc

In all of these cases, if the native API were to change in a way incompatible with the fallback usage, stuff could break.

Eliminating polyfills does not eliminate the need for them.

The benefit of polyfills over the techniques above is author-facing: polyfills are portable, maintainable, and typically more correct than ad-hoc fallbacks.

When a bug is identified in a polyfill, it can be fixed centrally. When a bug is identified in an ad-hoc fallback strategy, good luck finding all the callsites and fixing them.

Bottom line: eliminating polyfills does not eliminate the need for them and all other avenues of satisfying that need are measurably worse.

Polyfills decouple API design from implementation

Standardized APIs have intrinsic value, independently of browser implementations.

We think of polyfills as a toggle: use a polyfill, leave it in there, and later when all browsers implement the feature natively, it gets removed.

This misses out on one of the biggest benefits of polyfills: decoupling API design from implementation.

If a userland library isn’t working well, you must weigh the tradeoffs of refactoring your codebase to use a different library, and educating your team about the new library.

With a polyfill, the API itself is not within the purview of the polyfill. The polyfill supplies only implementation, while the API is externally decided by the standards. Thus, swapping a misbehaving polyfill for another has near-zero cost.

The benefits of API standardization are far greater when we consider the broader ecosystem. A dependency isn’t aware what your userland implementation may be for certain functionality. Either it needs to provide a way to pass it via configuration (expanding its API surface), or it needs to implement its own version of the functionality, which may be incompatible with that of the host.

Standardized APIs are the town square of the Web, uniting all consumers (developers, agents, tooling, etc) around a shared vocabulary.

For example, suppose we’re using:

  • a data binding framework that synchronizes JS data with form controls
  • a library that reads form control values and stores them in localStorage until the form is submitted
  • a custom command invoker for copying the value of an arbitrary form control to the clipboard

As long as these are implemented in an element-agnostic way, reading element.value 1 and listening to input and change events, they will work with any form control that implements the same API, whether it’s a native HTML element or a custom element, allowing for loose coupling.

But without this standardized API, we need to specify how every custom element expresses its data and what event(s) it uses to notify for changes to each and every one of these libraries. This is user effort on the magnitude of O(M × N) on the number of consumers and producers that must know about each other. Standardized APIs collapse it to O(1).

Are separate namespaces the solution?

From the same WHATWG discussion:

Anne: I would much rather people write a library that demonstrates the need for something as opposed to something that attempts to mimic the exact API shape of a proposal while simultaneously trampling all over our design flexibility.

Anne: You want to enable people using the amount element? Fine, but call it [something]-amount.

Stephen: I see “library that implements some feature” and “polyfill” as synonymous, but I can also see that fails to capture everything.

Anne: When I hear polyfill I think specifically of things that attempt to occupy the exact same API space and tend to cause issues, such as we had recently with Scoped Custom Element Registries. We ended up with a much worse standardized API because of that.

The topic of polyfilling often comes up in discussions about CSS and HTML polyfilling, which are currently much harder to polyfill than JS features.

Many people are of the opinion that the solution is to have a separate namespace for polyfills, so they cannot conflict with native implementations. For example, instead of polyfilling <amount>, you’d create a web component that polyfills <polyfill-amount>. Instead of polyfilling the CSS property border-shape, you’d write a polyfill that makes --border-shape work the same way.

At first glance, this seems ideal: the benefits of polyfilling without the risk of syntax lock-in! But we’ve tried it before.

Who remembers vendor prefixes?

Their core premise was exactly the same: if we experiment in a separate namespace, the native implementation can change without breaking any existing deployed experiments!

But remember, humans want to use the native feature when it’s there. And they don’t want to go back and edit their code when that happens. So what do they do? They use both! Even if the native feature has no implementations yet, pre-emptively.

We know exactly how this plays out, because it already has: stylesheets everywhere declared -webkit-border-radius with an unprefixed border-radius right below it — before any browser shipped the unprefixed property, and before its syntax was final.

So authors get worse DX, and web standards get no more design flexibility. Everybody loses.

Is dropping feature detection the solution?

As another attempt to mitigate the issues, some have started recommending polyfills that skip feature detection entirely and always use the fallback implementation, even when the native feature exists.

This is extremely wasteful. Polyfills add weight, are typically slower than native implementations, less accessible, less i18nclusive, and rarely handle edge cases. As their name implies, they are meant to temporarily cover a gap. They were never meant to be a long-term solution. The whole point is planned obsolescence: they eventually become dormant, even in a codebase that is no longer actively maintained. Feature detection and conditional loading are essential for that to work.

Authors accept these costs because they are temporary: every browser update quietly moves more of their users onto the native implementation, until the polyfill fades into a no-op. Remove feature detection, and the costs become permanent. Every user pays the download forever, and no user ever gets the native implementation’s performance, accessibility, or i18n — even when it’s sitting right there in their browser.

This approach does preserve the advantages of a standardized API, but at what cost? It trades away real, tangible benefits, felt by every user of the Web, to prevent a rare, largely theoretical risk. Every economist would be pulling their hair out at this cost-benefit!

Are ponyfills the solution?

Ponyfills, as originally envisioned by Sindre Sorhus, are basically userland libraries that closely track the native API, but do not modify the global environment and may intentionally diverge from the spec.

They are often suggested as a better alternative to polyfills.

For example, a polyfill for RegExp.escape() might look like this:

if (!RegExp.escape) {
	RegExp.escape = function (s) {
		return s.replace(/[.*+?^${}()|[\]\\]/g, '\\$&');
	};
}

Whereas a ponyfill might be:

export function regexpEscape(value) {
	return value.replace(/[.*+?^${}()|[\]\\]/g, '\\$&');
}

Note that this does not use the native implementation at all. It is not meant to be removed later. Its link to the native API is purely psychological.

I can see ponyfills being helpful for iterating on and getting feedback on an API while the standard is still being developed, or even to motivate a new proposal. But then again, so are userland libraries.

But for a mature feature, that has shipped in at least one browser, their appeal is much weaker.

They lack all strengths of polyfills:

  • They don’t use the native implementation, even when it exists.
  • They cannot be removed without refactoring
  • Without a standardized API, a ponyfill cannot be swapped for another without further refactoring.
  • They introduce a new userland dependency that needs to be evaluated, learned, documented, and maintained, just the same as if no standard existed at all.

IMO ponyfills are just userland libraries with better marketing.

Even their only advantage, not modifying the global environment and thus not trampling on the spec, is typically negated by actual usage: as a sort of …deconstructed polyfill.

See this post where the author is using a ponyfill for Number.MAX_SAFE_INTEGER as part of a makeshift polyfill:

const MAX_SAFE_INTEGER = Number.MAX_SAFE_INTEGER || require('number-max-safe-integer');

This is the norm, not some lone author failing to grok the concept of ponyfills. In fact, many people would call something like this a ponyfill as well:

export function regexpEscape(value) {
	if (RegExp.escape) {
		return RegExp.escape(value);
	}

	return value.replace(/[.*+?^${}()|[\]\\]/g, '\\$&');
}

This combines the disadvantages of both approaches, while getting you the benefits of neither!

In the end, the usage hasn’t changed, because the human need hasn’t changed.

Do polyfills discourage native implementations?

Stephen: […] polyfills can reduce the need for all browsers to implement something in a timely fashion.

Do they?

Yes, the existence of high-quality, lightweight polyfills can reduce the urgency for browsers to be the last to implement. But even then, the pressure never drops to zero: polyfills are slower and heavier than native implementations, and it’s the lagging browser’s own users who feel the difference. Without polyfills, authors wouldn’t use the feature at all — every browser would be equally fast at not supporting it, and the laggard could drag its feet indefinitely, consequence-free.

More importantly though, being last is not what’s critical for the Web’s evolution.

Check out my specs page. What is the average time from spec to first implementation, from that to the next, and from that to the last?

Milestone Proposals Mean time Median time
Spec → first implementation 10 1y 7m 6m 12d
First → second implementation 11 4m 26d 2m 24d
Second → last implementation 9 6m 6d 4m 3d

The first implementation is the hardest.

A Web platform without polyfills would be a stagnant platform.

What is the motivation for a browser to be the first to implement if authors cannot use the feature until all others implement it as well? Would you sink millions of dollars of engineering time into something your competitors can render moot, by means of simply …doing nothing?

We cannot A/B test reality, so this is purely a thought experiment, but I think if polyfills, fallbacks, and progressive enhancement suddenly disappeared, it would slightly increase motivation for those shipping last, but would significantly reduce motivation for shipping first. And since nobody can be last without someone else being first, a Web platform without polyfills would be a stagnant platform.

Additionally, often the biggest blocker in getting browsers to implement new features is demonstrating developer demand. A popular polyfill does that beautifully.

In fact, there is already plenty of precedent that if a feature cannot be used conditionally, browsers are reluctant to implement it. For example, decorators consistently top the list of missing JS features, but because JS syntax cannot be reasonably polyfilled, they are nontrivial to implement, and they are so widely used via transpilers, no browser has shipped them. “Let them use build tools” seems to be the general unspoken consensus.

Polyfills only get in the way when the standards process fails

I did some digging; Anne’s view traces back to a 2025 whatwg/html discussion where an API around scoped custom element registries had to be renamed due to conflicts with two existing polyfills that implemented a different behavior (emphasis mine):

We have prototyped a solution that seems to work and preserves the API pretty much as-is (still unfortunate though; please stop polyfilling and deploying polyfills)

To be fair, the underlying concern is real, so let me steelman it. Once a library squatting a proposed API name becomes popular enough, its exact behavior — bugs and all — becomes a web compat constraint. Standards groups then face a choice between adopting the library’s semantics or breaking deployed sites, and sometimes the only way out is renaming or redesigning the native feature, which is what happened here. That is a real cost, borne by the very people designing the platform.

But let’s be clear: none of the libraries that caused this problem was actually a polyfill, since there was no standardized API to polyfill.

At worst, they were naughty userland libraries, much like MooTools’ Array.prototype.flatten() that caused the smooshgate fiasco. At best, they were speculative polyfills (aka prollyfills) — an imagined API occupying the same namespace as a future builtin so authors can experiment with an emerging standard. Prollyfills are (rightly) more controversial, and not what this post is about.

Assigning blame to polyfills is like blaming car accidents on the ambulances that show up on the scene.

But when you examine the failure cases more closely, they all have something in common: In every single one, standards groups and/or browsers failed to react to a strong user need in a timely fashion.

Assigning blame to polyfills is like blaming car accidents on the ambulances that show up on the scene. A popular polyfill is a consequence. Polyfills should never become too popular in the first place: the feature should be widely implemented by then!

If a polyfill (or prollyfill) becomes so popular that it can create a compat problem, that is a symptom that a pervasive user need went unmet for too long. Whether it’s a polyfill or a prollyfill only changes which entity failed to react in time.

And even in the failure cases, consider the counterfactual. When a prollyfill constrains the design space, the damage is a worse name or a compromised API shape — bounded, and known before shipping. When an API ships without real-world validation, the damage is unbounded, and only discovered once the design is frozen into the platform by web compat. Remember AppCache? It shipped natively with no userland trial run, turned out to be fundamentally wrong, and took a decade to deprecate and replace with Service Workers. A prollyfill that surfaces design problems while the spec can still change is far cheaper than deploying the wrong API.

Developers don’t use polyfills in vain. Every dependency has a cost. If we see a polyfill becoming wildly popular, that should be a signal for urgent prioritization, not a reason to complain that authors are naughty.

Instead of blaming the user (“please stop polyfilling and deploying polyfills”), we should be doing a post-mortem on how to avoid such process failures in the future.

“If one user gets it wrong, it might be them. If two users get it wrong, it’s definitely you” — Ancient UX proverb2

When web platform design follows the priority of constituencies, and prioritizes end-user and author needs above implementors and standards authors, the failure cases are practically nonexistent, even when polyfills jump the gun and ship too early.

The WHATWG process invites these failures

Why did scoped registries take so long to ship? The web components community had been asking for years!

Part of this is that the WHATWG process is designed to be reactive rather than proactive. Even if there is a strong, demonstrated author need, WHATWG will refuse to flesh out a feature until at least two implementors express interest in implementing it. “needs implementer interest” is where so many good ideas go to die.

This made sense when WHATWG was founded as a reaction to the increasingly academic W3C HTML Working Group, which had been designing XHTML 2 in a vacuum, speccing features that no browser was willing to implement.

But having spent 15 years in the CSS WG and having proposed and/or helped drive several features to Baseline, I cannot imagine gating spec development on implementor interest. That’s putting the cart before the horse!

Demonstrating developer need is exactly what drives implementor interest in the first place! And that’s much easier to do with a feature that is actively being worked on.

For one, researching use cases and prior art to flesh out the feature often demonstrates author need in itself. But also, users have a lot of trouble expressing abstract pain points. It is much easier to point to an existing feature and say “I want browsers to support this” than to express a need for which no feature exists.

In a way, polyfills are to the web platform what user testing is to product design — and the prototype part isn’t even an analogy: a polyfill literally is a prototype of the feature. Real user feedback, without baking technical debt into the platform. One could even argue that browsers should be funding — or outright developing — these polyfills, precisely so they can gather this feedback before an API is frozen into the platform by web compat. Yes, there is some risk they may constrain the ergonomics of the eventual API — but if high-demand features actually ship at a reasonable pace, that risk shrinks dramatically.

Polyfills restore power balance in the ecosystem

Who remembers IE7.js? Or html5shiv?

For nearly a decade, IE was the boat anchor of the Web: dominant market share, no meaningful competition, and no incentive to implement anything new. Without polyfills, the rational strategy for many authors was to target IE and call it a day — and the rational strategy for every other browser would have been to stop investing in features nobody could use.

Instead, polyfills allowed authors to adopt modern standards years before IE supported them. That kept demand for standards alive, sustained pressure on IE, and gave end-users reasons to switch browsers. The fact that we were finally able to move away from IE6 and IE7 is in large part thanks to polyfills.

A browser lagging behind is not always a matter of will, either — release cadence matters. IE, and EdgeHTML after it, was bound to the Windows release schedule, just as Safari is tied to the macOS and iOS release trains today — a constraint the engineers working on these engines have no say in. A slow release train stretches exactly the gap that polyfills exist to cover: even once a feature ships, it reaches users in OS-update time, not browser-update time. If every engine could ship at the cadence of Chromium and Firefox, the need for polyfills would shrink significantly. Until then, polyfills are how authors deliver the benefits of native APIs — performance, accessibility, i18n — without being held hostage to the slowest release train.

Without polyfills, a single browser has undue power to hold back the Web.

Without polyfills, fallbacks, and progressive enhancement, a single browser has undue power to hold back the Web — whether by choice or by circumstance. I’m far more concerned about that than about the occasional smooshgate.

Polyfills make the Web faster, inclusive, and more robust

Native features are typically more performant, more accessible, more i18nclusive, and handle more edge cases than any userland implementation.

A userland library can cut corners, exclude locales, declare that a11y is out of scope, and fail to consider edge cases. A web standard cannot.

A polyfill inherits some of these limitations while it’s active, but unlike a userland library, it is graded against a spec: its target behavior has already been through accessibility and i18n review, so its gaps are well-defined, visible, and centrally fixable. A userland library gets to define its own bar.

Developers being able to use web features before wide availability is a win for the Web as a whole.

Can we stop trying to solve the wrong problem?

Cost-benefit analysis is a fundamental part of human decision-making.
We get in cars, even though there is a risk of accidents.
We go outside, even though we may catch a cold — or worse.
We swim, even though there is a small risk of drowning.

We weigh the extent of the risk, the probability of it happening, and the cost of mitigating it, against the extent and frequency of the benefits, and decide accordingly. We do this all the time, whether consciously or not.

When it comes to the Web, the benefits of polyfills are tangible and felt by everyone who develops for it. Historically, failure cases have been few, and generally have been mitigated well. Even smooshgate resulted in array.flat(), which to me is not obviously worse than array.flatten().

We are spending so much collective energy trying to mitigate a largely theoretical problem, that has only been a significant issue a handful of times in the 30+ years of the Web’s history. And yet, many are willing to sacrifice significant, tangible, far-reaching benefits to do so. This is an emotional reaction to a few high-profile incidents, not a rational cost-benefit tradeoff.

Instead of trying to eliminate polyfills, we should be more proactive in discovering and reacting to developer needs, so polyfills never become so popular that they threaten the design space of a native API.

Starting from polyfilling itself. 3

Huge thanks to Greg Whitworth and Cassondra Roberts for reviewing an earlier draft of this post.


  1. Special-casing known offenders like radios and checkboxes of course. ↩︎

  2. No, not really, I made this up, but the takeaway is pretty established in HCI. ↩︎

  3. Stay tuned: in Part 2 I’ll discuss what gaps in the Web platform make it hard to write good polyfills today, and how this varies across HTML, CSS, and JS. ↩︎

  •  

External import maps, today!

A few weeks ago, I posted Web dependencies are broken. Can we fix them?. Today’s post is a little less gloomy: Turns out that the major limitation that would allow centralized set-it-and-forget-it import map management can be lifted today, with excellent browser support!

The core idea is that you can use DOM methods to inject an import map dynamically, by literally creating an <script type="importmap"> element in a classic (blocking) script and appending it after the injector script. 💡

This is a gamechanger. It makes external import maps nice-to-have sugar instead of the only way to have centralized import map management decoupled from HTML generation.

All we need to do is build a little injector script, no need for tightly coupled workflows that take over everything. Once you have that, it takes a single line of HTML to include it anywhere. If you’re already using a templating system, great! You could add <script src="importmap.js"></script> to your <head> template for every page. But you don’t need a templating system: even if you’re rawdogging HTML (e.g. for a simple SPA), it’s no big deal to just include a <script src="importmap.js"></script> in there manually.

This is not even new: when the injector is a classic (non-module) script placed before any modules are fetched, it works in every import map implementation, all the way back to Chrome 89, Safari 16.4+, and Firefox 108+!

Turns out, JSPM made the same discovery: JSPM v4 uses the same technique. It is unclear why it took all of us so long to discover it but I’m glad we got there.

How does it work?

Basic import map injector script

First, while there is some progress around making import maps more resilient, your best bet for maximum compatibility is for the injector script to be a good ol’ blocking <script> that comes before everything else. This means no type="module", no async, no defer — you want to get it in before any modules start loading or many browsers will ignore it.

Then, you literally use DOM methods to create a <script type="importmap"> and append it after the script that is injecting the import map (which you can get via document.currentScript).

This is a minimal example:

(()=>{
	const map = {
		/* elided */
	};
	const script = Object.assign(document.createElement("script"), {
		type: "importmap",
		textContent: JSON.stringify(map)
	});
	document.currentScript.after(script);
})();

Fixing relative URLs

Remember, this literally injects inline import maps in your page. This means that any relative URLs will be interpreted relative to the current page!

If you’re building an SPA or your URLs are all absolute or root-relative, that’s no biggie. But if these are relative URLs, they will not work as expected across pages. You need to compute the absolute URL for each mapped URL and use that instead. This sounds complicated, but it only adds about 5 more lines of code:

(()=>{
	const map = {
		/* elided */
	};
	const mapUrl = document.currentScript.src;
	const rebase = m => { for (let k in m) m[k] = new URL(m[k], mapUrl).href; return m; };
	rebase(map.imports);
	for (let scope in (map.scopes ?? {})) {
		rebase(map.scopes[scope]);
	}
	const script = Object.assign(document.createElement("script"), {
		type: "importmap",
		textContent: JSON.stringify(map)
	});
	document.currentScript?.after(script);
})();

Error handling

Note that document.currentScript is null in module scripts, since the same module can be loaded from different places and different scripts. Once it becomes possible to inject import maps from a module script, you could use import.meta.url to get the URL of the current module. Until then, you can use a bit of error handling to catch mistakes:

(()=>{
	const map = {
		/* elided */
	};
	const mapUrl = document.currentScript?.src;
	if (!mapUrl) {
		throw new Error("Import map injector script must be a classic (non-module) script");
	}
	const rebase = m => { for (let k in m) m[k] = new URL(m[k], mapUrl).href; return m; };
	rebase(map.imports);
	for (let scope in (map.scopes ?? {})) {
		rebase(map.scopes[scope]);
	}
	const script = Object.assign(document.createElement("script"), {
		type: "importmap",
		textContent: JSON.stringify(map)
	});
	document.currentScript?.after(script);
})();

This is the minimum, since the script literally breaks if document.currentScript is null. You could get more elaborate and warn about async/defer attributes, or if type="module" scripts are present before the current script. These are left as an exercise for the reader.

Do we still need external import maps?

While this alleviates the immediate need for external import maps, the DX and footguns make it a bit gnarly, so having first-class external import map support would still be a welcome improvement. But even if we could do <script type="importmap" src="..."> today, the unfortunate coupling with HTML is still at the receiving end of all this, and creates certain limitations, such as specifiers not working in worker scripts.

My position remains that HTML being the only way to include import maps is a hack. I’m not saying this pejoratively. Hacks are often okay — even necessary! — in the short term. This particular hack allowed us to get import maps out the door and shipped quickly, without getting bogged down into architecture astronaut style discussions that can be non-terminating.

But it also created architectural debt. These types of issues can always be patched ad hoc, but that increases complexity, both for implementers and web developers. Ultimately, we need deeper integration of specifiers and import maps across the platform. <script type="importmap"> (with or without an src attribute) should become a shortcut, not the only way mappings can be specified.

In my earlier post, I outlined a few ideas that could help get us closer to that goal and make import maps ubiquitous and mindless. Since they were well received, I opened issues for them:

I’m linking to issues in standards repos in the interest of transparency. Please don’t spam them, even with supportive comments (that’s what reactions are for). Also keep in mind that the vast majority of import map improvements are meant for tooling authors and infrastructure providers — nobody expects regular web developers to author import maps by hand.

The hope is also that better platform-wide integration can pave the way for satisfying the (many!) requests to expand specifiers beyond JS imports. Currently, the platform has no good story for importing non-JS resources from a package, such as styles, images, icons, etc.

But even without any further improvement, simply the fact that injector scripts are possible opens up so many possibilities! The moment I found out about this I started working on making the tool I wished had existed to facilitate end-to-end dependency management without a build process (piggybacking on the excellent JSPM Generator for the heavy lifting), which I will announce in a separate post very soon 1. Stay tuned!


  1. But if you’re particularly curious and driven, you can find it even before then, both the repo and npm package are already public 😉🤫 ↩︎

  •  

Web dependencies are broken. Can we fix them?

A cartoon where JS is shown hanging out drinking with bundlers. Webpack is saying “just one more config!” and Vite and Rollup are saying “We can optimize this!”. The event looks like it's winding down after hours of depravity. On the right side, a group of fed up developers are holding up an “Intervention” banner.
No, this is not another rant about npm’s security issues.

Abstraction is the cornerstone of modern software engineering. Reusing logic and building higher-level solutions from lower-level building blocks is what makes all the technological wonders around us possible. Imagine if every time anyone wrote a calculator they also had to reinvent floating-point arithmetic and string encoding!

And yet, the web platform has outsourced this fundamental functionality to third-party tooling. As a result, code reuse has become a balancing of tradeoffs that should not have existed in the first place.

In NodeJS, you just npm install and reference specifiers straight away in your code. Same in Python, with pip install. Same in Rust with cargo add. In healthy ecosystems dependencies are normal, cheap, and first-class. You just install them using the one standard way, use them, and move on. You don’t have to ponder which third-party tool to use, or — worse — whether to use dependencies at all. “Dependency-free” is not a badge of honor.

Instead, dependency management in the web platform consists of bits and bobs of scattered primitives, with no coherent end-to-end solution. Naturally, bundlers such as Webpack, rollup, and esbuild have picked up the slack, with browserify being the one that started it all, in 2012.

Dependencies are too essential to be outsourced

On a very high-level, there are four things a bundler does for you:

  1. Performance optimizations: e.g., tree-shaking, prerendering, code splitting, minification, etc
  2. Transpilation / Templating, parsing one syntax and converting it to another. This includes templating, JSX, CSS preprocessing, TypeScript compilation, etc
  3. Dependency management. Making it possible to use libraries installed via package managers like npm or yarn
  4. Debugging improvements: Hot reloading, source maps, etc.

One of these is not like the others. Can you tell which one?

Performance, debugging improvements, and transpilation are generally advanced concerns. They are QoL improvements, but you can get quite far without them.1

But dependencies? Dependencies are essential! You don’t want to be writing your own drag and drop library, UI components, icons, charting library, and so on. In the vast majority of websites or libraries, the need for dependencies comes up in the first few lines of code.

Do you see the problem now? Requiring complex tools for complex needs is totally fine! But when you need complex tools for basic needs, that’s a smell that something is seriously broken in the ecosystem. Dependency management is such a basic and ubiquitous need, it should be a part of the platform, decoupled from bundling.

Bundling is not technically a necessary step of dependency management. Importing files through URLs is natively supported in every browser, via ESM imports. HTTP/2 makes importing multiple small files far more reasonable than it used to be — at least from a connection overhead perspective. Sure, a bundler will always win on first load, as it knows far more about your app than the browser ever could. But that is precisely the kind of optimization you should be able to layer on later, not the price of admission. You can totally get by without bundlers in a project that doesn’t use any libraries.

But the moment you add that first dependency, everything changes. You are suddenly faced with a huge usability cliff: which bundler to use, how to configure it, how to deploy with it, a mountain of decisions standing between you and your goal of using that one drag and drop library. A meta-framework does take the thought out of this, which is how we end up with websites using Next.js for a simple landing page.

Dependency management is one of the web platform’s usability cliffs: a small increase in use case complexity results in a large increase in system complexity.

How did we get here?

Many of us old farts often reminisce about the good old days: the simplicity of editing a file and seeing the result, no build step, no watcher, no configuration. But that carefully leaves out the numerous things that downright sucked, and dependency management was chief among them.

Remember when every dependency was basically a peer dependency, and you had to manually add <script> elements, not just for every dependency, but for their dependencies too? And get the order right? And good luck if two of them needed different versions of the same library — who remembers jQuery.noConflict()? I won’t even get into how versioning was done, to protect your sanity. You young’uns have no idea how good you have it.

Mastodon poll on reasons for using a bundler

Despite the name "bundler" hinting towards performance, dependency management outranks it as a motivating use case. Mastodon-only, as X/Twitter does not support multiple choice polls.

Bundlers gave us the DX of the NodeJS ecosystem: npm install and then you just import. The performance optimizations, debugging affordances, and transpilation were a nice cherry on top, but they are not what drove adoption.

Dependency management is also the hairiest of the four, because it has tentacles over everything. We had been transpiling and optimizing code with separate build scripts since the beginning of time, and that was never a problem: TS becomes JS and is then handled like regular JS. SCSS becomes CSS and is then handled like regular CSS. Nothing else in the codebase needs to know. But every part of the codebase needs to know how the repo manages dependencies. That is what drove monolithic bundlers to ubiquity: not performance, not transpilation, but the one basic need the platform never covered.

Don’t look at usage, look at sentiment

Asking developers whether they use a bundler is the wrong question. Of course they do. You can’t survive without it! Per State of JS 2024, Webpack alone has been used by 9 in 10 developers, with close to 100% awareness. Even CodePen had to add bundler support, because even small testcases and experiments are a pain without one.

Instead, try asking them how they feel. Despite the ubiquity of bundlers, “managing dependencies” was still No 3 in the State of JS pain points, right after “Code architecture” and “State management”!

Relevant: Dependency management is the 3rd JS pain point, and build tool issues 6th, above debugging even!

And sorting the State of JS build tool data by sentiment paints a very different picture than usage does, with satisfaction, interest, and positivity dropping year after year. Even those who never question the status quo can feel it in their gut that this is not okay.

So I asked point blank: do you use a bundler, and do you wish you didn’t?

Mastodon poll

Social media polls, run in March 2026. Yes, most developers use a bundler (88% on Twitter, 72% on Mastodon), but a pretty high percentage wishes they didn’t (a third of bundler users on X/Twitter and half on Mastodon).

A third to half is a pretty high amount of dissatisfaction! And when I had asked back in January, I was surprised to see how many had skipped bundlers altogether: 17.6% on Twitter/X and 40% (!) on Mastodon. Obviously, all of these suffer from selection bias, due to the snowball sampling nature of social media, but the pattern is consistent. I’m very curious how these folks manage the problems discussed below.

Anecdotally, from my conversations with developers, it seems the rest have simply resigned to the complexity in the same way one resigns to paying taxes, and just accept the status quo as the price to pay to deploy a website. Like boiling frogs, JS developers have resigned themselves to immense levels of complexity and gruntwork as simply how things are. The rise of AI introduced swaths of less technical folks to web development and their overwhelm and confusion is forcing us to take a long hard look at the current shape of the ecosystem — and it’s not pretty.

Dependencies without bundlers, today?

No-build today: here be dragons
The experience of going no-build today is fraught with hazards.

It is technically possible to use dependencies without bundlers, today. There are a few different approaches, and — I will not sugarcoat it — they all suck.

Fundamentally, there are two ways to reference a dependency: by URL or by specifier. URLs can be local (a path in your project) or remote (a CDN). Specifiers need something to map them to URLs, which today means import maps. There is currently no good answer for any of these, only fragile workarounds held together by duct tape.

Using a dependency should not need any additional song and dance besides “install this package” + “now import it here”. That’s it. That’s the minimum necessary to declare intent. And that’s precisely how it works in NodeJS and other JS runtimes. Anything beyond that is reducing signal-to-noise ratio, especially if it needs to be done separately for every project or worse, for every dependency.

You may need to have something to bite hard on while reading the next few sections. It’s going to be bad.

Path-based solutions

Typically, package managers like npm take care of deduplicating compatible package versions and may use a directory like node_modules to install packages. Some developers notice this and try rawdogging node_modules/ imports:

import { createApp } from "../node_modules/vue/dist/vue.esm-browser.js";

Eek. It works (in some cases), but deploying your entire node_modules directory is both wasteful, and a security risk. In fact, most serverless hosts (e.g. Netlify or Vercel) automatically remove it from the publicly deployed files after the build is finished, which means you need additional code to reinstate it or rewrite these imports.

Others have tried isolating the packages they actually need and copying them into a separate directory:

{
	"scripts": {
		"lib": "cp node_modules/vue/dist/vue.esm-browser.js common/lib/vue.js",
		"build": "npm run lib"
	}
}

It’s a little better than the former, but now you need to keep track of what packages each package imports and copy them too. Yikes!

But zooming out, both of these approaches are severely problematic, for two bigger reasons.

First, they break transitive dependencies. This may work fine when you’re vendoring packages with no dependencies of their own, but the moment you use a package that uses another package, it all collapses like the tower of cards it is. Even if you were willing to hunt down which of your packages use dependencies and vendor those too, how would the packages even reference them? They have no idea what your directory structure looks like. Unless, of course, you’re willing to rewrite the files you’re copying — but now you’re building your own bundler. Please don’t. And even if a package uses no dependencies today, that may change tomorrow, so instead of building whatever it is you’re building, you’re now monitoring your dependencies’ dependencies.

As someone who regularly releases open source packages (some with billions of npm installs), I find this incredibly frustrating. I want to write packages that can be consumed by people using whatever they want to manage their dependencies, but the only way to do that today is to basically not use any dependencies. I cannot even modularize my own packages without running into this! This doesn’t scale. The creator of htmx reached the same conclusion, and committed to not using dependencies so that their users can vendor htmx. This is an awful compromise that no library author should be forced into.

Specifiers are an essential abstraction

Second, any path-based solution breaks encapsulation. There is a reason why we reference packages using specifiers like vue or lit instead of URLs to the actual files.

Specifiers are an abstraction over URLs, but an essential one for dependency management. We don’t use specifiers instead of URLs because they look a little prettier. We use them because they decouple a dependency from:

  • the exact location of the package
  • the exact file path within the package (which often changes between versions)
  • the exact version, for the source referencing (different packages may import different versions of the same dependency using the same specifier)
  • the import conditions (e.g. browser, node, types, etc)

Worse, without specifiers, transitive dependencies have nothing reasonable to reference.

Specifiers should be non-negotiable. You should never have to track what the specifiers of your dependencies map to and update your code when they change. Seriously, if you find yourself doing that, take a long hard look in the mirror and ask yourself where things went wrong. Any dependency management system that forces you to write out paths manually should be a non-starter, period. The cost-benefit is just not there.

Importing from public CDNs

Another common path is importing from CDNs like Unpkg and JSDelivr. For Vue, it may look like this:

import { createApp } from "https://unpkg.com/vue@3";

It’s quick and easy. Nothing to install or configure! Some CDNs, like esm.sh, even rewrite specifiers on the fly, so transitive dependencies Just Work™, making this the only URL-based approach that actually scales. Great, right?

No. Not great.

It is always a bad idea to introduce a dependency on a whole other domain you do not control, and an even worse one when linking to executable code.

First, there is the obvious security risk. Unless you link to a specific version, down to the patch number and/or use SRI, the resource could turn malicious overnight under your nose if the package is compromised. And even if you link to a specific version, there is always the risk that the CDN itself could get compromised. Who remembers polyfill.io?

But supply-chain attacks aside, any third-party domain is an unnecessary additional point of failure. I still remember scrambling to change JSDelivr URLs to Unpkg during an outage right before one of my talks, or having to hunt down all my repos that used RawGit URLs when it sunset, including many libraries.

The DX is also suboptimal. You lose the immediacy and resilience of local paths. Without additional tooling (Requestly, hosts file edits, etc.), you now need to wait for CDN roundtrips even during local development. Wanted to code on a flight? Good luck. Needed to show a live demo during a talk, over clogged conference wifi? Maybe sacrifice a goat to the gods. 🐐

There is a subtler problem too. Specifiers don’t just abstract over locations, they also enforce consistency across the codebase: import "marked" means the same thing in every file of your project. With URLs, nothing stops foo.js from importing marked@18 while bar.js imports marked@17, and you end up shipping both, possibly even from different CDNs. Multiple versions of the same dependency can coexist, but that should be a deliberate choice, not accidental drift. And with AI defaulting to local edits, cross-codebase consistency is now more important than ever.

“But with public CDNs, I benefit from the resource having already been cached by another website the user visited!”
Oh my sweet summer child. I hate to be the one to break it to you, but no, you don’t, and that has been the case since about 2020. Double keyed caching obliterated this advantage.

Import maps to the rescue?

Browsers can import specifiers, as long as the mapping to a URL is explicitly provided through an import map. Import maps look like this:

<script type="importmap">
{
	"imports": {
		"vue": "./node_modules/vue/dist/vue.runtime.esm-bundler.js",
		"lodash": "./node_modules/lodash-es/lodash.js",
	}
}
</script>

Did you notice something? Yes, this is an HTML block. No, I cannot link to an import map that lives in a separate file. Instead, I have to include the darn thing in. Every. Single. Page.

“💡 Oh I know, I’ll inject it via DOM methods!” I hear you say. Yes, my sweet summer child, that actually works — as long as it’s done from a classic (non-module) script that runs before any module is fetched. It’s clunky, but it’s what lets us emulate external import maps today, and it’s what JSPM 4.0 does. So at least we can dodge the HTML templating tool. 🎉

“💡 And I’ll keep it short by routing everything through a CDN or the same local folder!” No, my sweet summer child. Go to sleep and dream of globs and URLPatterns. Then wake up and get to work, because you actually need to specify. Every. Single. Mapping. Yes, transitive dependencies too.

Yo dawg meme with the text “Yo Dawg, I heard you like dependencies, so I put the deps of your deps in your import maps” Ursula from The Little Mermaid singing “It’s sad, but true. If you want to use dependencies, my sweet you gotta pay the toll” to the tune of “Poor Unfortunate Souls”

You wanted to use dependencies? You will pay with your blood, sweat, and tears. Or, well, another build tool.

So now I need a build tool to manage the import map, like JSPM.

There are three invariants that import maps violate:

  1. Locality: Dependency declarations live in one global map owned by the final consumer. A library cannot even ship a fallback mapping, so it has no way to guarantee it works outside the consumer’s setup.
  2. Composability: Import maps do not compose across dependencies and require global coordination
  3. Scalability: Mapping every transitive dependency is not viable without tooling

Plus, you still have all of the issues discussed above, because you still need URLs to link to. Notably, JSPM’s primary flow is linking to node_modules/ on localhost and a CDN (they have their own too, that is optimized for this) in production. If you don’t want to use CDNs in production, you’re SOL.

To sum up, import maps are not the solution, but they are an essential part of it. They give us specifiers in the browser, which is huge, but on their own they don’t eliminate the need for tooling — they just make lighter tooling possible. And a lighter build tool is still an improvement!


Comic strip showing a conversation between two characters about the complexity of web development.
Panel 1:
A (excitedly): I want to use libraries! And frameworks! And components!
B: You need a bundler! Take your pick: webpack, rollup, vite, esbuild, parcel, there are so many!
Panel 2:
A (troubled): Um, I …don't want to use a bundler. It’s overkill for my project.
B: Well… you can import directly from CDNs. Take your pick: jspm.io, esm.sh, unpkg, jsdelivr, there are so many!
Panel 3:
A (troubled and pensive): Hmmmm… 🤔
B (oblivious): …you can even use nice specifiers like `vue` or `d3` instead of URLs, through import maps. You can use JSPM to manage those, it supports alll the CDNs!
Panel 4:
A (visibly uncomfortable and increasingly outraged): Uh, I …don’t want to depend on a CDN. Can’t I have dependencies that are _both_ local _and_ easy to manage? In Node I can just run `npm install` and everything just works without all this complexity. What’s the Web equivalent?
B: It’s a bundler! Take your pick: webpack, rollup, vite, esbuild, parcel, there are so many!
Panel 5 (dramatic climax, panel much wider than the previous panels (aspect ratio ogf about 2.5:1)):
A (head tilted back, mouth wide open, tears streaming, wails loudly): WHY IS THE WEB LIKE THIS??
B (still visible on the far right, small and passive, in the background, looking baffled): Why won't you just use a bundler like everyone else? Just don't look at the output and you'll be fine, really!
This has been me more times than I can count.

Are bundlers the lesser evil?

Given the current state of the ecosystem, not using bundlers in any nontrivial application does seem like an exercise in masochism. And yet, as we saw, a surprising share of developers do exactly that, and a much larger share wishes they could. This is not a reasonable way to manage dependencies. This is not a healthy ecosystem.

Oftentimes when discussing these issues, I get the question “but other languages are completely compiled, why is it a problem here?”. Yes, but their compiler is official and always there. You literally can’t use the language without it. You don’t get a broken experience, you get no experience.

The problem is not compilation, it’s fragmentation. It’s the newbie trying to use a drag and drop library, only to get mysterious errors about specifiers that failed to resolve. It’s having to add mountains of config and complexity to use a utility function. It’s having no clear path to write a package that uses another package, even if both are yours.

The problem is not compilation, it’s fragmentation.

Abstraction itself is not something to outsource to third-party tools. This is the programming equivalent of privatizing fundamental infrastructure — roads, law enforcement, healthcare — systems that work precisely because everyone can rely on them being there.

This is also actively harming web platform architecture. A general API design principle is to prioritize the needs of consumers over the needs of producers; the web platform even has its own version, the priority of constituencies. When it comes to bundlers, web developers are the consumers, so their needs should come first. But bundler ubiquity has reversed the natural order: now web developers cater to bundlers. Code that works perfectly fine in a browser has to be rewritten to work in bundlers. And because bundlers are so ubiquitous, we have ended up designing the platform around them, when it should be the opposite.

To reiterate, the problem isn’t that bundlers exist — it’s that they are the only viable way to get first-class dependency management on the web.

JS developers deserve better. The web platform deserves better.

Where do we go from here?

The web platform's specifier support feels like an arcade demo: you get to watch the first level, but there's no coin slot to play the actual game.

As a web standards person, my first thought when spotting such a lacking is “how can the web platform improve?”. And after four years in the TAG, I cannot shake the holistic architectural perspective of “which part of the Web stack is best suited for this?” The following is my take.

We need specifiers everywhere

It is clear that specifiers are an essential piece of the puzzle, for the reasons mentioned earlier. The web platform’s specifier support feels like an arcade demo: you get to watch the first level, but there’s no coin slot to play the actual game. While the web platform provides import maps to map specifiers to URLs, they only work for JS dependencies. But the Web is not just JS! What about CSS frameworks, icons, fonts, etc.?? There is no way to use specifiers for any other type of resource. You either rawdog URLs, or give up and use a bundler already.

Even for JS dependencies, specifiers don’t yet work in workers, but that’s a relatively simple fix, whatwg/html#10858 has just stalled due to lack of time.

Oh, and fun fact: they don’t even work in <script type=module src="foo">! That foo will be interpreted as a local URL, even if you’ve defined a corresponding specifier. Which brings me to my next point.

How could we retrofit specifiers into the web platform? We can’t just start accepting specifiers in places designed for URLs — <link rel=stylesheet href="foo"> or @import url('foo'); already have an established meaning: they are relative URLs to the file called foo. ESM avoided this by designing imports with specifier disambiguation from the get go.

The solutions are to either add one-off ESM-like specifier-first referencing syntax in every part of the platform that may want to import any resource from a dependency (CSS files, <script src>, CSS @import, CSS url(), SVG <use> etc etc), or to design a new URL scheme (specifier:?) to reference them everywhere (which is what I proposed a while ago). An advantage of that is also that it bridges the gap between specifiers and URLs. Rather than having two entirely separate primitives for linking to a resource, it makes specifiers a high-level primitive and URLs the low-level primitive that explains it.

Improving import maps

An area with huge room for improvement here is import maps. Both making it easier to generate and include import maps, and making the import maps themselves smaller, leaner, and easier to maintain.

Note that thanks to Shopify there have been some recent improvements making import maps a lot more resilient. Unfortunately, Firefox does not yet support them, which is proposed for Interop 2027.

External import maps

The most obvious gap is external import maps, even if it’s only via <script type=importmap src>. As we saw, they can be emulated via DOM injection from a regular JS file, which is what JSPM 4.0 does, but it’s needlessly complicated and error-prone. Native support would make linking an import map as boring as linking a stylesheet.

This was actually part of the original import map work, and was removed from the spec due to lack of implementer interest, despite overwhelming demand from developers. In 2022, external import maps were prototyped in WebKit (Safari), which prompted a new WHATWG issue. Unfortunately, it appears that progress has since stalled once more.

Import maps without HTML?

External import maps do alleviate some of the core pain points, but are still globally managed in HTML, which hinders composability and requires heavier tooling.

What if import maps could be imported into JS code? This would eliminate the dependency on HTML altogether, allowing for scripts to localize their own import info, and for the graph to be progressively composed instead of globally managed.

Originally, I was thinking of an import attribute (e.g. via import "map.json" with { type: "importmap" }), but perhaps the path of least resistance might be a JS API.

Import maps via HTTP header?

Going further, import maps via an HTTP header (e.g. Link) would even allow webhosts to generate them for you and send them down the wire completely transparently. This could be the final missing piece for making dependencies truly first-class.

Imagine a future where you just install packages and use specifiers without setting anything up, without compiling any files into other files, with the server transparently handling the mapping!

It may seem wild, but this is exactly how gzip or other compression mechanisms work: the server and the browser just sort it out between them, and the developer doesn’t have to care, or even know.

Deploying dependencies to URLs

However, import maps need URLs to map specifiers to, so we also need some way to deploy the relevant subset of node_modules to public-facing URLs, as deploying the entire node_modules directory is not a viable option.

clientDependencies in package.json?

One solution might be a way to explicitly mark dependencies as client side, possibly even specific exports. This would decouple detection from processing app files: in complex apps it can be managed via tooling, and in simple apps it could even be authored manually, since it would only include top-level dependencies.

Figuring out the dependency graph

Even if we had better ways to mark which dependencies are client-side and map specifiers to URLs, these are still pieces of the puzzle, not the entire puzzle. Without a way to figure out what depends on what, transitive dependencies will still need to be managed globally at the top level, defeating any hope of a tooling-light workflow.

The current system relies on reading and parsing thousands of package.json files to build the dependency graph. This is reasonable for a JS runtime where the cost of file reads is negligible, but not for a browser where HTTP roundtrips are costly. And even if it were, this does not account for any tree-shaking. I’m not sure what the solution might be here, except perhaps moving this to the server’s purview too, like compression.


But in the end, this is about the problem. I’m much more confident that there is a problem that needs solving here, than I am of any particular solution. Hopefully, after reading this, so are you.

So this is a call to action for the community. To browser vendors, to standards groups, to individual developers. Let’s fix this! 💪🏼

Thanks to Jordan Harband, Wes Todd, and Anne van Kesteren for reviewing earlier versions of this article.


  1. The only exception is perhaps HTML includes, which are already being prototyped in Chrome 🎉. ↩︎

  2. In fact, when I was in the TAG, Sangwhan Moon and I drafted a Finding on the topic, but the TAG never reached consensus on it. ↩︎

  •  

In the economy of user effort, be a bargain

Alan Kay

Alan Kay [source]

One of my favorite product design principles is Alan Kay’s “Simple things should be simple, complex things should be possible”. 1 I had been saying it almost verbatim long before I encountered Kay’s quote. Kay’s maxim is deceptively simple, but its implications run deep. It isn’t just a design ideal — it’s a call to continually balance friction, scope, and tradeoffs in service of the people using our products.

This philosophy played a big part in Prism’s success back in 2012, helping it become the web’s de facto syntax highlighter for years, with over 2 billion npm downloads. Simple things were easy: All it took to highlight code on a webpage was including two files, a JS file and a CSS file. No markup changes. No JS glue code. Styling used readable CSS class names. Even adding new languages — the most common “complex” use case — required far less knowledge and effort than alternatives. At the same time, highly complex things were possible: Prism exposed a deep extensibility model so plugin authors could patch internals and dramatically alter behavior. These choices were not free. The friendly styling API increased clash risk, and deep extensibility reduced encapsulation. These were conscious, hard, tradeoffs.

Since Alan Kay was a computer scientist, his quote is typically framed as a PL or API design principle, but that sells it short. It applies to a much, much broader class of interfaces.

This distinction hinges on the distribution of use cases. Products often cut scope by identifying the ~20% of use cases that drive ~80% of usage — aka the Pareto Principle. Some products, however, have such diverse use cases that Pareto doesn’t meaningfully apply to the product as a whole. There are common use cases and niche use cases, but no clean 20-80 split. The tail of niche use cases is so long, it becomes significant in aggregate. For lack of a better term, I’ll call these long‑tail UIs.

Nearly all creative tools are long-tail UIs. That’s why it works so well for programming languages and APIs — both are types of creative interfaces. But so are graphics editors, word processors, spreadsheets, and countless other interfaces that help humans create artifacts — even some you would never describe as creative.

Example: Google Calendar

You wouldn’t describe Google Calendar as a creative tool, but it is a tool that helps humans create artifacts (calendar events). It is also a long-tail product: there is a set of common, conceptually simple cases (one-off events at a specific time and date), and a long tail of complex use cases (recurring events, guests, multiple calendars, timezones, etc.).

Indeed, Kay’s maxim has clearly been used in its design. The simple case has been so optimized that you can literally add a one hour calendar event with a single click (using a placeholder title). A different duration can be set after that first click through dragging 2. But almost every edge case is also catered to — with additional user effort.

Google Calendar is squarely a long-tail UI.

The Pareto Principle is still useful for individual features, as they tend to be more narrowly defined. E.g. there is a set of spreadsheet formulas (actually much smaller than 20%) that drives >80% of formula usage.

While creative tools are the poster child of long-tail UIs, there are long-tail components in many transactional interfaces such as e-commerce or meal delivery (e.g. result filtering & sorting, product personalization interfaces, etc.).

Filtering UIs are another big category of long-tail UIs, and they involve so many tradeoffs and tough design decisions you could literally write a book about just them. Airbnb’s filtering UI here is definitely making an effort to make simple things easy with (personalized! 😍) shortcuts and complex things possible via more granular controls.

It’s all about the curve

Picture a plane with two axes: the horizontal axis being the complexity of the desired task (from the user’s perspective), and the vertical axis the cognitive and/or physical effort users need to expend to accomplish their task using a given interface.

Following Kay’s maxim guarantees these two points:

  • Simple things being easy guarantees a point on the lower left (low use case complexity → low user effort).
  • Complex things being possible guarantees a point somewhere on the far right. The lower down, the better — but higher up is acceptable.
Alan Kay's maxim visualized.

But even if we get these two points — what about all the points in between? There are infinite different ways to connect them, and they produce vastly different overall user experiences. How does your interface fare when their use case gets slightly more complex? Are users yeeted into the deep end of interface complexity (bad), or do they only need to invest a proportional, incremental amount of additional effort to achieve their goal (good)?

Meet the complexity-to-effort curve, the most important usability metric you’ve never heard of.

For delightful user experiences, making simple things easy and complex things possible is not enough — the transition between the two should also be smooth.

You see, simple use cases are the spherical cows in space of product design. They work great for prototypes to convince stakeholders, or in marketing demos, but the real world is messy. Most artifacts that users need to create to achieve their real-life goals rarely fit into your “simple” flows completely, no matter how well you’ve done your homework. They are mostly simple — with a liiiiitle wart here and there.

For a long-tail interface to serve user needs well in practice, we need to consciously design the curve, not just its endpoints.

User effort as a currency

A model with surprising predictive power is to treat user effort as a currency that users are spending to buy solutions to their problems. Nobody likes paying it; in an ideal world software would read our mind and execute perfectly with zero user effort. Since we don’t live in such a world, users understand to pay a bit of effort to achieve their goals, and are generally willing to pay more when they feel their use case warrants it.

Just like regular pricing, actual user experience often depends more on the relationship between cost and budget than on the absolute cost itself. If you pay more than you expected, you feel ripped off. You may still pay it because you need the product in the moment, but you’ll be looking for a better deal in the future. And if you pay less than you had budgeted, you feel like you got a bargain, with all the delight and loyalty that entails.

Avoid usability cliffs

Suppose you’re ordering pizza. You want a simple cheese pizza with ham and mushrooms. You use the online ordering system, and you notice that adding ham to your pizza triples its price. We’re not talking some kind of fancy ham where the pigs were fed on caviar and bathed in champagne, just a regular run-of-the-mill pizza topping. You may still order it if you’re really craving ham on your pizza and no other options are available, but how does it make you feel?

It’s not that different when the currency is user effort. The all too familiar “But I just wanted to _________, why is it so hard?”.

When a small increase in use case complexity results in a disproportionately large increase in user effort cost, we have a usability cliff. Usability cliffs make users feel resentful, just like the customers of our fictitious pizza shop.

A usability cliff is when a small increase in use case complexity requires a large increase in user effort.

Usability cliffs are very common in products that make simple things easy and complex things possible through entirely separate flows with no integration between them: a super high level one that caters to the most common use case with little or no flexibility, and a very low-level one that is an escape hatch: it lets users do whatever, but they have to recreate the solution to the simple use case from scratch before they can tweak it.

Example: The HTML video element

Simple things are certainly easy: all we need to get a video with a nice sleek set of controls that work well on every device is a single attribute: controls. We just slap it on our <video> element and we’re done with a single line of HTML:

<video src="videos/cat.mp4" controls></video>

➡️ A cat video player with a sleek toolbar

Now suppose use case complexity increases just a little. Maybe I want to add buttons to jump 10 seconds back or forwards. Or a language picker for subtitles. Or just to hide the volume control on a video that has no audio track. None of these are particularly niche, but the default controls are all-or-nothing: the only way to change them is to reimplement the whole toolbar from scratch, which takes hundreds of lines of code to do well.

Simple things are easy and complex things are possible. But once use case complexity crosses a certain (low) threshold, user effort abruptly shoots up. That’s a usability cliff.

Example: Instagram editor

For Instagram’s photo editor, the simple use case is canned filters, whereas the complex ones are those requiring tweaking through individual low-level controls. However, they are implemented as separate flows: you can tweak the filter’s intensity, but you can’t see or adjust the primitives it’s built from. You can layer both types of edits on the same image, but they are additive, which doesn’t work well.

Ideally, the two panels would be integrated, so that selecting a filter would adjust the low-level controls accordingly, which would both facilitate incremental tweaking and serve as a teaching aid for how filters work.

Example: Filtering in Coda

My favorite end-user facing product that gets this right is Coda, a cross between a document editor, a spreadsheet, and a database. All over its UI, it supports entering formulas instead of raw values, which makes complex things possible.

To make simple things easy, it also provides the GUI you’d expect even without a formula language. But here’s the twist: these presets generate formulas behind the scenes that users can tweak! Whenever users need to go a little beyond what the UI provides, they can switch to the formula editor and adjust what was generated — far easier than writing it from scratch.

Another nice touch: “And” is not just communicating how multiple filters are combined, but is also a control that lets users edit the logic.

Defining high-level abstractions in terms of low-level primitives is a great way to achieve a smooth complexity-to-effort curve, as it allows you to expose tweaking at various intermediate levels and scopes. The downside is that it can sometimes constrain the types of high-level solutions that can be implemented. Whether the tradeoff is worth it depends on the product and use cases.

Maximize signal-to-noise ratio

If you like eating out, this may be a familiar scenario:

— I would like the rib-eye please, medium-rare.
— Thank you sir/ma’am. How would you like your steak cooked?

Annoying, right? And yet, this is how many user interfaces work; expecting users to communicate the same intent multiple times in slightly different ways.

If incremental value should require incremental user effort, an obvious corollary is that things that produce no value should not require user effort. Using the currency model makes this obvious: who likes paying without getting anything in return?

Respect user effort. Treat it as a scarce resource — just like regular currency — and keep it close to the minimum necessary to declare intent. Do not require users to do work that confers them no benefit, and could have been handled by the UI. If it can be derived from other input, it should be derived from other input.

Source: NNGroup (adapted).

A once ubiquitous example that is thankfully going away, is the credit card form which asks for the type of credit card in a separate dropdown. Credit card numbers are designed so that the type of credit card can be determined from the first four digits. There is zero reason to ask for it separately.

Beyond wasting user effort, duplicating input that can be derived introduces an unnecessary error condition that you now need to handle: what happens when the entered type is not consistent with the entered number?

User actions that meaningfully communicate intent to the interface are signal. Any other step users need to take to accomplish their goal, is noise. This includes communicating the same input more than once, providing input separately that could be derived from other input with complete or high certainty, transforming input from their mental model to the interface’s mental model, and any other demand for user effort that does not serve to communicate new information about the user’s goal.

Some noise is unavoidable. The only way to have 100% signal-to-noise ratio would be if the interface could mind read. But too much noise increases friction and obfuscates signal.

Example: Programmatic Element removal

The two web platform methods to programmatically remove an element from the page provide a short yet demonstrative example of this for APIs. To signal intent in this case, the user needs to communicate two things: (a) what they want to do (remove an element), and (b) which element to remove. Anything beyond that is noise.

The modern element.remove() DOM method has an extremely high signal-to-noise ratio. It’s hard to imagine a more concise way to signal intent. It replaced the older parent.removeChild(child) method, which had much worse ergonomics. The older method was framed around removing a child, so it required two parameters: the element to remove, and its parent. But the parent is not a separate source of truth — it would always be the child node’s parent! As a result, its actual usage involved boilerplate, where developers had to write a much noisier if (element.parentNode) element.parentNode.removeChild(element) 3.

The difference in signal-to-noise ratio is staggering: 81% vs 20% in this case.

Of course, it was usually encapsulated in utility functions, which provided a similar signal-to-noise ratio as the modern method. However, user-defined abstractions don’t come for free, there is an effort (and learnability) tax there, too.

Boilerplate is repetitive code that users need to include without thought, because it does not actually communicate intent. It’s the software version of red tape: hoops you need to jump through to accomplish your goal, that serve no obvious purpose in furthering said goal except for the fact that they are required of you.

In case of parent.removeChild() above, the amount of boilerplate may seem small, but when viewed as a percentage of the total amount of code, the difference is staggering. The exact ratio (81% vs 20% here) varies based on the specifics of the API (variable names, method wording, etc.), but when the difference is meaningful, it transcends these types of low-level details. Think of it like big-O notation for API design.

Improving signal-to-noise ratio is also why the front-end web industry gravitated towards component architectures over copy-pasta snippets: components increase signal-to-noise ratio by encapsulating boilerplate and exposing a much higher signal UI. They are the utility functions of user interfaces. As an exercise for the reader, try to calculate the signal-to-noise ratio of a Bootstrap accordion (or any other complex component in any UI library that expects you to copy-paste snippets).

Instead of syntax, visual interfaces have micro-interactions. There are various models to quantify the user effort cost of micro-interactions, such as KLM.

You cannot uncover friction by asking users

When pointing out friction issues in design reviews, I have sometimes heard “users have not complained about this”. This reveals a fundamental misunderstanding about the psychology of user feedback.

Users are much more vocal about things not being possible, than about things being hard. The reason becomes clear if we look at the neuroscience of each.

Friction is transient in working memory; after completing the task, details fade from the user’s prefrontal cortex. However, the negative emotions persist in the limbic system and build up over time. Filing a complaint requires prefrontal engagement, which for friction is brief or absent. Users often can’t even articulate why the software feels unpleasant: the specifics vanish; the feeling remains.

Hard limitations, on the other hand, persist as conscious appraisals. The trigger doesn’t go away, since there is no workaround, so it’s far more likely to surface in explicit user feedback.

Both types of pain points cause negative emotions, but friction is primarily processed by the limbic system (emotion), whereas hard limitations remain in the prefrontal cortex (reasoning). This also means that when users finally do reach the breaking point and complain about friction, you better listen.

Second, user complaints are filed when there is a mismatch in expectations. Things are not possible but the user feels they should be, or interactions cost more user effort than the user had budgeted, e.g. because they know that a competing product offers the same feature for less (work). Often, users have been conditioned to expect poor user experiences, either because all options in the category are high friction, or because the user is too novice to know better 4. So they begrudgingly pay the price, and don’t think they have the right to complain, because it’s just how things are.

You might ask, “If all competitors are equally high-friction, how does this hurt us?” An unmet need is a standing invitation to disruption that a competitor can exploit at any time. Because you’re not only competing within a category; you’re competing with all alternatives — including nonconsumption (see Jobs‑to‑be‑Done). Even for retention, users can defect to a different category altogether (e.g., building native apps instead of web apps).

Historical examples abound. When it comes to actual currency, a familiar example is Airbnb: Until it came along, nobody would complain that a hotel of average price is expensive — it was just the price of hotels. If you couldn’t afford it, you just couldn’t afford to travel, period. But once Airbnb showed there is a cheaper alternative for hotel prices as a whole, tons of people jumped ship.

It’s no different when the currency is user effort. Stripe took the payment API market by storm when it demonstrated that payment APIs did not have to be so high friction. iPhone disrupted the smartphone market when it demonstrated that no, you did not have to be highly technical to use a smartphone. The list goes on.

Unfortunately, friction is hard to instrument. With good telemetry you can detect specific issues (e.g., dead clicks), but there is no KPI to measure friction as a whole. And no, NPS isn’t it — and you’re probably using it wrong anyway. Instead, the emotional residue from friction quietly drags many metrics down (churn, conversion, task completion), sending teams in circles like blind men touching an elephant. That’s why dashboards must be paired with product vision and proactive, first‑principles product leadership.

Steve Jobs exemplified this posture: proactively, aggressively eliminating friction presented as “inevitable.” He challenged unnecessary choices, delays, and jargon, without waiting for KPIs to grant permission. Do mice really need multiple buttons? Does installing software really need multiple steps? Do smartphones really need a stylus? Of course, this worked because he had the authority to protect the vision; most orgs need explicit trust to avoid diluting it.

So, if there is no metric for friction, how do you identify it?

  1. Usability testing lets you actually observe firsthand what things are hard instead of having them filtered through users’ memories and expectations.
  2. Design reviews/audits by usability experts is complementary to usability testing, as it often uncovers different issues. Design reviews are also great for maximizing the effectiveness of usability testing by getting the low-hanging fruit issues out of the way before it.
  3. Dogfooding is unparalleled as a discovery tool — nothing else will identify as many issues as using the product yourself, for your own, real needs. However, it’s important to keep in mind that you’re a huge power user of your own product. You cannot surface learnability issues (curse of knowledge) and you will surface issues no-one else has. Dogfooding is a fantastic discovery tool, but you still need user research to actually evaluate and prioritize the issues it surfaces.

User needs come first

Reducing friction rarely comes for free, just because someone had a good idea. These cases do exist, and they are great, but it usually takes sacrifices. And without it being an organizational priority, it’s very hard to steer these tradeoffs in that direction.

The most common tradeoff is implementation complexity. Simplifying user experience is usually a process of driving complexity inwards and encapsulating it in the implementation. Explicit, low-level interfaces are far easier to implement, which is why there are so many of them. Especially as deadlines loom, engineers will often push towards externalizing complexity into the user interface, so that they can ship faster. And if Product leans more data-driven than data-informed, it’s easy to look at customer feedback and conclude that what users need is more features (it’s not).

Simple to use is often at odds with simple to implement.

The first faucet is a thin abstraction: it exposes the underlying implementation directly, passing the complexity on to users, who now need to do their own translation of temperature and pressure into amounts of hot and cold water. It prioritizes implementation simplicity at the expense of wasting user effort.

The second design prioritizes user needs and abstracts the underlying implementation to support the user’s mental model. It provides controls to adjust the water temperature and pressure independently, and internally translates them to the amounts of hot and cold water. This interface sacrifices some implementation simplicity to minimize user effort.

This is why I’m skeptical of blanket calls for “simplicity.”: they are platitudes. Everyone agrees that, all else equal, simpler is better. It’s the tradeoffs between different types of simplicity that are tough.

In some cases, reducing friction even carries tangible financial risks, which makes leadership buy-in crucial. This kind of tradeoff cannot be made by individual designers — only when eliminating friction is an organizational priority.

The Oslo train ticket machine, with a screen saying 'Swipe card' and a single slot

The Oslo airport train ticket machine is the epitome of a high signal-to-noise interface. You simply swipe your credit card to enter and you swipe your card again as you leave the station at your destination. That’s it. No choices to make. No buttons to press. No ticket. You just swipe your card and you get on the train. Today this may not seem radical, but back in 2003, it was groundbreaking.

To be able to provide such a frictionless user experience, they had to make a financial tradeoff: it does not ask for a PIN code, which means the company would need to absorb the financial losses from fraudulent charges (stolen credit cards, etc.).

When user needs are prioritized at the top, it helps to cement that priority as an organizational design principle to point to when these tradeoffs come along in the day-to-day. Having a design principle in place will not instantly resolve all conflict, but it helps turn conflict about priorities into conflict about whether an exception is warranted, or whether the principle is applied correctly, both of which are generally easier to resolve. Of course, for that to work everyone needs to be on board with the principle. But here’s the thing with design principles (and most principles in general): they often seem obvious in the abstract, so it’s easy to get alignment in the abstract. It’s when the abstract becomes concrete that it gets tough.

The Web Platform has its own version of this principle, which is called Priority of Constituencies:

“User needs come before the needs of web page authors, which come before the needs of user agent implementors, which come before the needs of specification writers, which come before theoretical purity.”

This highlights another key distinction: the hierarchy of user needs is more nuanced than just users over developers.

Consumers over Producers

While users over developers is a good starting point, it is not sufficient to fully describe the hierarchy of user needs for many products. A more flexible framing is consumers over producers; developers are just one type of producer.

  • Consumers are typically more numerous than producers, so this minimizes collective pain.
  • Producers are typically more advanced, and can handle more complexity than consumers. I’ve heard this principle worded as “Put the pain on those who can bear it”, which emphasizes this aspect.
  • Producers are typically more invested, and less likely to leave

The web platform has multiple tiers of producers:

  • Specification writers are at the bottom of the hierarchy, and thus, can handle the most pain (ow! 🥴)
  • Browser developers (“user agent implementors” in the principle) are consumers when it comes to specifications, but producers when it comes to the web platform
  • Web developers are consumers when it comes to the web platform, but producers when it comes to their own websites

Even within the same tier there are often producer vs consumer dynamics. E.g. when it comes to web development libraries, the web developers who write them are producers and the web developers who use them are consumers.

This distinction also comes up in extensible software, where plugin authors are still consumers when it comes to the software itself, but producers when it comes to their own plugins. It also comes up in dual sided marketplace products (e.g. Airbnb, Uber, etc.), where buyer needs are generally higher priority than seller needs.

Life by a thousand ✨ sprinkles of delight ✨

In the economy of user effort, the antithesis of overpriced interfaces that make users feel ripped off are those where every bit of user effort required feels meaningful and produces tangible value to them. The interface is on the user’s side, gently helping them along with every step, instead of treating their time and energy as disposable. The user feels like they’re getting a bargain: they get to spend less than they had budgeted for! And we all know how motivating a good bargain is.

User effort bargains don’t have to be radical innovations; don’t underestimate the power of small touches. A zip code input that auto-fills city and state, a web component that automatically adapts to its context without additional configuration, a pasted link that automatically defaults to the website title (or the selected text, if any), a freeform date that is correctly parsed into structured data, a login UI that remembers whether you have an account and which service you’ve used to log in before, an authentication flow that takes you back to the page you were on before. Sometimes many small things can collectively make a big difference. In some ways, it’s the polar opposite of death by a thousand paper cuts: Life by a thousand sprinkles of delight! 😀

Conclusion

In the end, “simple things simple, complex things possible” is table stakes. The key differentiator is the shape of the curve between those points. Products win when user effort scales smoothly with use case complexity, cliffs are engineered out, and every interaction declares a meaningful piece of user intent. That doesn’t just happen by itself. It involves hard tradeoffs, saying no a lot, and prioritizing user needs at the organizational level. Treating user effort like real money, forces you to design with restraint. A rule of thumb is place the pain where it’s best absorbed by prioritizing consumers over producers. Do this consistently, and the interface feels delightful in a way that sticks. Delight turns into trust. Trust into loyalty. Loyalty into product-market fit.


  1. Kay himself replied on Quora and provided background on this quote. Don’t you just love the internet? ↩︎

  2. Yes, typing can be faster than dragging, but minimizing homing between input devices improves efficiency more, see KLM ↩︎

  3. Yes, today it would have been element.parentNode?.removeChild(element), which is a little less noisy, but this was before the optional chaining operator. ↩︎

  4. When I was running user studies at MIT, I’ve often had users exclaim “I can’t believe it! I tried to do the obvious simple thing and it actually worked!” ↩︎

  •  

State of HTML 2025 now open!

tl;dr: State of HTML 2025 survey is now open! Take it now

State of HTML 2025
Mamma mia, here we go again!

About two weeks ago, I announced that I was back leading this year’s State of HTML 2025 survey, after a one year hiatus. We are grateful for all the suggestions that poured in, they were immensely helpful in shaping the survey. After two weeks of hard work from a small team spanning three continents, we are finally ready to launch!

I would urge each and every one of you that works with the web platform to fill out this survey. It’s a unique opportunity to have your voice heard in the browser vendors’ decision-making process. Survey results are used by browsers to prioritize roadmaps — the reason Google is funding this. The results from State of … surveys directly feed into prioritization for next year’s Interop project.

Time spent thoughtfully filling them out is an investment that can come back to you tenfold in the form of seeing features you care about implemented, browser incompatibilities being prioritized, and gaps in the platform being addressed. In addition to browsers, several standards groups are also using the results for prioritization and decision-making.

Additionally, you get to learn about new and upcoming features you may have missed, and get a personalized, sharable score at the end to see how you compare to other respondents!

Take State of HTML 2025 Survey

While the survey will be open for about a month, responses entered within the first two weeks (until end of July) will have a much higher impact on the Web, as preliminary data will be directly used to inform Interop 2026.

Acknowledgements

I would like to thank the following people for their help in fleshing out the survey:

  • Sacha Greif for actually implementing the survey and tirelessly discussing my ideas
  • My apprentice Dmitry Sharabin for various fixes and improvements
  • My Google contacts, Philip Jägenstedt and Kadir Topal for making my involvement possible
  • And everyone who responded to my earlier call for suggestions — these were invaluable in shaping the survey, and I wish I could include them all!

FAQ

What’s new this year?

We spent a lot of time thinking about which features we are asking about and why. As a result, we added 35 new features, and removed 18 existing ones to make room. This is probably one of the hardest parts of the process, as we had to make some tough decisions.

We are also using the Web Components section to pilot a new format for pain points questions, consisting of a multiple choice question with common pain points, followed by the usual free form text list:

Screenshot showing the new pain points question format

While this increases the number of questions, we are hoping it will reduce survey fatigue by allowing participants to skip the freeform question more frequently (or spend less time on it) if most of their pain points have already been covered by the multiple choice question.

Last but not least, we introduced browser support icons for each feature, per popular request:

Can I edit my responses?

Absolutely! Do not worry about filling it out perfectly in one go. If you create an account, you can edit your responses for the whole period the survey is open, and even fill it out across multiple devices, e.g. start on your phone, then fill out some on your desktop, etc. Even if you’re filling it out anonymously, you can still edit responses on your device for some time, so you can have it open in a browser tab and revisit it periodically.

Why are there JS questions in an HTML survey?

This question comes up a lot every year.

For the same reason there are JS APIs in the HTML standard: many JS APIs are intrinsically related to HTML. We mainly included JS APIs that are in some way related to HTML, such as:

  • APIs used to manipulate HTML dynamically (DOM, interactivity, etc.)
  • Web Components APIs, used to create custom HTML elements
  • PWA features, including APIs used to access underlying system capabilities (OS capabilities, device capabilities, etc.)

The only two exceptions to this are two Intl APIs, which were mainly included because we wanted to get participants thinking about any localization/internationalization pain points they may have.

However, if you don’t write any JS, we absolutely still want to hear from you! In fact, I would encourage you even more strongly to fill out the survey, as people who don’t write JS are very underrepresented in these surveys. All questions are optional, so you can just skip any JS-related questions.

There is also a question at the end, where you can select that you only write HTML/CSS:

Question about HTML/CSS and JS balance

Why are some features included that are early stage proposals with no browser support?

While proposals with no browser support are not good candidates for immediate prioritization by browsers, their context chips give browser vendors and standards groups invaluable insight into what matters to developers, which also drives prioritization decisions.

However, we heard you loud and clear: when mature and early stage features are mixed together, you felt bait-and-switched. So this year, we are including icons to summarize browser support of each feature we ask about:

We are hoping this will also help prevent cases where participants confuse a new feature they have never heard of, with a more established feature they are familiar with.

Is the survey only available in English?

Absolutely not! Localization has been an integral part of these surveys since the beginning. Fun fact: None of the people working on these surveys is a native English speaker.

Screenshot showing dozens of languages and their contributors

State of HTML 2024 had translations for 31 languages.

However, since translations are a community effort, they are not necessarily complete, especially in the beginning. If you are a native speaker of a language that is not yet complete, please consider helping out!

I found a bug, what should I do?

Please file an issue so we can fix it!

  •  

Influence the State of HTML 2025 Survey!

State of HTML 2025
Mamma mia, here we go again!

Two years ago, I was funded by Google to design the inaugural State of HTML survey. While I had led State of … surveys before (also graciously sponsored by Google), that was by far the most intense, as 0→1 projects often are. In addition to the research, content, and analysis work that goes into every State of … survey, the unique challenges it presented were a forcing function for finally tackling some longstanding UX issues with these surveys. As a result, we pioneered new survey interaction UIs, and validated them via usability testing. This work did not just affect State of HTML, but had ripple effects on all subsequent State of … surveys.

The results made it all worth it. Turnout was the highest ever for a new Devographics 1 survey: 21 thousand participants, which remains a record high for State of HTML. The survey findings heavily influenced Interop 2024 (hello Popover API and Declarative Shadow DOM!) and helped prioritize several other initiatives, such as stylable selects. Despite lower 2024 participation, the survey still significantly influenced Interop 2025; notably, View transitions was added after being prominent in the survey for two years in a row.

This is the goal of these surveys: to drive meaningful change in the web platform. Sure, getting a shareable score about what you know and seeing how you compare to the rest of the industry is fun, but the reason browser vendors pour thousands of dollars into funding these surveys is because they provide unique vendor-neutral insights into developer pain points and priorities, which helps them make better decisions about what to work on. And this ultimately helps you: by getting your voice heard, you can directly influence the tools you work with. It’s a win-win: developers get better tools, and browser vendors get better roadmaps.

State of HTML 2025

Last year, I was too busy to take the lead again. Wrapping up my PhD and starting a new job immediately after, there was no time to breathe, let alone lead a survey. I’m happy to be returning to it this year, but my joy is bittersweet.

When I was first asked to lead this year’s survey a few months ago, I was still too busy to take it on. Someone else from the community accepted the role — someone incredibly knowledgeable and talented who would have done a fantastic job. But they live in the Middle East, and as the war escalated, their safety and their family’s well-being were directly impacted. Understandably, leading a developer survey became the least of their concerns. In the meantime, I made a few decisions that opened up some availability, and I was able to step in at the last minute. It’s a sobering reminder that events which feel far away can hit close to home — shaping not just headlines, but the work and lives of people we know.

Web Platform Features at the verge of Interop

A big part of these surveys is “feature questions”: respondents are presented with a series of web platform features, and asked about their familiarity and sentiment towards them. At the end, they get a score based on how many they were familiar with that they can share with others, and browser vendors and standards groups get signal on which upcoming features to prioritize or improve.

You can see which features were included in last year’s survey here or in 2 the table below.

State of HTML Features
Feature 2023 2024
<datalist> ✅ ✅
autocomplete attribute ✅ ✅
HTML Media Capture ✅ ✅
input.showPicker() ✅ ✅
FormData API ✅ ✅
<selectlist> ✅
contenteditable="plaintext-only" ✅ ✅
<dialog> ✅ ✅
<details> and <summary> ✅ ✅
Exclusive Accordion ✅ ✅
Popover API ✅ ✅
inert attribute ✅ ✅
Lazy loading ✅ ✅
srcset and sizes attributes ✅ ✅
Resource Hints ✅ ✅
Content-Security Policy (CSP) ✅ ✅
fetchpriority attribute ✅ ✅
blocking="render" ✅ ✅
<model> for AR/VR/3D content ✅ ✅
controlslist attribute ✅ ✅
<template> ✅ ✅
Using Custom Elements ✅ ✅
Defining Custom Elements ✅ ✅
Scoped Custom Element Registries ✅ ✅
Shadow DOM ✅ ✅
Declarative Shadow DOM ✅ ✅
Named slot assignment ✅ ✅
Imperative slot assignment ✅ ✅
ElementInternals API ✅ ✅
DOM Parts ✅ ✅
HTML Modules ✅ ✅
Landmark elements ✅ ✅
tabindex attribute ✅ ✅
focusgroup attribute ✅ ✅
<search> ✅ ✅
File System Access API ✅ ✅
Badging API ✅ ✅
Web Share API ✅ ✅
Launch Handler API ✅ ✅
File Handling API ✅ ✅
Window Controls Overlay API ✅ ✅
Isolated Web Apps ✅ ✅
Customizable Select ✅
EditContext ✅
caretPositionFromPoint ✅
Clipboard API ✅
CSS Custom Highlight API ✅
setHtmlUnsafe() ✅
parseHtmlUnsafe() ✅
Intl.Segmenter API ✅

I believe that co-designing these surveys with the community is the best way to avoid blind spots. While the timeline is tighter than usual this year (the survey is launching later this month!), there is still a little time to ask:

👉🏼 Which upcoming HTML features or Web APIs are currently on your radar? 👈🏼

What does “on your radar” mean? Features you’re excited about and would love to see progress on.

Why focus on upcoming features? The best candidates for these surveys are features that are mature enough to be fleshed out (at least a mature proposal, ideally a spec and WPT tests), but not so mature they have already been implemented in every browser. These are the features for which a survey such as this can drive meaningful impact.

If it’s so early for a feature that it’s not yet fleshed out, it’s hard to make progress via initiatives such as Interop. Interest is still useful signal to help prioritize work on fleshing it out, but it’s a bit of a longer game. And for features that are already implemented everywhere, the only thing that can improve things further is passage of time — a problem for which I unfortunately have no solution (yet).

Obviously we’re looking at all the usual suspects already, and initiatives such as webstatus.dev and Web platform features explorer provide a treasure trove of data which makes this task infinitely easier than it used to be. But this kind of preliminary signal is also useful for filtering and prioritization — to give you a sense, my list of candidate new features to ask about already has 57 items (!). Given that State of HTML 2024 asked about 49 features, that will need some very heavy pruning.

While the title is “State of HTML”, anything that wouldn’t fit better in State of CSS or State of JS is fair game. This includes topics such as accessibility, browser APIs, web components, templating, static site generation, media formats, and more. This may seem strange at first, but is no different than how the HTML specification itself covers a lot more than just HTML markup.

Any way to reach me works fine. You can post in the comments here (preferred), or reply on BlueSky, Mastodon, Threads, LinkedIn, or Twitter. Make sure to check the other replies first, and 👍 those with features you care about. Looking forward to your ideas and comments!


  1. Devographics is the company behind “State of …” surveys. ↩︎

  2. As an Easter egg, this widget is just a <details> element with custom CSS. Inspect it to see how it works! It works best in Chrome and Safari, as they fully support ::details-content. Chrome also supports calc-size(), which enables a nice animation, while the interaction in Safari is more abrupt. In terms of a11y, the summary gets spoken out as a regular <summary> element, with “Show more” or “Show less” at the end of its content. It seems ok-ish to me, but I’d love to hear from those with more expertise in this area. ↩︎

  •  

The Hovercar Framework for Deliberate Product Design

You may be familiar with this wonderful illustration and accompanying blog post by Henrik Kniberg about good MVPs:

Henrik Kniberg's MVP illustration

It’s a very visual way to illustrate the age-old concept that that a good MVP is not the one developed in isolation over months or years, grounded on assumptions about user needs and goals, but one that delivers value to users as early as possible, so that future iterations can take advantage of the lessons learned from real users.

From Hovercar to Skateboard

I love Henrik’s metaphor so much, I have been using a similar system to flesh out product requirements and shipping goals, especially early on. It can be immediately understood by anyone who has seen Henrik’s illustration, and I find it can be a lot more pragmatic and flexible than the usual simple two tiered system (core requirements and stretch goals). Additionally, I find this fits nicely into a fixed time, variable scope development process, such as Shape Up.

🛹 The Skateboard aka the Pessimist’s MVP
What is the absolute minimum we can ship, if need be? Utilitarian, bare-bones, and somewhat embarrassing, but shippable — barely. Anything that can be flintstoned gets flintstoned.
🛴 The Scooter aka the Realist’s MVP
The minimum product that delivers value. Usable, but no frills. This is the target.
🚲 The Bicycle aka the Optimist’s MVP
Stretch goals — UX polish, “sprinkles of delight”, nonessential but high I/E features. Great if we get here, fine if we don’t.
🏍️ The Motorcycle
Post-launch highest priority items.
🚗 The Car
Our ultimate vision, taking current constraints into account.
🏎️ The Hovercar aka the North Star UI
The ideal experience — unconstrained by time, resources, or backwards compatibility. Unlikely to ship, but a guiding light for all of the above.

Please note that the concept of a North Star UI has no relation to the North Star Metric. While both serve as a guiding light for product decisions, and both are important, the North Star UI guides you in designing the product, whereas the North Star Metric is about evaluating success. To avoid confusion, I’ll refer to it as “North Star UI”, although it’s not about the UI per se, but the product vision on a deeper level.

The first three stages are much more concrete and pragmatic, as they directly affect what is being worked on. The more we go down the list, the less fleshed out specs are, as they need to allow room for customer input. This also allows us to outline future vision, without having to invest in it prematurely.

The most controversial of these is the last one: the hovercar, i.e. the North Star UI. It is the very antithesis of the MVP. The MVP describes what we can ship ASAP, whereas the North Star describes the most idealized goal, one we may never be able to ship.

It is easy to dismiss that as a waste of time, a purely academic exercise. “We’re all about shipping. Why would we spend time on something that may not even be feasible?” I hear you cry in Agile.

Stay with me for a moment, and please try to keep an open mind. Paradoxical as it may sound, fleshing out your North Star can actually save you time. How? Start counting.

Core Idea

At its core, this framework is about breaking down tough product design problems into three more manageable components:

  1. North Star: What is the ideal solution?
  2. Constraints: What prevents us from getting there right now?
  3. Compromises: How close can we reasonably get given these constraints?

One way to frame it is is that 2 & 3 are the product version of tech debt.1

It’s important to understand what constraints are fair game to ignore for 1 and which are not. I often call these ephemeral or situational constraints. They are constraints that are not fundamental to the product problem at hand, but relate to the environment in which the product is being built and could be lifted or change over time. Things like:

  • Engineering resources
  • Time
  • Technical limitations (within reason)
  • Performance
  • Backwards compatibility
  • Regulatory requirements

Unlike ephemeral constraints, certain requirements are part of the problem description and cannot be ignored. Some examples from the case studies below:

While these may be addressed differently in different solutions, it would be an oxymoron to have a North Star that did not take them into account.

Benefits

1. It makes hard product problems tractable

Nearly every domain of human endeavor has a version of divide and conquer: instead of solving a complex problem all at once, break it down into smaller, manageable components and solve them separately. Product design is no different.

This process really shines when you’re dealing with the kinds of tough product problems where at least two of these questions are hard, so breaking it down can do wonders for reducing complexity.

2. It makes the product design process robust and adaptable

By solving these components separately, our product design process becomes can more easily adapt to changes.

I have often seen “unimplementable” solutions become implementable down the line, due to changes in internal or external factors, or simply because someone had a lightbulb moment.

By addressing these components separately, when constraints get lifted all we need to reevaluate is our compromises. But without this modularization, our only solution is to go back to the drawing board. Unsurprisingly, companies often choose to simply miss out on the opportunity, because it’s cheaper (or seems cheaper) to do so.

3. It facilitates team alignment by making the implicit, explicit

Every shipping goal is derived from the North Star, like peeling layers off an onion. This is whether you realize it or not.

Whether you realize it or not, every shipping goal is always derived from the North Star, like peeling layers off an onion. In some contexts the process of breaking down a bigger shipping goal into milestones that can ship independently is even called layering.

The process is so ingrained, so automatic, that most product designers don’t realize they are doing it. They go from hovercar to car so quickly they barely realize the hovercar was there to begin with. Thinking about the North Star is taboo — who has time for daydreaming? We must ship, yesterday!

But the hovercar is fundamental. Without it, there is no skateboard — you can’t reduce the unknown. When designing it is not an explicit part of the process, the result is that the main driver of all product design decisions is something that can never be explicitly discussed and debated like any other design decision. In what universe is that efficient?

A skateboard might be a good MVP if your ultimate vision is a hovercar, but it would be a terrible minimum viable cruise ship — you might want to try a wooden raft for that.

A wooden raft, then a simple sailboat, then a speedboat, then a yacht, and finally a ship.

A skateboard may be a great MVP for a car, but a terrible MVP for a cruise ship.

Making the North Star taboo doesn’t make it disappear (when did that ever work?).

It just means that everyone is following a different version of it. And since MVPs are products of the North Star, this will manifest as difficulty reaching consensus at every step of the way.

The product team will disagree on whether to ship a skateboard or a wooden raft, then on whether to build a scooter or a simple sailboat, then on whether to work on a speedboat or a yacht, and so on. It will seem like there is so much disconnect that every decision is hard, but there is actually only one root disconnect that manifests as multiple because it is never addressed head on.

Two people arguing. One has a speech bubble with a skateboard, the other a speech bubble with a wooden raft. The first also has a thought bubble with a car, the second a thought bubble with a ship.

When the North Star is not clearly articulated, everyone has their own.

Here is a story that will sound familiar to many readers:

A product team is trying to design a feature to address a specific user pain point. Alice has designed an elegant solution that addresses not just the problem at hand, but several prevalent longstanding user pain points at once — an eigensolution. She is aware it would be a little trickier to implement than other potential solutions, but the increase in implementation effort is very modest, and easily offset by the tremendous improvement in user experience. She has even outlined a staged deployment strategy that allows it to ship incrementally, adding value and getting customer feedback earlier.

Excited, she presents her idea to the product team, only to hear engineering manager Bob dismiss it with “this is scope creep and way too much work, it’s not worth doing”. However, what Bob is actually thinking is “this is a bad idea; any amount of work towards it is a waste”. The design session is now derailed; instead of debating Alice’s idea on its merits, the discussion has shifted towards costing and/or reducing effort. But this is a dead end because the amount of work was never the real problem. In the end, Alice wants to be seen as a team player, so she backs off and concedes to Bob’s “simpler” idea, despite her worries that it is overfit to the very specific use case being discussed, and the product is now worse.

Arguing over effort feels safer and less confrontational than debating vision — but is often a proxy war. Additionally, it is not productive. If the idea is poor, effort is irrelevant. And once we know an idea is good and believe it to our core, we have more incentive to figure out implementation, which often proves to be easier than expected once properly investigated. Explicitly fleshing out the Hovercar strips away the noise and brings clarity.

When we answer the questions above in order and reach consensus on the North Star before moving on to the compromises, we know what is an actual design decision and what is a compromise driven by practical constraints. Articulating these separately, allows us to discuss them separately. It is very hard to evaluate tradeoffs collaboratively if you are not on the same page about what we are trading off and how much it’s worth. You need both the cost and the benefit to do a cost-benefit analysis!

Additionally, fleshing the North Star out separately ensures that everyone is on the same page about what is being discussed. All too often have I seen early design sessions where one person is discussing the skateboard, another the bicycle, and a third one the hovercar, no-one realizing that the reason they can’t reach consensus is that they are designing different things.

4. It can improve the MVP via user testing

Conventional wisdom is that we strip down the North Star to an MVP, ship that, then iterate based on user input. With that process, our actual vision never really gets evaluated and by the time we get to it, it has already changed tremendously.

But did you know you can actually get input from real users without writing a single line of code?

alt text

Believe it or not, you don’t need to wait until a UI is prototyped to user test it. You can even user test a low-fi paper prototype or even a wireframe. This is widely known in usability circles, yet somehow entirely unheard of outside the field. The user tells you where they would click or tap on every step, and you mock the UI’s response by physically manipulating the prototype or showing them a wireframe of the next stage.

Obviously, this works better for some types of products than others. It is notably hard to mock rich interactions or UIs with too many possible responses. But when it does work, its Impact/Effort ratio is very high; you get to see whether your core vision is on the right track, and adjust your MVP accordingly.

It can be especially useful when there are different perspectives within a team about what the North Star might be, or when the problem is so novel that every potential solution is low-confidence. No-one’s product intuition is always right, and there is no point in evaluating compromises if it turns out that even the “perfect” solution was not actually all that great.

5. It paves the way for future evolution

So far, we have discussed the merits of designing our North Star, assuming we will never be able to ship it. However, in many cases, simply articulating what the North Star is can bring it within reach. It’s not magic, just human psychology.

Once we have a North Star, we can use it to evaluate proposed solutions: How do they relate to it? Are they a milestone along a path that ends at the North Star? Do they actively prevent us from ever getting there? Prioritizing solutions that get us closer to the North Star can be a powerful momentum building tool.

Humans find it a lot easier to make one more step along a path they are already on, than to make the first step on an entirely new path. This is well-established in psychology and often used as a technique for managing depression or executive dysfunction. However, it applies on anything that involves humans — and that includes product design.

Once we’re partway there, it naturally begs the question: can we get closer? How much closer? Even if we can’t get all the way there, maybe we can close enough that the remaining distance won’t matter. And often, the closer you get, the more achievable the finish line gets.

In fact, sometimes simply reframing the North Star as a sequence of milestones rather than a binary goal can be all that is needed to make it feasible. For an example of this, check out the CSS Nesting case study below.

Case studies

In my 20 years of product design, I have seen ephemeral constraints melt away so many times I have learned to interpret “unimplementable” as “kinda hard; right now”. Two examples from my own experience that I find particularly relevant below, one around Survey UI, and one around a CSS language feature.

Context Chips and the Power of Engineering Momentum

Illustration of context chips

The case study is described at length in Context Chips in Survey Design: “Okay, but how does it feel?”. In a nutshell, the relevant bits are:

  • Originally, I needed to aggressively prioritize due to minimal engineering resources, which led me to design an extremely low-effort solution which still satisfied requirements.
  • The engineer hated the low-effort idea so much, he prototyped a much higher-effort solution in a day, backend and all. Previously, this would have been entirely out of the question.
  • Once I took the ephemeral constraints out of the question, I was able to design a much better, novel solution, but it got pushback on the basis of effort.
  • Prototyping it allowed us to user test it, which revealed it performed way better than alternatives.
  • Once user testing built engineering momentum and the implementation was more deeply looked into, it turned out it did not actually require as much effort as initially thought.

Here is a dirty little secret about software engineering (and possibly any creative pursuit): neither feasibility nor effort are fixed for a given task. Engineers are not automatons that will implement everything with the same energy and enthusiasm. They may implement product vision they disagree with, but you will be getting very poor ROI out of their time.

Investing the time and energy to get engineers excited can really pay dividends. When good engineers are excited, they become miracle workers.

In fact, engineering momentum is often, all that is needed to make the infeasible, feasible. It may seem hard to fit this into the crunch of OKRs and KPIs but it’s worth it; the difference is not small, it is orders of magnitude. Things that were impossible or insurmountable become feasible, and things that would normally take weeks or months get done in days.

One way to build engineering momentum is to demonstrate the value and utility of what is being built. All too often, product decisions are made in a vacuum, based on gut feelings and assumptions about user needs. Backing them up with data, such as usability testing sessions is an excellent way to demonstrate (and test!) their basis. When possible, having engineers observe user testing sessions firsthand can be much more powerful than secondhand reports.

Relaxed CSS Nesting and the Power of Evolution

Sometimes high effort things just take a lot of hard work and there is no way around it. Other times, feasibility is just one good idea away.

One of my favorite examples, and something I’m proud to have helped drive is the relaxed CSS Nesting syntax, now shipped in every browser. It is such an amazing case study on the importance of having an explicit and consensus-backed North Star UI 2.

In a nutshell, CSS nesting was a (then new) CSS syntax that let developers better organize their code through reducing repetition.

table.browser-support {
	border-collapse: collapse;
}
table.browser-support th,
table.browser-support td {
	border: 1px solid silver;
}
@media (width < 600px) {
	table.browser-support,
	table.browser-support tr,
	table.browser-support th,
	table.browser-support td {
		display: block;
	}
}
table.browser-support th {
	border: 0;
}
table.browser-support td {
	background: yellowgreen;
}
table.browser-support td:empty {
	background: red;
}
table.browser-support td > a {
	color: inherit;
}

table.browser-support {
	border-collapse: collapse;

	@media (width < 600px) {
		&, tr, th, td {
			display: block;
		}
	}

	th, td {
		border: 1px solid silver;
	}
	th {
		border: 0;
	}
	td {
		background: yellowgreen;

		&:empty {
			background: red;
		}

		> a {
			color: inherit;
		}
	}
}

Example of CSS code, with (right) and without (left) nesting. Which one is easier to read?

This is one of the rare cases where the North Star was well known in advance, since the syntax was already well established in developer tooling (CSS preprocessors). Instead, the big challenge was navigating the practical constraints, since CSS implemented in browsers has different performance characteristics, so a syntax that is feasible for tooling may be out of reach for a browser. In this case, the North Star syntax had been ruled out by browser engineers due to prohibitive parsing performance 3, so we had to design a different, more explicit syntax that could be parsed more efficiently.

At this point, it is important to note that CSS Nesting is a feature that is very heavily used once available. Conciseness and readability are paramount, especially when conciseness is the sole purpose of the feature in the first place!

Initial attempts for a syntax that satisfied these technical requirements introduced a lot of noise, making the syntax tedious to write and noisy to read. Even worse, these attempts were actively incompatible with the North Star syntax, as well as other parts of the language (namely, the @scope rule). This meant that even if the North Star syntax became feasible later, CSS would need to forever support syntax that would then have no purpose, and would only exist as a wart from the past, just like HTML doctypes.

Once Google became very keen to ship Nesting (driven by State of CSS 2022, which showed it as the top missing CSS feature), a small subset of the CSS Working Group, led by Elika Etemad and myself met to explore alternatives, and produced four competing proposals. The one that the group voted to adopt 4 was the one I designed explicitly to answer the question: If the North Star syntax is out of the question right now, what is the largest subset of it that is feasible?

Once we got consensus on this intermediate syntax, I started exploring whether we could get any closer to the 🌟, even proposing an algorithm that would reduce the number of cases that required the slower parsing to essentially an edge case. A few other WG members joined me, with my co-TAG member Peter Linss being most vocal.

This is a big advantage of North Star compatible designs: it is much easier to convince people to move a little further along on the path they are already on, than to move to a completely different path. With a bit of luck, you may even find yourself implementing an “infeasible” North Star without even realizing it, one little step at a time.

We initially faced a lot of resistance from browser engineers, until eventually a brilliant Google engineer, Anders Ruud and his team experimented with variations of my proposed algorithm and actually closed in on a way to implement the North Star syntax in Chrome. The rest, as they say, is history. 🌟

Conclusion

Hopefully by now you’re convinced about the value of investing time in reaching alignment on an explicit North Star that has buy-in from the entire product team.

A common misconception is that the North Star is a static goal that prevents you from adapting to new data, such as customer feedback. But often, your North Star will change a lot over time, and that’s okay. Having an initial destination does not take away your ability to course correct. That’s not giving up, it’s adapting.

And yes, it’s true that many product teams do use a vision-led approach — they just start from the car, not the hovercar. While that confers some of the benefits above, there is still an implicit reduction happening, because the hovercar is still there in the back of their mind.

Note that for this framework to be beneficial, it is important that everyone is on the same page and understands the steps, benefits, and goals of this approach. Co-designing a North Star with a team that sees the process as a pointless thought experiment will only add friction and will not confer any of these benefits. Also, this is a mindset that can only work when applied top-down. If you are not a decision-maker at your place of work and leadership is not on board, you will have a very hard time if you try to push this ad hoc, without first getting leadership buy-in. You can try sending them a link to this blog post!

If this post resonated, please share your own case studies in the comments. Or, if you decide to give this framework a try, I’d love to hear how it went!


  1. Indeed, looks like I’m not the first to draw a parallel between the two! ↩︎

  2. I even did an entire talk about it at Web Unleashed, with a lot more technical detail than what I have included here. ↩︎

  3. for any Compilers geeks out there that want all the deets: it required potentially unbounded lookahead since there is no fixed number of tokens a parser can read and be able to tell the difference between a selector and a declaration. ↩︎

  4. Originally dubbed “Lea’s proposal”, and later “Non-letter start proposal”, but became known as Option 3 from its position among the five options considered (including the original syntax). ↩︎

  •  

Bluesky Likes Web Components

Screenshot of the Bluesky Likes components

Just want the components? Here you go: Demo Repo NPM

A love letter to the Bluesky API

I’m old enough to remember the golden Web 2.0 era, when many of today’s big social media platforms grew up. A simpler time, when the Web was much more extroverted. It was common for websites to embed data from others (the peak of mashups), and prominently feature widgets from various platforms to showcase a post’s likes or shares.

Especially Twitter was so ubiquitous that the number of Twitter shares was my primary metric for how much people were interested in a blog post I wrote. Then, websites started progressively becoming walled gardens, guarding their data with more fervor than Gollum guarding the Precious. Features disappeared or got locked behind API keys, ridiculous rate limits, expensive paywalls, and other restrictions. Don’t get me wrong, I get it. A lot of it was reactionary, a response to abuse — the usual reason we can’t have nice things. And even when it was to stimulate profit — it is understandable that they want to monetize their platforms. People gotta eat.

I was recently reading this interesting article by Salma Alam-Naylor. The article makes some great points, but it was something else that caught my eye: the widget of Bluesky likes at the bottom.

Screenshot of Salma's Bluesky likes widget
Salma's Bluesky likes widget that inspired these

I mentioned it to my trusty apprentice Dmitry who discovered the API was actually much simpler than what we’ve come to expect. Later, it turned out Salma has even written an entire post on how to implement the same thing on your own site.

The openness of the API was so refreshing. Not only can you read public data without being authenticated, you don’t even need an API key! Major nostalgia vibes.

It seemed the perfect candidate for a web component that you can just drop in to a page, give it a post URL, and it will display the likes for that post. I just had to make it, and of course use it right here.

Web Components that use API data have been historically awkward. Let’s set aside private API keys or APIs that require authentication even for reading public data for a minute. Even for public API keys, where on Earth do you put them?! There is no established pattern for passing global options to components. Attributes need to be specified on every instance, which is very tedious. So every component invents their own pattern: some bite the bullet and use attributes, others use static class fields, data-* attributes on any element or on specific elements, separate ES module exports, etc. None of these are ideal, so components often do multiple. Not to mention the onboarding hassle of creating API keys if you want to try multiple APIs.

The Bluesky API was a breath of fresh air: just straightforward HTTP GET requests with straightforward JSON data responses.

Sing with me!
🎶 all you need is fetch 🎺🎺🎺
🎶 all you need is fetch, fetch 🎶
🎶 fetch is all you need 🎶

Building a component that used it was a breeze.

Two Components for displaying Bluesky likes

In the end I ended up building two separate components, published under the same bluesky-likes npm package:

  • <bluesky-likes> — displays the number of likes for a post, and
  • <bluesky-likers> — displays the list of users who liked a post.

They can be used separately, or together. E.g. to get a display similar to Salma’s widget, the markup would look like this:

<script src="https://unpkg.com/bluesky-likes" type="module"></script>

<h2>
	<bluesky-likes src="https://bsky.app/profile/lea.verou.me/post/3lhygzakuic2n"></bluesky-likes>
	likes on Bluesky
</h2>

<p>
	<a href="https://bsky.app/profile/lea.verou.me/post/3lhygzakuic2n">Like this post on Bluesky to see your face on this page</a>
</p>

<bluesky-likers src="https://bsky.app/profile/lea.verou.me/post/3lhygzakuic2n"></bluesky-likers>

And the result would be similar to this:

I started by making a single component that did both, but it quickly became clear that it was better to split them up. It provided a lot more flexibility with only a tiny bit more effort for the common case, and it allowed me to simplify the internal structure of each component.

Requests are aggressively cached across component instances, so the fact that it’s two separate components doesn’t mean you’ll be making duplicate requests. Additionally, these ended up pretty lightweight: the whole package is ~2.5 KB minified & gzipped and dependency-free.

API Design for Web Components

Design Principles

Per my usual API design philosophy, I wanted these components to make common cases easy, complex cases possible, and not have usability cliffs, i.e. the progression from the former to the latter should be smooth.

API design curve

What does that mean for a web component?

Common use cases should be easy

You should have a good result by simply including the component and specifying the minimum input to communicate your intent, in this case, a Bluesky post URL.

  • You should not need to write CSS to make it look decent
  • You should not need to write JavaScript to make it work
  • You should not need to slot content for things that could have sensible defaults
  • You should not need to specify things it can figure out on its own from things you’ve already specified

Complex use cases should be possible

If you’re willing to put more work into it, the sky should be the limit. You should be able to completely restyle it, customize nearly every part of its UI etc, but the UX of these things doesn’t need to be optimized.

For example:

  • Extensibility over encapsulation: If something doesn’t need to be hidden away, expose it as a part. Don’t be frugal with your parts. The downsides of exposing too many parts are few and small, but not exposing enough parts can make certain styling impossible.
  • Don’t be frugal with slots: use slots with fallback content liberally. That way people can customize content or even entire parts of the UI.
  • Expose states for conditional styling. Yes, it’s Baseline now.

You can style the <slot> element itself, to avoid adding (and thus, having to expose) additional wrapper divs. And yes, you can expose a <slot> via a part as well. Just be mindful that that part will be available whether the slot has slotted content or not.

For these components, as a proof of concept, in addition to parts and slots all component styles and templates are exposed as static properties on the component class that you can modify or replace, either directly on it, or in your own subclass, for extreme customizability.

No usability cliffs

Making common things easy and complex things possible is not enough for a good API. Most use cases fall somewhere in between the two extremes. If a small increase in use case complexity throws users off the deep end in terms of API complexity, they’re gonna have a bad time.

The API should have enough customization hooks that common customizations do not require going through the same flow as full customization and recreating everything.

For web components, this might mean:

  • Ideally, standard CSS properties on the host should work. This is also part of the principle of least astonishment. However, sometimes this is simply not feasible or it would require unacceptable tradeoffs, which brings us to…
  • Exposing enough custom properties that basic, common customizations don’t require parts.
  • Nest slots liberally: You should not have to replace an entire part of the UI just to customize its content. Nested slots allow you to provide UI extension points at different levels of abstraction.

The 99-99 rule of Web Components

The Ninety-Ninety Rule tells us that the last 10% of the work takes 90% of the time. I would argue that for web components, it’s more like a 99-99 Rule.

Take these components as an example. They are the poster child for the kind of straightforward, simple component that does one thing well, right? But web components are a bit like children: if most people realized upfront how much work they are, way fewer would get made. 😅

Building a web component is always more work than it looks

Even when the core functionality is straightforward, there are so many other things that need to be done:

  • Dynamically responding to changes (in attributes, slots, nested content, etc) like regular HTML elements takes work, especially if you want to do it 100% properly, which is rarely a good idea (more on that below). Libraries like Lit make some of it easier, but not trivial.
  • Accessibility and i18n often take orders of magnitude more work than core functionality, especially together.
  • Designing & implementing style and UI customization hooks
  • Figuring out the right tradeoffs between performance and all of the above

And this is without any additional functionality creeping up.

Some battle scars examples below.

Customizing the link in <bluesky-likes>

A good component has sensible defaults, but allows customization of everything users may reasonably want to customize. There is nothing more annoying than finding a web component that does almost what you want, but doesn’t allow you to customize the one thing you really need to customize.

My first prototype of <bluesky-likes> always had an internal link in its shadow DOM that opened the full list of likers in a new tab. This opened it up to usability, accessibility, and i18n issues:

  • What if you want it to link to the post itself, or even an entirely different URL?
  • How to customize the link attributes, e.g. rel or target?
  • a11y: The link did not have a title at the time, only the icon had alt text. This meant assistive technologies would read it like “Butterfly blue heart fifteen”. How to word the link title to best communicate what the link does to assistive technologies without excessive verbosity?
  • And then, how to allow users to customize the link title for i18n?

Often components will solve these types of problems the brute force way, by replicating all <a> attributes on the component itself, which is both heavyweight and a maintenance nightmare over time.

Instead, we went with a somewhat unconventional solution: the component detects whether it’s inside a link, and removes its internal <a> element in that case. This solves all four issues at once; the answer to all of them is to just wrap it with the link of your choice. This allowed us to just pick a good default title attribute, and not have to worry about it.

It’s not perfect: now that :host-context() is removed, there is no way for a component to style itself differently when it’s inside a link, to e.g. control the focus outline. And the detection is not perfect, because doing it 100% perfectly would incur a performance penalty for little gain. But on balance, it so far seems the tradeoffs are worth it.

The pain of creating accessible components

My first prototype of <bluesky-likers> wrapped all avatars with regular links (they just had rel="nofollow" and target=_blank"). Quite reasonable, right? And then it dawned on me: this meant that if a keyboard user had the misfortune of stumbling across this component in their path, they would have needed to hit Tab 101 (!) times in the worst case to escape it. Yikes on bikes! 😱

So what to do? tabindex="-1" would remove the links from the tabbing order, fixing the immediate problem. But then how would keyboard users actually access them?

A bigger question is “Do they need to?”. These links are entirely auxiliary; in Salma’s original widget avatars were not links at all. Even if someone wants to explore the profiles of people who liked a post for some reason, the Bluesky “Liked By” page (already linked via <bluesky-likes>) is a much better fit for this.

When using a pointing device, links are free. If you don’t interact with them, they don’t get in your way, so you may as well have them even if few users will need them. But when something is part of the tabbing order, there is now a cost to it. Is the value of being able to tab to it outweighed by the friction of having to tab past it?

On the other hand, it feels wrong to have links that are not exposed at all to keyboard and assistive tech users. Even if they are auxiliary, making them entirely inaccessible feels like we’re talking away their agency.

I decided to err on the side of exposing the links to keyboard users, and added a description, via a description slot with default fallback content, to explain to SR users what is being displayed, and a skip link after it, which is visible when focused.

Why not use the default slot for the description?

The default slot can be very convenient when nothing else is slotted. However, it is very annoying to slot things in other slots without slotting anything in the default slot. Consider this:

<bluesky-likers src="...">
     <div slot="empty">No likers :(</div>
</bluesky-likers>

It may not look like it, but here we’ve also slotted a few blank text nodes to the default slot, which would obliterate the SR-accessible default description with no visible signs to the developer. And since 2/5 devs don’t test at all for screen readers, they would be unlikely to notice.

Default slots are great because they allow users to specify content without having to understand slots — it’s just how HTML works. However, because of this issue, I mainly recommend using them for things one nearly always wants to specify when using the component. If actual content is slotted into it, the additional blank nodes are not a problem. You could also choose to go for the default slot if you don’t have any other slots, though that’s a little more dangerous, as you may always want to add more slots later.

It’s still not an ideal user experience though. A skip link offers you the choice of skipping only at the beginning. What happens if you tab through 30 links, and then decide you’ve had too much? Or when you’re tabbing backwards, via Shift+Tab? Then you’re still stuck wading through all links with no escape and no respite.

In the end, perhaps I should bite the bullet and implement more sophisticated keyboard navigation, similar to how native form controls work (imagine a <select> having tab stops for every <option>!). But I have already spent more than is reasonable on these components, so it’s time to let them ride the trains, and leave the rest to PRs. For now, I implemented Home and End keys to jump to the first and last link respectively, so that at least users have an out.

But as a former TAG member, I can’t help but see this as a gap in the platform. It should not be this hard to create accessible components. It should not require jumping through hoops, and the process should not be a minefield. Good keyboard accessibility benefits everyone, and the primitives the web platform currently provides to enable that are egregiously insufficient.

The pain of creating localizable web components

Difficulty jumps to eleven when you want to make a component localizable. As a minimum, it means any UI text, no matter where it appears, must be customizable. This is desirable anyway for customizability, but it becomes essential for localization. The quick and dirty way is to provide slots for element content and attributes for content that appears in attributes (e.g. titles, aria-labels, etc).

Avoid providing attributes as the only way to customize content. This means they cannot contain HTML, which is often necessary for localization, and always desirable for customization. That said, attributes are totally fine as a shortcut for making common cases easy. E.g. a common pattern is to provide both an attribute and a label with the same name for commonly customizable things (e.g. labels).

However, this is often not enough. For example, both components display formatted numbers: <bluesky-likes> displays the total number of likes, and <bluesky-likers> displays the number of likes not shown (if any).

The web platform thankfully already provides a low-level primitive for formatting numbers: Intl.NumberFormat, which you can also access via number.toLocaleString(). For example, to format 1234567 as 1.2M , you can do

// Try it in the console!
(1234567).toLocaleString("en", {notation: "compact"})

This is great for English UIs, but what about other languages?

If you answered “Oh, we’ll just pass this.lang to instead of a hardcoded "en"”, you’d be wrong, at least for the general case. That gives you the element language only when it’s directly specified on the element via a lang attribute. However, usually the lang attribute is not specified on every element, but on an ancestor, and it inherits down.

Something like is a good compromise:

const lang = this.lang
			|| this.parentNode.closest("[lang]")?.lang
			|| this.ownerDocument.documentElement.lang
			|| "en";

This gets you the element’s language correctly if it’s:

  • specified on the element itself
  • specified on an ancestor element within the same shadow tree
  • specified on the root element of the document

This is what these components use. It’s not perfect, but it covers a good majority of cases with minimal performance impact. Notably, the cases it misses is when the component is inside a shadow tree but is getting its language from an element outside that shadow tree, that is also not the root element. I’d wager that case is very rare, and there is always the escape hatch of specifying the lang attribute on the component itself.

What would doing it 100% properly entail?

If the route above is a shortcut and misses some cases, you may be wondering what it would take to cover every possible case. Maybe it’s just for the lulz, or maybe you’re working under very strict guidelines that require you to fully emulate how a native element would behave.

I advise against following or even reading this section. Proceed at your own risk. Or save your mental health and skip it. Unless you’re in the WHATWG, in which case please, go ahead.

So what would doing it 100% properly look like? First, we’d want to take nested shadow roots into account, using something like this, which you might want to abstract into a helper function.

let lang = this.lang;
if (!lang) {
	let langElement = this;
	while (!(langElement = langElement.closest("[lang]"))) {
		let root = langElement.getRootNode();
		let host = root.host ?? root.documentElement;
		langElement = host;
	}

	lang = langElement?.lang || "en";
}

But, actually, if you really needed to do it properly, even now you wouldn’t be done! What about dynamically reacting to changes? Any element’s lang attribute could change at any point.

Er, take my advice and don’t go there. Pour yourself a glass of wine (replace with your vice of choice if wine is not your thing), watch an episode of your favorite TV show and try to forget about this.

Some of you will foolishly continue. I hear some voices at the back crying “But what about mutation observers?”.

Oh my sweet summer child. What are you going to observe?

The element with the lang attribute you just found? WRONG. What if a lang attribute is added to an element between that ancestor and your component? I.e. you go from this:

<div lang="el" id="a">
	<div id="b">
		<bluesky-likes src="..."></bluesky-likes>
	</div>
</div>

To this:

<div lang="el" id="a">
	<div lang="es" id="b">
		<bluesky-likes src="..."></bluesky-likes>
	</div>
</div>

Your component language is now es, but nothing changed in the element you were observing (#a), so nothing notified your component. What is your recourse?

I told you to not think about it. You didn’t listen. It’s still not too late to skip this section and escape the horrors that lie ahead.

Still here? Damn, you’re stubborn. Fine, here’s how to do it with mutation observers if you really need to. But be warned, it’s going to hurt.

Mutation observers cannot observe ancestors, so the only way to detect changes that way would be to observe not just the element with the lang attribute but also its entire subtree. Oh and if the path from your component to that ancestor involves shadow trees, you need to observe them separately, because mutation observers don’t reach past shadow trees (proposal to change that).

😮‍💨 Surely, that should do it, right? WRONG again. I told you it would hurt.

Consider the scenario where the ancestor with the lang attribute is removed. Mutation observers cannot observe element removal (proposal to fix that), so if you go from this:

<body lang="el">
	<div lang="el" id="a">
		<div id="b">
			<bluesky-likes src="..."></bluesky-likes>
		</div>
	</div>
</div>

To this:

<body lang="el">
	<div id="b">
		<bluesky-likes src="..."></bluesky-likes>
	</div>
</div>

…nothing will notify your component if you’re just observing #a and its descendants.

So the only way to get it right in all cases is to observe the entire tree, from the document root down to your component, including all shadow trees between your component and the root. Feeling nauseous yet?

There is one alternative. So, the browser knows what the element’s language is, but the only way it exposes it is the :lang() pseudo-class, which doesn’t allow you to read it, but only check whether an element matches a given language. While not ideal, we can hack this to observe language changes.

Coupled with the earlier snippet to detect the current language, this allows us to detect changes to the component’s language without the huge performance impact of observing the entire page.

How can we do that? Once you’ve detected the component language, generate a rule that sets a CSS variable. E.g. suppose you detected el, you’d add this to your shadow DOM:

:host(:lang(el)) {
	--lang: el;
}

Then, we register the --lang property, and observe changes to it via Style Observer or just raw transition events. When a change is detected, run the detection snippet again and add another CSS rule.

When registering component CSS properties, make sure to register them globally (e.g. via CSS.registerProperty()), as @property does not currently work in shadow DOM. This is already spec’ed, but not yet implemented by browsers.

Now, should you do this? Just because you can, doesn’t mean you should. In the vast majority of cases, a few false positives/negatives are acceptable, and the tradeoff and performance impact of introducing all this complexity is absolutely not worth it. I can only see it being a good idea in very specific cases, when you have a reason to strive for this kind of perfection.

Most of web components development is about making exactly these kinds of tradeoffs between how close you want to get to the way a native element would behave, and how much complexity and performance impact you’re willing to sacrifice for it. But going all the way is rarely a good balance of tradeoffs. That said, this should be easier. Reading a component’s language should not require balancing tradeoffs for crying out loud!

There is some progress on that front. In September at TPAC we got WHATWG consensus on standardizing a way to read the current language / direction and react to future changes. To my knowledge, not much has happened since, but it’s a start. Perhaps this dramatic reenactment generates some empathy among WHATWG folks on what web components developers have to go through.

🚢 it, squirrel!

It’s all fun and games and then you ship.

Hopefully, I have demonstrated that if you’re not careful, building a web component can become a potentially unbounded task. Some tasks are definitely necessary, e.g. accessibility, i18n, performance, etc, but there comes a point where you’re petting.

So here they are: Demo Repo NPM

They’re far from perfect. Yes, they could be improved in a number of ways. But they’re good enough to use here, and that will do for now. If you want to improve them, pull requests are welcome (check with me for big features though). And if you use them on a for-profit site, I do expect you to fund their development. That’s an ethical and social expectation, not a legal one (but it will help prioritization, and that’s in your best interest too).

If you’ve used them, I’d love to see what you do with them!

Thanks to Léonie Watson for some of the early a11y feedback, and to Dmitry Sharabin for helping with the initial API exploration.

  •  

Construction Lines

I recently stumbled across The Oatmeal’s series on Creativity. While all of it is spot on, the part on erasers hit especially hard.

“There is a lot of shame associated with backpedaling; things like quitting your job, getting a divorce, or simply starting over are considered shameful.

But forward isn’t always progress.

And backward isn’t always regress.

Sometimes going down the wrong path isn’t a mistake — it’s a construction line.”

— Matthew Inman (The Oatmeal)

It was exactly what I needed to hear. You see, only a few days prior, Font Awesome and I had parted ways — the end of a short, but transformative chapter. I’m proud of what we built together, and grateful for what I learned along the way. But it was time to move on.

Jobs are a lot like relationships. They often start with infatuation — and end with the realization that you’re simply not compatible, and that’s no-one’s fault. Letting go always stings, even when it’s the right call. There’s always grief: when you’re not ready to move on, you grieve the bond; when you are, you grieve your expectations. But every ending leaves behind clarity — about who you are, and what makes you happy.

The pursuit of happiness

Today is my 39th birthday — and this summer marks 20 years since I first dipped my toes into this industry. Naturally, I’ve been doing a lot of reflection.

As is typical for ADHDers, I have done a ton of different things, and built a diverse skillset as a result. But what made me happiest? The list of highs went a bit like this:

  • Entrepreneurship: Co-founding a startup and driving it to become a household name (in Greece — this was 2008!)
  • Consulting: Being a full-time consultant, speaker, and author, traveling the world and jumping from one exciting gig to another
  • Academia:1 Pushing the boundaries of Human-Computer Interaction at MIT and teaching MIT CS students to care about people.

All had three things in common: autonomy, breadth, and impact.

These three things have been the biggest predictors of happiness for me — far more than income 2 or work-life balance, which are the usual suspects.

I used to aspire to work-life balance in the same way I aspired to frequent exercise — because it was good for me, not because it gave me joy. Eventually I realized that what makes me happy isn’t working less, it’s loving what I do, and feeling it matters. Working less cannot transform how your work makes you feel; it can only dampen the effects. But dilution doesn’t turn misery into joy — at best it just makes it tolerable. Don’t get me wrong, poor WLB can absolutely make you miserable; when long hours are an externally imposed expectation, not an internal drive fueled by passion. As with many things in life, it’s enthusiastic consent that makes all the difference.

Then there’s breadth. Most jobs try to box you in: PM or engineer? Scientist or practitioner? UX Researcher or designer? DevRel or standards? And I’m like…

Aurora is my spirit animal 🫶🏼 Source

It’s silly that people are forced to choose, and present themselves as less than to seem more attractive to hiring managers. To use myself as an example:

  • Web architecture: I have designed several web technologies that have shipped across all browsers. I’ve spent 4 years in the TAG, reviewing new web technologies across the web platform, and eventually leading the Web Platform Design Principles effort.
  • Product/usability/HCI: Prior to working as Product Lead at Font Awesome, I’ve earned a PhD at MIT in Human-Computer Interaction with a minor in Entrepreneurship & Innovation. I published peer reviewed papers in top-tier HCI conferences, and co-created/taught a course on usability & web technologies that is now a permanent subject. I have run user research for scientific and industry projects. I have started several open source projects, some used by millions. In the more distant past, I co-founded a (then) well-known social startup in my home country, Greece and ran product, engineering, and design for three years (six if you count pre-incorporation).
  • DevRel: I’ve given over 100 conference talks, published a bestselling book on CSS, and was the first devrel hire at W3C back in 2012. I have built dozens of apps and polyfills that stimulated developer interest in new Web features and drove browser adoption.

Should I present myself as a web architecture expert, a usability/product person, an HCI researcher, or a Developer Advocate?

What a pointless dilemma if I ever saw one!

Combining skills across different areas is a strength to be celebrated, not a weakness to be swept under the rug. The crossover between skills is where the magic happens. Off the top of my head:

  • Understanding usability principles has made me a far better web standards designer.
  • Web standards work is product design on hard mode. After the impossibly hard constraints and tradeoffs you deal with when designing APIs for the Web platform, regular product problems seem like a cakewalk (we have versions? And we can actually change things?? And we have reliable metrics?!? And the stakeholders all work at the same company?!? 🤯).
  • They often feed into each other: DevRel work made me a better communicator in everything I do. Usability made me a better speaker and educator3, so a better developer advocate too.
  • Leading the Web Platform Design Principles convinced me that explicit design principles are immensely useful for all product work.
  • Web standards taught me that contrary to popular belief, you do not need a benevolent dictator to ship. But then you do need a good process. Consensus does not magically grow on trees, building consensus is its own art.

Lastly, impact does not have to be about solving world hunger or curing cancer. Making people’s lives a little better is meaningful impact too. It all boils down to:

Impact=Individual Impact×Reach

You can achieve the same total impact by improving the lives of a few people a lot, or the lives of many people a little. For example, my work on web standards has been some of the most fulfilling work I’ve ever done. Its Individual Impact is small, but the Reach is millions, since all front-end developers out there use the same web platform.

What’s next?

Since consulting and entrepreneurship have been my happiness peaks, I figured I’d try them again. Yes, both at once, because after all, we’ve already established that WLB is a foreign concept 🤣

My apprentice Dmitry and I have been in high gear building some exciting things, which I hope to be able to share soon, and I feel more exhilarated than I have in years. I had missed drawing my own lines.

In parallel, I’m taking on select consulting work, so if you need help with certain challenges, or to level up your team around web architecture, CSS, or usability, get in touch.

Don’t get me wrong, I’m not closing the door to full-time roles. I know there are roles out there that value passion and offer the kind of autonomy, breadth, and impact that would let me thrive. It’s the ROI of digging through rubble to find them that gives me pause — as a product person at heart, I/E tradeoffs are top of mind. But if you have such a unicorn, I’m all ears.

I also finally took a few small steps to make my pro bono work financially sustainable, a long overdue todo item. Both pages still need work, but you can now support my writing via ko-fi4, and my open source work via GitHub Sponsors. I made separate pages for my two most popular projects, Prism (nearing 1.8 billion total npm installs! 🤯) and Color.js. This is as much about prioritization as it is about sustainability: money is an excellent signal about what truly matters to people.

I don’t have a polished “next” to announce yet.
But I’m exactly where I need to be.

Sometimes the clearest lines are the ones drawn after you erase.


  1. Many things wrong with academia, but the intellectual freedom is unparalleled, and it makes up for a lot. ↩︎

  2. See also Alan Watts’ “What if money was no object?” — a classic, but still relevant. ↩︎

  3. Teaching is absolutely a form of UI design — a UI that exposes your knowledge to students — the users. There are many similarities between how good educators design their material and how good UI designers design interfaces. ↩︎

  4. Thanks Dan Abramov for the wording inspiration (with permission). These things are so hard. ↩︎

  •  

Style-observer: JS to observe CSS property changes, for reals

Style-observer social media teaser

I cannot count the number of times in my career I wished I could run JS in response to CSS property changes, regardless of what triggered them: media queries, user actions, or even other JS.

Use cases abound. Here are some of mine:

  • Implement higher level custom properties in components, where one custom property changes multiple others in nontrivial ways (e.g. a --variant: danger that sets 10 color tokens).
  • Polyfill missing CSS features
  • Change certain HTML attributes via CSS (hello --aria-expanded!)
  • Set CSS properties based on other CSS properties without having to mirror them as custom properties

The most recent time I needed this was to prototype an idea I had for Web Awesome, and I decided this was it: I’d either find a good, bulletproof solution, or I would build it myself.

Spoiler alert: Oops, I did it again

A Brief History of Style Observers

The quest for a JS style observer has been long and torturous. Many have tried to slay this particular dragon, each getting us a little bit closer.

The earliest attempts relied on polling, and thus were also prohibitively slow. Notable examples were ComputedStyleObserver by Keith Clark in 2018 and StyleObserver by PixelsCommander in 2019.

Jane Ori first asked “Can we do better than polling?” with her css-var-listener in 2019. It parsed the selectors of relevant CSS rules, and used a combination of observers and event listeners to detect changes to the matched elements.

Artem Godin was the first to try using transition events such as transitionstart to detect changes, with his css-variable-observer in 2020. In fact, for CSS properties that are animatable, such as color or font-size, using transition events is already enough. But what about the rest, especially custom properties which are probably the top use case?

In addition to pioneering transition events for this purpose, Artem also concocted a brilliant hack to detect changes to custom properties: he stuffed them into font-variation-settings, which is animatable regardless of whether the axes specified corresponded to any real axes in any actual variable font, and then listened to transitions on that property. It was brilliant, but also quite limited: it only supported observing changes to custom properties whose values were numbers (otherwise they would make font-variation-settings invalid).

The next breakthrough came four years later, when Bramus Van Damme pioneered a way to do it “properly”, using the (then) newly Baseline transition-behavior: allow-discrete after an idea by Jake Archibald. His @bramus/style-observer was the closest we’ve ever gotten to a “proper” general solution.

Releasing his work as open source was already a great service to the community, but he didn’t stop there. He stumbled on a ton of browser bugs, which he did an incredible job of documenting and then filing. His conclusion was:

Right now, the only cross-browser way to observe Custom Properties with @bramus/style-observer is to register the property with a syntax of “<custom-ident>”. Note that <custom-ident> values can not start with a number, so you can’t use this type to store numeric values.

Wait, what? That was still quite the limitation!

My brain started racing with ideas for how to improve on this. What if, instead of trying to work around all of these bugs at once, we detect them so we only have to work around the ones that are actually present?

World, meet style-observer

At first I considered just sending a bunch of PRs, but I wanted to iterate fast, and change too many things. I took the fact that the domain observe.style was available as a sign from the universe, and decided the time had come for me to take my own crack at this age-old problem, armed with the knowledge of those who came before me and with the help of my trusty apprentice Dmitry Sharabin (hiring him to work full-time on our open source projects is a whole separate blog post).

One of the core ways style-observer achieves better browser support is that it performs feature detection for many of the bugs Bramus identified. This way, code can work around them in a targeted way, rather than the same code having to tiptoe around all possible bugs. As a result, it basically works in every browser that supports transition-behavior: allow-discrete, i.e. 90% globally.

Keep Calm and Style Observe

  • Safari transition loop bug (#279012): StyleObserver detects this and works around it by debouncing.
  • Chrome unregistered transition bug (#360159391): StyleObserver detects this bug and works around it by registering the property, if unregistered.
  • Firefox no initial transitionstart bug (#1916214): By design, StyleObserver does not fire its callback immediately (i.e. works more like MutationObserver than like ResizeObserver). In browsers that do fire an initial transitionstart event, it is ignored.
  • In addition, while working on this, we found a couple more bugs.

Additionally, besides browser support, this supports throttling, aggregation, and plays more nicely with existing transitions.

Since this came out of a real need, to (potentially) ship in a real product, it has been exhaustively tested, and comes with a testsuite of > 150 unit tests (thanks to Dmitry’s hard work).

If you want to contribute, one area we could use help with is benchmarking.

That’s all for now! Try it out and let us know what you think!

Gotta end with a call to action, amirite?

  •  

Context Chips in Survey Design: “Okay, but how does it _feel_?”

Minimalistic skeleton diagram showing the concept presented in this article

One would think that we’ve more or less figured survey UI out by now. Multiple choice questions, checkbox questions, matrix questions, dropdown questions, freeform textfields, numerical scales, what more could one possibly need?!

And yet, every time Google sponsored me to lead one of the State Of … surveys, and especially the inaugural State of HTML 2023 Survey, I kept hitting the same wall; I kept feeling that the established options for answering UIs were woefully inadequate for balancing the collection good insights with minimal friction for end-users.

The State Of surveys used a completely custom survey infrastructure, so I could often (but not always) convince engineering to implement new question UIs. After joining Font Awesome, I somehow found myself leading yet another survey, despite swearing never to do this again. 🥲 Alas, building a custom survey UI was simply not an option in this case; I had to make do with the existing options out there 1, so I felt this kind of pain to my core once again.

So what are these cases where the existing answering UIs are inadequate, and how could better ones help? I’m hoping this case study to be Part 1 of a series around how survey UI innovations can help balance tradeoffs between user experience and data quality, though this is definitely the one I’m most proud of, as it was such a bumpy ride, but it was all worth it in the end.

The Problem

For context, the body of State Of surveys is a series of “Feature questions”, which present the respondent with a certain web platform feature and ask if they had heard of it or used it. Feature questions look like this:

alt text

An example of a feature question from the State of CSS 2022 survey.

Respondents get a score in the end, based on how many of these they had heard of or used. Each survey had dozens of these questions. Based on initial estimates, State of HTML was going to have at least fifty.

alt text

This was my score. We revamped the scoring system for this iteration and switched from a percentage to a point-based score, since not all questions were equally weighted.

Respondents love these questions. They learn about new things they may not have heard of, and get to test their knowledge. But also, from the survey designer’s perspective, they gamify a (very long) survey, increasing completion rates, and provide users incentive to share their score on social media, spreading the word.

One would expect that they also provide valuable data, yet browser vendors had repeatedly mentioned that this data was largely useless to them. Surveys were all about what people felt, not what they knew or had used — they had better ways to gauge those. Instead, the reason they funneled thousands into funding these surveys every year was the 1-2 pain points questions towards the end. That was it. Survey data on experience and awareness could be useful, but only if it was accompanied with subjective sentiment data: if they hadn’t used it or heard about it, were they interested? If they had used it, how did it feel?

Optional freeform comments had been added the year prior, but got an abysmally low response rate, and being entirely freeform, were hard to analyze.

As an attempt to address this feedback, a button that opened a freeform comment field had been introduced the year prior, but response rates were abysmally low, starting from 0.9% for the first question 2 and dropping further along the way. This was no surprise to me: freeform questions have a dramatically lower response rate than structured questions, and hidden controls get less interaction (“out of sight, out of mind”). But even if they had a high response rate, freeform comments are notoriously hard to analyze, especially when they are so domain specific.

Ideation

Essentially, the data we needed to collect was a combination of two variables: experience and sentiment. Collecting data on two variables is common in survey design, and typically implemented as a matrix question.

🤷 👍 👎
Never heard of it
Heard of it
Used it
If user experience and cognitive load were not a concern, the same data could actually be collected with a matrix question.

Indeed, if there were only a couple such questions, a matrix could have been acceptable. But …could you imagine filling out 50 of these?

An acceptable solution needed to add minimal friction for end-users: there were at least 50 such questions, so any increase in friction would quickly add up — even one extra click was pushing it. And we needed a sufficiently high response rate to have a good CI. But it also needed to facilitate quantitative data analysis. Oh, and all of that should involve minimal engineering effort, as the (tiny) engineering team was already stretched thin.

Did I hear anyone say overconstrained? 😅

Idea 1: Quick context

Initially, I took these constraints to heart. Misguided as it may have been, the comment field and the infrastructure around it already existed, so I designed a UI that revealed relevant positive/negative sentiment options using contextual progressive disclosure. These inserted predefined responses into the comment field with a single click.

Being a purely client-side interaction meant it could be implemented in a day, and it still kept end-user friction at bay: providing sentiment was optional and only required a single click.

In theory, quantitative data analysis was not optimally covered, as freeform responses are notoriously hard to analyze. However, based in the psychology of user behavior, I hypothesized that the vast majority of users would not edit these at all, a minority would append context, and an even tinier minority would actually edit the responses. This meant we could analyze them via simple string matching and only lose a few false negatives.

Mockup of the quick context idea.

I was very proud of myself: I had managed to design a solution that satisfied all constraints, a feat that initially seemed impossible! Not to mention this design gently guided users towards using the comment field, which could motivate them to add even more context.

Yet, when I presented my mocks to the team, engineering hated it with a passion. The lead engineer (who was also the project founder) found the idea of turning a structured interaction into unstructured data deeply unsettling. So much it motivated him to implement a whole backend to store these followups properly, something I had initially thought was out of the question.

So now what? Back to the drawing board, but with one constraint lifted!

Ideas 2 & 3: Followups and sentiment radios

Mockups of intermediate ideas. Left: Followups (by lead engineer) Right: Sentiment radios (by Google PM)

This new backend came with a UI proposal that raised red flags for both me and the Google PM I was collaborating with (one of the survey’s core stakeholders, but not the main one). Even seeing the followup UI required an extra click, so it was guaranteed to have a low response rate. It would have been better than the 0.9% of the comment field (clicking is easier than typing!), but still pretty low (I would estimate < 15%). And even when users were intrinsically motivated to leave feedback, two clicks and a popover was a steep price to pay.

Another idea came from the Google PM: sentiment radios. It was an attempt to simplify the interaction by framing it as a two step process: first experience, then sentiment, through radio buttons that slid down once a main answer was selected. However, I was very concerned that such a major UI shift after every single answer would quickly become overwhelming over the course of the survey.

Idea 4: Context chips

Back to the drawing board, I asked myself: if I had infinite engineering resources, what UI would I design? The biggest challenge was reducing friction. All ideas so far had required at least one extra (optional) click to select sentiment. Could we do better? What if users could select both experience and sentiment with a single click?

Guided by this, I designed a UI where selecting sentiment is done via “context chips” which are actually part of the answer, so clicking them also selects the answer they are accompanying, allowing users to express an answer across both variables with a single click, or just select the answer itself to express no sentiment. To reduce visual clutter, these only faded in on hover. Additionally, clicking on the selected chip a second time would deselect it, fixing a longstanding UX issue with radio buttons 3.

Over the course of designing this, I became so convinced it was the right solution, that I implemented a high fidelity prototype myself, complete with code that could be easily adapted to the infrastructure used by the survey app.

The context chips prototype on desktop and mobile.

There were so many things I loved about this design, even beyond the core idea of answering both variables with a single click. There were no layout shifts, the followups were in close proximity to the main answer, and the styling of the chips helped build a visual association to reduce friction even more as you go. I was not a huge fan of the mobile version, but I couldn’t think of a much better way to adapt this UI to mobile.

Early alternative concept that supported followups. This was deemed too complicated and was abandoned early on.

Reception of context chips was not what I had hoped at first. I had expected pushback due to the engineering effort needed, but folks also had other concerns: that users would find things appearing on hover distracting and feel “ambushed”, that the UI was too “weird”, that users would not discover the 1-click interaction and use it as a two-step process anyway, and that response rate would be low because these chips were not visible upfront.

Mini-feature questions: Context Chips + Checkboxes?

Around the same time as designing context chips, I had a relevant realization: we don’t actually need to know both awareness and usage for all features.

For old, widely supported features, awareness doesn’t matter, because even when it’s low, it has plateaued. And for features that are so new they have not yet been implemented in browsers, usage is largely meaningless. For these cases, each feature only has two states, and thus experience can be expressed with a checkbox! This would allow us to combine questions about multiple features in one, and we could still use context chips, albeit a little differently:

The mini features prototype on desktop and mobile.

While these could be used for questions that either discern usage or awareness, we decided to stick to the former, as there was a (valid) concern that having mini-feature questions whose checked state meant different things could be confusing and lead to errors. That way, only old, lower-priority features would be relegated to this template, and new features which tend to be higher priority for browser vendors would still get the full UI, comments and all. Instead, to improve the experience for cutting edge features, we introduced a “Not implemented” tag next to the “Used it” option.

One disadvantage of the mini feature UI is that due to the way context chips work, it is not possible to select sentiment for features you have not used: once you click on a chip, it also selects the feature, as if you had clicked on its label. I guess it could be possible to click on a chip and then uncheck the feature, but that would be a very weird interaction.

Idea 5: Existing 5-point question template

At this point, the lead engineer dredged up a question template that had been used in other surveys to ask about the respondent’s experience with various types of tooling. Instead of separating experience and sentiment, it used a 5-point scale where each answer except the first answered both questions.

The existing 5-point question template.

The eng lead was sold: zero engineering effort! The Google PM was also sold: 100% response rate! (since it was not possible to avoid expressing sentiment for features you had heard or used).

I had serious reservations.

  • There are arguments for even numbered Likert scales (no neutral option), but these always involve scales of at least 4 points. If you force people to select between two states, positive or negative, you’re simply going to get garbage data. Neutral votes get pushed into positive votes, and the data around positive sentiment becomes useless.
  • These did not allow users to express sentiment for features they had not heard of, despite these questions often including enough info for users to know whether they were interested.
  • I was worried that increasing the number of upfront answers to 5 would increase cognitive load too much — and even scrolling distance, by 66%!

A UX researcher we were working with even did a heuristic evaluation that somewhat favored the 5-point template mainly on the basis of being a more familiar UI. The odds seemed stacked against context chips, but the upcoming usability testing could still tip the scales in their favor.

Usability Testing to the Rescue!

Despite the lead engineer being unconvinced about the merits of context chips and being adamant that even adapting my fully functional prototype was too much work, since the prototype existed, we decided to user test it against the 5-point question and see how it compared.

We ran a within-subjects usability study with 6 participants (no, they are not too few) recruited via social media. Half of the survey used the 5-point template, the other half context chips. The order of the conditions was randomized to avoid order effects.

In addition to their actual experience, we also collected subjective feedback at the end of the survey, showing them a screenshot of each answering UI and asking how each felt.

What worked well: Context Chips

I have run many usability studies in the last ten years, and I have never seen results as resounding as this one. So much that we unanimously agreed to switch to context chips after the 5th participant, because the scales were so tipped in favor of context chips that nothing that happened in the last session could have tipped them the other way.

The lead engineer observed some of the sessions, and this was instrumental in changing his mind. This was not a coincidence: when engineering is unconvinced that a certain UI is worth the implementation complexity, it can be a good strategy to have them observe usability testing sessions. Not only does it help prove the value to them, it also builds long-term user empathy, which makes future consensus easier. Given the unfortunate lack of HCI prioritization in Computer Science curricula, this may even be their first exposure to usability testing.

All of my concerns about the 5-point template were brought up by participants on their own accord, repeatedly:

  • All participants really liked being able to express sentiment, and were vocal about their frustration when they could not express it.
  • All but one participant (4/5) complained about being forced into selecting a sentiment when they had no opinion.
  • Some participants even mentioned that the 5-point template felt overwhelming.

Furthermore, none of the concerns about context chips were validated:

  • No-one found the chips appearing on hover distracting or felt “ambushed”.
  • No-one struggled to understand how to use them.
  • Everyone discovered the 1-click interaction pretty fast (typically within the first 2-3 questions). But interestingly, they still chose to use it as a two-step process for some of the questions, presumably to reduce cognitive load for difficult to answer questions by breaking down the decision into two smaller ones. The fact that this UI allowed users to make their own efficiency vs cognitive load tradeoffs was an advantage I had not even considered when designing it!
  • Response rate was generally high — when people did not select sentiment, it was because they genuinely had no opinion, not because they couldn’t be bothered.

What worked okay: Mini-feature Questions

Mini-feature questions did successfully help cut down response time per feature by 75%, though this came at a cost: Once more, we saw that participants really wanted to express sentiment, and were frustrated when they couldn’t, which was the case for features they had not used. Regardless, we agreed that the tradeoff was worth it for the low-priority questions we were planning to use mini-features for.

What did not work: Context Chips on Mobile

A blind spot in our testing was that we did not test the UI on mobile. Usability tests were conducted remotely via video call, so it was a lot easier to get participants to use their regular computers. Additionally, stats for previous surveys showed that mobile use was a much smaller percentage in these surveys than for the web in general (~25%), so we did not prioritize it.

This was a mistake in itself: using current usage stats to inform prioritization may seem like a great idea, but it can be prone to reverse causality bias. Meaning, are people not using these surveys on mobile very much because they genuinely don’t need to, or because the experience on mobile is subpar? We often see this with accessibility too: people claim that it doesn’t matter because they don’t have users with disabilities, but often they don’t have users with disabilities because their site is not accessible!

But even if 75% of users genuinely preferred to take these surveys on desktop (which is plausible, since they are long and people often do them in increments), we should at least have done a few sessions on mobile — 25% is not negligible!

Once responses started coming in, we realized that participants had trouble understanding what the up and down arrows meant, since on mobile these are shown without labels until selected. This would have been an easy fix had it had been caught early, e.g. thumbs up/down icons could have been used instead. This was not a huge issue, as their purpose becomes clear when selected, but it definitely adds some friction.

Aftermath: Context Chips in the Wild

In our usability testing, we had seen a high response rate for sentiment (% of question respondents who selected sentiment), but that is no guarantee things will play out that way post-launch as well. When participants know they are being watched they are always more willing to engage and pay a lot more attention, no matter how much you emphasize that they should act naturally when briefing them. That’s not their failing; it’s simply human nature.

Indeed, sentiment response rates in the real-world were lower than those observed in the usability study, but still high — ranging from 24% to 59% and averaging 38% (with the same median) per question, meaning that out of every ten participants that answered each question, approximately four also provided a sentiment. This was more than enough to draw conclusions. In fact, context chips were deemed such a success they were later adopted by all other State Of surveys, even at the cost of continuity with previous years.

Against expectations, participants were just as likely to express sentiment for features they had never heard of, and in fact marginally more likely than for features they had simply heard of. In general response rates were pretty uniform across all experiences:

Experience Sentiment response rate (average) Sentiment response rate (median)
Never heard of it 37.3% 37.4%
Heard of it 37.3% 36.9%
Used it 39.0% 40.1%
Overall 37.6% 37.9%

Sentiment response rates overall and by experience (per question).

As we had observed in the user study as well, participants were far more likely to express positive rather than negative sentiment (possibly a case of acquiescence bias). Here are some interesting stats:

  • The feature with the most negative sentiment overall across all experiences (<model>) still only had 10% of respondents expressing negative sentiment for it, and still had 2.4x more positive sentiment than negative (24.7% vs 10.4%)!
  • In contrast, the feature with the most positive sentiment (<datalist>) got a whopping 55% of respondents expressing positive sentiment (and only 4% negative).
  • In fact, even the feature with the least positive sentiment (Imperative Slot Assignment 🤔) still had way more positive sentiment (17.24%) than <model> had negative sentiment (10%)!
  • If we look at the ratio of positive over negative sentiment, it ranged from 64x (!) more positive than negative sentiment (45% vs 0.7% for landmark elements) to a mere 2.4x times more positive sentiment (24.7% vs 10.4% for <model>), and was 11x on average (8x median).

The analysis presented in this section includes data from 20K respondents, which was most of the whole dataset (around 90%) but not all, as it was done before the survey closed.

Results Visualization

Presenting all this data was another challenge. When you have two variables, ideally you want to be able to group results by either. E.g. you may be more interested in the total negative sentiment for a feature, or how many people had used it, and the results visualization should support both. How do we design a results display that facilitates this? Thankfully the visualizations for State Of surveys were already very interactive so interactivity was not out of the question.

I was no longer involved by then but consulted in a volunteer capacity. My main advice was to use proximity for clear visual grouping, and to use a consistent visual association for bars that represented the same bit of data, both of which they followed. This was the rendering they settled on for the results:

Interactive bar chart presenting two variables at once.

I think in terms of functionality this works really well. The visual design could be improved to communicate IA better and appear less busy at first glance, but given there is no dedicated designer in the team, I think they did a fantastic job.

Generalizability

While this UI was originally designed to collect sentiment about the selected option in a multiple choice question, I think it could be generalized to improving UX for other types of two variable questions. Generally, it can be a good fit when we have questions that collect data across two variables and:

  1. The second variable is optional and lower priority than the first
  2. The first variable is exclusive (single) choice, i.e. not checkbox questions.

The core benefit of this approach is the reduction in cognitive load. It is well established that matrix questions are more overwhelming. This design allows questions to initially appear like a simple multiple choice question, and only reveal the UI for the second variable upon interaction. Additionally, while matrix questions force participants to decide on both variables at once, this design allows them to make their own tradeoff of cognitive load vs efficiency, treating the UI as single step or two step as they see fit.

Another benefit of this design is that it allows for option labels to be context-dependent for the second variable, whereas a matrix limits you to a single column header. In the sentiment case, the labels varied depending on whether the feature had been used (“Positive experience” / “Negative experience”) or not (“Interested” / “Not interested”).

The more such questions a survey has, the bigger the benefits — if it’s only about a couple questions, it may not be worth the implementation complexity, though I’m hoping that survey software may eventually provide this out of the box so that this is no longer a tradeoff.

That said, matrix questions do have their benefits, when used appropriately, i.e. when the two requirements listed above are not met.

Matrix questions have an big edge when users need to make a single selection per row, especially when this may be the same answer for multiple rows, which means they can just tick down a whole column. Context chips do not allow users to build this positional association, as they are not aligned vertically. THey are placed right after the answer text, and thus their horizontal position varies per answer. To mitigate this, it can be useful to color-code them and maintain the same color coding consistently throughout the survey so that participants can build a visual association 4.

Context chips also enforce a clear prioritization across the two variables: the question is presented as a multiple choice question across the first variable, with the chips allowing the respondent to provide optional additional context across a second variable. Matrix questions allow presenting the two variables with the same visual weight, which could be desirable in certain cases. For example, there are cases when we don’t want to allow the respondent to provide an answer to the first variable without also providing an answer to the second.

Lessons Learned

In addition to any generalizable knowledge around survey design, I think this is also an interesting product management case study, and teaches us several lessons.

Never skimp on articulating the north star UI

Start any product design task by ignoring ephemeral constraints (e.g. engineering resources) and first reach consensus on what the optimal UI is, before you start applying constraints. Yes, you read that right. I want to write a whole post about the importance of north star UIs, because this is one of many cases over the course of my career where tight implementation constraints were magically lifted, either due to a change of mind, a change in the environment, or simply someone’s brilliant idea. Without consensus on what the north star UI is (or even a clear idea about it) you then have to go back to the drawing board when this happens.

User testing is also a consensus-building tool

You probably already know that usability testing is a great tool for improving user experience, but there is a second, more strategic hidden utility to it: consensus building.

I’ve been in way, way too many teams where UI decisions were made by hypothesizing about user behavior, which could not only be missing the mark, but also there is no way forwards for disagreements. What do you do, hypothesize harder? When there is user testing data, it is much harder to argue against it.

This is especially useful in convincing engineering that a certain UI is worth the implementation complexity, and having engineers observe usability testing sessions can be an educational experience for many.

Heuristic evaluations are not a substitute for usability testing

There are many things to like about heuristic evaluations and design reviews. They can be done by a usability expert alone and can uncover numerous issues that would have taken multiple rounds of usability testing, especially if they are also a domain expert. Fixing the low hanging fruit issues means user testing time can be spent more efficiently, uncovering less obvious problems. That are are also certain types of issues that can only be uncovered by a heuristic evaluation, such as _“death by a thousand paper cuts” type issues: small issues that are not a big deal on their own and are too small to observe in a user study, but add up to more friction.

However, a big downside of these is that they are inherently prone to bias. They can be excellent for finding problems that may have been overlooked and are often obvious once pointed out. However (unless the number of evaluators is large), they are not a good way to decide between alternatives.


  1. Unlike Devographics, surveys are not FA’s core business, so the Impact/Effort tradeoff simply wasn’t there for a custom UI, at least at this point in time. I ended up going with Tally, mainly due to the flexibility of its conditional logic and its support for code injection (which among other things, allowed me to use FA icons — a whopping 120 different ones!). ↩︎

  2. Meaning out of the people who responded to that question about their experience with a feature, only 0.9% left a comment. ↩︎

  3. A radio group with all buttons off cannot be returned to that state by user interaction. ↩︎

  4. The ~9% of people with atypical color vision won’t benefit, but that’s okay in this case, as color is used to add an extra cue, and not an essential part of the interface. ↩︎

  •  

Web Components are not Framework Components — and That’s Okay

Disclaimer: This post expresses my opinions, which do not necessarily reflect consensus by the whole Web Components community.

A blog post by Ryan Carniato titled “Web Components Are Not the Future” has recently stirred a lot of controversy. A few other JS framework authors pitched in, expressing frustration and disillusionment around Web Components. Some Web Components folks wrote rebuttals, while others repeatedly tried to get to the bottom of the issues, so they could be addressed in the future.

When you are on the receiving end of such an onslaught, the initial reaction is to feel threatened and become defensive. However, these kinds of posts can often end up shaking things up and pushing a technology forwards in the end. I have some personal experience: after I published my 2020 post titled “The failed promise of Web Components” which also made the rounds at the time, I was approached by a bunch of folks (Justin Fagnani, Gray Norton, Kevin Schaaf) about teaming up to fix the issues I described. The result of these brainstorming sessions was the Web Components CG which now has a life of its own and has become a vibrant Web Components community that has helped move several specs of strategic importance forwards.

As someone who deeply cares about Web Components, my initial response was also to push back. I was reminded of how many times I have seen this pattern before. It is common for new web platform features to face pushback and resistance for many years; we tend to compare them to current userland practices, and their ergonomics often fare poorly at the start. Especially when there is no immediately apparent 80/20 solution, making things possible tends to precede making them easy.

Web platform features operate under a whole different set of requirements and constraints:

  • They need to last decades, not just until the next major release.
  • They need to not only cater to the current version of the web platform, but anticipate its future evolution and be compatible with it.
  • They need to be backwards compatible with the web as it was 20 years ago.
  • They need to be compatible with a slew of accessibility and internationalization needs that userland libraries often ignore at first.
  • They are developed in a distributed way, by people across many different organizations, with different needs and priorities.

Usually, the result is more robust, but takes a lot longer. That’s why I’ve often said that web standards are “product work on hard mode” — they include most components of regular product work (collecting user needs, designing ergonomic solutions, balancing impact over effort, leading without authority, etc.), but with the added constraints of a distributed, long-term, and compatibility-focused development process that would make most PMs pull their hair out in frustration and run screaming.

I’m old enough to remember this pattern playing out with CSS itself: huge pushback when it was introduced in the mid 90s. It was clunky for layout and had terrible browser support — “why fix something that wasn’t broken?” folks cried. Embarrassingly, I was one of the last holdouts: I liked CSS for styling, but was among the last to switch to floats for layout — tables were just so much more ergonomic! The majority resistance lasted until the mid '00s when it went from “this will never work” to “this was clearly the solution all along” almost overnight. And the rest, as they say, is history. 🙂

But the more I thought about this, the more I realized that — as often happens in these kinds of heated debates — the truth lies somewhere in the middle. Having used both several frameworks, and several web components, and having authored both web components (most of them experimental and unreleased) and even one framework over the course of my PhD, both sides do have some valid points.

Frankly, if framework authors were sold the idea that web components would be a compile target for their frameworks, and then got today’s WC APIs, I understand their frustration. Worse yet, if every time they tried to explain that this sucks as a compile target they were told “no you just don’t get it”, heck I’d feel gaslit too! Web Components are still far from being a good compile target for all framework components, but that is not a prerequisite for them being useful. They simply solve different problems.

Let me explain.

Venn diagram illustrating general vs project-specific components

Not all component use cases are the same.

I think the crux of this debate is that the community has mixed two very different categories of use cases, largely because frameworks do not differentiate between them; “component” has become the hammer with which to hammer every nail. Conceptually, there are two core categories of components:

  1. Generalizable elements that extend what HTML can do and can be used in the same way as native HTML elements across a wide range of diverse projects. Things like tabs, rating widgets, comboboxes, dialogs, menus, charts, etc. Another way to think about these is “if resources were infinite, elements that would make sense as native HTML elements”.
  2. Reactive templating: UI modules that have project-specific purposes and are not required to make sense in a different project. For example, a font foundry may have a component to demo a font family with child components to demo a font family style, but the uses of such components outside the very niche font foundry use case are very limited.

Of course, it’s a spectrum; few things in life fit neatly in completely distinct categories. For example an <html-demo> component may be somewhat niche, but would be useful across any site that wants to demo HTML snippets (e.g. a web components library, a documentation site around web technologies, a book teaching how to implement UI patterns, etc.). But the fact that it’s a spectrum does not mean the distinction does not exist.

WCs primarily benefit the use case of generalizable elements that extend HTML, and are still painful to use for reactive templating. Fundamentally, it’s about the ratio of potential consumers to authors.

The huge benefit of Web Components is interoperability: you write it once, it works forever, and you can use it with any framework (or none at all). It makes no sense to fragment efforts to reimplement e.g. tabs or a rating widget separately for each framework-specific silo, it is simply duplicated busywork.

As a personal anecdote, a few weeks ago I found this amazing JSON viewer component, but I couldn’t use it because I don’t use React (I prefer Vue and Svelte). To this day, I have not found anything comparable for Vue, Svelte, or vanilla JS. This kind of fragmentation is sadly an everyday occurrence for most devs.

But when it comes to project-specific components, the importance of interop decreases: you typically pick a framework and stick to it across your entire project. Reusing project-specific components across different projects is not a major need, so the value proposition of interop is smaller.

Additionally, the ergonomics of consuming vs authoring web components are vastly different. Consuming WCs is already pretty smooth, and the APIs are largely there to demystify most of the magic of built-in elements and expose it to web components (with a few small gaps being actively plugged as we speak). However, authoring web components is a whole different story. Especially without a library like Lit, authoring WCs is still painful, tedious, and riddled with footguns. For generalizable elements, this is an acceptable tradeoff, as their potential consumers are a much larger group than their authors. As an extreme example of this, nobody complains about the ergonomics of implementing native elements in browsers using C++ or Rust. But when using components as a templating mechanism, authoring ergonomics are crucial, since the overlap between consumers and authors is nearly 100%.

This was the motivation behind this Twitter poll I posted a while back. I asked if people mostly consumed web components, used WCs that others have made, or both. Note that many people who use WCs are not aware of it, so the motivation was not to gauge adoption, but to see if the community has caught on to this distinction between use cases. The fact that > 80% of people who knowingly use web components are also web components authors is indicative of the problem. WCs are meant to empower folks to do more, not to be consumed by expert web developers who can also write them. Until this number becomes a lot smaller, Web Components will not have reached their full potential. This was one of the reasons I joined the Web Awesome project; I think that is the right direction for WCs: encapsulating complexity into beautiful, generalizable, customizable elements that give people superpowers by extending what HTML can do: they can be used by developers to author gorgeous UIs, designers to do more without having to learn JS, or even hobbyists that struggle with both (since HTML is the most approachable web platform language).

So IMO making it about frameworks vs web components is a false dichotomy. Frameworks already use native HTML elements in their components. Web components extend what native elements can do, and thus make crafting project-specific components easier across all frameworks (as well as no frameworks). I wonder if this narrative could resonate across both sides and reconcile them. Basically “yes, we may still need frameworks for nontrivial apps, but web components make their job easier” rather than pitting them against each other in a pointless comparison where everyone loses.

We will certainly eventually get to the point where web components are more ergonomic to author, but we first need to get the low-level foundations right. At this point the focus is still on making things possible rather than making them easy. The last remaining pieces of the puzzle are things like Reference Target for cross-root ARIA or ElementInternals.type to allow custom elements to become popover targets or submit buttons, both of which saw a lot of progress at W3C TPAC last week.

After that, perhaps eventually web components will even become viable for reactive templating use cases; things like the open-stylable shadow roots proposal, declarative elements, or DOM Parts are some early beginnings in that direction, and declarative shadow DOM paved the way for SSR (among other things). Then, and only then, they may make sense as a compile target for frameworks. However, that is quite far off. And even if we get there, frameworks would still be useful for complex use cases, as they do a lot more than let you use and define components. Components are not even the best reuse mechanism for every project-specific use case — e.g. for list rendering, components are overkill compared to something like v-for. And by then frameworks will be doing even more. It is by definition that frameworks are always a step ahead of the web platform, not a failing of the web platform. As Cory said, “Frameworks are a testbed for new ideas that may or may not work out.”.

The bottom line is, web components reduce the number of use cases where we need to reach for a framework, but complex large applications will likely still benefit from one. So how about we conclude that frameworks are useful, web components are also useful, stop fighting and go make awesome sh!t using whatever tools we find most productive?

Thanks to Michael Warren, Nolan Lawson, Cory LaViska, Steve Orvell, and others for their feedback on earlier drafts of this post.

  •  

Making the Web more Awesome — for everyone

Folks, I have some exciting news to share. 🤩

Today I start a new chapter in my career. After a decade at MIT, teaching and doing research at the intersection of usability and programming language design, I wrapped up my PhD two weeks ago (yes, I’m a Dr now! And damn right I will — once it actually sinks in) and today I start my new role as Product Lead at Font Awesome.

Font Awesome + Lea Verou

I will be evaluating user needs and improving product design and usability across all company products, with an emphasis on Web Awesome, the product we are launching early next year to revolutionize how Web UIs are built by using web components and CSS in ways you’ve never seen before. Beyond improving the products themselves (all of which include extensive free & open source versions), part of my role will utilize my web standards experience to collect web platform pain points from across the company and translating them to new and existing web standards proposals.

Yes, I know, it’s a match made in heaven. 😍 There is even a small chance I may have been the first to create an icon font for use in a web UI via @font-face, which would make it even more wonderfully poetic that I’m joining the company that has become synonymous with icon fonts on the Web.

However, it was not my MIT PhD that led me to this role, but an email from Dave Gandy (creator & CEO of Font Awesome) about Color.js, that turned into hours of chats, and eventually a job offer for a role I could not refuse, one that was literally molded around my skills and interests.

The role is not the only reason I’m excited to join Font Awesome, though. The company itself is a breath of fresh air: open source friendly (as Dave says, “literally the only reason we have Pro versions is that we need to sustain this somehow” 😅), already profitable (= no scrambling to meet VC demands by cramming AI features nobody wants into our products), fully remote, huge emphasis on work-life balance, and an interview process that did not feel like an interview — or even a process. In fact, they did not even want to look at my resume (despite my efforts 🤣). It is telling that in their 10 years of existence, not a single person has left the company, and they have never had to let anyone go. Moreover, it bridges the best of both worlds: despite having existed for a decade, branching out to new products1 and markets gives it a startup-like energy and excitement.

I had been extremely selective in the job opportunities I pursued, so it took a while to find the perfect role. Having ADHD (diagnosed only last year — I want to write a blog post about that too at some point), I knew it was crucial to find a job I could be passionate about: ADHD folks are unstoppable machines in jobs they love (I have literally built my career by directing my hyperfocus to things that are actually productive), but struggle way more than neurotypicals in jobs they hate. It took a while, but when I started talking with Dave, I knew Font Awesome was it.

I’m still reeling from the mad rush of spending the past couple of months averaging 100-hour weeks to wrap up my PhD before starting, but I couldn’t be more excited about this new chapter.

I’m hoping to write a series of blog posts in the coming weeks about about my journey to this point. Things like:

  • How I decided that academia was not for me — but persisted to the finish line anyway because I’m stubborn AF 😅
  • How I realized that product work is my real calling, not software engineering per se (as much as I love both)
  • How I used web technologies instead of LaTeX to write my PhD thesis (and print it to PDF for submission), with 11ty plus several open source plugins, many of which I wrote, an ecosystem I hope to one day free more people from the tyranny of LaTeX (which was amazing in the 70s, but its ergonomics are now showing their age).

But for now, I just wanted to share the news, and go off to make the web more awesome — for everyone. 🚀


  1. My excitement grew even stronger when a week before my start date, I learned that 11ty (and its creator, Zach Leatherman) had also joined Font Awesome — I think at this point every tool I use regularly is officially Awesome 😅. Yes, this site is built on 11ty as well. And even my PhD thesis! ↩︎

  •  

Forget “show, don’t tell”. Engage, don’t show!

A few days ago, I gave a very well received talk about API design at dotJS titled “API Design is UI Design” 1. One of the points I made was that good UIs (and thus, good APIs) have a smooth UI complexity to Use case complexity curve. This means that incremental user effort results in incremental value; at no point going just a little bit further requires a disproportionately big chunk of upfront work 2.

Observing my daughter’s second ever piano lesson today made me realize how this principle extends to education and most other kinds of knowledge transfer (writing, presentations, etc.). Her (generally wonderful) teacher spent 40 minutes teaching her notation, longer and shorter notes, practicing drawing clefs, etc. Despite his playful demeanor and her general interest in the subject, she was clearly distracted by the end of it.

It’s easy to dismiss this as a 5 year old’s short attention span, but I could tell what was going on: she did not understand why these were useful, nor how they connect to her end goal, which is to play music. To her, notation was just an assortment of arbitrary symbols and lines, some of which she got to draw. Note lengths were just isolated sounds with no connection to actual music. Once I connected note lengths to songs she has sung with me and suggested they try something more hands on, her focus returned instantly.

I mentioned to her teacher that kids that age struggle to learn theory for that long without practicing it. He agreed, and said that many kids are motivated to get through the theory because they’ve heard their teacher play nice music and want to get there too. The thing is… sure, that’s motivating. But as far as motivations go, it’s pretty weak.

Humans are animals, and animals don’t play the long game, or they would die. We are programmed to optimize for quick, easy dopamine hits. The farther into the future the reward, the more discipline it takes to stay motivated and put effort towards it. This applies to all humans, but even more to kids and ADHD folks 3. That’s why it’s so hard for teenagers to study so they can improve their career opportunities and why you struggle to eat well and exercise so you can be healthy and fit.

So how does this apply to knowledge transfer? It highlights how essential it is for students to a) understand why what they are learning is useful and b) put it in practice ASAP. You can’t retain information that is not connected to an obvious purpose 4 — your brain will treat it as noise and discard it.

The thing is, the more expert you are on a topic, the harder these are to do when conveying knowledge to others. I get it. I’ve done it too. First, the purpose of concepts feels obvious to you, so it’s easy to forget to articulate it. You overestimate the student’s interest in the minutiae of your field of expertise. Worse yet, so many concepts feel essential that you are convinced nothing is possible without learning them (or even if it is, it’s just not The Right Way™). Looking back on some of my earlier CSS lectures, I’ve definitely been guilty of this.

As educators, it’s very tempting to say “they can’t possibly practice before understanding X, Y, Z, they must learn it properly”. Except …they won’t. At best they will skim over it until it’s time to practice, which is when the actual learning happens. At worst, they will give up. You will get much better retention if you frequently get them to see the value of their incremental imperfect knowledge than by expecting a big upfront attention investment before they can reap the rewards.

There is another reason to avoid long chunks of upfront theory: humans are goal oriented. When we have a goal, we are far more motivated to absorb information that helps us towards that goal. The value of the new information is clear, we are practicing it immediately, and it is already connected to other things we know.

This means that explaining things in context as they become relevant is infinitely better for retention and comprehension than explaining them upfront. When knowledge is a solution to a problem the student is already facing, its purpose is clear, and it has already been filtered by relevance. Furthermore, learning it provides immediate value and instant gratification: it explains what they are experiencing or helps them achieve an immediate goal.

Even if you don’t teach, this still applies to you. I would go as far as to say it applies to every kind of knowledge transfer: teaching, writing documentation, giving talks, even just explaining a tricky concept to your colleague over lunch break. Literally any activity that involves interfacing with other humans benefits from empathy and understanding of human nature and its limitations.

To sum up:

  1. Always explain why something is useful. Yes, even when it’s obvious to you.
  2. Minimize the amount of knowledge you convey before the next opportunity to practice it. For non-interactive forms of knowledge transfer (e.g. a book), this may mean showing an example, whereas for interactive ones it could mean giving the student a small exercise or task. Even in non-interactive forms, you can ask questions — the receiver will still pause and think what they would answer even if you are not there to hear it.
  3. Prefer explaining in context rather than explaining upfront.

“Show, don’t tell”? Nah. More like “Engage, don’t show”.

(In the interest of time, I’m posting this without citations to avoid going down the rabbit hole of trying to find the best source for each claim, especially since I believe they’re pretty uncontroversial in the psychology / cognitive science literature. That said, I’d love to add references if you have good ones!)


  1. The video is now available on YouTube: API Design is UI Design ↩︎

  2. When it does, this is called a usability cliff. ↩︎

  3. I often say that optimizing UX for people with ADHD actually creates delightful experiences even for those with neurotypical attention spans. Just because you could focus your attention on something you don’t find interesting doesn’t mean you enjoy it. Yet another case of accessibility helping everyone! ↩︎

  4. I mean, you can memorize anything if you try hard enough, but by optimizing teaching we can keep rote memorization down to the bare minimum. ↩︎

  •  

Inline conditionals in CSS, now?

The CSS WG resolved to add if() to CSS, but that won’t be in browsers for a while. What are our options in the meantime?

A couple days ago, I posted about the recent CSS WG resolution to add an if() function to CSS. Great as it may be, this is still a long way off, two years if everything goes super smoothly, more if not. So what can you do when you need conditionals right now?

You may be pleased to find that you’re not completely out of luck. There is a series of brilliant, horrible hacks that enable you to expose the kinds of higher level custom properties that conditionals typically enable.

Using hacks in production?!

The instinctive reaction many developers have when seeing hacks like these is “Nice hack, but can’t possibly ever use this in production”. This sounds reasonable on the surface (keeping the codebase maintainable is a worthy goal!) but when examined deeply, it reflects the wrong order of priorities, prioritizing developer convenience over user convenience.

The TAG maintains a Web Platform Design Principles document 1 that everyone designing APIs for the web platform is supposed to read and follow. I’m a strong believer in having published Design Principles, for any product2. They help stay on track, and remember what the big picture vision is, which is otherwise easy to lose sight of in the day to day minutiae. One of the core principles in the document is the Priority of Constituencies. The core of it is:

User needs come before the needs of web page authors, which come before the needs of user agent implementors, which come before the needs of specification writers, which come before theoretical purity.

Obviously in most projects there are far fewer stakeholders than for the whole web platform, but the spirit of the principle still applies: the higher the abstraction, the higher priority the user needs. Or, in other words, consumers above producers.

For a more relatable example, in a web app using a framework like e.g. Vue and several Vue components, the user needs of website users come before the needs of the web app developers, which come before the needs of the developers of its Vue components, which come before the needs of the Vue framework developers (sorry Evan :).

The TAG did not invent this principle; it is well known in UX and Product circles with a number of different wordings:

  • “Put the pain on those who can bear it”
  • Prefer internal complexity over external complexity

Why is that? Several reasons:

  • It is far easier to change the implementation than to change the user-facing API, so it’s worth making sacrifices to keep it clean from the get go.
  • Most products have way more users than developers, so this minimizes collective pain.
  • Internal complexity can be managed far more easily, with tooling or even good comments.
  • Managing complexity internally localizes it and contains it better.
  • Once the underlying platform improves, only one codebase needs to be changed to reap the benefits.

The corollary is that if hacks allow you to expose a nicer API to component users, it may be worth the increase in internal complexity (to a degree). Just make sure that part of the code is well commented, and keep track of it so you can return to it once the platform has evolved to not require a hack anymore.

Like all principles, this isn’t absolute. A small gain in user convenience is not a good tradeoff when it requires tremendous implementation complexity. But it’s a good north star to follow.

As to whether custom properties are a better option to control styling than e.g. attributes, I listed several arguments for that in my previous article. Although, there are also cases where using custom properties is not a good idea…

When is it not a good idea to do this?

In a nutshell, when the abstraction is likely to leak. Ugliness is only acceptable if it’s encapsulated and not exposed to component users. If there is a high chance they may come into contact with it, it might be a better idea to simply use attributes and call it a day.

A series of callouts with --variant declarations next to them

Example callouts with three variants.

In many of the examples below, I use variants as the canonical example of a custom property that a component may want to expose. However, if component consumers may need to customize each variant, it may be better to use attributes so they can just use e.g. [variant="success"] instead of having to understand whatever crazy hack was used to expose a --variant custom property. And even from a philosophical purity perspective, variants are on the brink of presentational vs semantic anyway.

The current state of the art

There is a host of hacks and workarounds that people have come up with to make up for the lack of inline conditionals in CSS, with the first ones dating back to as early as 2015.

1. Binary Linear Interpolation

This was first documented by Roma Komarov in 2016, and has since been used in a number of creative ways. The gist of this method is to use essentially the linear interpolation formula for mapping [0,1] to [a,b]:

p×a+(1−p)×b

However, instead of using this to map a range to another range, we use it to map two points to two other points, basically the two extremes of both ranges: p=0 and p=1 to select a and b respectively.

This was Roma’s original example:

:root {
		--is-big: 0;
}

.is-big {
		--is-big: 1;
}

.block {
		padding: calc(
				25px * var(--is-big) +
				10px * (1 - var(--is-big))
		);
		border-width: calc(
				3px * var(--is-big) +
				1px * (1 - var(--is-big))
		);
}

He even expands it to multiple conditions by multiplying the interpolation factors. E.g. this code snippet to map 0 to 100px, 1 to 20px, and 2 to 3px:

.block {
		padding: calc(
				100px * (1 - var(--foo)) * (2 - var(--foo)) * 0.5 +
				20px  * var(--foo) * (2 - var(--foo)) +
				3px   * var(--foo) * (1 - var(--foo)) * -0.5
		);
}

Which these days could be rewritten as this, which also makes the boolean logic at play clearer:

.block {
		--if-not-0: min(max(0 - var(--foo), var(--foo) - 0), 1);
		--if-not-1: min(max(1 - var(--foo), var(--foo) - 1), 1);
		--if-not-2: min(max(2 - var(--foo), var(--foo) - 2), 1);

		--if-0: var(--if-not-1) * var(--if-not-2);
		--if-1: var(--if-not-0) * var(--if-not-2);
		--if-2: var(--if-not-0) * var(--if-not-1);

		padding: calc(
				100px * var(--if-0) +
				20px  * var(--if-1) +
				3px   * var(--if-2)
		);
}

Back then, min() and max() were not available, so he had to divide each factor by an obscure constant to make it equal to 1 when it was not 0. Once abs() ships this will be even simpler (the inner max() is basically getting the absolute value of N - var(--foo))

Ana Tudor also wrote about this in 2018, in this very visual article: DRY Switching with CSS Variables. Pretty sure she was also using boolean algebra on these too (multiplication = AND, addition = OR), but I couldn’t find the exact post.

2. Toggles (Space Toggle, Cyclic Toggles)

This was independently discovered by Ana Tudor (c. 2017), Jane Ori in April 2020 (who gave it the name “Space Toggle”), David Khoursid (aka David K Piano) in June 2020 (he called it prop-and-lock), and yours truly in Oct 2020 (I called it the --var: ; hack, arguably the worst name of the three 😅).

The core idea is that var(--foo, fallback) is actually a very limited form of conditional: if --foo is initial (or IACVT), it falls back to fallback, otherwise it’s var(--foo). Furthermore, we can set custom properties (or their fallbacks) to empty values to get them to be ignored when used as part of a property value. It looks like this:

:root {
	--if-success: ;
	--if-warning: ;
}
.success {
	--if-success: initial;
}

.warning {
	--if-warning: initial;
}

.callout {
	background:
		var(--if-success, var(--color-success-90))
		var(--if-warning, var(--color-warning-90));
}

One of the downsides of this version is that it only supports two states per variable. Note how we needed two variables for the two states. Another downside is that there is no way to specify a fallback if none of the relevant variables are set. In the example above, if neither --if-success nor --if-warning are set, the background declaration will be empty, and thus become IACVT which will make it transparent.

Cyclic Toggles

In 2023, Roma Komarov expanded the technique into what he called “Cyclic Dependency Space Toggles” which addresses both limitations: it supports any number of states, and allows for a default value. The core idea is that variables do not only become initial when they are not set, or are explicitly set to initial, but also when cycles are encountered.

Roma’s technique depends on this behavior by producing cycles on all but one of the variables used for the values. It looks like this:

.info {
	--variant: var(--variant-default);

	--variant-default: var(--variant,);
	--variant-success: var(--variant,);
	--variant-warning: var(--variant,);
	--variant-error:   var(--variant,);

	background:
		var(--variant-default, lavender)
		var(--variant-success, palegreen)
		var(--variant-warning, khaki)
		var(--variant-error,   lightpink);
}

And is used like this:

.my-warning {
	--variant: var(--variant-warning);
}

A downside of this method is that since the values behind the --variant-success, --variant-warning, etc variables are specific to the --variant variable they need to be namespaced to avoid clashes.

Layered Toggles

A big downside of most of these methods (except for the animation-based ones) is that you need to specify all values of the property in one place, and the declaration gets applied whether your custom property has a value or not, which makes it difficult to layer composable styles leading to some undesirable couplings.

Roma Komarov’s “Layered Toggles” method addresses this for some cases by allowing us to decouple the different values by taking advantage of Cascade Layers. The core idea is that Cascade Layers include a revert-layer keyword that will cause the current layer to be ignored wrt the declaration it’s used on. Given that we can use unnamed layers, we can simply user a @layer {} rule for every block of properties we want to apply conditionally.

This approach does have some severe limitations which made it rather unpractical for my use cases. The biggest one is that anything in a layer has lower priority than any unlayered styles, which makes it prohibitive for many use cases. Also, this doesn’t really simplify cyclic toggles, you still need to set all values in one place. Still, worth a look as there are some use cases it can be helpful for.

3. Paused animations

The core idea behind this method is that paused animations (animation-play-state: paused) can still be advanced by setting animation-delay to a negative value. For example in an animation like animation: 100s foo, you can access the 50% mark by setting animation-delay: -50s. It’s trivial to transform raw numbers to <time> values, so this can be abstracted to plain numbers for the user-facing API.

Here is a simple example to illustrate how this works:

@keyframes color-mixin {
	0% { background: var(--color-neutral-90); border-color: var(--color-neutral-80); }
	25% { background: var(--color-success-90); border-color: var(--color-success-80); }
	50% { background: var(--color-warning-90); border-color: var(--color-warning-80); }
	75% { background: var(--color-danger-90); border-color: var(--color-danger-80); }
}

button {
	animation: foo 100s calc(var(--variant) * -100s / 4 ) infinite paused;
}

Used like:

.error button {
	--variant: 2;
}

This is merely to illustrate the core idea, having a --variant property that takes numbers is not a good API! Though the numbers could be aliased to variables, so that users would set --variant: var(--success).

This technique seems to have been first documented by me in 2015, during a talk about …pie charts (I would swear I showed it in an earlier talk but I cannot find it). I never bothered writing about it, but someone else did, 4 years later.

To ensure you don’t get slightly interpolated values due to precision issues, you could also slap a steps() in there:

button {
	animation: foo 100s calc(var(--variant) * -100s / 4 ) infinite paused steps(4);
}

This is especially useful when 100 divided by your number of values produces repeating decimals, e.g. 3 steps means your keyframes are at increments of 33.33333%.

A benefit of this method is that defining each state is done with regular declarations, not involving any weirdness, and that .

It does also have some obvious downsides:

  • Values restricted to numbers
  • Takes over the animation property, so you can’t use it for actual animations.

4. Type Grinding

So far all of these methods impose constraints on the API exposed by these custom properties: numbers by the linear interpolation method and weird values that have to be hidden behind variables for the space toggle and cyclic toggle methods.

In October 2022, Jane Ori was the first one to discover a method that actually allows us to support plain keywords, which is what the majority of these use cases needs. She called it “CSS-Only Type Grinding”.

Its core idea is if a custom property is registered (via either @property or CSS.registerProperty()), assigning values to it that are not valid for its syntax makes it IACVT (Invalid at computed value time) and it falls back to its initial (or inherited) value.

She takes advantage of that to progressively transform keywords to other keywords or numbers through a series of intermediate registered custom properties, each substituting one more value for another.

I was recently independently experimenting with a similar idea. It started from a use case of one of my components where I wanted to implement a --size property with two values: normal and large. Style queries could almost get me there, but I also needed to set flex-flow: column on the element itself when --size was large.

The end result takes N + 1 @property rules, where N is the number of distinct values you need to support. The first one is the rule defining the syntax of your actual property:

@property --size {
	syntax: "normal | large",
	initial-value: normal;
	inherits: true;
}

Then, you define N more rules, each progressively substituting one value for another:

@property --size-step-1 {
	syntax: "row | large";
	initial-value: row;
	inherits: false;
}

@property --size-step-end {
	syntax: "row | column";
	initial-value: column;
	inherits: false;
}

And at the component host you daisy chain them like this:

:host {
	--size-step-1: var(--size);
	--size-step-end: var(--size-step-1);
	flex-flow: var(--size-step-end);
}

And component consumers get a really nice API:

.my-component {
	--size: large;
}

You can see it in action in this codepen:

See the Pen Transform keywords to other keywords (2 keyword version) by Lea Verou (@leaverou) on CodePen.

You can use the same general idea to transform more keywords or to transform keywords into different sets of keywords for use in different properties.

We can also transform keywords to numbers, by replacing successive keywords with <integer> in the syntax, one at a time, with different initial values each time. Here is the --variant example using this method:

@property --variant {
	syntax: "none | success | warning | danger";
	initial-value: none;
	inherits: true;
}


@property --variant-step-1 {
	syntax: "none | <integer> | warning | danger";
	initial-value: 1;
	inherits: false;
}

@property --variant-step-2 {
	syntax: "none | <integer> | danger";
	initial-value: 2;
	inherits: false;
}

@property --variant-step-3 {
	syntax: "none | <integer>";
	initial-value: 3;
	inherits: false;
}

@property --variant-index {
	syntax: "<integer>";
	initial-value: 0;
	inherits: false;
}

.callout {
	--variant-step-1: var(--variant);
	--variant-step-2: var(--variant-step-1);
	--variant-step-3: var(--variant-step-2);
	--variant-index: var(--variant-step-3);

	/* Now use --variant-index to set other values */
}

Then, we can use techniques like linear range mapping to transform it to a length or a percentage (generator) or recursive color-mix() to use that number to select an appropriate color.

5. Variable animation name

In 2018, Roma Komarov discovered another method that allows plain keywords to be used as the custom property API, forgot about it, then rediscovered it in June 2023 😅. He still never wrote about it, so these codepens are the only documentation we have. It’s a variation of the previous method: instead of using a single @keyframes rule and switching between them via animation-delay, define several separate @keyframes rules, each named after the keyword we want to use:

@keyframes success {
	from, to {
		background-color: var(--color-success-90);
		border-color: var(--color-success-80);
	}
}
@keyframes warning {
	from, to {
		background-color: var(--color-warning-90);
		border-color: var(--color-warning-80);
	}
}
@keyframes danger {
	from, to {
		background-color: var(--color-danger-90);
		border-color: var(--color-danger-80);
	}
}

.callout {
	padding: 1em;
	margin: 1rem;
	border: 3px solid var(--color-neutral-80);
	background: var(--color-neutral-90);

	animation: var(--variant) 0s paused both;
}

Used like:

.warning {
	--variant: warning;
}

The obvious downsides of this method are:

  • Impractical to use outside of Shadow DOM due to the potential for name clashes.
  • Takes over the animation property, so you can’t use it for actual animations.

Improvements

Every one of these methods has limitations, some of which are inerent in its nature, but others can be improved upon. In this section I will discuss some improvements that me or others have thought of. I decided to include these in a separate section, since they affect more than one method.

Making animation-based approaches cascade better

A big downside with the animation-based approaches (3 and 5) is the place of animations in the cascade: properties applied via animation keyframes can only be overridden via other animations or !important.

One way to deal with that is to set custom properties in the animation keyframes, that you apply in regular rules. To use the example from Variable animation name:

@keyframes success {
	from, to {
		--background-color: var(--color-success-90);
		--border-color: var(--color-success-80);
	}
}
@keyframes warning {
	from, to {
		--background-color: var(--color-warning-90);
		--border-color: var(--color-warning-80);
	}
}
@keyframes danger {
	from, to {
		--background-color: var(--color-danger-90);
		--border-color: var(--color-danger-80);
	}
}

.callout {
	padding: 1em;
	margin: 1rem;
	border: 3px solid var(--border-color, var(--color-neutral-80));
	background-color: var(--background-color, var(--color-neutral-90));

	animation: var(--variant) 0s paused both;
}

Note that you can combine the two approaches (variable animation-name and paused animations) when you have two custom properties where each state of the first corresponds to N distinct states of the latter. For example, a --variant that sets colors, and a light/dark mode within each variant that sets different colors.

Making animation-based approaches compose better with author code

Another downside of the animation-based approaches is that they take over the animation property. If authors want to apply an animation to your component, suddenly a bunch of unrelated things stop working, which is not great user experience.

There isn’t that much to do here to prevent this experience, but you can at least offer a way out: instead of defining your animations directly on animation, define them on a custom property, e.g. --core-animations. Then, if authors want to apply their own animations, they just make sure to also include var(--core-animations) before or after.

Discrete color scales

Many of the approaches above are based on numerical values, which are then mapped to the value we actually want. For numbers or dimensions, this is easy. But what about colors?

I linked to Noah Liebman’s post above on recursive color-mix(), where he presents a rather complex method to select among a continuous color scale based on a 0-1 number.

However, if you don’t care about any intermediate colors and just want to select among a few discrete colors, the method can be a lot simpler. Simple enough to be specified inline.

Let me explain: Since color-mix() only takes two colors, we need to nest them to select among more than 2, no way around that. However, the percentages we calculate can be very simple: 100% when we want to select the first color and 0% otherwise. I plugged these numbers into my CSS range mapping tool (example) and noticed a pattern: If we want to output 100% when our variable (e.g. --variant-index) is N-1 and 0% when it’s N, we can use 100% * (N - var(--variant-index)).

We can use this on every step of the mixing:

background: color-mix(in oklab,
	var(--stone-2) calc(100% * (1 - var(--color-index, 0))), /* default color */
	color-mix(in oklab,
		var(--green-2) calc(100% * (2 - var(--color-index))),
		color-mix(in oklab,
			var(--yellow-2) calc(100% * (3 - var(--color-index))),
			var(--red-2)
		)
	)
);

But what happens when the resulting percentage is < 0% or > 100%? Generally, percentages outside [0%, 100%] make color-mix() invalid, which would indicate that we need to take care to keep our percentages within that range (via clamp() or max()). However, within math functions there is no parse-time range-checking, so values are simply clamped to the allowed range.

Here is a simple example that you can play with (codepen):

See the Pen Discrete color scales with simpler recursive color-mix() by Lea Verou (@leaverou) on CodePen.

And here is a more realistic one, using the Type Grinding method to transform keywords to numbers, and then using the above technique to select among 4 colors for backgrounds and borders (codepen).

Combining approaches

There are two components to each method: the input values it supports, i.e. your custom property API that you will expose, e.g. numbers, keywords, etc., and the output values it supports (<dimension>, keywords, etc.).

Even without doing anything, we can combine methods that support the same type of input values, e.g. Binary Linear Interpolation and Paused animations or Type Grinding and Variable animation names.

If we can transform the input values of one method to the input values of another, we can mix and match approaches to maximize flexibility. For example, we can use type grinding to transform keywords to numbers, and then use paused animations or binary linear interpolation to select among a number of quantitative values based on that number.

Keywords → Numbers
Type grinding
Numbers → Keywords
We can use paused animations to select among a number of keywords based on a number (which we transform to a negative animation-delay).
Space toggles → Numbers
Easy: --number: calc(0 var(--toggle, + 1))
Numbers → Space toggles
Once again, Roma Komarov has come up with a very cool trick: he conditionally applies an animation which interpolates two custom properties from initial to the empty value and vice versa — basically variable animation names but used on an internal value. Unfortunately a Firefox bug prevents it from working interoperably. He also tried a variant for space toggles but that has even worse compatibility, limited to Chrome only. I modified his idea a bit to use paused animations instead, and it looks like my attempt works on Firefox as well. 🎉

So, which one is better?

I’ve summarized the pros and cons of each method below:

Method Input values Output values Pros Cons

Binary Linear Interpolation

Numbers Quantitative
  • Lightweight
  • Requires no global rules
  • Limited output range

Toggles

var(--alias) (actual values are too weird to expose raw)

Any
  • Can be used in part of a value
  • Weird values that need to be aliased

Paused animations

Numbers Any
  • Normal, decoupled declarations
  • Takes over animation property
  • Cascade weirdness

Type Grinding

Keywords

Any value supported by the syntax descriptor

  • High flexibility for exposed API
  • Good encapsulation
  • Must insert CSS into light DOM
  • Tedious code (though can be automated with build tools)
  • No Firefox support (though that’s changing)

Variable animation name

Keywords Any
  • Normal, decoupled declarations
  • Impractical outside of Shadow DOM due to name clashes
  • Takes over animation property
  • Cascade weirdness

The most important consideration is the API we want to expose to component users. After all, exposing a nicer API is the whole point of this, right?

If your custom property makes sense as a number without degrading usability (e.g. --size may make sense as a number, but small | medium | large is still better than 0 | 1 | 2), then Binary Linear Interpolation is probably the most flexible method to start with, and as we have seen in Combining approaches section, numbers can be converted to inputs for every other method.

However, in the vast majority of cases I have seen, the north star API is a set of plain, high-level keywords. This is only possible via Type Grinding and Variable animation names.

Between the two, Type Grinding is the one providing the best encapsulation, since it relies entirely on custom properties and does not hijack any native properties.

Unfortunately, the fact that @property is not yet supported in Shadow DOM throws a spanner in the works, but since these intermediate properties are only used for internal calculations, we can just give them obscure names and insert them in the light DOM.

On the other hand, @keyframes are not only allowed, but also properly scoped when used in Shadow DOM, so Variable animation name might be a good choice when you don’t want to use the same keywords for multiple custom properties on the same component and its downsides are not dealbreakers for your particular use case.

Conclusion

Phew! That was a long one. If you’re aware of any other techniques, let me know so I can add them.

And I think after all of this, if you had any doubt that we need if() in CSS, the sheer number and horribleness of these hacks must have dispelled it by now. 😅

Thanks to Roma Komarov for reviewing earlier drafts of this article.


  1. I’ve always thought this was our most important deliverable, and pushed for prioritizing it. Recently, I even became editor of it. 🙃 ↩︎

  2. I’m using product here in the general sense, of any software product, technology, or API, not just for-profit or commercial ones. ↩︎

  •  

Inline conditionals in CSS?

Last week, the CSS WG resolved to add an inline if() to CSS. But what does that mean, and why is it exciting?

Last week, we had a CSS WG face-to-face meeting in A Coruña, Spain. There is one resolution from that meeting that I’m particularly excited about: the consensus to add an inline if() to CSS. While I was not the first to propose an inline conditional syntax, I did try and scope down the various nonterminating discussions into an MVP that can actually be implemented quickly, discussed ideas with implemenators, and eventually published a concrete proposal and pushed for group resolution. Quite poetically, the relevant discussion occurred on my birthday, so in a way, I got if() as the most unique birthday present ever. 😀

This also comes to show that proposals being rejected is not the end-all for a given feature. It is in fact quite common for features to be rejected for several times before they are accepted: CSS Nesting, :has(), container queries were all simply the last iteration in a series of rejected proposals. if() itself was apparently rejected in 2018 with very similar syntax to what I proposed. What was the difference? Style queries had already shipped, and we could simply reference the same syntax for conditions (plus media() and supports() from Tab’s @when proposal) whereas in the 2018 proposal how conditions would work was largely undefined.

I posted about this on a variety of social media, and the response by developers has been overwhelmingly positive:

I even had friends from big companies writing to tell me their internal Slacks blew up about it. This proves what I’ve always suspected, and was part of the case I made to the CSS WG: that this is a huge pain point. Hopefully the amount and intensity of positive reactions will help browsers prioritize this feature and add it to their roadmaps earlier rather than later.

Across all these platforms, besides the “I can’t wait for this to ship!” sentiment being most common, there were a few other recurring questions and a fair bit of confusion that I figured were worth addressing.

FAQ

What is if() for? Does it replace style queries?

Quite the opposite — if() complements style queries. If you can do something with style queries, by all means, use style queries — they are almost certainly a better solution. But there are things you simply cannot do with style queries. Let me explain.

The motivating use case was that components (in the broader sense) often need to define higher level custom properties, whose values are not just used verbatim in declarations, but that set unrelated values on a variety of declarations.

For example, consider a --variant custom property (inspired from Shoelace’s variant attribute). It could look like this:

--variant: success | danger | warning | primary | none;

This needs to set background colors, border colors, text colors, icons, etc. In fact, it’s actual value is not used verbatim anywhere, it is only used to set other values.

Style queries get us halfway there:

.callout { /* or :host if in Shadow DOM */
	@container (style(--variant: success)) {
		&::before {
			content: var(--icon-success);
			color: var(--color-success);
		}
	}

	/* (other variants) */
}

However, style queries only work on descendants. We cannot do this:

.callout {
	@container (style(--variant: success)) {
		border-color: var(--color-success-30);
		background-color: var(--color-success-95);

		&::before {
			content: var(--icon-success);
			color: var(--color-success-05);
		}
	}

	/* (other variants) */
}

Often the declarations we need to set on the element itself are very few, sometimes even just one. However, even one is one too many and makes using custom properties untenable for many (possibly most) higher level custom property use cases. As a result, component libraries end up resorting to presentational attributes like pill, outline, size, etc.

While presentational attributes may seem fine at first glance, or even better for DX (fewer characters — at least compared to setting a variable per element), they have several usability issues:

Reduced flexibility
They cannot be conditionally applied based on selectors, media queries, etc. Changing them requires more JS. If they are used within another component, you’re SOL, whereas with (inheritable) custom properties, you can set the property on the parent component and it will inherit down.
Verbosity
They have to be applied to individual instances, and cannot be inherited. Even if one uses some form of templating or componentization to reduce duplication, they still have to wade through these attributes when debugging with dev tools.
Lack of consistency
Since almost every mature component also supports custom properties, users have to remember which styling is done via attributes and which via custom properties. The distinction is often arbitrary, as it’s not driven by use cases, but implementation convenience.

With if(), the above example becomes possible, albeit with worse ergonomics than style queries since it cannot cascade (though I do have a proposal to allow it to — plus all other IACVT declarations):

.callout {
	border-color: if(
		style(--variant: success) ? var(--color-success-30) :
		style(--variant: danger) ? var(--color-danger-30) :
		/* (other variants) */
		var(--color-neutral-30)
	);
	background-color: if(
		style(--variant: success) ? var(--color-success-95) :
		style(--variant: danger) ? var(--color-danger-95) :
		/* (other variants) */
		var(--color-neutral-95)
	);

	@container (style(--variant: success)) {
		&::before {
			content: var(--icon-success);
			color: var(--color-success-05);
		}
	}

	/* (other variants) */
}

While this was the primary use case, it turned out that it’s pretty easy to also make media queries and supports conditions part of if()’s conditional syntax. And since it’s a function, its arguments (including the condition!) can be stored in other custom properties. This means you can do things like this:

:root {
	--xl: media(width > 1600px);
	--l: media (width > 1200px);
	--m: media (width > 800px);
}

and then define values like:

padding: if(
	var(--xl) ? var(--size-3) :
	var(--l) or var(--m) ? var(--size-2) :
	var(--size-1)
);

Just like ternaries in JS, it may also be more ergonomic for cases where only a small part of the value varies:

animation: if(media(prefers-reduced-motion) ? 10s : 1s) rainbow infinite;

So is it in browsers yet?

Believe it or not, that was a real question I got 😅. No, it’s not in browsers yet, and it won’t be for a while. The most optimistic estimate is 2 years or so, if the process doesn’t stall at any point (as it often does).

All we have is consensus to work on the feature. The next steps are:

  1. Reach consensus on the syntax of the feature. Syntax debates can often take a very long time, because syntax is an area where everyone has opinions. The current debates revolve around:
  2. Spec the feature.
  3. Get the first implementation. Often that is the hardest part. Once one browser implements, it is far easier to get the others on board.
  4. Get it shipped across all major browsers.

I do have a page where I track some of my standards proposals which should help illuminate what the timeline looks like for each of these steps. In fact, you can track the progress of if() specifically there too.

Is this the first conditional in CSS?

Many responses were along the lines of “Wow, CSS is finally getting conditionals!”.

Folks… CSS had conditionals from the very beginning. Every selector is essentially a conditional!

In addition:

  • @media and @supports rules are conditionals. And let’s not forget @container.
  • var(--foo, fallback) is a limited type of conditional (essentially if(style(--foo: initial) ? var(--foo) : fallback)), hence why it’s the basis of most workarounds for emulating inline conditionals.

Does this make CSS imperative?

A widespread misconception is that non-linear logic (conditionals, loops) makes a language imperative.

Declarative vs imperative is not about logic, but level of abstraction. Are we describing the goal or how to achieve it? In culinary terms, a recipe is imperative, a restaurant menu is declarative

Conditional logic can actually make a language more declarative if it helps describe intent better.

Consider the following two snippets of CSS:

Space toggleif()
button {
	border-radius: calc(.2em + var(--pill, 999em));
}

.fancy.button {
	/* Turn pill on */
	--pill: initial;
}

button {
	border-radius: if(style(--shape: pill) ? 999em : .2em);
}

.fancy.button {
	--shape: pill;
}

I would argue the latter is far more declarative, i.e. much closer to specifying the goal rather than how to achieve it.

Does this make CSS a programming language?

A very common type of response was around whether CSS is now a programming language (either asking whether it is, or asserting that it now is). To answer that, one first needs to answer what a programming language is.

If it’s Turing-completeness that makes a language a programming language, then CSS has been a programming language for over a decade. But then again, so is Excel or Minecraft. So what does that even mean?

If it’s imperativeness, then no, CSS is not a programming language. But neither are many actual programming languages!

But a deeper question is, why does it matter? Is it because it legitimizes choosing to specialize in CSS? It is because you can then be considered a programmer even if you only write HTML & CSS? If this only matters for optics, then we should fix the issue at its core and fight to legitimize CSS expertise regardless of whether CSS is a programming language. After all, as anyone who knows several well-respected programming languages and CSS can attest, CSS is far harder to master.


Great as all this may be, it won’t be in browsers for a while. What can we do right now? I wrote Part 2 exactly about that: CSS Conditionals, now?

  •  
❌