I cannot count the number of times in my career I wished I could run JS in response to CSS property changes,
regardless of what triggered them: media queries, user actions, or even other JS.
Use cases abound.
Here are some of mine:
Implement higher level custom properties in components, where one custom property changes multiple others in nontrivial ways (e.g. a --variant: danger that sets 10 color tokens).
Polyfill missing CSS features
Change certain HTML attributes via CSS (hello --aria-expanded!)
Set CSS properties based on other CSS properties without having to mirror them as custom properties
The most recent time I needed this was to prototype an idea I had for Web Awesome,
and I decided this was it:
I’d either find a good, bulletproof solution, or I would build it myself.
Jane Ori first asked “Can we do better than polling?” with her css-var-listener in 2019.
It parsed the selectors of relevant CSS rules, and used a combination of observers and event listeners to detect changes to the matched elements.
Artem Godin was the first to try using transition events such as transitionstart to detect changes, with his css-variable-observer in 2020.
In fact, for CSS properties that are animatable, such as color or font-size, using transition events is already enough.
But what about the rest, especially custom properties which are probably the top use case?
In addition to pioneering transition events for this purpose, Artem also concocted a brilliant hack to detect changes to custom properties:
he stuffed them into font-variation-settings, which is animatable regardless of whether the axes specified corresponded to any real axes in any actual variable font, and then listened to transitions on that property.
It was brilliant, but also quite limited: it only supported observing changes to custom properties whose values were numbers (otherwise they would make font-variation-settings invalid).
The next breakthrough came four years later, when Bramus Van Damme pioneered a way to do it “properly”, using the (then) newly Baseline transition-behavior: allow-discrete after an idea by Jake Archibald.
His @bramus/style-observer was the closest we’ve ever gotten to a “proper” general solution.
Releasing his work as open source was already a great service to the community, but he didn’t stop there.
He stumbled on a ton of browser bugs, which he did an incredible job of documenting and then filing.
His conclusion was:
Right now, the only cross-browser way to observe Custom Properties with @bramus/style-observer is to register the property with a syntax of “<custom-ident>”.
Note that <custom-ident> values can not start with a number, so you can’t use this type to store numeric values.
Wait, what?
That was still quite the limitation!
My brain started racing with ideas for how to improve on this.
What if, instead of trying to work around all of these bugs at once, we detect them so we only have to work around the ones that are actually present?
At first I considered just sending a bunch of PRs, but I wanted to iterate fast, and change too many things.
I took the fact that the domain observe.style was available as a sign from the universe, and decided the time had come for me to take my own crack at this age-old problem, armed with the knowledge of those who came before me and with the help of my trusty apprentice Dmitry Sharabin(hiring him to work full-time on our open source projects is a whole separate blog post).
One of the core ways style-observer achieves better browser support is that
it performs feature detection for many of the bugs Bramus identified.
This way, code can work around them in a targeted way, rather than the same code having to tiptoe around all possible bugs.
As a result, it basically works in every browser that supports transition-behavior: allow-discrete,
i.e. 90% globally.
Safari transition loop bug (#279012):
StyleObserverdetects this and works around it by debouncing.
Chrome unregistered transition bug (#360159391):
StyleObserverdetects this bug and works around it by registering the property, if unregistered.
Firefox no initial transitionstart bug (#1916214):
By design, StyleObserver does not fire its callback immediately (i.e. works more like MutationObserver than like ResizeObserver).
In browsers that do fire an initial transitionstart event, it is ignored.
Additionally, besides browser support, this supports throttling, aggregation, and plays more nicely with existing transitions.
Since this came out of a real need, to (potentially) ship in a real product, it has been exhaustively tested, and comes with a testsuite of > 150 unit tests (thanks to Dmitry’s hard work).
If you want to contribute, one area we could use help with is benchmarking.
That’s all for now!
Try it out and let us know what you think!
One would think that we’ve more or less figured survey UI out by now.
Multiple choice questions, checkbox questions, matrix questions, dropdown questions, freeform textfields, numerical scales,
what more could one possibly need?!
And yet, every time Google sponsored me to lead one of the State Of … surveys, and especially the inaugural State of HTML 2023 Survey,
I kept hitting the same wall; I kept feeling that the established options for answering UIs were woefully inadequate for
balancing the collection good insights with minimal friction for end-users.
The State Of surveys used a completely custom survey infrastructure,
so I could often (but not always) convince engineering to implement new question UIs.
After joining Font Awesome, I somehow found myself leading yet another survey, despite swearing never to do this again. 🥲
Alas, building a custom survey UI was simply not an option in this case; I had to make do with the existing options out there 1, so I felt this kind of pain to my core once again.
So what are these cases where the existing answering UIs are inadequate, and how could better ones help?
I’m hoping this case study to be Part 1 of a series around how survey UI innovations can help balance tradeoffs between user experience and data quality, though this is definitely the one I’m most proud of, as it was such a bumpy ride, but it was all worth it in the end.
For context, the body of State Of surveys is a series of “Feature questions”,
which present the respondent with a certain web platform feature and ask if they had heard of it or used it.
Feature questions look like this:
An example of a feature question from the State of CSS 2022 survey.
Respondents get a score in the end, based on how many of these they had heard of or used.
Each survey had dozens of these questions.
Based on initial estimates, State of HTML was going to have at least fifty.
This was my score. We revamped the scoring system for this iteration and switched from a percentage to a point-based score,
since not all questions were equally weighted.
Respondents love these questions.
They learn about new things they may not have heard of, and get to test their knowledge.
But also, from the survey designer’s perspective, they gamify a (very long) survey, increasing completion rates,
and provide users incentive to share their score on social media, spreading the word.
One would expect that they also provide valuable data, yet browser vendors had repeatedly mentioned that this data was largely useless to them.
Surveys were all about what people felt, not what they knew or had used — they had better ways to gauge those.
Instead, the reason they funneled thousands into funding these surveys every year was the 1-2 pain points questions towards the end.
That was it.
Survey data on experience and awareness could be useful, but only if it was accompanied with subjective sentiment data:
if they hadn’t used it or heard about it, were they interested? If they had used it, how did it feel?
Optional freeform comments had been added the year prior, but got an abysmally low response rate,
and being entirely freeform, were hard to analyze.
As an attempt to address this feedback, a button that opened a freeform comment field had been introduced the year prior, but response rates were abysmally low,
starting from 0.9% for the first question 2 and dropping further along the way.
This was no surprise to me: freeform questions have a dramatically lower response rate than structured questions,
and hidden controls get less interaction (“out of sight, out of mind”).
But even if they had a high response rate, freeform comments are notoriously hard to analyze, especially when they are so domain specific.
Essentially, the data we needed to collect was a combination of two variables: experience and sentiment.
Collecting data on two variables is common in survey design, and typically implemented as a matrix question.
🤷
👍
👎
Never heard of it
Heard of it
Used it
If user experience and cognitive load were not a concern, the same data could actually be collected with a matrix question.
Indeed, if there were only a couple such questions, a matrix could have been acceptable.
But …could you imagine filling out 50 of these?
An acceptable solution needed to add minimal friction for end-users:
there were at least 50 such questions, so any increase in friction would quickly add up — even one extra click was pushing it.
And we needed a sufficiently high response rate to have a good CI.
But it also needed to facilitate quantitative data analysis.
Oh, and all of that should involve minimal engineering effort, as the (tiny) engineering team was already stretched thin.
Initially, I took these constraints to heart.
Misguided as it may have been, the comment field and the infrastructure around it already existed, so I designed a UI that revealed relevant positive/negative sentiment options using contextual progressive disclosure.
These inserted predefined responses into the comment field with a single click.
Being a purely client-side interaction meant it could be implemented in a day, and it still kept end-user friction at bay:
providing sentiment was optional and only required a single click.
In theory, quantitative data analysis was not optimally covered, as freeform responses are notoriously hard to analyze.
However, based in the psychology of user behavior, I hypothesized that the vast majority of users would not edit these at all, a minority would append context, and an even tinier minority would actually edit the responses.
This meant we could analyze them via simple string matching and only lose a few false negatives.
Mockup of the quick context idea.
I was very proud of myself: I had managed to design a solution that satisfied all constraints, a feat that initially seemed impossible!
Not to mention this design gently guided users towards using the comment field, which could motivate them to add even more context.
Yet, when I presented my mocks to the team, engineering hated it with a passion.
The lead engineer (who was also the project founder) found the idea of turning a structured interaction into unstructured data deeply unsettling.
So much it motivated him to implement a whole backend to store these followups properly, something I had initially thought was out of the question.
So now what?
Back to the drawing board, but with one constraint lifted!
Mockups of intermediate ideas.
Left: Followups (by lead engineer)
Right: Sentiment radios (by Google PM)
This new backend came with a UI proposal that raised red flags for both me and the Google PM I was collaborating with (one of the survey’s core stakeholders, but not the main one).
Even seeing the followup UI required an extra click, so it was guaranteed to have a low response rate.
It would have been better than the 0.9% of the comment field (clicking is easier than typing!), but still pretty low (I would estimate < 15%).
And even when users were intrinsically motivated to leave feedback, two clicks and a popover was a steep price to pay.
Another idea came from the Google PM: sentiment radios.
It was an attempt to simplify the interaction by framing it as a two step process:
first experience, then sentiment, through radio buttons that slid down once a main answer was selected.
However, I was very concerned that such a major UI shift after every single answer would quickly become overwhelming over the course of the survey.
Back to the drawing board, I asked myself: if I had infinite engineering resources, what UI would I design?
The biggest challenge was reducing friction.
All ideas so far had required at least one extra (optional) click to select sentiment.
Could we do better?
What if users could select both experience and sentiment with a single click?
Guided by this, I designed a UI where selecting sentiment is done via “context chips” which are actually part of the answer,
so clicking them also selects the answer they are accompanying, allowing users to express an answer across both variables with a single click, or just select the answer itself to express no sentiment.
To reduce visual clutter, these only faded in on hover.
Additionally, clicking on the selected chip a second time would deselect it, fixing a longstanding UX issue with radio buttons 3.
Over the course of designing this, I became so convinced it was the right solution, that I implemented a high fidelity prototype myself, complete with code that could be easily adapted to the infrastructure used by the survey app.
The context chips prototype on desktop and mobile.
There were so many things I loved about this design, even beyond the core idea of answering both variables with a single click.
There were no layout shifts, the followups were in close proximity to the main answer, and the styling of the chips helped build a visual association to reduce friction even more as you go.
I was not a huge fan of the mobile version, but I couldn’t think of a much better way to adapt this UI to mobile.
Early alternative concept that supported followups.
This was deemed too complicated and was abandoned early on.
Reception of context chips was not what I had hoped at first.
I had expected pushback due to the engineering effort needed, but folks also had other concerns:
that users would find things appearing on hover distracting and feel “ambushed”,
that the UI was too “weird”,
that users would not discover the 1-click interaction and use it as a two-step process anyway,
and that response rate would be low because these chips were not visible upfront.
Around the same time as designing context chips, I had a relevant realization:
we don’t actually need to know both awareness and usage for all features.
For old, widely supported features, awareness doesn’t matter, because even when it’s low, it has plateaued.
And for features that are so new they have not yet been implemented in browsers, usage is largely meaningless.
For these cases, each feature only has two states, and thus experience can be expressed with a checkbox!
This would allow us to combine questions about multiple features in one,
and we could still use context chips, albeit a little differently:
The mini features prototype on desktop and mobile.
While these could be used for questions that either discern usage or awareness, we decided to stick to the former, as there was a (valid) concern that having mini-feature questions whose checked state meant different things could be confusing and lead to errors.
That way, only old, lower-priority features would be relegated to this template,
and new features which tend to be higher priority for browser vendors would still get the full UI, comments and all.
Instead, to improve the experience for cutting edge features, we introduced a “Not implemented” tag next to the “Used it” option.
One disadvantage of the mini feature UI is that due to the way context chips work, it is not possible to select sentiment for features you have not used:
once you click on a chip, it also selects the feature, as if you had clicked on its label.
I guess it could be possible to click on a chip and then uncheck the feature, but that would be a very weird interaction.
At this point, the lead engineer dredged up a question template that had been used in other surveys to ask about the respondent’s experience with various types of tooling.
Instead of separating experience and sentiment, it used a 5-point scale where each answer except the first answered both questions.
The existing 5-point question template.
The eng lead was sold: zero engineering effort!
The Google PM was also sold: 100% response rate! (since it was not possible to avoid expressing sentiment for features you had heard or used).
I had serious reservations.
There are arguments for even numbered Likert scales (no neutral option), but these always involve scales of at least 4 points.
If you force people to select between two states, positive or negative, you’re simply going to get garbage data.
Neutral votes get pushed into positive votes, and the data around positive sentiment becomes useless.
These did not allow users to express sentiment for features they had not heard of, despite these questions often including enough info for users to know whether they were interested.
I was worried that increasing the number of upfront answers to 5 would increase cognitive load too much — and even scrolling distance, by 66%!
A UX researcher we were working with even did a heuristic evaluation that somewhat favored the 5-point template mainly on the basis of being a more familiar UI.
The odds seemed stacked against context chips, but the upcoming usability testing could still tip the scales in their favor.
Despite the lead engineer being unconvinced about the merits of context chips and being adamant that even adapting my fully functional prototype was too much work, since the prototype existed, we decided to user test it against the 5-point question and see how it compared.
We ran a within-subjects usability study
with 6 participants (no, they are not too few)
recruited via social media.
Half of the survey used the 5-point template, the other half context chips.
The order of the conditions was randomized to avoid order effects.
In addition to their actual experience, we also collected subjective feedback at the end of the survey,
showing them a screenshot of each answering UI and asking how each felt.
I have run many usability studies in the last ten years, and I have never seen results as resounding as this one.
So much that we unanimously agreed to switch to context chips after the 5th participant, because the scales were so tipped in favor of context chips that nothing that happened in the last session could have tipped them the other way.
The lead engineer observed some of the sessions, and this was instrumental in changing his mind.
This was not a coincidence: when engineering is unconvinced that a certain UI is worth the implementation complexity,
it can be a good strategy to have them observe usability testing sessions.
Not only does it help prove the value to them, it also builds long-term user empathy, which makes future consensus easier.
Given the unfortunate lack of HCI prioritization in Computer Science curricula, this may even be their first exposure to usability testing.
All of my concerns about the 5-point template were brought up by participants on their own accord, repeatedly:
All participants really liked being able to express sentiment, and were vocal about their frustration when they could not express it.
All but one participant (4/5) complained about being forced into selecting a sentiment when they had no opinion.
Some participants even mentioned that the 5-point template felt overwhelming.
Furthermore, none of the concerns about context chips were validated:
No-one found the chips appearing on hover distracting or felt “ambushed”.
No-one struggled to understand how to use them.
Everyone discovered the 1-click interaction pretty fast (typically within the first 2-3 questions).
But interestingly, they still chose to use it as a two-step process for some of the questions, presumably to reduce cognitive load for difficult to answer questions by breaking down the decision into two smaller ones.
The fact that this UI allowed users to make their own efficiency vs cognitive load tradeoffs was an advantage I had not even considered when designing it!
Response rate was generally high — when people did not select sentiment, it was because they genuinely had no opinion, not because they couldn’t be bothered.
Mini-feature questions did successfully help cut down response time per feature by 75%,
though this came at a cost:
Once more, we saw that participants really wanted to express sentiment, and were frustrated when they couldn’t,
which was the case for features they had not used.
Regardless, we agreed that the tradeoff was worth it for the low-priority questions we were planning to use mini-features for.
A blind spot in our testing was that we did not test the UI on mobile.
Usability tests were conducted remotely via video call, so it was a lot easier to get participants to use their regular computers.
Additionally, stats for previous surveys showed that mobile use was a much smaller percentage in these surveys than for the web in general (~25%), so we did not prioritize it.
This was a mistake in itself: using current usage stats to inform prioritization may seem like a great idea, but it can be prone to reverse causality bias.
Meaning, are people not using these surveys on mobile very much because they genuinely don’t need to,
or because the experience on mobile is subpar?
We often see this with accessibility too: people claim that it doesn’t matter because they don’t have users with disabilities,
but often they don’t have users with disabilities because their site is not accessible!
But even if 75% of users genuinely preferred to take these surveys on desktop (which is plausible, since they are long and people often do them in increments), we should at least have done a few sessions on mobile — 25% is not negligible!
Once responses started coming in, we realized that participants had trouble understanding what the up and down arrows meant, since on mobile these are shown without labels until selected.
This would have been an easy fix had it had been caught early, e.g. thumbs up/down icons could have been used instead.
This was not a huge issue, as their purpose becomes clear when selected, but it definitely adds some friction.
In our usability testing, we had seen a high response rate for sentiment (% of question respondents who selected sentiment),
but that is no guarantee things will play out that way post-launch as well.
When participants know they are being watched they are always more willing to engage and pay a lot more attention,
no matter how much you emphasize that they should act naturally when briefing them.
That’s not their failing; it’s simply human nature.
Indeed, sentiment response rates in the real-world were lower than those observed in the usability study,
but still high — ranging from 24% to 59% and averaging 38% (with the same median) per question, meaning that out of every ten participants that answered each question, approximately four also provided a sentiment.
This was more than enough to draw conclusions.
In fact, context chips were deemed such a success they were later adopted by all other State Of surveys,
even at the cost of continuity with previous years.
Against expectations, participants were just as likely to express sentiment for features they had never heard of,
and in fact marginally more likely than for features they had simply heard of.
In general response rates were pretty uniform across all experiences:
Experience
Sentiment response rate (average)
Sentiment response rate (median)
Never heard of it
37.3%
37.4%
Heard of it
37.3%
36.9%
Used it
39.0%
40.1%
Overall
37.6%
37.9%
Sentiment response rates overall and by experience (per question).
As we had observed in the user study as well, participants were far more likely to express positive rather than negative sentiment (possibly a case of acquiescence bias).
Here are some interesting stats:
The feature with the most negative sentiment overall across all experiences (<model>) still only had 10% of respondents expressing negative sentiment for it, and still had 2.4x more positive sentiment than negative (24.7% vs 10.4%)!
In contrast, the feature with the most positive sentiment (<datalist>) got a whopping 55% of respondents expressing positive sentiment (and only 4% negative).
In fact, even the feature with the least positive sentiment (Imperative Slot Assignment 🤔) still had way more positive sentiment (17.24%) than <model> had negative sentiment (10%)!
If we look at the ratio of positive over negative sentiment, it ranged from 64x (!) more positive than negative sentiment (45% vs 0.7% for landmark elements) to a mere 2.4x times more positive sentiment (24.7% vs 10.4% for <model>), and was 11x on average (8x median).
The analysis presented in this section includes data from 20K respondents, which was most of the whole dataset (around 90%) but not all, as it was done before the survey closed.
Presenting all this data was another challenge.
When you have two variables, ideally you want to be able to group results by either.
E.g. you may be more interested in the total negative sentiment for a feature, or how many people had used it, and the results visualization should support both.
How do we design a results display that facilitates this?
Thankfully the visualizations for State Of surveys were already very interactive so interactivity was not out of the question.
I was no longer involved by then but consulted in a volunteer capacity.
My main advice was to use proximity for clear visual grouping, and to use a consistent visual association for bars that represented the same bit of data, both of which they followed.
This was the rendering they settled on for the results:
Interactive bar chart presenting two variables at once.
I think in terms of functionality this works really well.
The visual design could be improved to communicate IA better and appear less busy at first glance,
but given there is no dedicated designer in the team, I think they did a fantastic job.
While this UI was originally designed to collect sentiment about the selected option in a multiple choice question,
I think it could be generalized to improving UX for other types of two variable questions.
Generally, it can be a good fit when we have questions that collect data across two variables and:
The second variable is optional and lower priority than the first
The first variable is exclusive (single) choice, i.e. not checkbox questions.
The core benefit of this approach is the reduction in cognitive load.
It is well established that matrix questions are more overwhelming.
This design allows questions to initially appear like a simple multiple choice question, and only reveal the UI for the second variable upon interaction.
Additionally, while matrix questions force participants to decide on both variables at once, this design allows them to make their own tradeoff of cognitive load vs efficiency, treating the UI as single step or two step as they see fit.
Another benefit of this design is that it allows for option labels to be context-dependent for the second variable, whereas a matrix limits you to a single column header.
In the sentiment case, the labels varied depending on whether the feature had been used (“Positive experience” / “Negative experience”) or not (“Interested” / “Not interested”).
The more such questions a survey has, the bigger the benefits — if it’s only about a couple questions,
it may not be worth the implementation complexity,
though I’m hoping that survey software may eventually provide this out of the box so that this is no longer a tradeoff.
That said, matrix questions do have their benefits, when used appropriately, i.e. when the two requirements listed above are not met.
Matrix questions have an big edge when users need to make a single selection per row,
especially when this may be the same answer for multiple rows, which means they can just tick down a whole column.
Context chips do not allow users to build this positional association, as they are not aligned vertically.
THey are placed right after the answer text, and thus their horizontal position varies per answer.
To mitigate this, it can be useful to color-code them and maintain the same color coding consistently throughout the survey so that participants can build a visual association 4.
Context chips also enforce a clear prioritization across the two variables:
the question is presented as a multiple choice question across the first variable,
with the chips allowing the respondent to provide optional additional context across a second variable.
Matrix questions allow presenting the two variables with the same visual weight,
which could be desirable in certain cases.
For example, there are cases when we don’t want to allow the respondent to provide an answer to the first variable without also providing an answer to the second.
In addition to any generalizable knowledge around survey design, I think this is also an interesting product management case study, and teaches us several lessons.
Start any product design task by ignoring ephemeral constraints (e.g. engineering resources) and first reach consensus on what the optimal UI is, before you start applying constraints.
Yes, you read that right.
I want to write a whole post about the importance of north star UIs, because this is one of many cases over the course of my career where tight implementation constraints were magically lifted, either due to a change of mind, a change in the environment, or simply someone’s brilliant idea.
Without consensus on what the north star UI is (or even a clear idea about it) you then have to go back to the drawing board when this happens.
You probably already know that usability testing is a great tool for improving user experience,
but there is a second, more strategic hidden utility to it: consensus building.
I’ve been in way, way too many teams where UI decisions were made by hypothesizing about user behavior, which could not only be missing the mark, but also there is no way forwards for disagreements.
What do you do, hypothesize harder?
When there is user testing data, it is much harder to argue against it.
This is especially useful in convincing engineering that a certain UI is worth the implementation complexity,
and having engineers observe usability testing sessions can be an educational experience for many.
There are many things to like about heuristic evaluations and design reviews.
They can be done by a usability expert alone and can uncover numerous issues that would have taken multiple rounds of usability testing, especially if they are also a domain expert.
Fixing the low hanging fruit issues means user testing time can be spent more efficiently, uncovering less obvious problems.
That are are also certain types of issues that can only be uncovered by a heuristic evaluation, such as _“death by a thousand paper cuts” type issues: small issues that are not a big deal on their own and are too small to observe in a user study, but add up to more friction.
However, a big downside of these is that they are inherently prone to bias.
They can be excellent for finding problems that may have been overlooked and are often obvious once pointed out.
However (unless the number of evaluators is large), they are not a good way to decide between alternatives.
Unlike Devographics, surveys are not FA’s core business, so the Impact/Effort tradeoff simply wasn’t there for a custom UI, at least at this point in time. I ended up going with Tally, mainly due to the flexibility of its conditional logic and its support for code injection (which among other things, allowed me to use FA icons — a whopping 120 different ones!). ↩︎
Meaning out of the people who responded to that question about their experience with a feature, only 0.9% left a comment. ↩︎
A radio group with all buttons off cannot be returned to that state by user interaction. ↩︎
The ~9% of people with atypical color vision won’t benefit, but that’s okay in this case,
as color is used to add an extra cue, and not an essential part of the interface. ↩︎
Disclaimer: This post expresses my opinions, which do not necessarily reflect consensus by the whole Web Components community.
A blog post by Ryan Carniato
titled “Web Components Are Not the Future” has recently stirred a lot of controversy.
A few other JS framework authors pitched in, expressing frustration and disillusionment around Web Components.
Some Web Components folkswroterebuttals,
while others repeatedlytried to get to the bottom of the issues,
so they could be addressed in the future.
When you are on the receiving end of such an onslaught,
the initial reaction is to feel threatened and become defensive.
However, these kinds of posts can often end up shaking things up and pushing a technology forwards in the end.
I have some personal experience:
after I published my 2020 post titled “The failed promise of Web Components” which also made the rounds at the time,
I was approached by a bunch of folks (Justin Fagnani, Gray Norton, Kevin Schaaf) about teaming up to fix the issues I described.
The result of these brainstorming sessions was the Web Components CG which now has a life of its own
and has become a vibrant Web Components community that has helped move several specs of strategic importance forwards.
As someone who deeply cares about Web Components,
my initial response was also to push back.
I was reminded of how many times I have seen this pattern before.
It is common for new web platform features to face pushback and resistance for many years;
we tend to compare them to current userland practices, and their ergonomics often fare poorly at the start.
Especially when there is no immediately apparent 80/20 solution, making things possible tends to precede making them easy.
Web platform features operate under a whole different set of requirements and constraints:
They need to last decades, not just until the next major release.
They need to not only cater to the current version of the web platform, but anticipate its future evolution and be compatible with it.
They need to be backwards compatible with the web as it was 20 years ago.
They need to be compatible with a slew of accessibility and internationalization needs that userland libraries often ignore at first.
They are developed in a distributed way, by people across many different organizations, with different needs and priorities.
Usually, the result is more robust, but takes a lot longer.
That’s why I’ve often said that web standards are “product work on hard mode” — they include most components of regular product work (collecting user needs, designing ergonomic solutions, balancing impact over effort, leading without authority, etc.), but with the added constraints of a distributed, long-term, and compatibility-focused development process that would make most PMs pull their hair out in frustration and run screaming.
I’m old enough to remember this pattern playing out with CSS itself:
huge pushback when it was introduced in the mid 90s.
It was clunky for layout and had terrible browser support — “why fix something that wasn’t broken?” folks cried.
Embarrassingly, I was one of the last holdouts:
I liked CSS for styling, but was among the last to switch to floats for layout — tables were just so much more ergonomic!
The majority resistance lasted until the mid '00s when it went from “this will never work” to “this was clearly the solution all along” almost overnight.
And the rest, as they say, is history. 🙂
But the more I thought about this, the more I realized that — as often happens in these kinds of heated debates — the truth lies somewhere in the middle.
Having used both several frameworks, and several web components,
and having authored both web components (most of them experimental and unreleased) and even one framework over the course of my PhD, both sides do have some valid points.
Frankly, if framework authors were sold the idea that web components would be a compile target for their frameworks, and then got today’s WC APIs, I understand their frustration.
Worse yet, if every time they tried to explain that this sucks as a compile target they were told “no you just don’t get it”, heck I’d feel gaslit too!
Web Components are still far from being a good compile target for all framework components,
but that is not a prerequisite for them being useful.
They simply solve different problems.
Let me explain.
Not all component use cases are the same.
I think the crux of this debate is that the community has mixed two very different categories of use cases,
largely because frameworks do not differentiate between them;
“component” has become the hammer with which to hammer every nail.
Conceptually, there are two core categories of components:
Generalizable elements that extend what HTML can do and can be used in the same way as native HTML elements across a wide range of diverse projects.
Things like tabs, rating widgets, comboboxes, dialogs, menus, charts, etc.
Another way to think about these is “if resources were infinite, elements that would make sense as native HTML elements”.
Reactive templating: UI modules that have project-specific purposes and are not required to make sense in a different project.
For example, a font foundry may have a component to demo a font family with child components to demo a font family style,
but the uses of such components outside the very niche font foundry use case are very limited.
Of course, it’s a spectrum; few things in life fit neatly in completely distinct categories.
For example an <html-demo> component may be somewhat niche, but would be useful across any site that wants to demo HTML snippets
(e.g. a web components library, a documentation site around web technologies, a book teaching how to implement UI patterns, etc.).
But the fact that it’s a spectrum does not mean the distinction does not exist.
WCs primarily benefit the use case of generalizable elements that extend HTML,
and are still painful to use for reactive templating.
Fundamentally, it’s about the ratio of potential consumers to authors.
The huge benefit of Web Components is interoperability:
you write it once, it works forever, and you can use it with any framework (or none at all).
It makes no sense to fragment efforts to reimplement e.g. tabs or a rating widget separately for each framework-specific silo,
it is simply duplicated busywork.
As a personal anecdote, a few weeks ago I found this amazing JSON viewer component, but I couldn’t use it because I don’t use React (I prefer Vue and Svelte).
To this day, I have not found anything comparable for Vue, Svelte, or vanilla JS.
This kind of fragmentation is sadly an everyday occurrence for most devs.
But when it comes to project-specific components, the importance of interop decreases:
you typically pick a framework and stick to it across your entire project.
Reusing project-specific components across different projects is not a major need,
so the value proposition of interop is smaller.
Additionally, the ergonomics of consuming vs authoring web components are vastly different.
Consuming WCs is already pretty smooth, and the APIs are largely there to demystify most of the magic of built-in elements and expose it to web components (with a few small gaps being actively plugged as we speak).
However, authoring web components is a whole different story.
Especially without a library like Lit, authoring WCs is still painful, tedious, and riddled with footguns.
For generalizable elements, this is an acceptable tradeoff, as their potential consumers are a much larger group than their authors.
As an extreme example of this, nobody complains about the ergonomics of implementing native elements in browsers using C++ or Rust.
But when using components as a templating mechanism, authoring ergonomics are crucial,
since the overlap between consumers and authors is nearly 100%.
This was the motivation behind this Twitter poll I posted a while back.
I asked if people mostly consumed web components, used WCs that others have made, or both.
Note that many people who use WCs are not aware of it, so the motivation was not to gauge adoption,
but to see if the community has caught on to this distinction between use cases.
The fact that > 80% of people who knowingly use web components are also web components authors is indicative of the problem.
WCs are meant to empower folks to do more, not to be consumed by expert web developers who can also write them.
Until this number becomes a lot smaller, Web Components will not have reached their full potential.
This was one of the reasons I joined the Web Awesome project;
I think that is the right direction for WCs:
encapsulating complexity into beautiful, generalizable, customizable elements that give people superpowers by extending what HTML can do:
they can be used by developers to author gorgeous UIs,
designers to do more without having to learn JS,
or even hobbyists that struggle with both (since HTML is the most approachable web platform language).
So IMO making it about frameworks vs web components is a false dichotomy.
Frameworks already use native HTML elements in their components.
Web components extend what native elements can do, and thus make crafting project-specific components easier across all frameworks (as well as no frameworks).
I wonder if this narrative could resonate across both sides and reconcile them.
Basically “yes, we may still need frameworks for nontrivial apps, but web components make their job easier”
rather than pitting them against each other in a pointless comparison where everyone loses.
We will certainly eventually get to the point where web components are more ergonomic to author,
but we first need to get the low-level foundations right.
At this point the focus is still on making things possible rather than making them easy.
The last remaining pieces of the puzzle are things like
Reference Target for cross-root ARIA
or ElementInternals.type to allow custom elements to become popover targets or submit buttons,
both of which saw a lot of progress at W3C TPAC last week.
After that, perhaps eventually web components will even become viable for reactive templating use cases;
things like the open-stylable shadow roots proposal,
declarative elements, or DOM Parts
are some early beginnings in that direction,
and declarative shadow DOM paved the way for SSR (among other things).
Then, and only then, they may make sense as a compile target for frameworks.
However, that is quite far off.
And even if we get there, frameworks would still be useful for complex use cases,
as they do a lot more than let you use and define components.
Components are not even the best reuse mechanism for every project-specific use case — e.g. for list rendering, components are overkill compared to something like v-for.
And by then frameworks will be doing even more.
It is by definition that frameworks are always a step ahead of the web platform,
not a failing of the web platform.
As Cory said, “Frameworks are a testbed for new ideas that may or may not work out.”.
The bottom line is, web components reduce the number of use cases where we need to reach for a framework,
but complex large applications will likely still benefit from one.
So how about we conclude that frameworks are useful, web components are also useful, stop fighting and go make awesome sh!t using whatever tools we find most productive?
Thanks to Michael Warren, Nolan Lawson, Cory LaViska, Steve Orvell, and others for their feedback on earlier drafts of this post.
Today I start a new chapter in my career.
After a decade at MIT, teaching and
doing research at the intersection of usability and programming language design,
I wrapped up my PhD two weeks ago
(yes, I’m a Dr now! And damn right I will — once it actually sinks in)
and today I start my new role as Product Lead at Font Awesome.
I will be evaluating user needs and improving product design and usability across all company products,
with an emphasis on Web Awesome,
the product we are launching early next year to revolutionize how Web UIs are built by using web components and CSS in ways you’ve never seen before.
Beyond improving the products themselves (all of which include extensive free & open source versions),
part of my role will utilize my web standards experience to collect web platform pain points from across the company and translating them to new and existing web standards proposals.
Yes, I know, it’s a match made in heaven. 😍
There is even a small chance I may have been the first to create an icon font for use in a web UI via @font-face,
which would make it even more wonderfully poetic that I’m joining the company that has become synonymous with icon fonts on the Web.
However, it was not my MIT PhD that led me to this role,
but an email from Dave Gandy (creator & CEO of Font Awesome) about Color.js,
that turned into hours of chats,
and eventually a job offer for a role I could not refuse, one that was literally molded around my skills and interests.
The role is not the only reason I’m excited to join Font Awesome, though.
The company itself is a breath of fresh air:
open source friendly (as Dave says, “literally the only reason we have Pro versions is that we need to sustain this somehow” 😅),
already profitable (= no scrambling to meet VC demands by cramming AI features nobody wants into our products),
fully remote, huge emphasis on work-life balance,
and an interview process that did not feel like an interview — or even a process.
In fact, they did not even want to look at my resume (despite my efforts 🤣).
It is telling that in their 10 years of existence, not a single person has left the company, and they have never had to let anyone go.
Moreover, it bridges the best of both worlds: despite having existed for a decade,
branching out to new products1 and markets gives it a startup-like energy and excitement.
I had been extremely selective in the job opportunities I pursued, so it took a while to find the perfect role.
Having ADHD (diagnosed only last year — I want to write a blog post about that too at some point),
I knew it was crucial to find a job I could be passionate about:
ADHD folks are unstoppable machines in jobs they love (I have literally built my career by directing my hyperfocus to things that are actually productive),
but struggle way more than neurotypicals in jobs they hate.
It took a while, but when I started talking with Dave, I knew Font Awesome was it.
I’m still reeling from the mad rush of spending the past couple of months averaging 100-hour weeks to wrap up my PhD before starting,
but I couldn’t be more excited about this new chapter.
I’m hoping to write a series of blog posts in the coming weeks about about my journey to this point.
Things like:
How I decided that academia was not for me — but persisted to the finish line anyway because I’m stubborn AF 😅
How I realized that product work is my real calling, not software engineering per se (as much as I love both)
How I used web technologies instead of LaTeX to write my PhD thesis (and print it to PDF for submission), with 11ty plus several open source plugins, many of which I wrote, an ecosystem I hope to one day free more people from the tyranny of LaTeX (which was amazing in the 70s, but its ergonomics are now showing their age).
But for now, I just wanted to share the news, and go off to make the web more awesome — for everyone. 🚀
A few days ago, I gave a very well received talk about API design at dotJS titled “API Design is UI Design” 1.
One of the points I made was that good UIs (and thus, good APIs) have a smooth UI complexity to Use case complexity curve.
This means that incremental user effort results in incremental value;
at no point going just a little bit further requires a disproportionately big chunk of upfront work 2.
Observing my daughter’s second ever piano lesson today made me realize how this principle extends to education and most other kinds of knowledge transfer (writing, presentations, etc.).
Her (generally wonderful) teacher spent 40 minutes teaching her notation, longer and shorter notes, practicing drawing clefs, etc.
Despite his playful demeanor and her general interest in the subject, she was clearly distracted by the end of it.
It’s easy to dismiss this as a 5 year old’s short attention span, but I could tell what was going on:
she did not understand why these were useful, nor how they connect to her end goal, which is to play music.
To her, notation was just an assortment of arbitrary symbols and lines, some of which she got to draw.
Note lengths were just isolated sounds with no connection to actual music.
Once I connected note lengths to songs she has sung with me and suggested they try something more hands on, her focus returned instantly.
I mentioned to her teacher that kids that age struggle to learn theory for that long without practicing it.
He agreed, and said that many kids are motivated to get through the theory because they’ve heard their teacher play nice music and want to get there too.
The thing is… sure, that’s motivating.
But as far as motivations go, it’s pretty weak.
Humans are animals, and animals don’t play the long game, or they would die.
We are programmed to optimize for quick, easy dopamine hits.
The farther into the future the reward, the more discipline it takes to stay motivated and put effort towards it.
This applies to all humans, but even more to kids and ADHD folks 3.
That’s why it’s so hard for teenagers to study so they can improve their career opportunities and why you struggle to eat well and exercise so you can be healthy and fit.
So how does this apply to knowledge transfer?
It highlights how essential it is for students to
a) understand why what they are learning is useful and
b)put it in practice ASAP.
You can’t retain information that is not connected to an obvious purpose 4 — your brain will treat it as noise and discard it.
The thing is, the more expert you are on a topic, the harder these are to do when conveying knowledge to others.
I get it. I’ve done it too.
First, the purpose of concepts feels obvious to you, so it’s easy to forget to articulate it.
You overestimate the student’s interest in the minutiae of your field of expertise.
Worse yet, so many concepts feel essential that you are convinced nothing is possible without learning them (or even if it is, it’s just not The Right Way™).
Looking back on some of my earlier CSS lectures, I’ve definitely been guilty of this.
As educators, it’s very tempting to say “they can’t possibly practice before understanding X, Y, Z, they must learn it properly”.
Except …they won’t.
At best they will skim over it until it’s time to practice, which is when the actual learning happens.
At worst, they will give up.
You will get much better retention if you frequently get them to see the value of their incremental imperfect knowledge
than by expecting a big upfront attention investment before they can reap the rewards.
There is another reason to avoid long chunks of upfront theory:
humans are goal oriented.
When we have a goal, we are far more motivated to absorb information that helps us towards that goal.
The value of the new information is clear, we are practicing it immediately, and it is already connected to other things we know.
This means that explaining things in context as they become relevant is infinitely better for retention and comprehension than explaining them upfront.
When knowledge is a solution to a problem the student is already facing, its purpose is clear, and it has already been filtered by relevance.
Furthermore, learning it provides immediate value and instant gratification: it explains what they are experiencing or helps them achieve an immediate goal.
Even if you don’t teach, this still applies to you.
I would go as far as to say it applies to every kind of knowledge transfer:
teaching, writing documentation, giving talks, even just explaining a tricky concept to your colleague over lunch break.
Literally any activity that involves interfacing with other humans benefits from empathy and understanding of human nature and its limitations.
To sum up:
Always explain why something is useful. Yes, even when it’s obvious to you.
Minimize the amount of knowledge you convey before the next opportunity to practice it.
For non-interactive forms of knowledge transfer (e.g. a book), this may mean showing an example,
whereas for interactive ones it could mean giving the student a small exercise or task.
Even in non-interactive forms, you can ask questions — the receiver will still pause and think what they would answer even if you are not there to hear it.
Prefer explaining in context rather than explaining upfront.
“Show, don’t tell”? Nah.
More like “Engage, don’t show”.
(In the interest of time, I’m posting this without citations to avoid going down the rabbit hole of trying to find the best source for each claim, especially since I believe they’re pretty uncontroversial in the psychology / cognitive science literature. That said, I’d love to add references if you have good ones!)
When it does, this is called a usability cliff. ↩︎
I often say that optimizing UX for people with ADHD actually creates delightful experiences even for those with neurotypical attention spans.
Just because you could focus your attention on something you don’t find interesting doesn’t mean you enjoy it.
Yet another case of accessibility helping everyone! ↩︎
I mean, you can memorize anything if you try hard enough, but by optimizing teaching we can keep rote memorization down to the bare minimum. ↩︎
The CSS WG resolved to add if() to CSS, but that won’t be in browsers for a while.
What are our options in the meantime?
A couple days ago, I posted about the recent CSS WG resolution to add an if() function to CSS.
Great as it may be, this is still a long way off, two years if everything goes super smoothly, more if not.
So what can you do when you need conditionals right now?
You may be pleased to find that you’re not completely out of luck.
There is a series of brilliant, horrible hacks that enable you to expose the kinds of higher level custom properties that conditionals typically enable.
The instinctive reaction many developers have when seeing hacks like these is “Nice hack, but can’t possibly ever use this in production”.
This sounds reasonable on the surface (keeping the codebase maintainable is a worthy goal!) but
when examined deeply, it reflects the wrong order of priorities,
prioritizing developer convenience over user convenience.
The TAG maintains a Web Platform Design Principles document 1
that everyone designing APIs for the web platform is supposed to read and follow.
I’m a strong believer in having published Design Principles, for any product2.
They help stay on track, and remember what the big picture vision is, which is otherwise easy to lose sight of in the day to day minutiae.
One of the core principles in the document is the Priority of Constituencies.
The core of it is:
User needs come before the needs of web page authors, which come before the needs of user agent implementors, which come before the needs of specification writers, which come before theoretical purity.
Obviously in most projects there are far fewer stakeholders than for the whole web platform,
but the spirit of the principle still applies:
the higher the abstraction, the higher priority the user needs.
Or, in other words, consumers above producers.
For a more relatable example, in a web app using a framework like e.g. Vue and several Vue components,
the user needs of website users come before the needs of the web app developers,
which come before the needs of the developers of its Vue components,
which come before the needs of the Vue framework developers (sorry Evan :).
The TAG did not invent this principle; it is well known in UX and Product circles with a number of different wordings:
“Put the pain on those who can bear it”
Prefer internal complexity over external complexity
Why is that? Several reasons:
It is far easier to change the implementation than to change the user-facing API, so it’s worth making sacrifices to keep it clean from the get go.
Most products have way more users than developers, so this minimizes collective pain.
Internal complexity can be managed far more easily, with tooling or even good comments.
Managing complexity internally localizes it and contains it better.
Once the underlying platform improves, only one codebase needs to be changed to reap the benefits.
The corollary is that if hacks allow you to expose a nicer API to component users, it may be worth the increase in internal complexity (to a degree).
Just make sure that part of the code is well commented, and keep track of it so you can return to it once the platform has evolved to not require a hack anymore.
Like all principles, this isn’t absolute.
A small gain in user convenience is not a good tradeoff when it requires tremendous implementation complexity.
But it’s a good north star to follow.
As to whether custom properties are a better option to control styling than e.g. attributes,
I listed several arguments for that in my previous article.
Although, there are also cases where using custom properties is not a good idea…
In a nutshell, when the abstraction is likely to leak.
Ugliness is only acceptable if it’s encapsulated and not exposed to component users.
If there is a high chance they may come into contact with it, it might be a better idea to simply use attributes and call it a day.
Example callouts with three variants.
In many of the examples below, I use variants as the canonical example of a custom property that a component may want to expose.
However, if component consumers may need to customize each variant, it may be better to use attributes so they can just use e.g. [variant="success"] instead of having to understand whatever crazy hack was used to expose a --variant custom property.
And even from a philosophical purity perspective, variants are on the brink of presentational vs semantic anyway.
There is a host of hacks and workarounds that people have come up with to make up for the lack of inline conditionals in CSS,
with the first ones dating back to as early as 2015.
However, instead of using this to map a range to another range,
we use it to map two points to two other points,
basically the two extremes of both ranges: and to select and respectively.
Back then, min() and max() were not available, so he had to divide each factor by an obscure constant to make it equal to 1 when it was not 0.
Once abs() ships this will be even simpler (the inner max() is basically getting the absolute value of N - var(--foo))
Ana Tudor also wrote about this in 2018, in this very visual article: DRY Switching with CSS Variables.
Pretty sure she was also using boolean algebra on these too (multiplication = AND, addition = OR), but I couldn’t find the exact post.
This was independently discovered by Ana Tudor (c. 2017),
Jane Ori in April 2020 (who gave it the name “Space Toggle”),
David Khoursid (aka David K Piano) in June 2020 (he called it prop-and-lock),
and yours truly in Oct 2020 (I called it the --var: ; hack, arguably the worst name of the three 😅).
The core idea is that var(--foo, fallback) is actually a very limited form of conditional: if --foo is initial (or IACVT), it falls back to fallback, otherwise it’s var(--foo).
Furthermore, we can set custom properties (or their fallbacks) to empty values to get them to be ignored when used as part of a property value.
It looks like this:
One of the downsides of this version is that it only supports two states per variable.
Note how we needed two variables for the two states.
Another downside is that there is no way to specify a fallback if none of the relevant variables are set.
In the example above, if neither --if-success nor --if-warning are set, the background declaration will be empty, and thus become IACVT which will make it transparent.
In 2023, Roma Komarov expanded the technique into what he called “Cyclic Dependency Space Toggles” which
addresses both limitations:
it supports any number of states,
and allows for a default value.
The core idea is that variables do not only become initial when they are not set, or are explicitly set to initial,
but also when cycles are encountered.
Roma’s technique depends on this behavior by producing cycles on all but one of the variables used for the values.
It looks like this:
A downside of this method is that since the values behind the --variant-success, --variant-warning, etc variables are specific to the --variant variable
they need to be namespaced to avoid clashes.
A big downside of most of these methods (except for the animation-based ones) is that you need to specify all values of the property in one place,
and the declaration gets applied whether your custom property has a value or not,
which makes it difficult to layer composable styles leading to some undesirable couplings.
Roma Komarov’s “Layered Toggles” method addresses this for some cases
by allowing us to decouple the different values by taking advantage of Cascade Layers.
The core idea is that Cascade Layers include a revert-layer keyword that will cause the current layer to be ignored wrt the declaration it’s used on.
Given that we can use unnamed layers, we can simply user a @layer {} rule for every block of properties we want to apply conditionally.
This approach does have some severe limitations which made it rather unpractical for my use cases.
The biggest one is that anything in a layer has lower priority than any unlayered styles,
which makes it prohibitive for many use cases.
Also, this doesn’t really simplify cyclic toggles, you still need to set all values in one place.
Still, worth a look as there are some use cases it can be helpful for.
The core idea behind this method is that paused animations (animation-play-state: paused) can still be advanced by setting animation-delay to a negative value.
For example in an animation like animation: 100s foo, you can access the 50% mark by setting animation-delay: -50s.
It’s trivial to transform raw numbers to <time> values, so this can be abstracted to plain numbers for the user-facing API.
Here is a simple example to illustrate how this works:
This is merely to illustrate the core idea, having a --variant property that takes numbers is not a good API!
Though the numbers could be aliased to variables, so that users would set --variant: var(--success).
This technique seems to have been first documented by me in 2015, during a talk about …pie charts
(I would swear I showed it in an earlier talk but I cannot find it).
I never bothered writing about it, but someone else did, 4 years later.
To ensure you don’t get slightly interpolated values due to precision issues, you could also slap a steps() in there:
This is especially useful when 100 divided by your number of values produces repeating decimals,
e.g. 3 steps means your keyframes are at increments of 33.33333%.
A benefit of this method is that defining each state is done with regular declarations, not involving any weirdness,
and that .
It does also have some obvious downsides:
Values restricted to numbers
Takes over the animation property, so you can’t use it for actual animations.
So far all of these methods impose constraints on the API exposed by these custom properties:
numbers by the linear interpolation method and weird values that have to be hidden behind variables
for the space toggle and cyclic toggle methods.
In October 2022, Jane Ori was the first one to discover a method that actually allows us to support plain keywords,
which is what the majority of these use cases needs.
She called it “CSS-Only Type Grinding”.
Its core idea is if a custom property is registered (via either @property or CSS.registerProperty()),
assigning values to it that are not valid for its syntax makes it IACVT (Invalid at computed value time) and it falls back to its initial (or inherited) value.
She takes advantage of that to progressively transform keywords to other keywords or numbers through a series of intermediate registered custom properties,
each substituting one more value for another.
I was recently independently experimenting with a similar idea.
It started from a use case of one of my components where I wanted to implement a --size property with two values: normal and large.
Style queries could almost get me there, but I also needed to set flex-flow: column on the element itself when --size was large.
The end result takes N + 1 @property rules, where N is the number of distinct values you need to support.
The first one is the rule defining the syntax of your actual property:
We can also transform keywords to numbers, by replacing successive keywords with <integer> in the syntax, one at a time, with different initial values each time.
Here is the --variant example using this method:
In 2018, Roma Komarov discovered another method that allows plain keywords to be used as the custom property API,
forgot about it, then rediscovered it in June 2023 😅.
He still never wrote about it, so these codepens are the only documentation we have.
It’s a variation of the previous method: instead of using a single @keyframes rule and switching between them via animation-delay,
define several separate @keyframes rules, each named after the keyword we want to use:
Every one of these methods has limitations, some of which are inerent in its nature, but others can be improved upon.
In this section I will discuss some improvements that me or others have thought of.
I decided to include these in a separate section, since they affect more than one method.
A big downside with the animation-based approaches (3 and 5) is the place of animations in the cascade:
properties applied via animation keyframes can only be overridden via other animations or !important.
One way to deal with that is to set custom properties in the animation keyframes, that you apply in regular rules.
To use the example from Variable animation name:
Note that you can combine the two approaches (variable animation-name and paused animations)
when you have two custom properties where each state of the first corresponds to N distinct states of the latter.
For example, a --variant that sets colors, and a light/dark mode within each variant that sets different colors.
Another downside of the animation-based approaches is that they take over the animation property.
If authors want to apply an animation to your component, suddenly a bunch of unrelated things stop working, which is not great user experience.
There isn’t that much to do here to prevent this experience, but you can at least offer a way out:
instead of defining your animations directly on animation, define them on a custom property, e.g. --core-animations.
Then, if authors want to apply their own animations, they just make sure to also include var(--core-animations) before or after.
Many of the approaches above are based on numerical values, which are then mapped to the value we actually want.
For numbers or dimensions, this is easy.
But what about colors?
I linked to Noah Liebman’s post above on recursive color-mix(),
where he presents a rather complex method to select among a continuous color scale based on a 0-1 number.
However, if you don’t care about any intermediate colors and just want to select among a few discrete colors, the method can be a lot simpler.
Simple enough to be specified inline.
Let me explain: Since color-mix() only takes two colors, we need to nest them to select among more than 2, no way around that.
However, the percentages we calculate can be very simple: 100% when we want to select the first color and 0% otherwise.
I plugged these numbers into my CSS range mapping tool
(example) and noticed a pattern:
If we want to output 100% when our variable (e.g. --variant-index) is N-1 and 0% when it’s N, we can use 100% * (N - var(--variant-index)).
And here is a more realistic one, using the Type Grinding method to transform keywords to numbers, and then using the above technique to select among 4 colors for backgrounds and borders (codepen).
There are two components to each method: the input values it supports, i.e. your custom property API that you will expose, e.g. numbers, keywords, etc.,
and the output values it supports (<dimension>, keywords, etc.).
If we can transform the input values of one method to the input values of another, we can mix and match approaches to maximize flexibility.
For example, we can use type grinding to transform keywords to numbers, and then use paused animations or binary linear interpolation to select among a number of quantitative values based on that number.
Keywords → Numbers
Type grinding
Numbers → Keywords
We can use paused animations to select among a number of keywords based on a number (which we transform to a negative animation-delay).
Impractical outside of Shadow DOM due to name clashes
Takes over animation property
Cascade weirdness
The most important consideration is the API we want to expose to component users.
After all, exposing a nicer API is the whole point of this, right?
If your custom property makes sense as a number without degrading usability
(e.g. --size may make sense as a number, but small | medium | large is still better than 0 | 1 | 2),
then Binary Linear Interpolation is probably the most flexible method to start with,
and as we have seen in Combining approaches section, numbers can be converted to inputs for every other method.
Between the two, Type Grinding is the one providing the best encapsulation,
since it relies entirely on custom properties and does not hijack any native properties.
Unfortunately, the fact that @property is not yet supported in Shadow DOM throws a spanner in the works,
but since these intermediate properties are only used for internal calculations,
we can just give them obscure names and insert them in the light DOM.
Phew! That was a long one. If you’re aware of any other techniques, let me know so I can add them.
And I think after all of this, if you had any doubt that we need if() in CSS,
the sheer number and horribleness of these hacks must have dispelled it by now. 😅
Thanks to Roma Komarov for reviewing earlier drafts of this article.
I’ve always thought this was our most important deliverable, and pushed for prioritizing it. Recently, I even became editor of it. 🙃 ↩︎
I’m using product here in the general sense, of any software product, technology, or API, not just for-profit or commercial ones. ↩︎
Last week, the CSS WG resolved to add an inline if() to CSS.
But what does that mean, and why is it exciting?
Last week, we had a CSS WG face-to-face meeting in A Coruña, Spain.
There is one resolution from that meeting that I’m particularly excited about:
the consensus to add an inline if() to CSS.
While I was not the first to propose an inline conditional syntax,
I did try and scope down the various nonterminating discussions into an MVP that can actually be implemented quickly,
discussed ideas with implemenators,
and eventually published a concrete proposal and pushed for group resolution.
Quite poetically, the relevant discussion occurred on my birthday, so in a way, I got if() as the most unique birthday present ever. 😀
This also comes to show that proposals being rejected is not the end-all for a given feature.
It is in fact quite common for features to be rejected for several times before they are accepted: CSS Nesting, :has(), container queries were all simply the last iteration in a series of rejected proposals.
if() itself was apparently rejected in 2018 with very similar syntax to what I proposed.
What was the difference? Style queries had already shipped, and we could simply reference the same syntax for conditions (plus media() and supports() from Tab’s @when proposal) whereas in the 2018 proposal how conditions would work was largely undefined.
I posted about this on a variety of social media, and the response by developers has been overwhelmingly positive:
I even had friends from big companies writing to tell me their internal Slacks blew up about it.
This proves what I’ve always suspected, and was part of the case I made to the CSS WG: that this is a huge pain point.
Hopefully the amount and intensity of positive reactions will help browsers prioritize this feature and add it to their roadmaps earlier rather than later.
Across all these platforms, besides the “I can’t wait for this to ship!” sentiment being most common,
there were a few other recurring questions and a fair bit of confusion that I figured were worth addressing.
Quite the opposite — if()complementsstyle queries.
If you can do something with style queries, by all means, use style queries — they are almost certainly a better solution.
But there are things you simply cannot do with style queries.
Let me explain.
The motivating use case was that components (in the broader sense) often need to define higher level custom properties,
whose values are not just used verbatim in declarations, but that set unrelated values on a variety of declarations.
For example, consider a --variant custom property (inspired from Shoelace’s variant attribute).
It could look like this:
This needs to set background colors, border colors, text colors, icons, etc.
In fact, it’s actual value is not used verbatim anywhere, it is only used to set other values.
Style queries get us halfway there:
.callout { /* or :host if in Shadow DOM */
	@container (style(--variant: success)) {
		&::before {
			content: var(--icon-success);
			color: var(--color-success);
		}
	}

	/* (other variants) */
}
However, style queries only work on descendants.
We cannot do this:
Often the declarations we need to set on the element itself are very few, sometimes even just one.
However, even one is one too many and makes using custom properties untenable for many (possibly most) higher level custom property use cases.
As a result, component libraries end up resorting to presentational attributes like pill, outline, size, etc.
While presentational attributes may seem fine at first glance, or even better for DX (fewer characters — at least compared to setting a variable per element),
they have several usability issues:
Reduced flexibility
They cannot be conditionally applied based on selectors, media queries, etc.
Changing them requires more JS.
If they are used within another component, you’re SOL, whereas with (inheritable) custom properties, you can set the property on the parent component and it will inherit down.
Verbosity
They have to be applied to individual instances, and cannot be inherited.
Even if one uses some form of templating or componentization to reduce duplication,
they still have to wade through these attributes when debugging with dev tools.
Lack of consistency
Since almost every mature component also supports custom properties,
users have to remember which styling is done via attributes and which via custom properties.
The distinction is often arbitrary, as it’s not driven by use cases, but implementation convenience.
With if(), the above example becomes possible, albeit with worse ergonomics than style queries since it cannot cascade
(though I do have a proposal to allow it to — plus all other IACVT declarations):
While this was the primary use case, it turned out that it’s pretty easy to also make media queries and supports conditions part of if()’s conditional syntax.
And since it’s a function, its arguments (including the condition!) can be stored in other custom properties.
This means you can do things like this:
:root {
	--xl: media(width > 1600px);
	--l: media (width > 1200px);
	--m: media (width > 800px);
}
Believe it or not, that was a real question I got 😅.
No, it’s not in browsers yet, and it won’t be for a while.
The most optimistic estimate is 2 years or so, if the process doesn’t stall at any point (as it often does).
All we have is consensus to work on the feature.
The next steps are:
Reach consensus on the syntax of the feature.
Syntax debates can often take a very long time, because syntax is an area where everyone has opinions.
The current debates revolve around:
What separators to use between the condition and the branches?
Get the first implementation.
Often that is the hardest part. Once one browser implements, it is far easier to get the others on board.
Get it shipped across all major browsers.
I do have a page where I track some of my standards proposals which should help illuminate what the timeline looks like for each of these steps.
In fact, you can track the progress of if() specifically there too.
Many responses were along the lines of “Wow, CSS is finally getting conditionals!”.
Folks… CSS had conditionals from the very beginning.
Every selector is essentially a conditional!
In addition:
@media and @supports rules are conditionals. And let’s not forget @container.
var(--foo, fallback) is a limited type of conditional (essentially if(style(--foo: initial) ? var(--foo) : fallback)),
hence why it’s the basis of most workarounds for emulating inline conditionals.
A widespread misconception is that non-linear logic (conditionals, loops) makes a language imperative.
Declarative vs imperative is not about logic, but level of abstraction.
Are we describing the goal or how to achieve it?
In culinary terms, a recipe is imperative, a restaurant menu is declarative
Conditional logic can actually make a language more declarative if it helps describe intent better.
A very common type of response was around whether CSS is now a programming language
(either asking whether it is, or asserting that it now is).
To answer that, one first needs to answer what a programming language is.
If it’s imperativeness, then no, CSS is not a programming language.
But neither are many actual programming languages!
But a deeper question is, why does it matter?
Is it because it legitimizes choosing to specialize in CSS?
It is because you can then be considered a programmer even if you only write HTML & CSS?
If this only matters for optics, then we should fix the issue at its core and fight to legitimize CSS expertise regardless of whether CSS is a programming language.
After all, as anyone who knows several well-respected programming languages and CSS can attest, CSS is far harder to master.
Great as all this may be, it won’t be in browsers for a while.
What can we do right now?
I wrote Part 2 exactly about that: CSS Conditionals, now?
Out of all the CSS features I have designed,
Relative Colors aka Relative Color Syntax (RCS) is definitely among the ones I’m most proud of.
In a nutshell, they allow CSS authors to derive a new color from an existing color value by doing arbitrary math on color components
in any supported color space:
--color-lighter: hsl(from var(--color) h s calc(l * 1.2));
--color-lighterer: oklch(from var(--color) calc(l + 0.2) c h);
--color-alpha-50: oklab(from var(--color) l a b / 50%);
The elevator pitch was that by allowing lower level operations they provide authors flexibility on how to derive color variations,
giving us more time to figure out what the appropriate higher level primitives should be.
Even if my prediction is off, it already is available to 83% of users worldwide,
and if you sort its caniuse page by usage,
you will see the vast majority of the remaining 17% doesn’t come from Firefox,
but from older Chrome and Safari versions.
I think its current market share warrants production use today,
as long as we use @supports to make sure things work in non-supporting browsers, even if less pretty.
Most Relative Colors tutorials
revolve around its primary driving use cases:
making tints and shades or other color variations by tweaking a specific color component up or down,
and/or overriding a color component with a fixed value,
like the example above.
While this does address some very common pain points,
it is merely scratching the surface of what RCS enables.
This article explores a more advanced use case, with the hope that it will spark more creative uses of RCS in the wild.
One of the big longstanding CSS pain points is that it’s impossible to automatically specify a text color that is guaranteed to be readable on arbitrary backgrounds,
e.g. white on darker colors and black on lighter ones.
Why would one need that?
The primary use case is when colors are outside the CSS author’s control.
This includes:
User-defined colors. An example you’re likely familiar with: GitHub labels. Think of how you select an arbitrary color when creating a label and GitHub automatically picks the text color — often poorly (we’ll see why in a bit)
Colors defined by another developer. E.g. you’re writing a web component that supports certain CSS variables for styling.
You could require separate variables for the text and background, but that reduces the usability of your web component by making it more of a hassle to use.
Wouldn’t it be great if it could just use a sensible default, that you can, but rarely need to override?
GitHub Labels are an example where colors are user-defined, and the UI needs to pick a text color that works with them.
GitHub uses WCAG 2.1 to determine the text color, which is why (as we will see in the next section) the results are often poor.
Even in a codebase where every line of CSS code is controlled by a single author,
reducing couplings can improve modularity and facilitate code reuse.
The good news is that this is not going to be a pain point for much longer.
The CSS function contrast-color() was designed to address exactly that.
This is not new, you may have heard of it as color-contrast() before, an earlier name.
I recently drove consensus to scope it down to an MVP that addresses the most prominent pain points and can actually ship soonish,
as it circumvents some very difficult design decisions that had caused the full-blown feature to stall.
I then added it to the spec per WG resolution, though some details still need to be ironed out.
Glorious, isn’t it?
Of course, soonish in spec years is still, well, years.
As a data point, you can see in my past spec work that with a bit of luck (and browser interest), it can take as little as 2 years to get a feature shipped across all major browsers after it’s been specced.
When the standards work is also well-funded,
there have even been cases where a feature went from conception to baseline in 2 years,
with Cascade Layers being the poster child for this:
proposal by Miriam in Oct 2019,
shipped in every major browser by Mar 2022.
But 2 years is still a long time (and there are no guarantees it won’t be longer).
What is our recourse until then?
As you may have guessed from the title, the answer is yes.
It may not be pretty, but there is a way to emulate contrast-color() (or something close to it) using Relative Colors.
In the following we will use the OKLCh color space, which is the most perceptually uniformpolar color space that CSS supports.
Let’s assume there is a Lightness value above which black text is guaranteed to be readable regardless of the chroma and hue,
and below which white text is guaranteed to be readable.
We will validate that assumption later, but for now let’s take it for granted.
In the rest of this article, we’ll call that value the threshold and represent it as Lthreshold.
We will compute this value more rigously in the next section (and prove that it actually exists!),
but for now let’s use 0.7 (70%).
We can assign it to a variable to make it easier to tweak:
--l-threshold: 0.7;
Let’s work backwards from the desired result.
We want to come up with an expression that is composed of widely supported CSS math functions,
and will return 1 if L ≤ Lthreshold and 0 otherwise.
If we could write such an expression, we could then use that value as the lightness of a new color:
--l: /* ??? */;
color: oklch(var(--l) 0 0);
How could we simplify the task?
One way is to relax what our expression needs to return.
We don’t actually need an exact 0 or 1
If we can manage to find an expression that will give us 0 when L > Lthreshold
and > 1 when L ≤ Lthreshold,
we can just use clamp(0, /* expression */, 1) to get the desired result.
One idea would be to use ratios, as they have this nice property where they are > 1 if the numerator is larger than the denominator and ≤ 1 otherwise.
The ratio of is < 1 for L ≤ Lthreshold and > 1 when L > Lthreshold.
This means that will be a negative number for L < Lthreshold and a positive one for L > Lthreshold.
Then all we need to do is multiply that expression by a huge (in magnitude) negative number so that when it’s negative the result is guaranteed to be over 1.
One worry might be that if L gets close enough to the threshold we could get a number between 0 - 1,
but in my experiments this never happened, presumably since precision is finite.
Update (October 2026) Since sign() is Baseline 2025 we can simplify this expression further:
The last piece of the puzzle is to provide a fallback for browsers that don’t support RCS.
Update (October 2026) RCS is now Baseline 2024, and supported in 93.5% of browsers, so I unless you have an unusually wide browser support target, I think you can skip this.
We can use @supports with any color property and any relative color value as the test, e.g.:
In the previous section we’ve made a pretty big assumption:
That there is a Lightness value (Lthreshold) above which black text is guaranteed to be readable regardless of the chroma and hue,
and below which white text is guaranteed to be readable regardless of the chroma and hue.
But does such a value exist?
It is time to put this claim to the test.
When people first hear about perceptually uniform color spaces like Lab, LCH or their improved versions, OkLab and OKLCH,
they imagine that they can infer the contrast between two colors by simply comparing their L(ightness) values.
This is unfortunately not true, as contrast depends on more factors than perceptual lightness.
However, there is certainly significant correlation between Lightness values and contrast.
At this point, I should point out that while most web designers are aware of the WCAG 2.1 contrast algorithm,
which is part of the Web Content Accessibility Guidelines and baked into law in many countries,
it has been known for years that it produces extremely poor results.
So bad in fact that in some tests it performs almost as bad as random chance for any color that is not very light or very dark.
There is a newer contrast algorithm, APCA that produces far better results,
but is not yet part of any standard or legislation, and there have previously been some bumps along the way with making it freely available to the public (which seem to be largely resolved).
Some text
Some text
Which of the two seems more readable?
You may be surprised to find that the white text version fails WCAG 2.1,
while the black text version even passes WCAG AAA!
So where does that leave web authors?
In quite a predicament as it turns out.
It seems that the best way to create accessible color pairings right now is a two step process:
Use APCA to ensure actual readability
Compliance failsafe: Ensure the result does not actively fail WCAG 2.1.
I ran some quick experiments using Color.js
where I iterate over the OKLCh reference range (loosely based on the P3 gamut)
in increments of increasing granularity and calculate the lightness ranges for colors where white was the “best” text color (= produced higher contrast than black) and vice versa.
I also compute the brackets for each level (fail, AA, AAA, AAA+) for both APCA and WCAG.
I then turned my exploration into an interactive playground where you can run the same experiments yourself,
potentially with narrower ranges that fit your use case, or with higher granularity.
Calculating lightness ranges and contrast brackets for black and white on different background colors.
Note that these are the min and max L values for each level.
E.g. the fact that white text can fail WCAG when L ∈ [62.4%, 100%] doesn’t mean that every color with L > 62.4% will fail WCAG,
just that some do.
So, we can only draw meaningful conclusions by inverting the logic:
Since all white text failures are have an L ∈ [62.4%, 100%],
it logically follows that if L < 62.4%, white text will pass WCAG
regardless of what the color is.
By applying this logic to all ranges, we can draw similar guarantees for many of these brackets:
0% to 52.7%
52.7% to 62.4%
62.4% to 66.1%
66.1% to 68.7%
68.7% to 71.6%
71.6% to 75.2%
75.2% to 100%
Compliance WCAG 2.1
white
✅ AA
✅ AA
black
✅ AA
✅ AAA
✅ AAA
✅ AAA
✅ AAA
✅ AAA+
Readability APCA
white
😍 Best
😍 Best
😍 Best
🙂 OK
🙂 OK
black
🙂 OK
🙂 OK
😍 Best
Contrast guarantees we can infer for black and white text over arbitrary colors.
OK = passes but is not necessarily best.
You may have noticed that in general, WCAG has a lot of false negatives around white text,
and tends to place the Lightness threshold much lower than APCA.
This is a known issue with the WCAG algorithm.
Therefore, to best balance readability and compliance, we should use the highest threshold we can get away with.
This means:
If passing WCAG is a requirement, the highest threshold we can use is 62.3%.
If actual readability is our only concern, we can safely ignore WCAG and pick a threshold somewhere between 68.7% and 71.6%, e.g. 70%.
Here’s a demo so you can see how they both play out.
Edit the color below to see how the two thresholds work in practice, and compare with the actual contrast brackets, shown on the table next to (or below) the color picker.
Your browser does not support Relative Color Syntax, so the demo below will not work.
This is what it looks like in a supporting browser:
Lthreshold = 62.3%
Lthreshold = 70%
Actual contrast ratios
Text color
APCA
WCAG 2.1
White
Black
Avoid colors marked “P3+”, “PP” or “PP+”, as these are almost certainly outside your screen gamut,
and browsers currently do not gamut map properly, so the visual result will be off.
Note that if your actual color is more constrained (e.g. a subset of hues or chromas or a specific gamut),
you might be able to balance these tradeoffs better by using a different threshold.
Run the experiment yourself with your actual range of colors and find out!
Here are some examples of narrower ranges I have tried and the highest threshold that still passes WCAG 2.1:
It is particularly interesting that the threshold is improved to 64.5% by just ignoring colors that are not actually displayable on modern screens.
So, assuming (though sadly this is not an assumption that currently holds true) that browsers prioritize preserving lightness when gamut mapping, we could use 64.5% and still guarantee WCAG compliance.
You can even turn this into a utility class that you can combine with different thesholds:
When colors have sufficiently different lightness values (as happens with white or black text),
humans disregard chromatic contrast (the contrast that hue/colorfulness provide)
and basically only use lightness contrast to determine readability.
This is why L can be such a good predictor of whether white or black text works best.
But while OkLCh lightness is meant to closely track human lightness perception, many use cases require strict WCAG 2.0 compliance, due to legal or organizational requirements.
WCAG 2 color contrast guidelines actually use relative luminance rather than lightness (L) to determine readability.
If you absolutely need to meet WCAG, fear not, you can still use this!
Turns out, relative luminance is just the Y component in the XYZ D65 color space, which is natively supported in CSS.
So, instead of doing the math in oklch(), we’ll just do them in color(xyz) (or color(xyz-d65), same thing).
where (L_1) is the relative luminance of the lighter color and (L_2) is the relative luminance of the darker color.
Solving for the threshold where white and black tie, we get:
One complication is that white is not color(xyz 1 1 1) but color(xyz 0.9505 1 1.089) (the D65 white point), but aside from that it’s pretty straightforward:
This also has the advantage that it more closely tracks contrast-color() as currently implemented in browsers.
The big downside being the well-known problems with the WCAG 2 contrast algorithm, established above.
This guarantees passing WCAG AA. It does not guarantee WCAG AAA, since AAA (7:1) is unreachable for Y in (0.1, 0.3) with either white or black.
That’s inherent to WCAG, not to this code.
If you don’t have a hard requirement to meet WCAG 2.0 contrast ratios, I would not recommend using this as it produces suboptimal results compared to the oklch() formula.
This is only a start.
I can imagine many directions for improvement.
For example, we currently only calculate thresholds for white and black text.
However, in real designs, we rarely want pure black text.
How would this extend to darker tints of the background color?
tl;dr:Overfitting happens when solutions don’t generalize sufficiently and is a hallmark of poor design.
Eigensolutions are the opposite: solutions that generalize so much they expose links between seemingly unrelated use cases.
Designing eigensolutions takes a mindset shift from linear design to composability.
In product literature, the design process looks a bit like this:
This works great with the kinds of transactional processes (marketplaces, social media, search engines, etc) most product literature centers around,
but can fall apart when designing creative tools (developer tools, no-code tools, design tools, languages, APIs etc.),
as there are fundamental differences1 between the two:
In transactional processes, users have clearly defined goals, and the task is highly specialized
(e.g. “Go to work”, “Order takeout”, “Find accommodation for my upcoming trip”) and can often be modeled as a linear process.
In creator tools, use cases vary wildly, goals are neither linear, nor clearly defined, and may even change throughout the session.
Creator tools typically ship knowingly addressing only a percentage of their key use cases — otherwise they would never ship at all.
It’s all about balancing UX, use case coverage, and design/implementation effort.
The floor is the minimum level of knowledge users need to create something useful.
The ceiling refers to the extent of what can be created.
I think that vocabulary generalizes more broadly to creator tools, and can be a useful UX metric.
Programming languages tend to have high ceiling, but also a high floor: You make anything, but it requires months or years of training,
whereas domain specific GUI builders like Google Forms have a low floor, but also a low ceiling: Anyone can start using them with no training, but you can also only make very specific kinds of things with them.
A product that combines a low floor with a high ceiling is the unicorn of creator tools.
Therefore, most product work in creator tools centers around either reducing the floor (making things easier), or increasing the ceiling (making things possible).
Which one of the two takes priority depends on various factors (user research, product philosophy, strategy etc.), and could differ by product area or even by feature.
In creator tools, use cases tend to accumulate at a much faster rate than they can be addressed, especially in the beginning.
Therefore we end up with what I call a “use case backlog”: a list of use cases that are within scope, but we cannot yet address
due to lack of resources, good solutions, or both.
The more general purpose and the more ambitious the tool is, the higher the rate of accumulation, since the pool of use cases is naturally larger.
Pain points get processed into use cases, which accumulate in the use case backlog
Unlike the linear design process of transactional processes,
the design process for creator tools often consists of matching use cases to solutions, which can happen before, during, or after idea conception.
A product may include both transactional processes and creator tools,
e.g. Instagram is a social media platform (transactional) with a photo editor (creator tool).
Although these tend to be more domain-specific creator tools, which are less good examples for the concepts discussed here.
Shishir Mehrotra (of Coda) wrote about the importance of “Eigenquestions” when framing problems, a term he coined, inspired from his math background:
the eigenquestion is the question where, if answered, it likely answers the subsequent questions as well.
This inspired me to name a symmetrical concept I’ve been pondering for a while: Eigensolutions.
The eigensolution is a solution that addresses several key use cases, that previously appeared unrelated.
An eigensolution is the polar opposite of overfitting.
Overfitting happens when the driving use cases behind a solution are insufficiently diverse,
so the solution ends up being so specific it cannot even generalize to use cases that are clearly related.
Overfitting is one of the worst things that can happen during the design process.
It is a hallmark of poor design that leads to feature creep and poor user experiences.
It forces product teams to keep adding more features to address the use cases that were not initially addressed.
The result is UI clutter and user confusion, as from the user’s perspective, there are now multiple distinct features that solve subtly different problems.
This is all nice and dandy, but how do we design and ship eigensolutions?
Do we just sit around waiting for inspiration to strike?
Well, we could, but it would be a pretty poor use of resources. :)
Instead, it takes a mindset shift, from the linear Use case → Idea → Solution process to composability.
Rather than designing a solution to address only our driving use cases,
step back and ask yourself:
can we design a solution as a composition of smaller, more general features, that could be used together to address a broader set of use cases?
In many cases the features required for that composition are already implemented and are just missing one piece: our eigensolution.
In other cases composability may require more than one new feature, but the result can still be a net win since these features are useful on their own and can ship independently.
A composability mindset requires being aware of pain points and use cases across many different product areas.
This becomes harder in larger organizations, where product teams are highly specialized.
It’s not impossible, but requires conscious effort to cross-polinate all the way down,
rather than completely depending on higher levels of the hierarchy to maintain a bird’s eye view of the product.
It’s also important to note that it’s a spectrum, not a binary: overfitting and eigensolutions are just its two opposite ends.
Eigensolutions do not come along every day, and do not even exist for all problems.
While it’s important to actively guard against overfitting by making sure solutions are validated by many diverse use cases,
going too far the other side and chasing a general solution for every problem is also a poor use of resources.
Instead, I think a happy medium is to try and be on the right side of the spectrum:
Good design is only part of the work; but without shipping, even the most well designed feature is a pointless document.
Contrary to what you may expect, eigensolutions can actually be quite hard to push to stakeholders:
Due to their generality, they often require significantly higher engineering effort to implement.
Quick-wins are easier to sell: they ship faster and add value sooner.
In my 11 years designing web technologies, I have seen many beautiful, elegant eigensolutions be vetoed due to implementation difficulties in favor of far more specific solutions — and often this was the right decision, it’s all about the cost-benefit.
Eigensolutions tend to be lower level primitives, which are more flexible, but can also involve higher friction to use than a solution that is tailored to a specific use case.
In many cases, layering can resolve or mitigate both of these issues.
My north star product design principle is “Common things should be easy, complex things should be possible” (paraphrasing Alan Kay — because common things are not always simple, but it’s common things you want to optimize for),
which in essence is another way of aiming for low floors and high ceilings.
Eigensolutions tend to be lower level primitives.
They enable a broad set of use cases, but may not be the most learnable or efficient way to implement all of them, compared to a tailored solution.
In other words, they make complex things possible, but do not necessarily make common things easy.
Some do both, in which case congratulations, you’ve got an even bigger unicorn! You can skip this section. :)
However, this is one of the rare times in life where we can have our cake and eat it too.
Instead of implementing tailored solutions ad-hoc (risking overfitting),
they can be implemented as shortcuts: higher level abstractions using the lower level primitive.
Done well, shortcuts provide dual benefit: not only do they reduce friction for common cases,
they also serve as teaching aids for the underlying lower level feature.
This offers a very smooth ease-of-use to power curve:
if users need to go further than what the shortcut provides, they can always fall back on the lower level primitive to do so.
We know that tweaking is easier than creating from scratch,
so even when users use that escape hatch, they can tweak what they had created with the higher level UI, rather than starting from scratch.
This combined approach both reduces the floor and increases the ceiling!
Coda is a product I’ve been using a lot in the last few months.
It has replaced Google Docs, Google Sheets, and a few more niche or custom apps I was using.
Its UI is full of examples of this pattern, but for the sake of brevity, I will focus on one: table filtering.
At first, the filtering UI is pretty high level, designed around common use cases:
Also note the nice touch of “And” not just being informative, but also a control that allows the user to edit the logic used to combine multiple filters.
For the vast majority of use cases (I would guess >95%), the UI is perfectly sufficient.
If you don’t need additional flexibility, you may not even notice the little f button on the top right.
But for those that need additional power it can be a lifesaver.
That little f indicates that behind the scenes, the UI is actually generating a formula for filtering.
Clicking it opens a formula editor, where you can edit the formula directly:
I suspect that even for the use cases that require that escape hatch, a small tweak to the generated formula is all that is necessary.
The user may have not been able to write the formula from scratch, but tweaking is easier.
As one data point, the one time I used this, it was just about using parentheses to combine AND and OR differently than the UI allowed.
And as a bonus, the app can collect metrics about what users do with the lower level feature and use that to improve the higher level UI.
It’s a win-win all around.
In an ideal world, lower level primitives and higher level abstractions would be designed and shipped together.
However, engineering resources are typically limited, and it often makes sense to ship one before the other,
so we can provide value sooner.
This can happen in either direction:
Lower level primitive first.
Shortcuts to make common cases easy can ship at a later stage,
and demos and documentation to showcase common “recipes” can be used as a stopgap meanwhile.
This prioritizes use case coverage over optimal UX, but it also allows collecting more data,
which can inform the design of the shortcuts implemented.
Higher level abstraction first, as an independent, ostensibly ad hoc feature.
Then later, once the lower level primitive ships, it is used to “explain” the shortcut, and make it more powerful.
This prioritizes optimal UX over use case coverage:
we’re not covering all use cases, but for the ones we are covering, we’re offering a frictionless user experience.
But which one?
As with most things in life, the answer is “it depends”.
A few considerations are:
How many shortcuts do we need? What percentage of use cases do they cover?
How much harder is it to use the lower level primitive directly? Are we certain we will need to provide shortcuts, or is it possible it may be sufficient on its own?
Which one are we more confident about?
How much engineering effort does the lower level primitive require and how does it compare to implementing the shortcuts as ad hoc features?
Do we have extensibility mechanisms in place for users to create and share their own higher level abstractions over the lower level feature?
Outside of specific cases,
it’s also good to have a design principle in place about which way is generally favored, which is part of the product philosophy
(the answer to the eigenquestion:
“Are we optimizing for flexibility or learnability?”)
and can be used to fall back on if weighing tradeoffs ends up inconclusive.
Note that even when we don’t think the eigensolution is implementable,
it can still be useful as a north star UI and designing the tailored solutions as special cases of it can still be a good idea.
In the web platform we’ve gone back and forth on this a lot.
In the beginning, the Web skewed towards shipping higher level abstractions.
It had a low floor, but also a relatively low ceiling: many capabilities required browser plugins, or desktop applications.
The Extensible Web Manifesto was created as a reaction,
urging standards groups to design low level primitives first.
For a while, this became the gold standard and many new features were very low level.
This filled some necessary gaps in the platform, but since resources are limited, the layering was often missed, resulting in only low level primitives which were a pain to use.
More recently, we’ve been recommending a more balanced approach, where tradeoffs are evaluated on a case by case basis.
Suppose we were working on a fictional product that is an improvement over spreadsheets, let’s call it TableSoda.
It has several features that make it more powerful and user-friendly than spreadsheets:
It allows users to have multiple tables and define formulas or datatypes for a whole column
It also supports references from a cell of one table to a row of another table.
Its formula language supports operations on entire columns, and can return entire rows from other tables.
Each table can be shared with different people, but a given user can either see/edit all the rows and columns of a table, or none.
Pivot tables: tables that display stats about the usage of a value in another table (usually counts but also sum, min, max, average, etc.)2
Unions of multiple tables. For example, combining a table of debits and a table of credits into a table of transactions.
Vertical splitting: Multiple tables augmenting the same data with different metadata. For example, a table of product features, another table that scores these features on various factors, and lastly, a table of 👍🏼 reactions by different team members about each feature.
Granular access control, by row(s) or column(s). For example, a table of tasks where each row is assigned to a different team member, and each team member can only see their own tasks and only edit the status column.
With the traditional PM mindset, we would prioritize which one(s) of these is most important to solve, design a few possible solutions, evaluate tradeoffs between them.
Over time, we may end up with a pivot table feature, a table union feature, a table vertical split feature, a row-level access control feature, and a column-level access control feature.
These features would not necessarily be overfitting, they may solve their respective use cases quite well.
But they also add a lot of complexity to the product.
Instead, we would still prioritize which one to address first, but with the mindset of decomposing it to its essential components
and addressing those (note that there may be many different possible decompositions).
Suppose we decide that we want to prioritize pivot tables.
A pivot table is essentially2:1:
A table of all unique values in the source column
For each unique value, columns with its count, sum, etc. in the source column
Users can already count the number of values in a column using formulas, and they can also use a unique() formula to get a list of unique values in a column.
So what prevents them from creating their own pivot tables?
There is no way to create dynamic tables in TableSoda, rows can only be added by users.
What if we could populate a table’s rows via a formula? The formula values could be used either for one column or multiple (if it returns a list of objects).
Formula-populated tables not only solve our driving use case, but all of the above:
Unions can be implemented by using a formula to concatenate the rows of multiple tables into a single list.
Vertical splitting can be implemented by using a formula to keep the rows of multiple tables in sync with a master table
Granular access control can be implemented by having a table with different permissions that is populated using a formula that filters the rows and/or columns of the source table.
It’s an eigensolution!
Note that our eigensolution is not the end for any of our use cases.
It makes many things possible, but none of them are easy.
Some of them are common enough to warrant a shortcut: UI that generates the formula needed.
For others, our solution is more of a workaround than a primary solution, and the search for a primary solution continues, potentially with reduced prioritization.
And others don’t come up often enough to warrant anything further.
But even if we still need to smoothen the ease-of-use to power curve, making things possible bought us a lot more time to make them easy.
The most discerning of readers may have noticed that despite the name eigensolution, it’s still all about the use cases:
eigensolutions just expose links between use cases that may have been hard to detect, but seem obvious in retrospect.
In the example above, one could have seen in advance that all of these use cases were fundamentally about dynamically populating tables.
But wasn’t it so much easier to see in retrospect?
Requiring all use cases to precede any design work can be unnecessarily restrictive,
as frequently solving a problem improves our understanding of the problem.
I believe it’s best to think of a use case as a test case to see if your basic tools are working. What’s missing from the toolbox? What are the limits of what’s available? What 4 use cases would open up with the addition of one more tool?
Use cases should be applied after design is done — to check if the tools available can accomplish the job. As a starting point, they put you in a mindset to overfit. This is especially dangerous because users will often tell you they love it in concept testing. “Ah yes, here is my process, represented in pictures!” But it’s only when you actually try to use the tool — hold the thing in your hands — that there’s a hundred things you need it to do that it doesn’t. It’s not flexible — it’s a series of menus and disappointed feature requirements.
Joe argues for using use cases only at the end, to validate a design, as he believes that starting from use cases leads puts you in a mindset to overfit.
This is so much the polar opposite of current conventional wisdom, that many would consider it heresy.
I think that also imposes unnecessary constraints on the design process.
I personally favor a more iterative process:
Collect as many diverse use cases as possible upfront to drive the design
Additional use cases are used to refine the design until it stabilizes
Even more at the end to validate it further.
If you’re on the right path, additional use cases will smoothly take you from refinement to validation as the design stabilizes.
If you’re not on the right path, they will expose fundamental flaws in your design and show you that you need to start over.
This has some similarities to test-driven development in engineering:
engineers start with a few test cases before writing any code,
then add more as they go to make sure everything works as expected.
But if someone else’s design thinking works best with using use cases only for validation, more power to them!
What matters is that the outcome is a solution that addresses a broad set of use cases in a way users can understand and use.
We can probably all agree that no proposal should be considered without being rigorously supported by use cases.
It is not enough for use cases to exist;
they need to be sufficiently diverse and correspond to real user pain points that are common enough to justify the cost of adding a new feature.
But whether use cases drove the design, were used to validate it, or a mix of both is irrelevant,
and requiring one or the other imposes unnecessary constraints on the design process.
Thanks to Marily Nika and Elika Etemad for providing feedback on an earlier draft of this post.
I hesitantly published this article right before the 2023 winter break.
I say hesitantly, because it was a departure from my usual content, and I wasn’t sure how it would be received.
I was elated to see that despite its length, somewhat intimidating title, and publication date, it did get some very validating reactions.
I just came across an excellent post by Lea Verou which argues for building software on more general and composable abstractions.
In short, I see several different ideas at play in her piece:
Use cases lead to overfitting and it’s better to design more coherent and general increments of function;
More complex and domain-specific functionality can often be obtained as an instantiation or composition of more abstract and general functionality;
Even if you don’t implement the more general and abstract functionality, it might be better to design it and think of your implementation as partial;
You can use progressive disclosure in the UI as a bridge between more common domain-specific functionality and more general functionality.
These ideas seem to have a lot in common with concept design. Maybe her eigensolutions are concepts? What do y’all think? Also, I really liked the critique of use cases, which connects to our discussion last year of Bertrand Meyer’s piece.
It was very validating to see that the ideas resonated with someone who has been thinking about good conceptual design so deeply that it’s his primary area of research at MIT for years, and has published an excellent book on the matter (I only started reading it recently, but I’m loving it so far).
This is by far the best design article I’ve read in a very long time. Lea dives right into what it takes to build complex tools that have to meet wide, unmapped user needs.
I also love how it does not shy away from the complexity of the topic even for a moment: on the contrary, the title is already telling you what you’re signing up for.
@leaverou is no stranger to great writing, but this one is truly a gem.
I recently started using Miro myself, for diagrams and wireframes (most illustrations in this article have been made with Miro), and there are some real gems in its design, so it was very validating to see that the ideas resonated with someone who works on designing it.
Are you new to UX? This post will be a bit like taking an elevator up above the clouds, where you can see further, beyond the constraints of the transactional systems you might be working on already. Recommended.
He even subsequently proceeded to quote concepts from it in a number ofcomments on other posts! 🤩
This is a wonderful article! What @LeaVerou defines is what I consider platform design, which I think sits one level below UI systems design. Ie:
Product design
⬇️
Systems design (UI)
⬇️
Platform design
Although her approach to design is relevant to each.
I’ve spent so long designing creator tools that I tended to assume my observations and learnings from my experience are universal.
I first read about this distinction in Joe Mc Lean’s
excellent post on overfitting, and it was a bit of an a-ha moment. ↩︎
Yes, pivot tables are more complex than that, but let’s keep it simple for the sake of the example. ↩︎↩︎
Usability and aesthetics usually go hand in hand.
In fact, there is even what we call the “Aesthetic Usability Effect”:
users perceive beautiful interfaces as easier to use and cut them more slack when it comes to minor usability issues.
Unfortunately, sometimes usability and aesthetics can be at odds, also known as “form over function”.
A common incarnation of form-over-function, is when designers start identifying signifiers and affordances as noise to be eliminated,
sacrificing a great deal of learnability for an — often marginal — improvement in aesthetics.
Aesthetic and Minimalist Design is one of the Nielsen/Norman core usability heuristics (and all other heuristics taxonomies have something similar).
More poetically, Antoine de Saint-Exupéry said “Perfection is achieved, not when there is nothing more to add, but when there is nothing left to take away”.
However, this is one of those cases where everyone agrees with the theory, but the devil is in the details (though user testing can do wonders for consensus).
Case in point: The new Github comment UI is beautiful.
Look at how the text area smoothly blends with the tab, creating an irregular and visually interesting shape!
The new GitHub commenting UI, unfocused.
The new GitHub commenting UI, focused. Am I the only one that expected the focus outline to also follow the irregular shape?
However, I cannot for the life of me internalize that this is a text field that I can type in.
Even after using it over a dozen times, I still have to do a double take every time (“Where is the comment field?!”, “Why is this read-only?”).
For comparison, this was the old UI:
The old GitHub commenting UI, with and without focus.
While definitely more cluttered, its main UI elements were much more recognizable:
there is a text field, indicated by the rounded rectangle, and tabs, indicated by the light gray border around the active tab.
By merging the two, both affordances are watered down to the point of being unrecognizable.
Yes, there was more visual clutter, not all of which serves a purpose.
A skilled designer could probably eliminate the rounded rectangle around the entire area without impacting usability.
But the current design goes too far, and throws the baby out with the bathwater.
Twitter seems to be trying something similar, but since there is no irregular shape,
the text field affordance is not entirely lost.
Communication is all about mutually understood conventions: a sufficiently widespread grammatical mistake eventually becomes part of the language.
In the language of user interfaces, affordances and signifiers are the vocabulary, and the same principles apply.
Learnability is not an intrinsic property of a UI; it is a function of the context (cultural and otherwise) in which it is used.
Many affordances and signifiers use metaphors from the physical world to communicate what a user can do.
For example a button that looks raised reminds us of physical buttons.
Tabs are a metaphor for the tabs in a binder.
Others are entirely arbitrary and acquire meaning through learning, such as link underlines or the “hamburger” menu icon.
We see the same pattern in language: some words are onomatopoeic, such as “buzz” or “meow”, while others are entirely learned, such as “dog” or “cat”.
Similarly, writing systems began as pictograms, but evolved to be more abstract and symbolic.
At first, the symbols are direct (if cartoony) representations. Then they slowly lose their extrinsic meaning and become defined more by our conventions of using them (our shared language) and the references to outside concepts disappear.
It’s worth reading the whole post if you have time.
UI evolution is rife with patterns that began as obscure and ended up as obvious.
In other words, external consistency improved,
not because the UIs changed, but because the environment did.
Buttons used to need a 3D appearance to be perceived as such.
We gradually evolved such that any rectangle around text is perceived as a button, even if it is entirely flat (though research shows that theyare stilllesseffective).
Could it be that the new GitHub comment UI is the beginning of a new convention?
It’s possible, but the odds are slim.
For new conventions to become established, they need to be widespread.
Links, buttons, website logos are present on any website, so users get plenty of exposure to any evolution in their design.
Similarly, multiline text fields and tabs are very commonplace UI elements. However, their combination is far less common.
Even if every tabbed text field on the Web begun using the exact same design, the average user would still not get enough exposure to internalize it.
It is entirely possible that I’m overestimating the impact of this on GitHub users.
After all, I have not done user testing on it, so I’m basing my opinion on my own experience, and on what I’ve learned about usability spending the better part of the last decade at MIT teaching it and doing a PhD on it.
I wondered if it could be an A/B test, so I asked Chris to show me what UI he was seeing.
He was also seeing the new UI, but interestingly he expressed frustration about being unable to tell where the text field actually is, and where he can type even before I told him about this article.
Whether or not it’s not an A/B test, I’m really hoping that GitHub is collecting enough metrics so they can evaluate the impact of this design on user experience at scale.
As for me, I take comfort in knowing that when there is no alternative, users can eventually adapt to any UI, no matter how poor, so I will at some point get used to it.
Airplane cockpits are the canonical example here, but this is commonly seen in UIs of a lot of enterprise software (though the wind of change is blowing straight into the face of enterprise UX).
Our life is rife with examples of poor usability, to the point where if something is easy to use, people are often surprised.
There is even what some of us call “UX Stockholm Syndrome”: after very prolonged exposure to a poor interface, users start believing that it is easy to use, and even advocate against improvements.
The curse of knowledge makes them forget how difficult it was to learn, and the prolonged exposure can even make them efficient at using it.
Take hex colors for example. Quick, what color is #7A6652?
Learning to mentally translate between hex color notation and actual visible colors takes years of practice.
Hex notation was never designed for humans; it was designed for machines, as a compact way to represent the 3 bytes of RGB channels of earlier screens.
Humans do not think of colors as combinations of lights.
It’s not logical that to make brown you combine some red, a bit less green, and even less blue.
That is neither how we think about color, nor does it relate to any of our real-world color mixing experiences.
There are several color models with a more human-centered design, such as HSL, LCH, OKLCH.
Their coordinates are designed around how humans describe colors,
such as hue for the main color (e.g. red, yellow, green, etc.), chroma/saturation to specify how intense the color is (e.g. 0 would be gray), and lightness to specify how light it is (e.g. white would be 100% and black would be 0%).
Yet, it’s common to see the kinds of people who have had very prolonged exposure to this notation (e.g. web designers) not only prefer it, but even try to sing its praises!
Another example, entirely outside of software, is music notation.
You’ve likely learned it as a child, so it’s hard to remember what the learning experience was like,
and if you regularly read music sheets, you may even believe it’s easy.
But if we try to step back and examine it objectively, it’s highly unintuitive.
Expanding on this would take a whole other article, but I will just give one example.
Take a look at the symbols for notes and pauses:
There is not only an ordering here, but successive symbols even have a fixed ratio of 2.
Yet absolutely nothing in their representation signifies this.
Nothing in the depiction of ♩ indicates that it is longer than ♪, let alone that it is double the length.
You just have to learn it.
Heck, there’s nothing even indicating whether a symbol produces sound or not!
Demanding a lot of knowledge in the head
is not a problem in itself; it’s a common tradeoff when efficiency is higher priority than learnability.
E.g. the alphabet is also a set of arbitrary symbols we need to learn to be able to form words.
But even the best tradeoff is worse than none, aka having your cake and eating it too beats both options.
Was a tradeoff really necessary here?
Was there really no possible depiction of these symbols that could communicate their purpose, order, and ratios? Or at least a notation that was memorable by association rather than straight memorization?
@leaverou @github I really thought the page was broken or incompletely loaded until I saw it enough times to try typing in it. It’s emotionally uncomfortable to type in, fighting how it looks vs. what I know it is.
— Benjamin @hazula@hachyderm.io, Nov 3rd, 2023
The Primer team at GitHub reached out to me to discuss the issue, and I was happy to see that they were very receptive to feedback.
They then iterated, and came up with a new design that communicates purpose much better, even if less minimalistic:
The textarea is now clearly outlined, both before and after focus, clearly indicating that this is a multiline text field.
@leaverou @github thank you for this post. We have shipped improvements to make it easier again to identify the textarea and distinguish between Write and Preview.
— Daniel Adams (@dipree@mastodon.social), Nov 20th, 2023
Always great to see an org that is receptive to feedback!
Survey results are used by browsers to prioritize roadmaps — the reason Google is funding this.
Time spent thoughtfully filling them out is an investment that can come back to you tenfold
in the form of seeing features you care about implemented, browser incompatibilities being prioritized, and gaps in the platform being addressed.
In addition to browsers, several standards groups are also using the results for prioritization and decision-making.
Learn about new and upcoming features you may have missed; add features to your reading list and get a list of resources at the end!
Get a personalized score and see how you compare to other respondents
Learn about the latest trends in the ecosystem and what other developers are focusing on
While the survey will be open for 3 weeks, responses entered within the first 9 days (until October 1st) will have a much higher impact on the Web,
as preliminary data will be used to inform Interop 2024 proposals.
The State of HTML logo, designed by Chris Kirk-Nielsen, who I think surpassed himself with this one!
This is likely the most ambitious Devographics survey to date.
For the past couple of months, I’ve been hard at work leading a small product team spread across three continents (2am to 8am became my second work shift 😅).
We embarked on this mission with some uncertainty about whether there were enough features for a State of HTML survey,
but quickly found ourselves with the opposite problem:
there were too many, all with good reasons for inclusion!
To help weigh the tradeoffs and decide what makes the cut we consulted both the developer community,
as well as stakeholders across browsers, standards groups, community groups, and more.
We even designed new UI controls to facilitate collecting the types of complex data that were needed without making the questions too taxing,
and did original UX research to validate them.
Once the dust settles, I plan to write separate blog posts about some of these.
Absolutely! Do not worry about filling it out perfectly in one go.
If you create an account, you can edit your responses for the whole period the survey is open, and even split filling it out across multiple devices (e.g. start on your phone, then fill out some on your desktop, etc.)
Even if you’re filling it out anonymously, you can still edit responses on your device for a while.
You could even start anonymously and create an account later, and your responses will be preserved (the only issue is filling it out anonymously, then logging in with an existing account).
For the same reason there are JS APIs in the HTML standard:
many JS APIs are intrinsically related to HTML.
We mainly included JS APIs in the following areas:
APIs used to manipulate HTML dynamically (DOM, form validation, etc.)
Web Components APIs, used to create custom HTML elements
APIs used to create web apps that feel like native apps (e.g. Service Workers, Web App Manifest, etc.)
If you don’t write any JS, we absolutely still want to hear from you!
In fact, I would encourage you even more strongly to fill out the survey: we need to hear from folks who don’t write JS, as they are often underrepresented.
Please feel free to skip any JS-related questions (all questions are optional anyway) or select that you have never heard these features.
There is a question at the end, where you can select that you only write HTML/CSS:
Absolutely not! Localization has been an integral part of these surveys since the beginning.
Fun fact: Nobody in the core State of HTML team is a native English speaker.
Each survey gets (at least partially) translated to over 30 languages.
However, since translations are a community effort, they are not necessarily complete, especially in the beginning.
If you are a native speaker of a language that is not yet complete, please consider helping out!
Previous surveys reported score as a percentage: “You have heard or used X out of Y features mentioned in the survey”.
This one did too at first:
This was my own score when the survey first launched, and I created the darn survey 😅
Our engineer, Sacha who is also the founder of Devographics got 19%!
These were a lot lower for this survey, for two reasons:
It asks about a lot of cutting edge features, more than the other surveys.
As I mentioned above, we had a lot of difficult tradeoffs to make,
and had to cut a ton of features that were otherwise a great fit.
We err’ed on the side of more cutting edge features, as those are the areas the survey can help make the most difference in the ecosystem.
To save on space, and be able to ask about more features, we used a new compact format for some of the more stable features, which only asks about usage, not awareness.
Here is an example from the first section of the survey (Forms):
However, this means that if you have never used a feature, it does not count towards your score, even if you have been aware of it for years.
It therefore felt unfair to many to report that you’ve “heard or used” X% of features, when there was no way to express that you have heard 89 out of 131 of them!
To address this, we changed the score to be a sum of points, a bit like a video game:
each used feature is worth 10 points, each known feature is worth 5 points.
Since the new score is harder to interpret by itself and only makes sense in comparison to others,
we also show your rank among other participants, to make this easier.
My score after the change.
If you have already taken the survey, you can just revisit it (with the same device & browser if filled it in anonymously)
and go straight to the finish page to see your new score and ranking!
As you may know, this summer I am leading the design of the inaugural State of HTML survey.
Naturally, I am also exploring ways to improve both survey UX, as well as all questions.
Shaine Madala, a data scientist working on the survey design team proposed using numerical inputs instead of brackets for the income question.
While I was initially against it,
I decided to explore this a bit further, which changed my opinion.
The current income question, which uses 6 brackets plus a "Not Applicable" option.
There are actually four demographics questions in State of X surveys where the answer is essentially a number, yet we ask respondents to select a bracket:
age, years of experience, company size, and income.
The arguments for brackets are:
They are more privacy preserving for sensitive questions (e.g. people may feel more comfortable sharing an income bracket than their actual income)
They are more efficient to input (one click vs homing to keyboard and hitting several keystrokes).
In some cases respondents may not know the precise number offhand (e.g. company size)
The arguments for numerical input are:
Depending on the specifics, these can actually be faster to answer overall since they involve lower cognitive overhead (for known numbers).
The brackets are applied at the analysis stage, so they can be designed to provide a better overview of the dataset
More elaborate statistics can be computed (e.g. averages, medians, stdevs, the sky is the limit)
We can actually calculate this!
Average reading speed for non-fiction is around 240 wpm (= 250ms/word) 1
Therefore, we can approximate reading time for each question by multiplying number of brackets × average words per bracket (wpb) × 250ms.
However, this assumes the respondent reads all brackets from top to bottom, but this is a rare worst case scenario.
Usually they stop reading once they find the bracket that matches their answer, and they may even skip some brackets, performing a sort of manual binary search.
We should probably halve these times to get a more realistic estimate.
Average typing speed is 200 cpm 2 (≈ 300ms/character).
This means we can approximate typing time for each question by multiplying the number of digits on average × 300ms.
Let’s see how this works out for each question:
Question
Brackets
WPB
Reading time
Avg Digits
Typing time
Age
8
4
4s
2
0.6s
Years of Experience
6
4
3s
2
0.6s
Company size
9
4
4.5s
3
0.9s
Income
7
2
1.75s
5
1.5s
As you can see, despite our initial intuition that brackets are faster, the time it takes to read each bracketed question vastly outweighs typing time for all questions!
Of course, this is a simplification.
There are models in HCI, such as KLM that can more accurately estimate the time it takes for certain UI flows.
We even taught some of these to MIT students in 6.813,
as well as its successor.
For example, here are some of the variables we left out in our analysis above:
When answering with numerical input, most users need to home from mouse to keyboard, which takes time (estimated as 0.4s in KLM)
and then focus the input so they can write in it, which takes an additional click (estimated as 0.2s in KLM)
When answering with brackets, users need to move the mouse to the correct bracket, which takes time (KLM estimates all pointing tasks as a flat 1.1s, but this can be more accurately estimated using Fitts’ Law)
We are assuming that the decision is instantaneous, but doing the mental math of comparing the number in your head to the bracket numbers also takes time.
However, given the vast difference in times, I don’t think a more accurate model would change the conclusion much.
Note that this analysis is based on a desktop interface, primarily because it’s easier (most of these models were developed before mobile was widespread, e.g. KLM was invented in 1978!)
Mobile would require a separate calculation taking into account the specifics of mobile interaction (e.g. the time it takes for the keyboard to pop up), though the same logic applies.
(thanks Tim for this exellent question!)
Sliders are uncommon in surveys, and for good reason.
They offer the most benefit in UIs where changes to the value provide feedback, and allow users to iteratively approach the desired value by reacting to this feedback.
For example:
In a color picker, the user can zero in to the desired coordinates iteratively, by seeing the color change in real time
In a video player, the user can drag the slider to the right time by getting feedback about video frames.
In searches (e.g. for flights), dragging the slider updates the results in real time, allowing the user to gradually refine their search with suitable tradeoffs
In surveys, there is usually no feedback, which eliminates this core benefit.
When the number is known in advance, sliders are usually a poor choice, except when we have very few numbers to choose among (e.g. a 1-5 rating)
and the slider UI makes it very clear where to click to select each of them, or we don’t much care about the number we select (e.g. search flights by departure time).3
None of our demographics questions falls in this category (unless bracketed, in which case why not use regular brackets?).
There are several reasons for this:
It is hard to predict where exactly to click to select the desired number. The denser the range, the harder it is.
Efficiency is not the only consideration here.
Privacy is a big one. These surveys are anonoymous, but respondents are still often concerned about entering data they consider sensitive.
Also, for the efficiency argument to hold true, the numerical answer needs to be top of mind, which is not always the case.
While most people know their rough company size, they very rarely would be able to provide an exact number without searching.
This is a good candidate for brackets.
However, the number of brackets should be reduced from the current 9 (does the difference between 2-5 and 6-10 employees really matter?),
and their labels should be copyedited for scannability.
We should also take existing data into account.
Looking at the State of CSS 2022 results for this question,
it appears that about one third of respondents work at companies with 2-100 people,
so we should probably not combine these 5 brackets into one, like I was planning to propose.
101 to 1000 employees is also the existing bracket with the most responses (15.1%), so we could narrow it a little,
shifting some of its respondents to the previous bracket.
Taking all these factors into consideration,
I proposed the following brackets:
The question that started it all is unfortunately the hardest.
Income is a number that people know (or can approximate).
It is faster to type, but only marginally (1.75s vs 1.5s).
We can however reduce the keystrokes further (from 1.5s to 0.6s on average) by asking people to enter thousands.
The biggest concern here is privacy.
Would people be comfortable sharing a more precise number?
We could mitigate this somewhat by explicitly instructing respondents to round it further, e.g. to the nearest multiple of 10:
What is your approximate yearly income (before taxes)?
Feel free to round to the nearest multiple of 10 if you are not comfortable sharing an exact number.
If it varies by year, please enter an average.
However, this assumes that the privacy issues are about granularity, or about the number being too low (rounding to 10s could help with both).
However, David Karger made an excellent point in the comments,
that people at the higher income brackets may also be reluctant to share their income:
I don’t think that rounding off accomplishes anything. It’s not the least significant digit that people care about, but the most significant digit. This all depends on who they imagine will read the data of course. But consider some techy earnings, say 350k. That’s quite a generous salary and some people might be embarrassed to reveal their good fortune. Rounding it to 300k would still be embarrassing. On the other hand, a bracket like 150 to 500 would give them wiggle room to say that they’re earning a decent salary without revealing that they’re earning a fantastic one. I don’t have immediate insight into what brackets should be chosen to give people the cover they need to be truthful, but I think they will work better for this question.
Another idea was to offer UI that lets users indicate that the number they have entered is actually an upper or lower bound.
What is your approximate yearly income (before taxes)?
Of course, a dropdown PLUS a number input is much slower than using brackets,
but if only a tiny fraction of respondents uses it, it does not affect the analysis of the average case.
However, after careful consideration and input, both qualitative and quantitative, it appears that privacy is a much bigger factor than I had previously realized.
Even though I was aware that people see income level as sensitive data (more so in certain cultures than others),
I had not fully realized the extent of this.
In the end, I think the additional privacy afforded by brackets far outweighs any argument for efficiency or data analysis convenience.
I’m sure there is a lot of prior art on the general dilemma on numerical inputs vs brackets,
but I wanted to do some analysis with the specifics of this case and outline an analytical framework for answering these kinds of dilemmas.
That said, if you know of any relevant prior art, please share it in the comments!
Same if you can spot any flaws in my analysis or recommendations.
KLM is a poor model for dragging tasks for two reasons:
First, it regards dragging as simply a combination of three actions: button press, mouse move, button release.
But we all know from experience that dragging is much harder than simply pointing, as managing two tasks simultaneously (holding down the mouse button and moving the pointer) is almost always harder than doing them sequentially.
Second, it assumes that all pointing tasks have a fixed cost (1.1s), which may be acceptable for actual pointing tasks, but the inaccuracy is magnified for dragging tasks.
A lot of HCI literature (and even NNGroup) refers to the Steering Law to estimate the time it takes to use a slider,
however modern sliders (and scrollbars) do not require steering, as they are not constrained to a single axis:
once dragging is initiated, moving the pointer in any direction adjusts the slider, until the mouse button is released.
Fitts Law actually appears to be a better model here, and indeed there are many papers extending it to dragging.
However, evaluating this research is out of scope for this post. ↩︎
You have likely participated in several Devographics surveys before,
such as State of CSS, or State of JS.
These surveys have become the primary source of unbiased data for the practices of front-end developers today
(there is also the Web Almanac research, but because this studies what is actually used on the web, it takes a lot longer for changes in developer practices to propagate).
You may remember that last summer, Google sponsored me to be Survey Design Lead for State of CSS 2022.
It went really well: we got 60% higher response rate than the year before, which gave browsers a lot of actionable data to prioritize their work.
The feedback from these surveys is a prime input into the Interop project,
where browsers collaborate to implement the most important features for developers interoperably.
So this summer, Google trusted me with a much bigger project, a brand new survey: State of HTML!
For some of you, a State of HTML survey may be the obvious next step, the remaining missing piece.
For others, the gap this is filling may not be as clear.
No, this is not about whether you prefer <div> or <span>!
It turns out, just like JavaScript and CSS, HTML is actually going through an evolution of its own!
New elements like <selectmenu> and <breadcrumb> are on the horizon, or cool new features like popovers and declarative Shadow DOM.
There are even JS APIs that are intrinsically tied to HTML, such as e.g. Imperative slot assignment
or DOM APIs like input.showPicker()
Historically, these did not fit in any of these surveys.
Some were previously asked in State of JS, some in State of CSS, but it was always a bit awkward.
This new survey aims to fill these gaps, and finish surveying the core technologies of the Web, which are HTML, CSS and JavaScript.
Designing a brand new survey is a more daunting task than creating the new edition of an existing survey,
but also an exciting one, as comparability with the data from prior years is not a concern,
so there is a lot more freedom.
Each State of X survey consists of two parts:
Part 1 is a quiz: a long list of lesser-known and/or cutting-edge (or even upcoming) features where respondents select one of three options:
Starting with State of CSS 2022, respondents could also add freeform comments to provide more context about their answer through the little speech bubble icon.
One of my goals this year is to make this feature quicker to use for common types of feedback,
and to facilitate quantitative analysis of the responses (to some degree).
At the end of the survey, respondents even get a knowledge score based on their answers,
which provides immediate value and motivation which reduces survey fatigue.
Part 2 is more freeform, and usually includes multiple-choice questions about tools and resources, freeform questions about pain points, and of course, demographics.
This process worked exceptionally well for uncovering blind spots: it turned out there were a bunch of CSS features that would be good to ask about, but were simply not on our radar.
This is one of the reasons I strongly believe in transparency and co-design: no one human or small team can ever match the collective intelligence of the community.
Predictably, I plan to try the same approach for State of HTML.
Instead of using MaVoice, this year I’m trying GitHub Discussions.
These allow one click voting from the GitHub interface itself,
without users having to authorize a separate app.
They also allow for more discussion, and do not clutter Issues, which are better suited for – well – actual issues.
I have created a Discussions category for this and seeded it with 55 features spanning 12 focus areas (Forms & Editing, Making Web Components, Consuming Web Components, ARIA & Accessibility APIs, Embedding, Multimedia, Interactivity, Semantic HTML, Templating, Bridging the gap with native, Performance, Security & Privacy).
These initial ideas and focus areas came from a combination of personal research, as well as several brainstorming sessions with the WebDX CG.
You can also see a (read-only) summary of the proposed features with their metadata here
though keep in mind that it’s manually updated so it may not not include new proposals.
Note that the feedback period will be open for two weeks, until August 10th.
After that point, feedback may still be taken into account, but it may be too late in the process to make a difference.
Some things to keep in mind when voting and generally participating in these discussions:
The votes and proposals collected through this process are only one of the many variables that feed into deciding what to ask about, and are non-binding.
There are two goals to balance here:
The survey needs to provide value to developers – and be fun to fill in!
The survey needs to provide value to browsers, i.e. get them actionable feedback they can use to help prioritize what to work on. This is the main way that these surveys have impact on the web platform, and is at least as important as (1).
While the title is “State of HTML”, certain JS APIs or even CSS syntax is also relevant, especially those very close to HTML, such as DOM, ARIA, Web Components, PWAs etc.
Stable features that have existed for a long time and are widely known are generally less likely to make it to the survey.
WordPress has been with me since my very first post in 2009.
There is a lot to love about it: It’s open source, it has a thriving ecosystem, a beautiful default theme, and a revolutionary block editor that makes my inner UX geek giddy.
Plus, WP made building a website and publishing content accessible to everyone.
No wonder it’s the most popular CMS in the world, by a huge margin.
However, for me, the bad had started to outweigh the good:
Things I could do in minutes in a static site, in WP required finding a plugin or tweaking PHP code.
It was slow and bloated.
Getting a draft out of it and into another medium was a pain.
Despite having never been hacked, I was terrified about it, given all the horror stories.
I was periodically getting “Error establishing a database connection” errors, whose frequency kept increasing.
It was time to move on.
It’s not you WP, it’s me.
It seemed obvious that the next step would be a statically generated blog.
I had been using Eleventy for a while on a variety of sites at that point and loved it, so using that was a no-brainer.
In fact, my blog was one of my last remaining non-JAMstack sites, and by far the biggest.
I had built a simple 11ty blog for my husband a year ago, and was almost jealous of the convenience and simplicity.
There are so many conveniences that just come for free with this workflow: git, Markdown, custom components, even GitHub Copilot as you write your prose!
And if you can make the repo public, oooooh, the possibilities! People could even file PRs and issues for your blog posts!
Using Netlify as a platform was also a no-brainer:
I had been using it for years, for over 30 sites at this point!
I love their simplicity, their focus on developer experience, and their commitment to open source.
I also happen to know a bunch of folks there, and they have a great culture too.
However, I was dreading the amount of work it would take to migrate 14 years of content, plugins, and styling.
The stroke that broke the camel’s back was a particularly bad db outage.
I tweeted about my frustration, but I had already made up my mind.
I reviewed the list of plugins I had installed on WP to estimate the amount of work.
Nearly all fell in one of two categories:
Solving problems I wouldn’t have if I wasn’t using WP (e.g. SVG support, Don’t Muck My Markup)
Giving me benefits I could get in 11ty with very little code (e.g. Prism syntax highlighting, Custom Body Class, Disqus, Unlist Posts & Pages, Widget CSS classes)
Giving me benefits I could get with existing Eleventy plugins (e.g. Add Anchor Links, Easy Table of Contents)
One of the hardest dilemmas was whether to make the repo for this website public or private.
Overall, I was happy to have most files be public, but there were a few things I wanted to keep private:
Drafts (some drafts I’m ok to share publicly, but not all)
Unlisted pages and posts (posts with publicly accessible URLs, but not linked from anywhere)
Private pages (e.g. in the previous site I had a password-protected page with my details for conference organizers)
Unfortunately, right now it’s all-or-nothing, even if only one file needs to be private, the whole repo needs to be private.
Making the repo public does have many advantages:
Transparency is one of my core values, and this is in line with it.
People can learn from my code and avoid going down the same rabbit holes I did.
People can file issues for problems.
People can send PRs to fix both content and functionality.
I wouldn’t need to use a separate public repo for the data that populates my Speaking, Publications, and Projects pages.
I went back and forth quite a lot, but in the end I decided to make it public.
In fact, I fully embraced it, by making it as easy as possible to file issues and submit PRs.
Each page has a link to report a problem with it, which prefills as much info as possible.
This was also a good excuse to try out GitHub Issue Forms,
as well as URLs for prefilling the form!
Each page has a link to edit it on GitHub, which automatically takes you through a PR flow if you don’t have write access to the repo.
Note that a public repo is not automatically open source.
As you know, I have a long track record of open sourcing my code.
I love seeing people learning from it, using it in their own projects, and blogging about what they’ve learned.
So, MIT-licensing the code part of this website is a no-brainer.
CC-BY also seems like a no-brainer for content, because, why not?
Where it gets tricky is the design.
I’m well aware that neither my logo nor the visual style of this website would win any design awards;
I haven’t worked as a graphic designer for many years, and it shows.
However, it’s something I feel is very personal to me, my own personal brand, which by definition needs to be unique.
Seeing another website with the same logo and/or visual style would feel just as unsettling as walking into a house that looks exactly like mine.
I’m speaking from experience: I’ve had my logo and design copied many times, and it always felt like a violation.
I’m not sure how to express this distinction in a GitHub LICENSE file, so I haven’t yet added one,
but I did try to outline it in the Credits & Making Of page.
It’s still difficult to draw the line precisely, especially when it comes to CSS code.
I’m basically happy for people to copy as much of my CSS code as they want (following MIT license rules),
as long as the end result doesn’t scream “Lea Verou” to anyone who has seen this site.
But how on Earth do you express that? 🤔
The title of this section says “to Markdown” because that’s one of the benefits of this approach:
static site generators are largely compatible with each other, so if I ever needed to migrate again, it would be much easier.
Thankfully, travelers on this road before me had already paved it.
Many open source scripts out there to migrate WP to Markdown!
The one that worked well for me was lonekorean/wordpress-export-to-markdown
(though I later discovered there’s a more updated fork now)
It was still a bumpy road. First, it kept getting stuck on parsing the WP XML export, specifically in comments.
I use Disqus for comments, but it mirrors comments in the internal WP system.
Also, WP seems to continue recording trackbacks even if they are not displayed anywhere.
Turns out I had hundreds of thousands of spam trackbacks, which I spent hours cleaning up (it was quite a meditative experience).
In the end I got the total comments + trackbacks from 290K down to 26K which reduced the size of the XML export from 210 MB to a mere 31 MB.
This did not fix the parsing issue, but allowed me to simply open the file in VS Code and delete the problematic comments manually.
It also fixed the uptime issues I was having: I never got another “Error establishing a database connection” error after that, despite taking my own sweet time to migrate (started in April 2023, and finished in July!).
Ideally, I wish WP had an option to export without comments, but I guess that’s not a common use case.
While this importer is great, and allowed me to configure the file structure in a way that preserved all my URLs, I did lose a few things:
Pages (I had to manually copy them over, but it was only a handful)
Any custom classes were gone (e.g. a "view-demo" class I used to create “call to action” links)
A few other issues:
It downloaded all images, but did not update the URLs in the Markdown files.
This was easy to fix with a regex find and replace from https?://lea.verou.me/wp-content/uploads/(\d{4}/\d{2})/([\w\.-]+\.(?:png|gif|jpe?g)) to images/$2.
Some images from some posts were not downloaded – I still have no idea why.
It did not download any non-media uploads, e.g. zip files.
Thankfully, these were only a couple, so I could detect and port over manually.
Older posts included code directly in the content, without code blocks, which meant it was being parsed as HTML, often with disastrous results (e.g. the post just cutting off in the middle of a sentence because it mentioned <script>, which opened an actual <script> element and ate up the rest of the content).
I fixed a few manually, but I’m sure there’s more left.
Because code was just included as content, the importer also escaped all Markdown special symbols, so adding code blocks around it was not enough, I also had to remove a bunch of backslashes manually.
While the importer preserved both tags and categories, this was a good opportunity to rethink whether I need them both,
and to re-evaluate how I use them.
Probably one of the hardest parts of this migration was preserving Disqus comments.
In fact, it was so hard that I procrastinated on it for three months,
being stuck in a limbo where I couldn’t blog because I’d have to port the new post manually.
I’ve documented the process in a separate blog post, as it was quite involved,
including some thoughts about what system to use in the future, as I eventually hope to migrate away from Disqus.
I wanted to preserve the URL structure of my old site as much as possible, both for SEO, but also because cool URLs don’t change.
The WP importer I used allowed me to preserve the /year/month/slug structure of my URLs.
I did want to have the blog in its own directory though.
This site started as a blog, but I now see it as more of a personal site with a blog.
Thankfully, redirecting these URLs to corresponding /blog/ URLs was a one liner using Netlify redirects:
/20* /blog/20:splat 301
Going forwards, I also decided to do away with the month being part of the URL, as it complicates the file structure for no discernible benefit and I don’t blog nearly as much now as I did in 2009, e.g. compare 2009 vs 2022: 38 vs 7!
I do think I will start blogging more again now, not only due to the new site,
but also due to new interests and a long backlog of ideas (just look at July 2023 so far!).
However, I doubt I will ever get back to the pre-2014 levels, I simply don’t have that kind of time anymore
(coincidentally, it appears my blogging frequency dropped significantly after I started my PhD).
I also wanted to continue having nice, RESTful, usable URLs, which also requires:
URLs that are “hackable” to allow users to move to higher levels of the information architecture by hacking off the end of the URL
In practice, this means it’s not enough if tags/foo/ shows all posts tagged “foo”, tags/ should also show all tags.
Similarly, it’s not enough if /blog/2023/04/private-fields-considered-harmful/ links to the corresponding blog post,
but also:
Overall, I’m happy with the result, and the flexibility.
I’ve had a lot of fun with this project, and it was a great distraction during a very difficult time in my life,
due to dealing with some serious health issues in my immediate family.
However, there are a few things that are now more of a hassle than they were in WP,
mainly around the editing flow:
In WP, editing a blog post I was looking at in my browser was a single click (provided I was logged in).
I guess I could still do that by editing through GitHub, but now I’m spoiled, I want an easy way to edit in my own editor
(VS Code, which has a lot of nice features for Markdown editing),
however the only way to do that is to either painfully traverse the directory structure, or …search to find the right *.md file,
neither of which is ideal.
Previewing a post I was editing was also a single click, whereas now I need to run a local server and manually type the URL in (or browse the website to find it).
Making edits now requires me to think of a suitable commit message.
Sure, this is useful sometimes, but most of the time, I want the convenience of just saving my changes and being done with it.
There is a way to solve the first problem: VS Code supports a vscode:// protocol that allows you to
open a file in VS Code from the browser.
This means, this link would open the file for this blog post in VS Code:
<a href="vscode://file/Users/leaverou/Documents/lea.verou.me/blog/2023/going-lean/index.md">Edit in VS Code</a>
See the issue? I cannot add a button to the UI that only works for me!
However, I don’t need to add a button to the UI:
as long as I expose the input path of the current page (Eleventy’s page.inputPath) in the HTML somehow,
I can just add a bookmarklet to my own browser that just does:
In fact, here it is, ready to be dragged to the bookmarks bar:
Edit in VS Code
Now, if only I could find a way to do the opposite: open the localhost URL that corresponds to the Markdown file I’m editing — and my workflow would be complete!
Obviously, there’s a lot of work left to do, and I bet people will find a lot more breakage than I had noticed.
I also have a backlog of blog post ideas that I can’t wait to write about.
But I’ve also been toying around with the idea of porting over my personal (non-tech) blog posts,
and keep them in an entirely separate section of the website.
I don’t like that my content is currently hostage to Tumblr (2012-2013) and Medium (2017-2021),
and would love to own it too,
though I’m a bit concerned that properly separating the two would take a lot of work.
Just like most WP users, I was using both categories and tags, simply because they came for free.
However the difference between them was a bit fuzzy, as evidenced by how inconsistently they are used, both here and around the Web.
I was mainly using Categories for the type of article (Articles, Rants, Releases, Tips, Tutorials, News, Thoughts),
however there were also categories that were more like content tags (e.g. CSS WG, Original, Speaking, Benchmarks).
This was easily solved by moving the latter to actual tags.
However, tags are no panacea, there are several issues with them as well.
First, there were many tags that were synonyms of each other, and posts were fragmented across them, or had to include both (e.g. JS and Javascript).
I addressed this by defining aliases in a global data file, and using Eleventy to dynamically build Netlify redirects for them.
# Tag aliases
{% for alias, tag in tag_aliases %}/tags/{{ alias }}/ /tags/{{ tag }}/ 301
{% endfor %}
Turns out I’m not the first to think of building the Netlify _redirects file dynamically, some googling revealed this blog post from 2021 that does the same thing.
I’ve also decided to expose these aliases in the tags index:
Lastly, another issue is what I call “orphan tags”: Tags that are only used in a single post.
The primary use case for both tags and categories is to help you discover related content.
Tags that are only used once clutter the list of tags, but serve no actual purpose.
It is important to note that orphan tags are not (always) an authoring mistake.
While some tags are definitely too specific and thus unlikely to be used again,
the vast majority of orphan tags are tags that could plausibly be used again, but it simply hasn’t happened.
I definitely removed a bunch of overly specific tags from the content,
but was still left with more orphan tags than tags with more than one post (103 vs 78 as I write these lines).
For (1), the best course of action is probably to remove the tags from the content altogether.
However for (2), there are two things to consider.
This is a little trickier.
For now, I’ve refrained from making them links, and I’m displaying them faded out to communicate this.
Another alternative I’m contemplating is to hide them entirely.
Not as a punitive measure because they have failed at their one purpose in life 😅, but because this would allow me to use tags liberally,
and only what sticks would be displayed to the end user.
A third, intermediate solution, would be to have a “and 4 orphan tags” message at the end of the list of tags, which can be clicked to show them.
These are not just UX/IA improvements, they are also performance improvements.
Not linking orphan tags to tag pages means I don’t need to generate these tag pages at all.
Since the majority of tags are orphan tags, this allowed me to substantially reduce the number of pages that need to be generated,
and cut down build time by a whopping 40%, from 2.7s to 1.7s (on average).
There is a separate tag for ES (ECMAScript), and a separate one for JS.
However, any post tagged ES should also be tagged JS – though the opposite is not true.
There is a tag for CSS, tags for specific CSS specifications (e.g. CSS Backgrounds & Borders), and even tags for specific CSS functions or properties (e.g. background-attachment, background-size).
However, these are not orthogonal: posts tagged with specific CSS features should also be tagged with the CSS spec that contains them, as well as a general “CSS” tag.
I have yet to see a use case for tagging that does not result in implicit hierarchies.
Yet, all UIs for entering tags assume that they are flat.
Instead, it’s up to each individual post to maintain these relationships, which is tedious and error prone.
In practice, the more general tags are often left out, but not intentionally or predictably.
It would be much better to be able to define this hierarchy in a central place, and have it automatically applied to all posts.
In 11ty, it could be as simple as a data file for each tag’s “parent” tag.
Every time the tag is used, its parent is also added to the post automatically, recursively all the way up to the root (at build time).
I have not tried this yet, but I’m excited to experiment with it once I have a bit more time.
Back to our original dilemma: Do I still need categories, especially if I eventually implement tag hierarchies?
It does seem that the categories I used in WP for the article type (Articles, Rants, Releases, Tips, Tutorials, News, Thoughts etc)
are somewhat distinct from my usage of tags, which are more about the content of the article.
However, it is unclear whether this is the best use of categories, or whether I should just use tags for this as well.
Another common practice is to use tags for more specific content tags, and categories for broader areas (e.g. “Software engineering”, “Product”, “HCI”, “Personal” etc).
Skipping past the point that tag hierarchies make it easy to use tags for this too, this makes me think: maybe what is needed is actually metadata, not categories.
Instead of deciding that categories hold the article type, or the broader domain, what if we had certain attributes for both of these things.
Then, we could have a “type” attribute, and a “domain” attribute, and use them both for categorization, and for filtering.
Since Eleventy already supports arbitrary metadata, this is just a matter of implementation.
Lots to think about, but one thing seems clear: Categories do not have a clear purpose, and thus I’m doing away with them.
For now, I have converted all past categories to tags, so that the additional metadata is not lost,
and I will revisit how to best expose this metadata in the future.
It was important to me to have good, RESTful, usable, hackable URLs.
While a lot of that is easy and comes for free, following this principle with Eleventy proved quite hard:
URLs that are “hackable” to allow users to move to higher levels of the information architecture by hacking off the end of the URL
What does this mean in practice?
It means it’s not enough if tags/foo/ shows all posts tagged “foo”, tags/ should also show all tags.
Similarly, it’s not enough if /blog/2023/04/private-fields-considered-harmful/ links to the corresponding blog post,
but also:
Eleventy has a pagination feature, which actually does a lot more than pagination:
it’s used every time you want to generate several pages from a single template by chunking object keys and using them in permalinks.
One of the most common non-pagination use cases for it is tag pages. The typical /tags/tagname/ page is generated by a deceptively simple template:
---
pagination:
  data: collections
  size: 1
  alias: tag
  filter: ["blog", "all"]
permalink: /blog/tags/{{ tag }}/
override:tags: []
eleventyComputed:
  title: "{{ collections[ tag ].length | pluralize('post') }} on {{ tag | format_tag }}"
---

{% set taglist = collections[ tag ] | reverse %}
{# ... Loop over taglist here ... #}
That was it, then you just loop over taglist (or collections[ tag ] | reverse directly) to template the posts under each tag in reverse chronological order.
Simple, right?
But what about the indices?
As it currently stands, visiting /blog/tags/ will just produce a 404.
Creating an index of all tags only involves a single page, so it does not involve contorting the pagination feature to mind-bending levels,
like the rest of this post.
However, we need to do some processing to sort the tags by post count, and remove those that are not “real” tags.
The quick and dirty way is to just iterate over collections and count the posts for each tag:
<ol>
{% for tag, posts in collections %}
	<li>{{ tags.one(tag) }}
		({{ posts.length }} posts)
	</li>
{% endfor %}
</ol>
Unfamiliar with the tags.one() syntax above?
It’s using Nunjucks macros (there’s a {% import "_tags.njk" as tags %} earlier in the template too).
Macros allow you to create parameterized templates snippets,
and I’ve come to love them during this migration project.
The problem is that this does not produce the tags in any particular order,
and you usually want frequently used tags to come first.
You could actually fix that with CSS:
The only advantage of this approach is that this is entirely doable via templates and doesn’t require any JS,
but there are several drawbacks.
First, it limits what styling you can use: for the order property to actually have an effect, you need to be using either Flexbox or Grid layout.
But worse, the order property does not affect the order screen readers read your content one iota.
config.addCollection("postsByTag", (collectionApi) => {
	const posts = collectionApi.getFilteredByTag("blog");
	let ret = {};

	for (let post of posts) {
		for (let tag of post.data.tags) {
			ret[tag] ??= [];
			ret[tag].push(post);
		}
	}

	// Now sort, and reconstruct the object
	ret = Object.fromEntries(Object.entries(ret).sort((a, b) => b[1].length - a[1].length));

	return ret;
});
Usually, filters are meant for more broadly usable utility functions, and are not a good fit here.
However, the filter approach can be more elegant if your use case is more complicated and involves many different outputs.
For the vast majority of use cases, a dynamic collection is more appropriate.
Generating yearly indices can be quite similar as generating tag pages.
The main difference is that for tags the collection already exists (collections[tag]) whereas
for years you have to build it yourself, using addCollection() in your config file.
This seems to come up pretty frequently, both for years and months (the next section):
Pagination only works on one level:
You cannot paginate a paginated collection (though Zach has a workaround for that that I’m still trying to wrap my head around).
This also means that you cannot easily paginate tag or year index pages.
I worked around that by simply showing a more compact post list if there are more than 10 posts.
However, it also means you cannot process the postsByYear collection and somehow paginate by month.
You need to create another collection, this time with the year + month as the key:
config.addCollection("postsByMonth", (collectionApi) => {
    const posts = collectionApi.getFilteredByTag("blog").reverse();
    const ret = {};

    for (let post of posts) {
        let key = filters.format_date(post.date, "iso").substring(0, 7); // YYYY-MM
        ret[key] ??= [];
        ret[key].push(post);
    }

    return ret;
});
I had been using Disqus for comments for years, so I didn’t want to lose them, even if I ended up using a different solution for the future (or no comments at all).
Looking around for an existing solution did not yield many results.
There’s Zach’s eleventy-import-disqus but it’s aimed at importing Disqus comments as static copies,
but I wanted to have the option to continue using Disqus.
Looking at the WP generated HTML source, I noticed that Disqus was using the WP post id (a number that is not displayed in the UI) to link its threads to the posts.
However, the importer I used did not preserve the post ids as metadata (filed issue #95).
What to do?
My first thought was to add the post id to each post manually, but use a HEAD request to my existing blog to read it from the Link header, possibly en masse.
My second thought was, if I can use JS to get it, maybe I can include Disqus dynamically, through JS, after it procures this number.
Then I remembered that 11ty can handle any number of different data sources, and combines them all into a single data object.
If I could build an index of slug → post id as another data file, I could add a post id via JS in the 11ty config.
My last epiphany was realizing I didn’t need any HTTP requests to get the post id: it was all in the exported sitemap XML, just unused by the importer!
Indeed, each <item> included a <wp:post_id> element with the post id and a <link> element with the URL.
I tried to open it in Chrome so I could run some JS on it and build the index, but it complained of parse errors.
When I fixed them, the tab crashed under its sheer size.
I needed to remove non-relevant data, and I needed to do it fast.
All I really needed was the post id, the slug, and the containing <item> element.
Since this did not just contain posts, but also other types of content, such as attachments or custom blocks,
we also needed to retain <wp:post_type> so we can filter these out.
I copied the XML over to a separate file, and run a series of find & replaces in VS Code:
^(?!.*(wp:post_id|wp:post_type|</?item>|</?link>)).+\n (regex) with empty string
\n{3,} (regex) with \n (to remove empty lines)
wp:post with post to remove namespaces and make the XML easier to handle
https://lea.verou.me/ with empty string and </link> with </link> to keep just the yyyy/mm/slug part of the URL
Then added <?xml version="1.0" encoding="UTF-8" ?> at the top and wrapped everything in a <root> element to make it valid XML.
This resulted in a series of <item> elements that looked like this:
Note that as it currently stands, this will not display the Disqus UI on new posts, since they won’t have a wpid.
Even if I switch to something else in the future, Disqus is better than nothing meanwhile
(for me – many people would disagree: switching to no comments at all seems very common when people switch to a SSG blog).
So, new posts don’t have a wpid, but they don’t need one either.
As long as we pass some kind of unique identifier to Disqus, we have a comment thread.
The easiest way to do this is to use the post’s path, e.g. 2023/preserve-disqus for this one, as this is guaranteed to be unique.
We also want to be able to disable comments on a per-post basis, so we need a way to do that.
So instead of dealing with wpid directly in templates, I added another computed property in blog.11tydata.js:
disqus_id: data => {
	let wpid = data.wpid;

	if (wpid) {
		return `${ wpid } https:\/\/lea.verou.me\/?p=${ wpid }`;
	}
	else if (data.disqus !== false) {
		return typeof data.disqus !== "string"? data.postUrlStem : data.disqus;
	}
}
Note that this allows us to pass a custom identifier to Disqus by using a string, disable it by using false,
or just get the automatic behavior by using true or not specifying it at all.
The custom identifier can be useful if we want to change the URL of a post without losing the comments.
Then, I updated the template to use disqus_id instead of wpid.
I don’t know if I will continue using Disqus.
It’s convenient, but also heavyweight, and there are privacyconcernsaround it.
However, I’m not sure what I would use instead.
Any third party SaaS service would have the same privacy issues. Not necessarily now, but quite likely in the future.
I’ve looked into Webmentions, but the end-user experience does not compare to a regular comment system,
and it seems like quite a hassle to implement.
Utterances is a really cool idea: it uses GitHub issues as a backend for a comment system.
Having myself (ab)used the GitHub API as a storage backend many a times (even as early as 2012), I can see the appeal.
This may be a viable path forwards, though I need to verify that GitHub Issues can be easily exported, so that I’m not locked in.
On a similar vein, I really loved Gisqus seems great too: It’s like Utterances, but uses GitHub Discussions instead of Issues.
What holds me back from switching to it is that Discussions cannot yet be exported,
and I think portability is important here.
People don’t even really use comments much anymore, they post on social media instead.
I would have loved some way to simply collect the discussions about the post from various social media and display them underneath,
but with API prices getting out of control (12), that doesn’t seem feasible.
If there are any options I missed, please let me know in the (Disqus, for now 😕) comments!
Today I mourn. What am I mourning? Encapsulation. At least in my projects.
As a library author, I’ve decided to avoid private class fields from now on and gradually refactor them out of my existing libraries.
Why did I make such a drastic decision?
It all started a few days ago, when I was building a Vue 3 app that used Color.js Color objects. For context, Vue 3 uses proxies to implement its reactivity system, just like Mavo did back in 2016 (the first one to do so as far as I’m aware). I was getting several errors and upon tracking them down I had a very sad realization: instances of classes that use private fields cannot be proxied.
I will let that sink in for a bit. Private fields, proxies, pick one, you can’t have both. Here is a reduced testcase illustrating the problem.
Basically, because a Proxy creates a different object, it breaks both strict equality (obj1 === obj2), as well as private properties. MDN even has a whole section on this. Unfortunately, the workaround proposed is no help when proxies are used to implement reactivity, so when I tried to report this as a Vue bug, it was (rightly) closed as wontfix. It would not be possible to fix this in Mavo either, for the same reason.
I joined TC39 fairly recently, so I was not aware of the background when proxies or private class fields were designed. Several fellow TC39 members filled me in on the discussions from back then. A lot of the background is in this super long thread, some interesting tl;drs as replies to my tweet:
After a lot of back and forth, I decided I cannot justify using private properties going forwards. The tradeoff is simply not worth it. There is no real workaround for proxy-ability, whereas for private fields there is always private-by-convention. Does it suck? Absolutely. However, a sucky workaround is better than a nonexistent workaround.
Also, I control the internal implementation of my classes, whereas proxying happens by other parties. As a library user, it must be incredibly confusing to have to deal with errors about access to private fields in a class you did not write.
This was one of the saddest PRs I have ever written https://github.com/LeaVerou/color.js/pull/306. It feels like such a huge step backwards. I’ve waited years for private fields to be supported everywhere and relished when they got there. I was among the first library authors to adopt them in library code, before a lot of tooling even parsed them properly (and some still don’t).
Sure, they were kind of annoying to use (you usually want protected, i.e. visible to subclasses, not actually private), but they were better than nothing. I was not joking in the first paragraph; I am literally grieving.
I may still use private fields on a case by case basis, where I cannot imagine objects being proxied being very useful, for example in web components. But from now on I will not reach to them without thought, like I have been for the past couple of years.
It has been over a decade when I launchedcontrast-ratio.com, an app to calculate the WCAG 2.1 contrast ratio between any two CSS colors. At the time, all similar tools suffered from several flaws when being used for CSS editing:
No support for semi-transparent colors (Since WCAG included no guidance for alpha transparency — I had to do original research to calculate the contrast ratio range for that case)
No support for color formats other than hex or (at best) RGB with sliders. I wanted something where I could just paste a CSS color just like I had it specified in my code (e.g. hsl(220 10% 90%), possibly tweak it a bit to pass, then paste it back. I didn’t want to use unintuitive hex colors, and I didn’t want to fiddle with sliders.
Poor UX, often calculating the actual ratio required further user actions, making iteration tedious
Over the years, contrast-ratio.com grew in popularity: it was recommended in several books, talks, and workshops. It basically became the standard URL developers would visit for this purpose.
Therefore, when Ross and Drew from Siege Media approached me with a generous offer to buy the domain, and a commitment to take over maintainship of the open source project, I was cautiously optimistic. But now, after having seen some of their plans for it, I could not be more certain that the future of this tool is much brighter with them.
Please join me in welcoming them to the project and help them get settled in as new stewards!
Update:I got re-elected!! Thank you for trusting me once more with this huge responsibility towards the Open Web. I will continue to do my best to justify the confidence the W3C membership has placed in me. 🥹
Context: In 2020, I ran for the TAG election for the first time and had the great honor of being elected by the W3C membership. This year, I’m running for re-election. The W3C Technical Architecture Group (TAG) is the Working Group that ensures that Web Platform technologies are usable and follow consistent design principles, whether they are created inside or outside W3C. It advocates for the needs of everyone who uses the Web and everyone who works on the Web. If you work for a company that is a W3C Member, please consider encouraging your AC rep to vote for me! My candidate statement follows.
I’m Lea, and I’m running for re-election to the TAG to continue applying my usability research, CSS WG, and TAG experience to help W3C stay connected to the developer community, and to better serve their needs by ensuring web platform features are not only powerful, but also learnable and approachable, with a smooth ease-of-use to complexity curve.
I wear many hats. My background spans almost two decades of web design & development experience, one decade of standards work in the CSS WG, nearly a decade of PhD level human-computer interaction research & teaching at MIT, and over a decade of educating web developers through talks, books, articles, and helping them through my dozens of open source projects, some of which are used on millions of websites. For those unfamiliar with my background, I encourage taking a look at my 2020 candidate statement.
In 2020, I had the great honor of being elected to serve on the TAG by the W3C membership. In the two years I have served on the TAG, I participated in over 70 design reviews and helped prioritize API design in our reviewing. I have been publicly praised for the quality of design reviews I led.
It is important that the TAG does not operate in a vacuum: The primary purpose of our work is to serve developers and end-users by ensuring web platform features are usable, secure and privacy preserving. I have used my experience during design reviews to make sure we remain connected to this mission.
Together with Sangwhan Moon, I took the lead on our Web Platform Design Principles effort, which documents the principles that underlie Web Platform features — previously only existing in WG lore. The Web Platform is going through an explosion of new features; only in the last year the TAG received almost a hundred design review requests. With this volume, it is important that reviews are consistent, transparent, and fast. Evolving our published design principles helps with all three goals.
The Web ecosystem is not just the Web Platform itself, but also the various tools and libraries out there. I started a project to publish a subset of the design principles that apply to web developers, to help them in creating Web Platform compatible APIs. After all, with web components, web developers are now HTML designers, with Houdini APIs, they are now CSS designers, and with JS, they’ve been JS API designers since forever. The project is currently in its infancy, and If elected, it will be one of my tasks to get it published within my next term.
As a Greek woman, I bring both a Mediterranean and European perspective that diversifies the TAG and as a fully bilingual Greek and English speaker, I can fully participate in rapid technical discussions while also having an appreciation of the Internationalization needs of those who use the Web in languages other than English.
To ensure my participation has been beneficial for the TAG, I reached out to the chairs for feedback before deciding to run again. Both were very positive and strongly encouraged me to run again.
As someone not employed at a big tech company, I am not influenced by any particular company line. My only agenda is to lead the Web Platform to its full potential, and if re-elected, I’m willing to commit to spending the requisite hundreds of hours working towards that goal over the next two years. This was just the beginning, there is so much more important work to be done!
I would like to thank Open JS Foundation for graciously funding my TAG-related travel, in the event that I am re-elected, and both OpenJS Foundation and Bocoup for funding it during my first term.

 Connexion


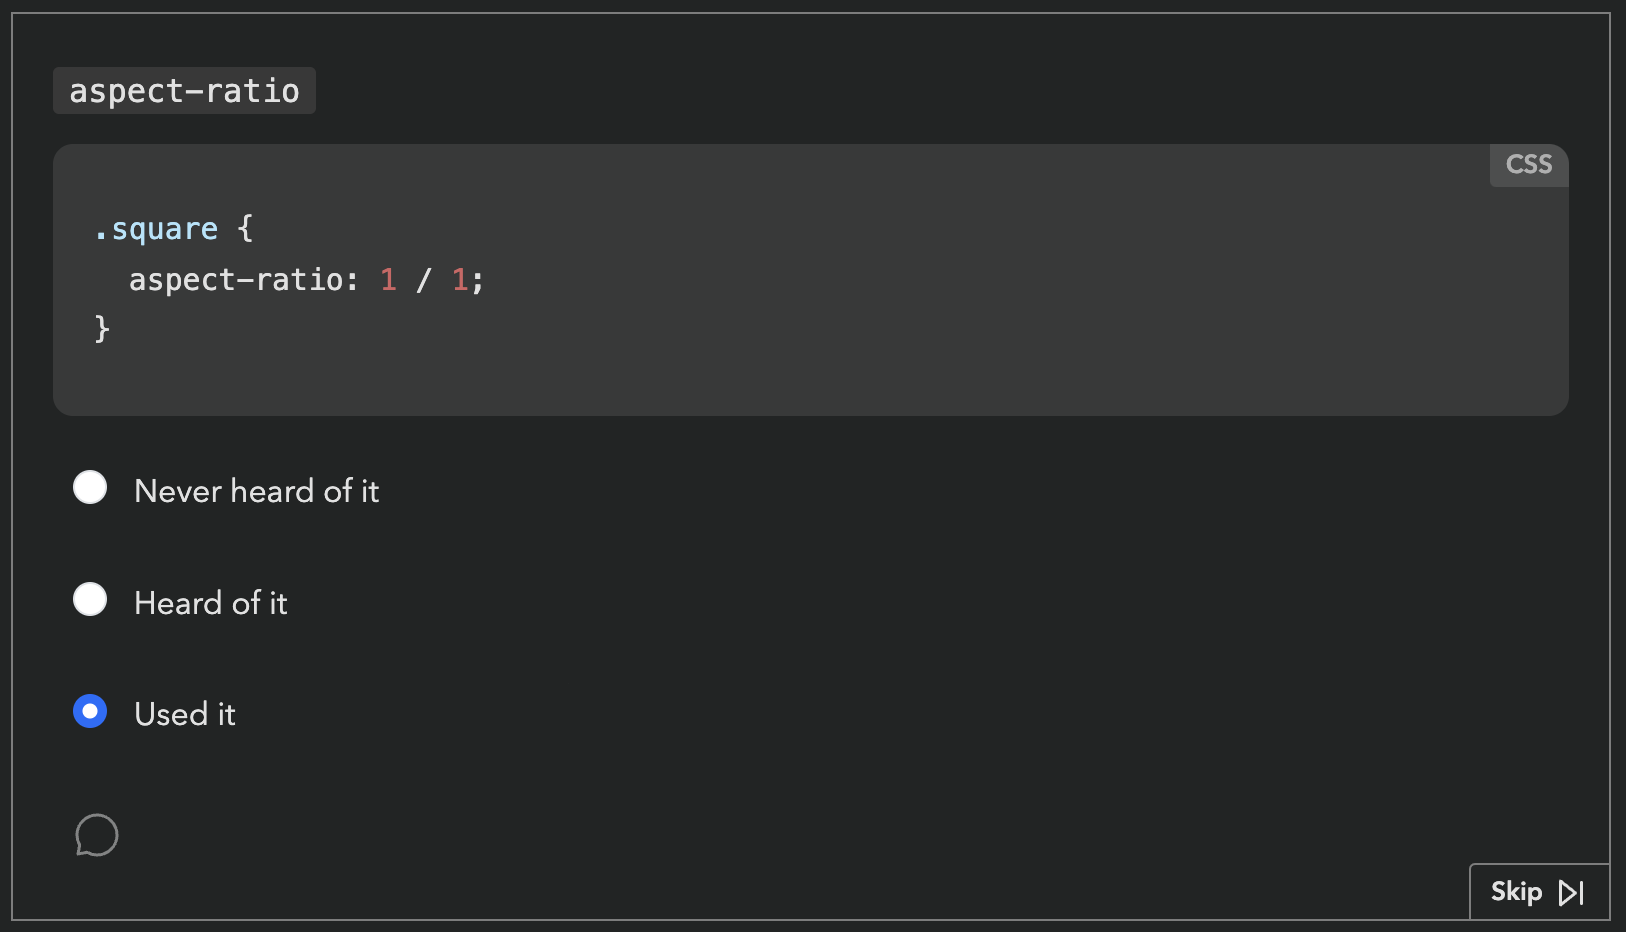
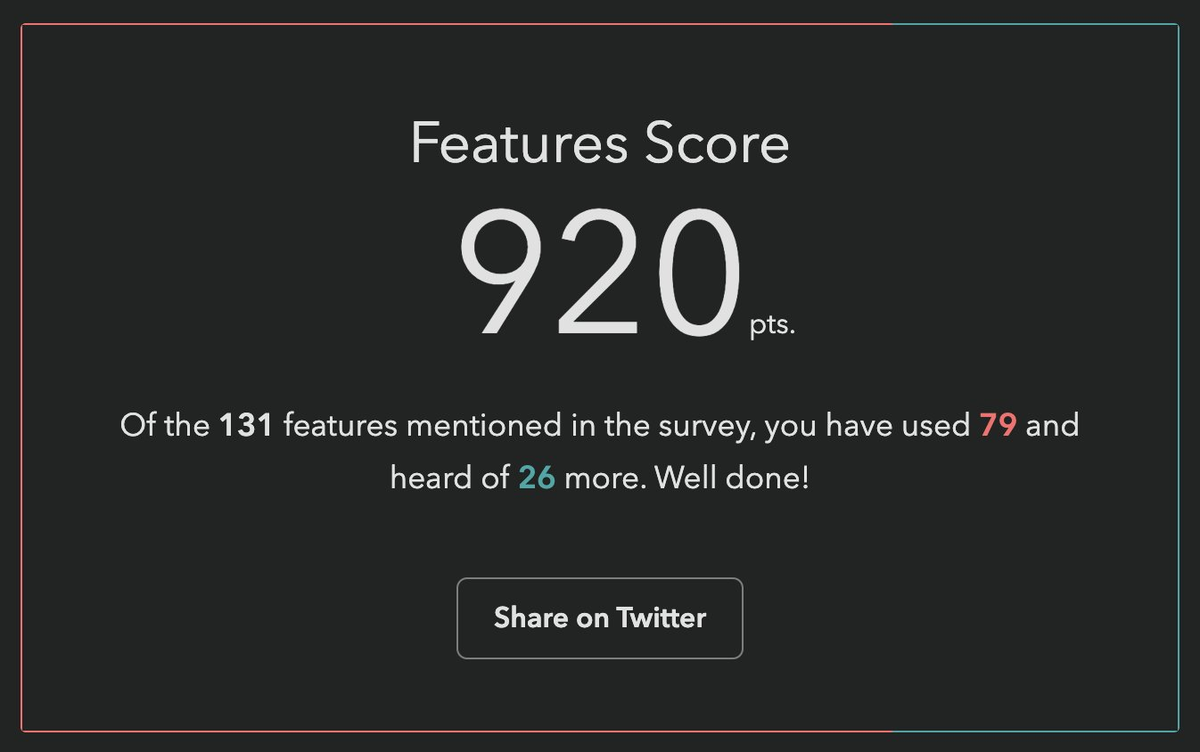
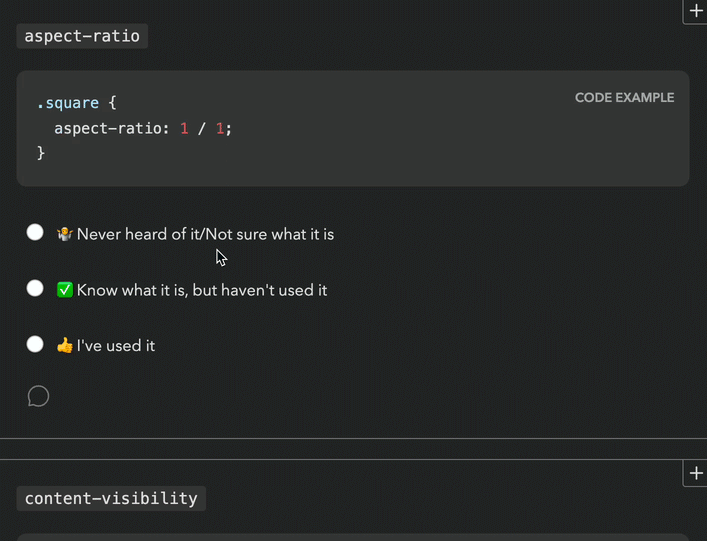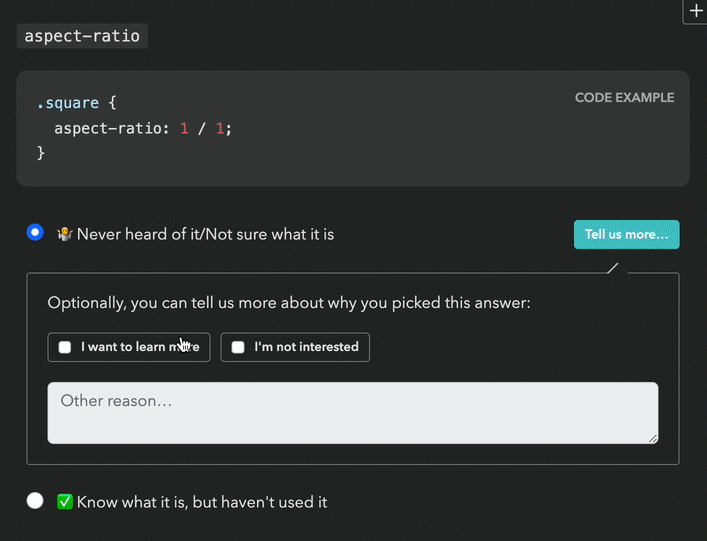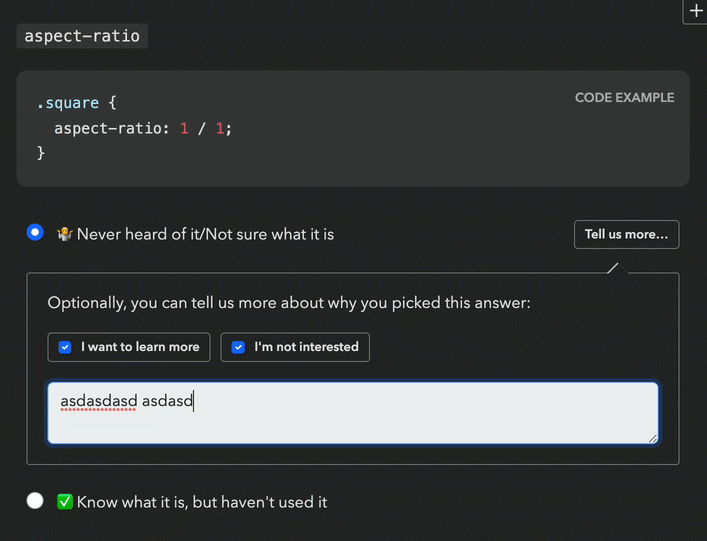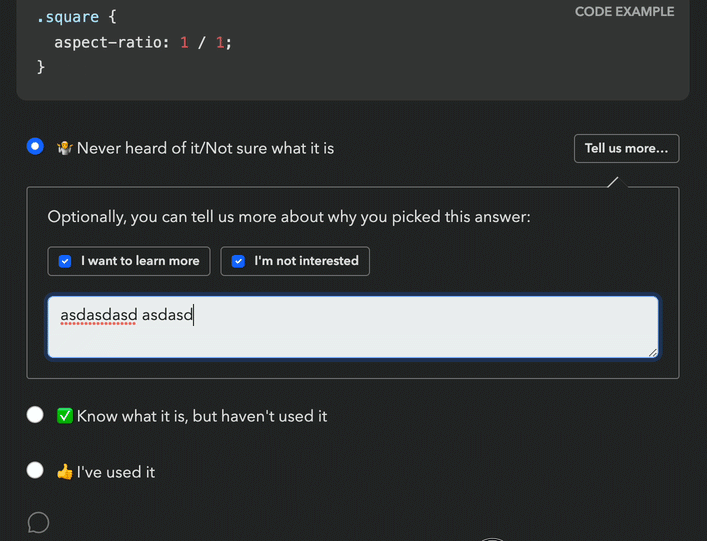
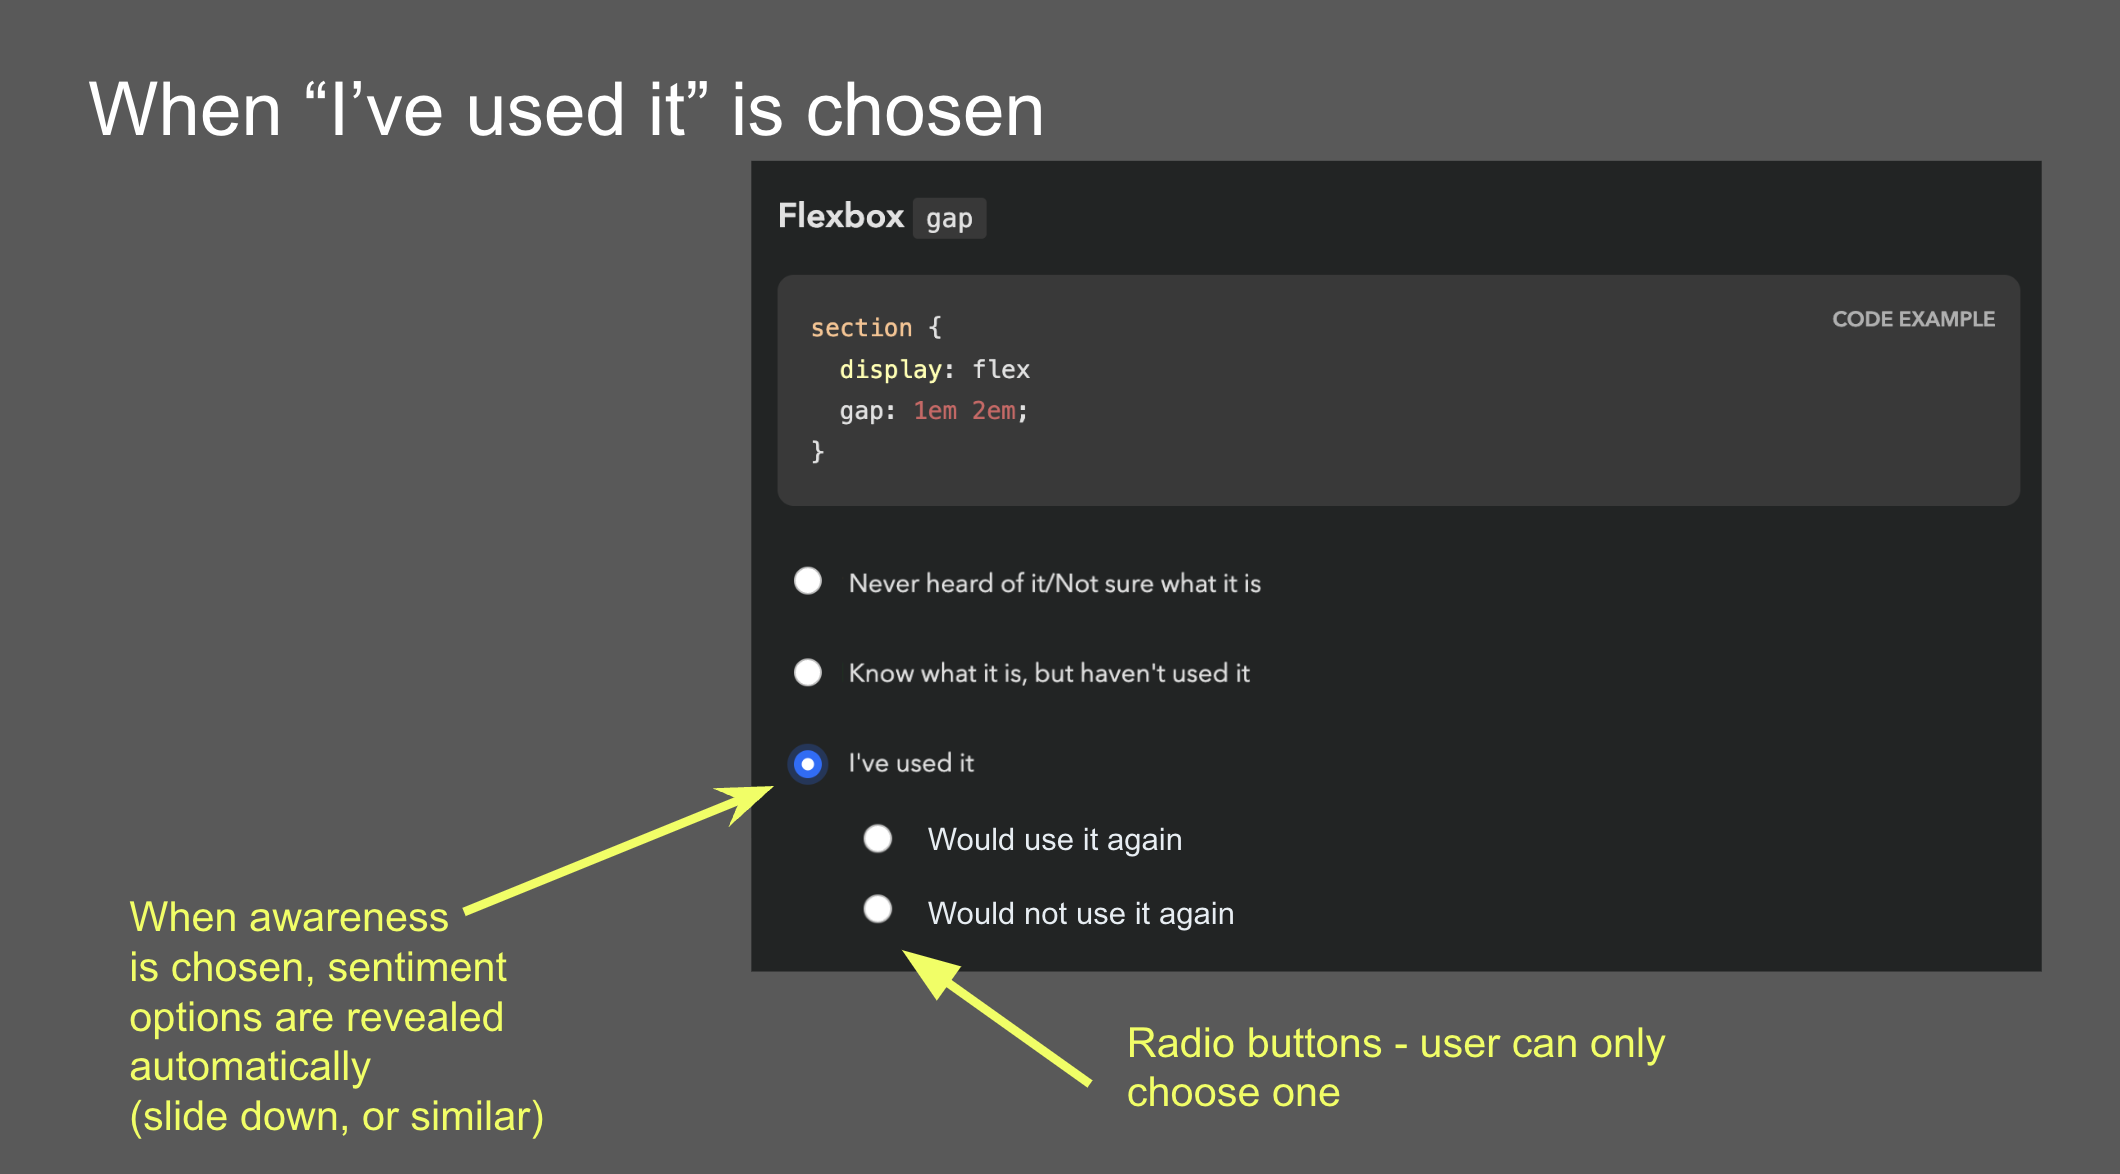

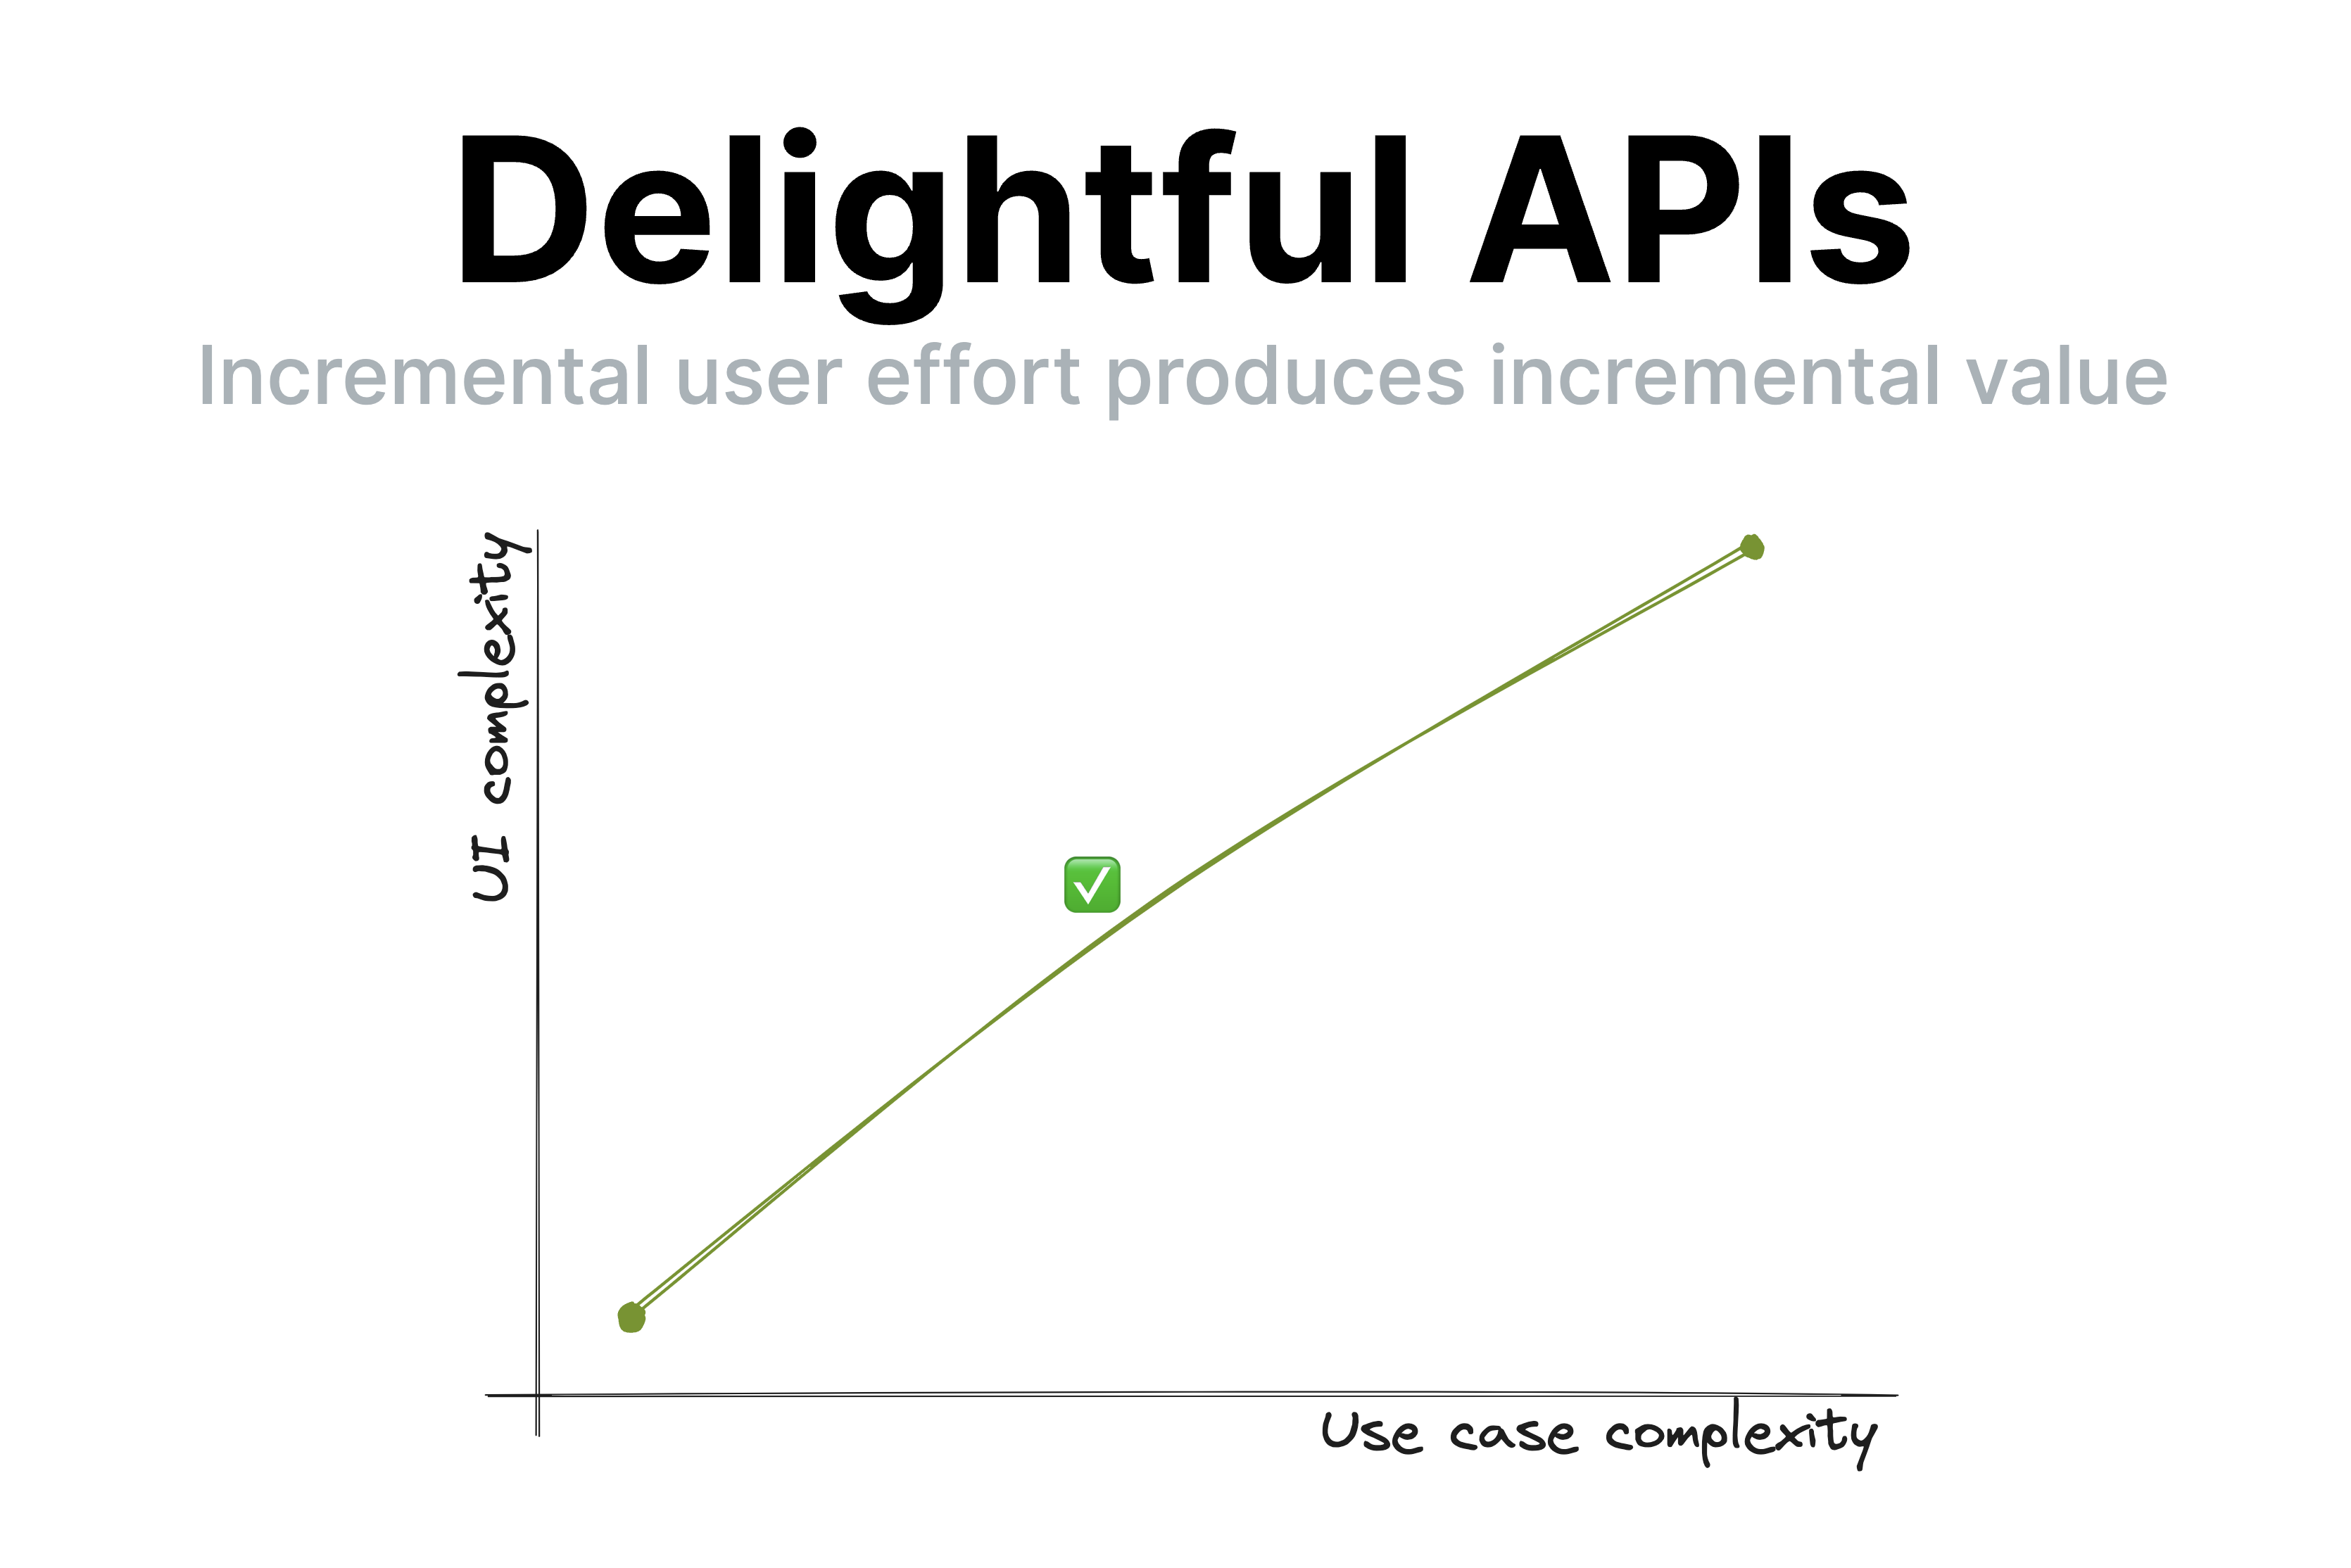
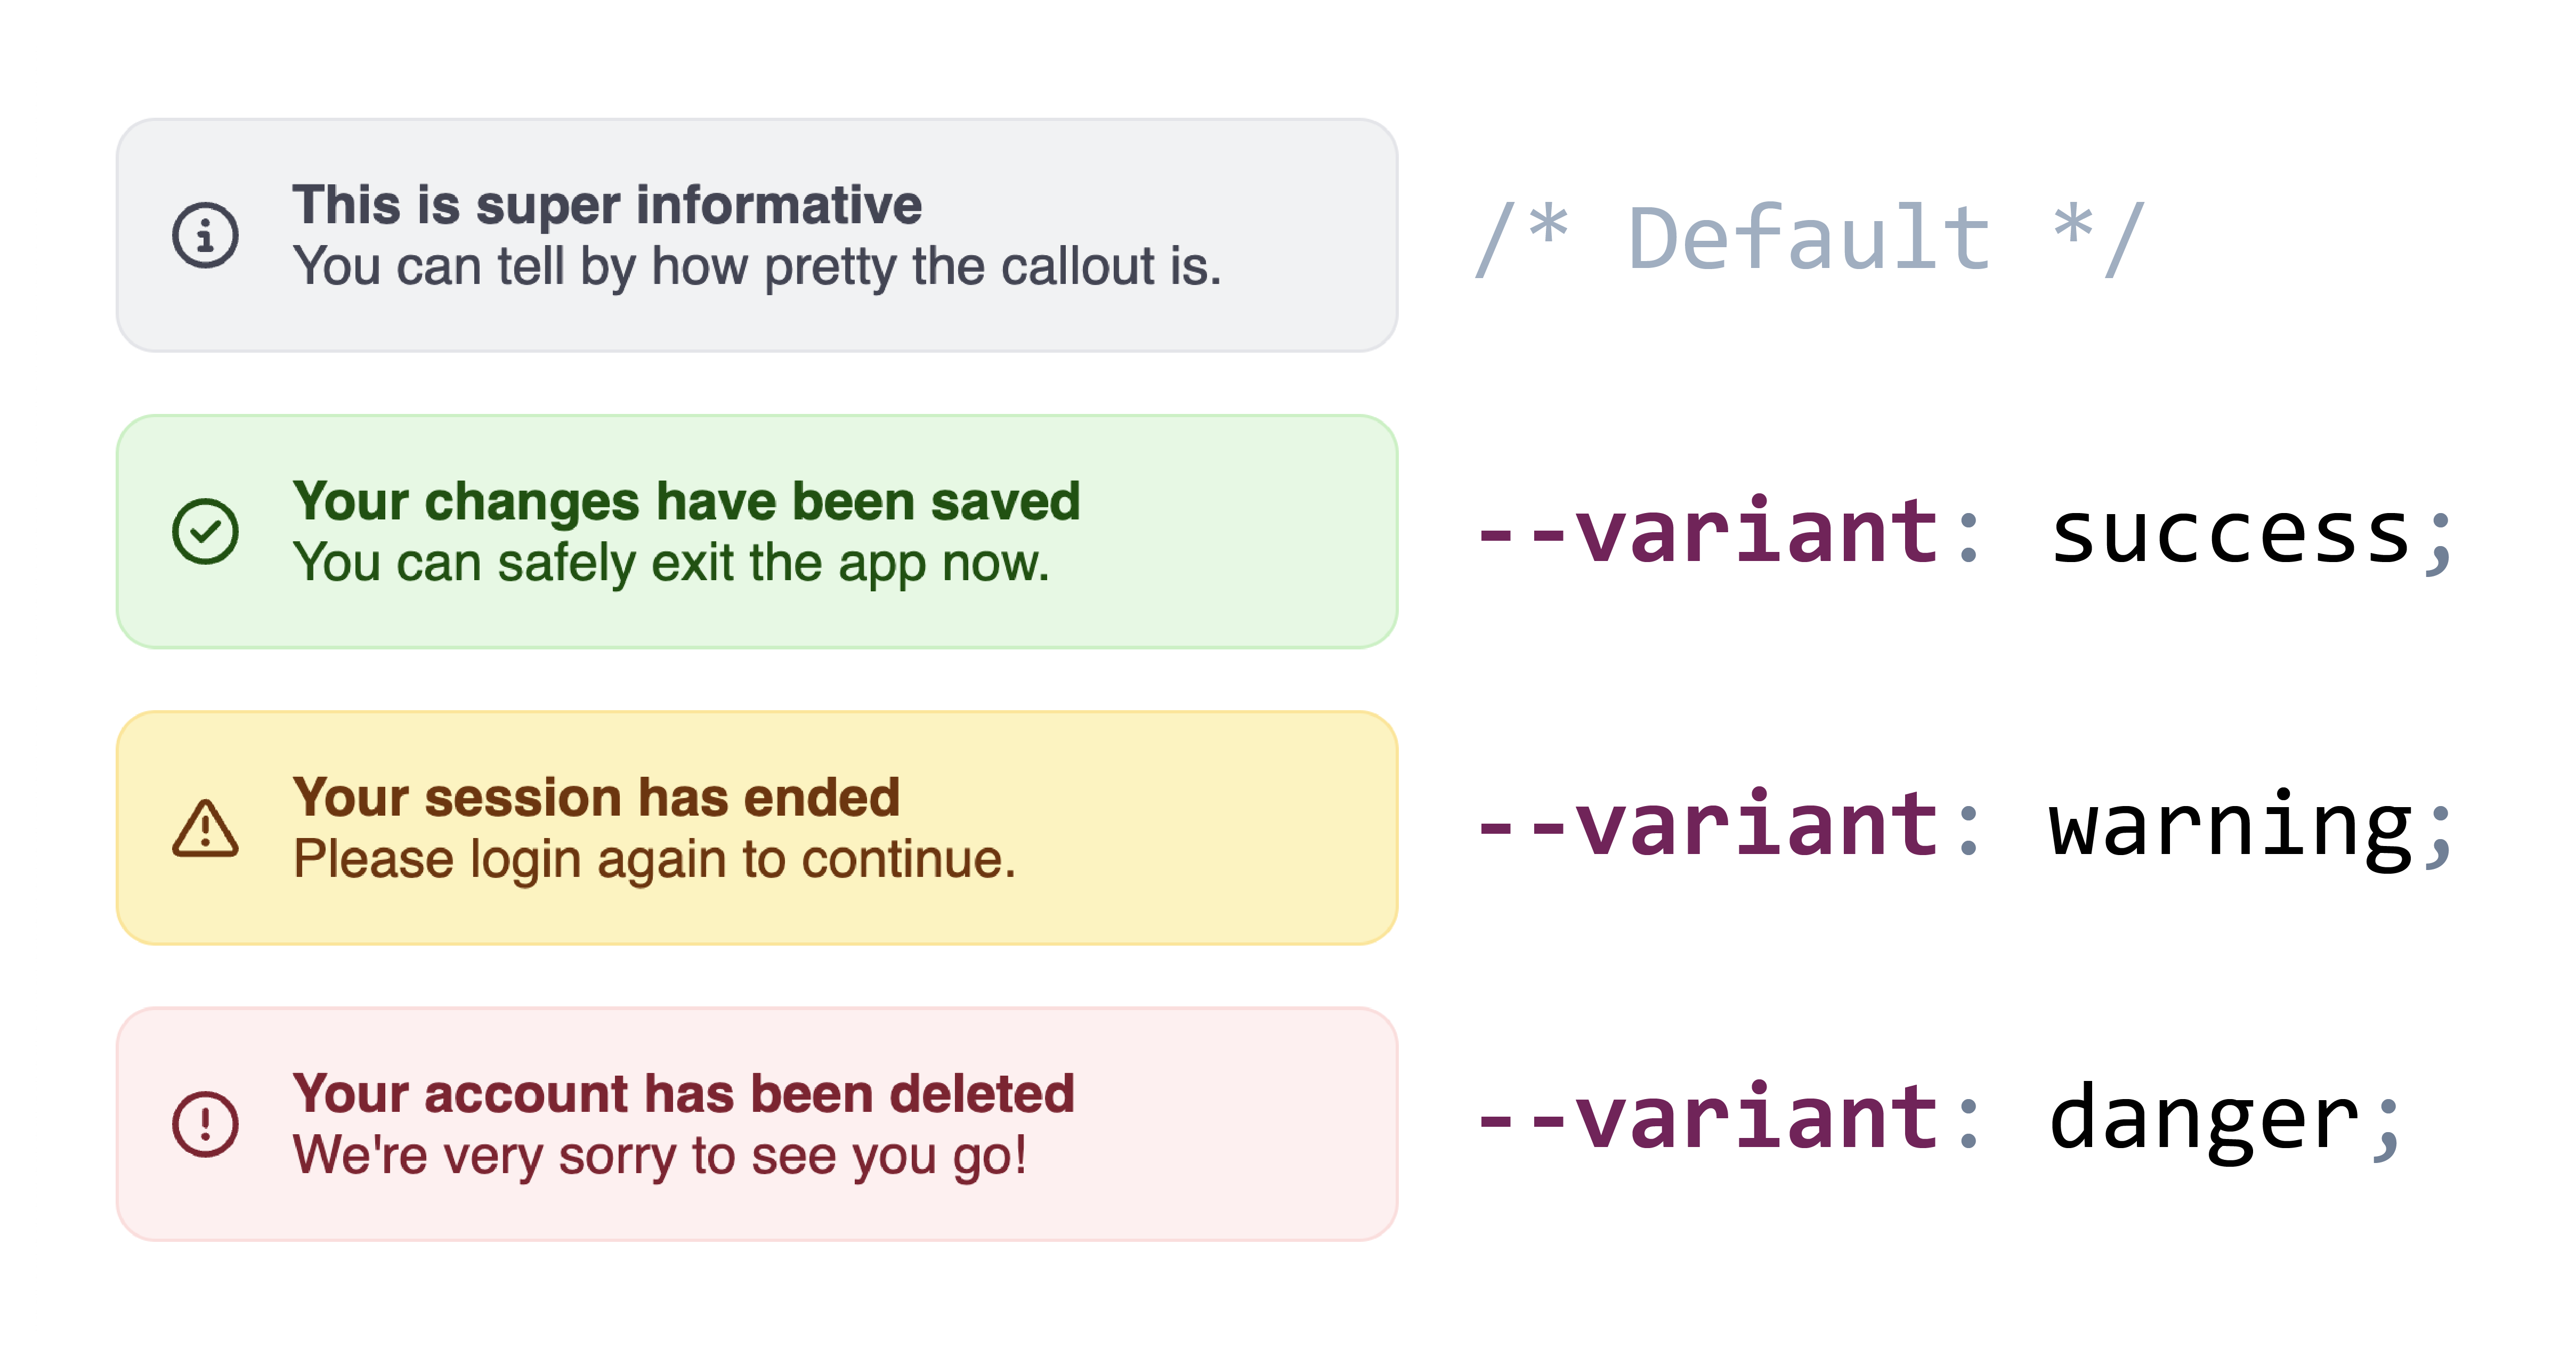
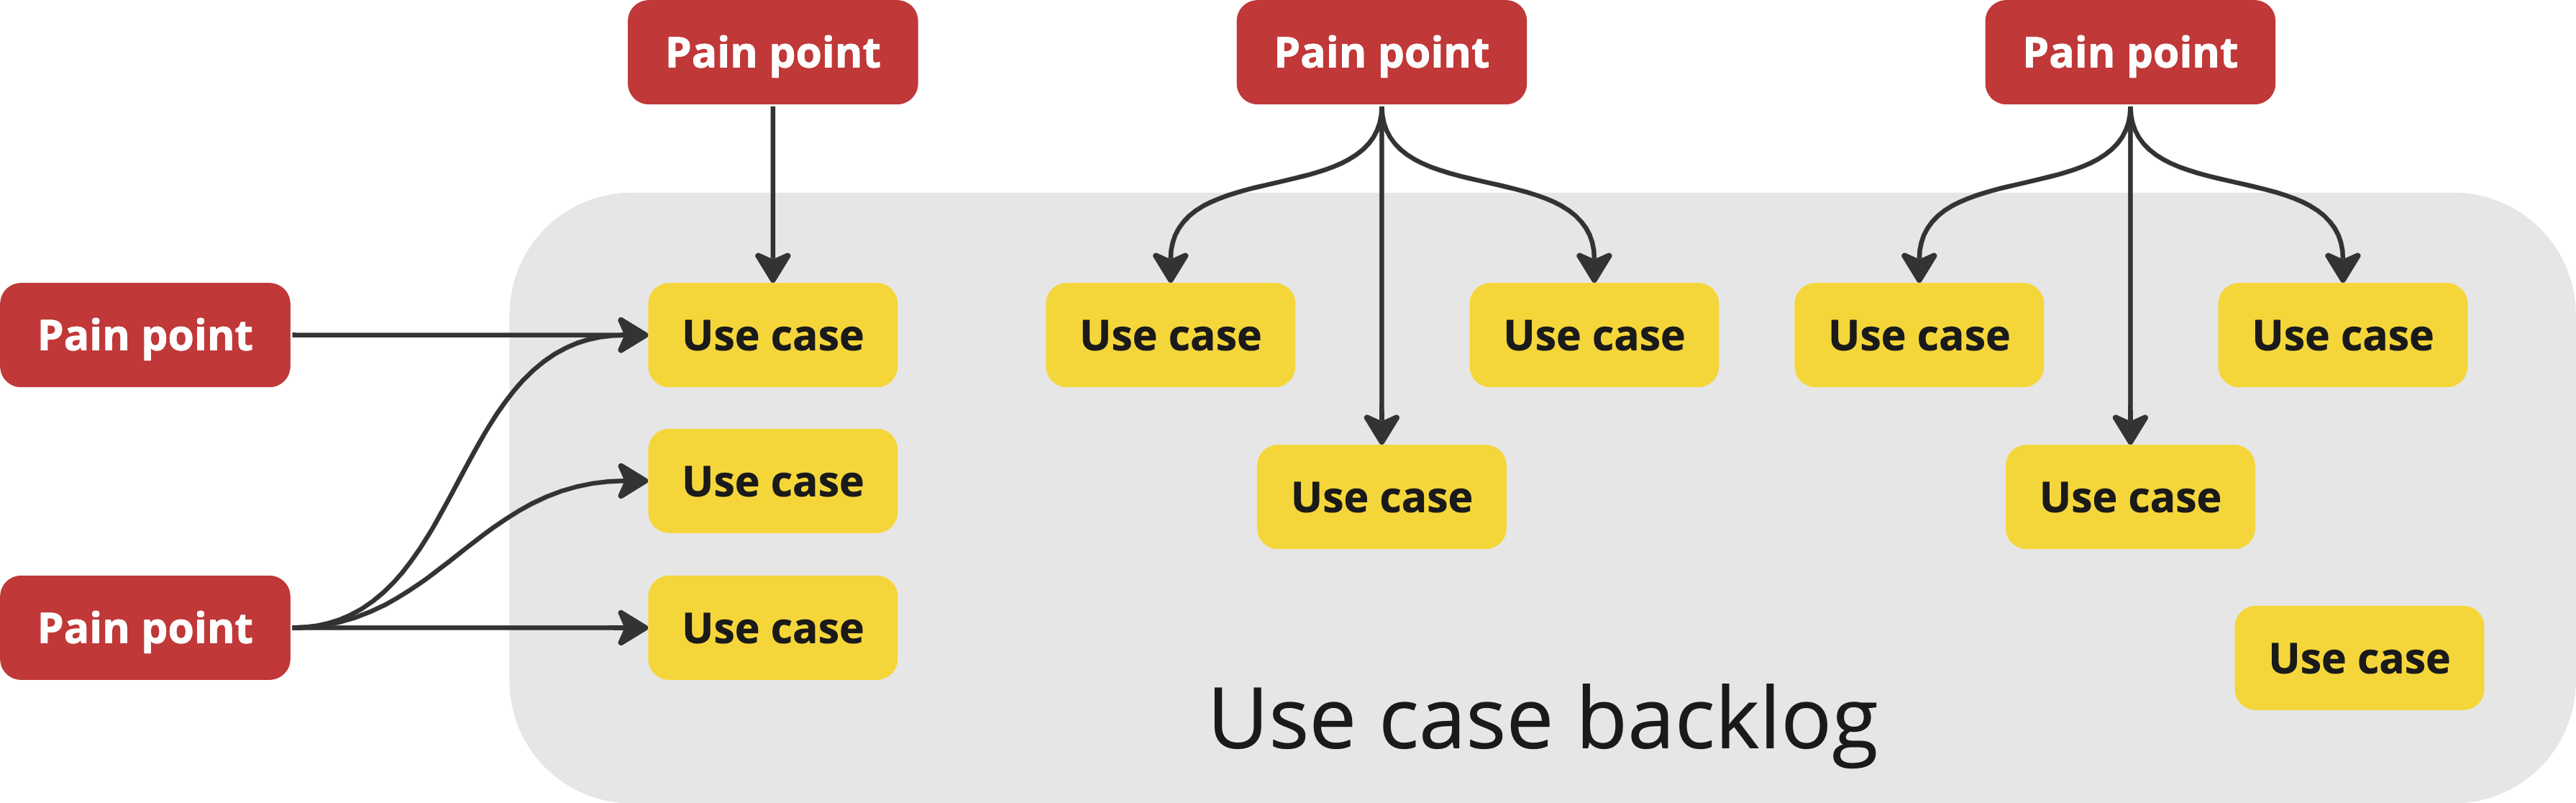

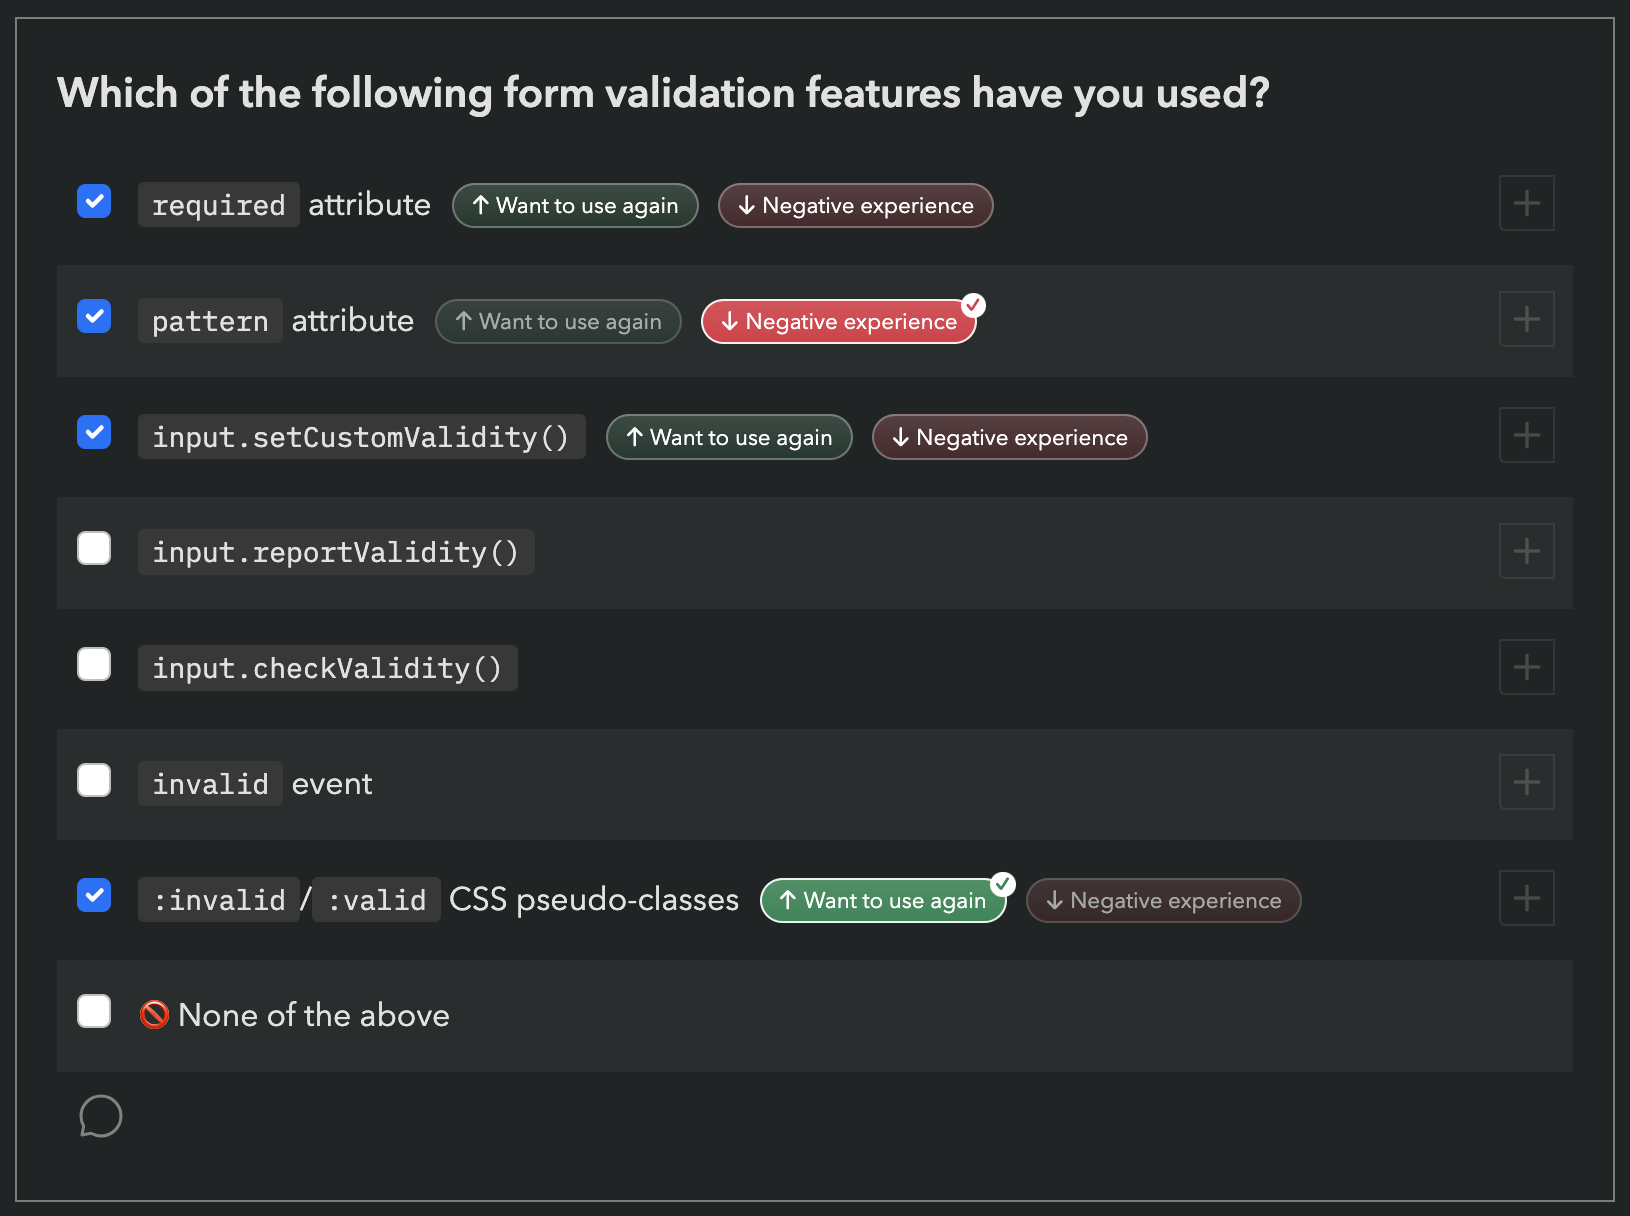 However, this means that if you have never used a feature, it does not count towards your score, even if you have been aware of it for years.
It therefore felt unfair to many to report that you’ve “heard or used” X% of features, when there was no way to express that you have heard 89 out of 131 of them!
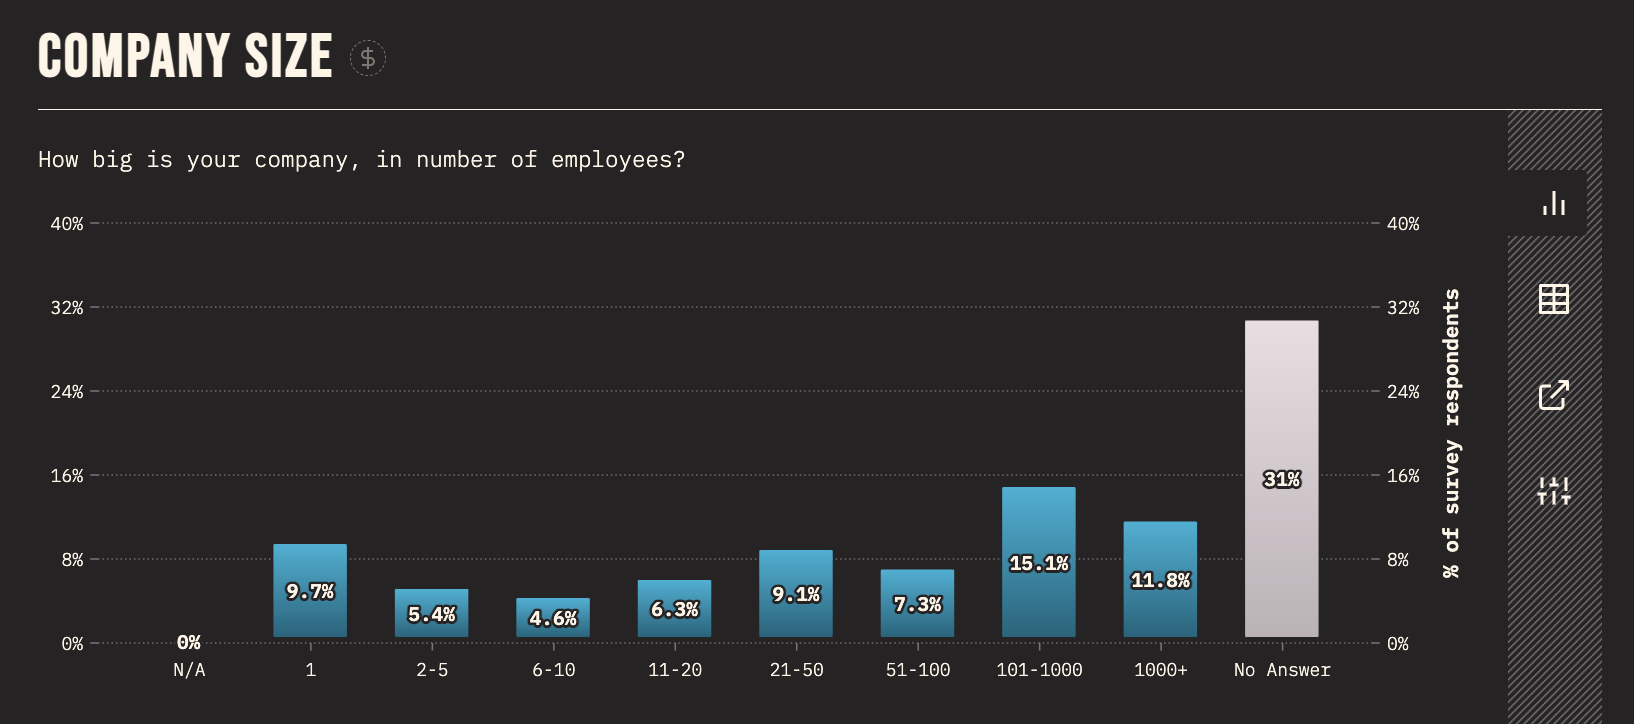
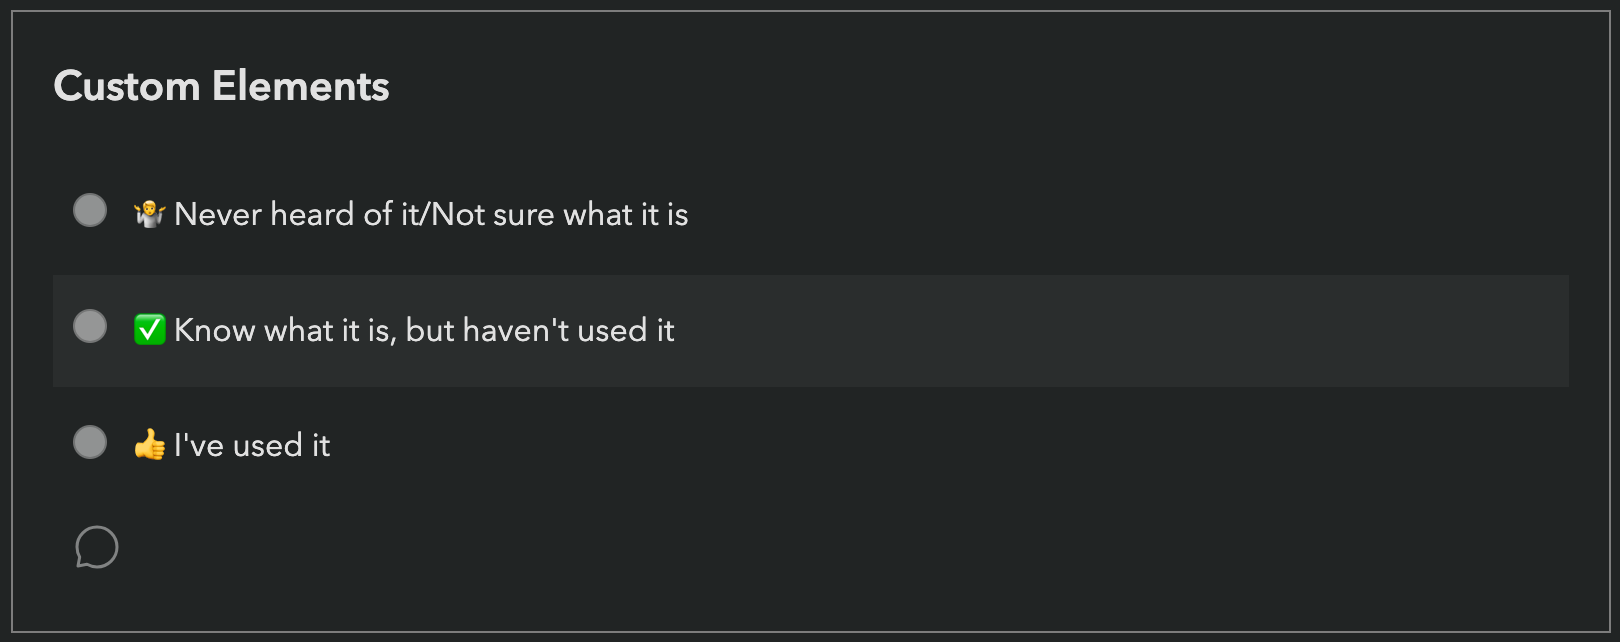 Starting with State of CSS 2022, respondents could also add freeform comments to provide more context about their answer through the little speech bubble icon.
One of my goals this year is to make this feature quicker to use for common types of feedback,
and to facilitate quantitative analysis of the responses (to some degree).